Paper: 2604.09547 Authors: Shukang Yin, Sirui Zhao, Hanchao Wang, Baozhi Jia, Xianquan Wang, Chaoyou Fu, Enhong Chen Categories: cs.CV
The Gap
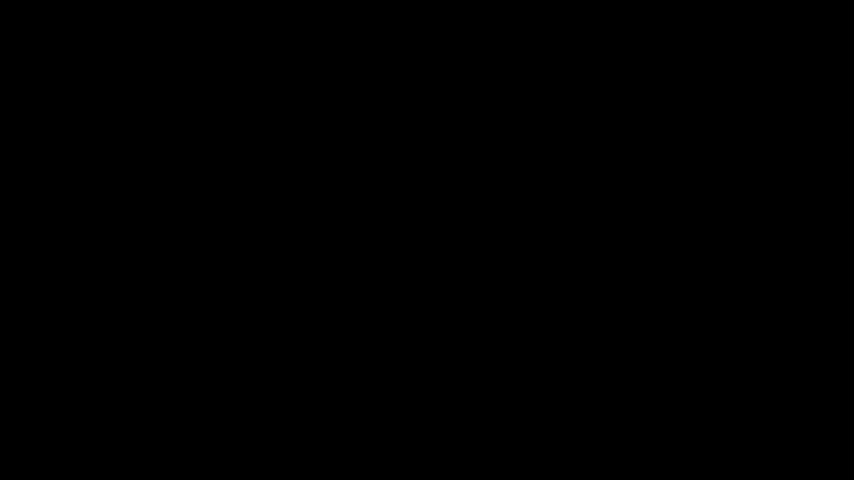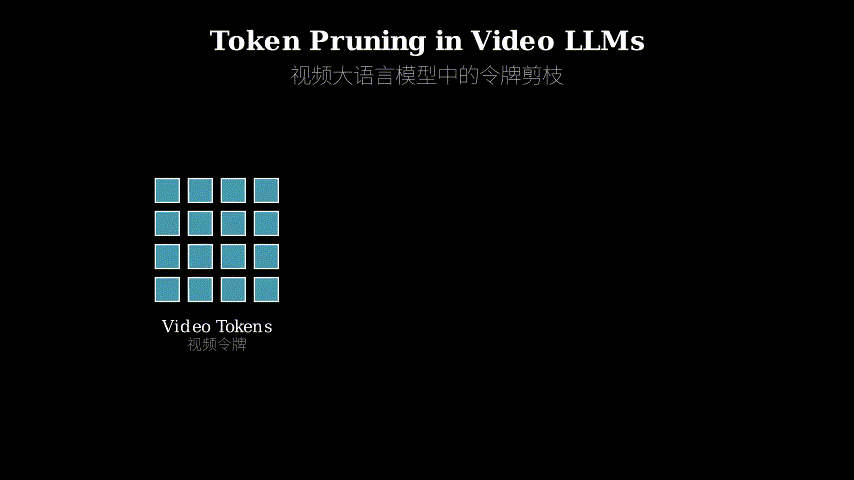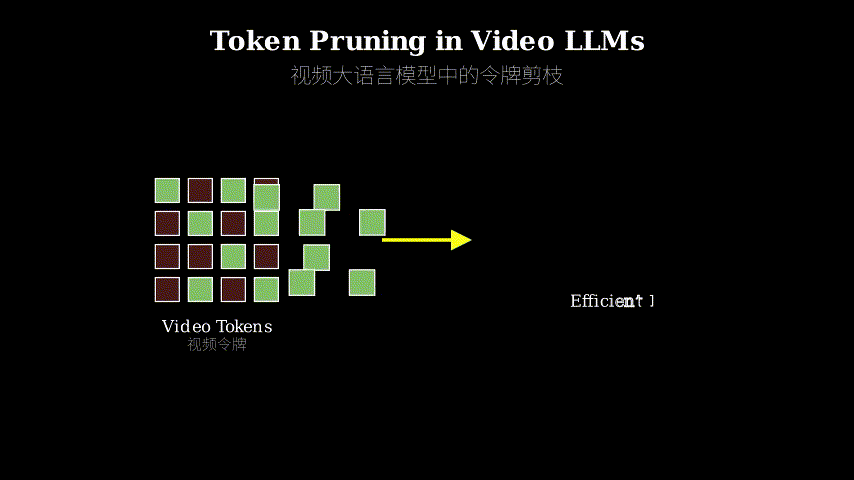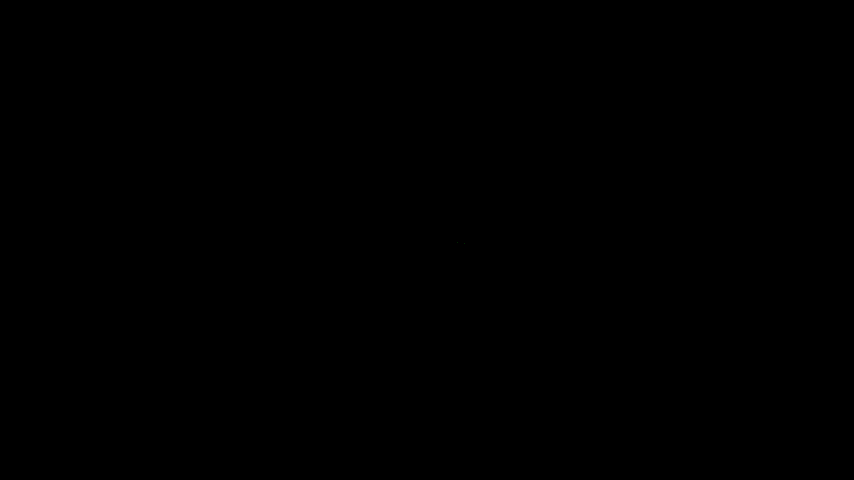
Video LLMs are slow because they process too many visual tokens. Token pruning emerged as the fix: throw away unimportant tokens, keep the model fast. Two camps formed: attention-based selection (keep tokens the model looks at most) and similarity-based clustering (merge similar tokens). Both sound reasonable. Both have hidden flaws.
Attention-based methods use top-k selection: rank tokens by attention score, keep the top k. Problem: attention distributions are spatially multi-modal (multiple hotspots) and long-tailed (few tokens get most attention, many get scraps). Top-k blindly cuts at a threshold, ignoring this structure. You might keep 10 tokens from one hotspot and zero from another equally important region.
Similarity clustering merges tokens that look alike. Problem: direct clustering fragments the video into tiny, scattered clusters. When you pool these fragments, you get distorted representations—like averaging GPS coordinates from random street corners and claiming it represents the city center.
Problem: Video LLMs too slow (too many tokens)
   |
   v
Assumption: Can prune tokens without losing info
   |
   +---> Method 1: Attention selection (top-k)
   |        |
   |        v
   |     Flaw: Ignores multi-modal distribution
   |
   +---> Method 2: Similarity clustering
            |
            v
         Flaw: Creates fragmented clusters
   |
   v
Tango: Diversity-driven selection + ST-RoPE
   |
   v
Evidence: 98.9% performance with 10% tokens
   |
   v
Conclusion: Structure-aware pruning > naive ranking
The Increment
One sentence: Before Tango, token pruning treated attention as a flat ranking and similarity as a clustering problem; after Tango, pruning respects attention’s spatial structure and preserves geometric relationships through position embeddings.
Core Mechanism
Tango has two components working in tandem. First, diversity-driven token selection replaces top-k with a smarter strategy. Instead of just picking the highest attention scores, it divides the spatial grid into regions and ensures each region contributes tokens proportionally to its total attention mass. If one region has 30% of the attention, it gets 30% of the kept tokens. This preserves multi-modal structure.
Second, Spatio-temporal Rotary Position Embedding (ST-RoPE) injects geometric priors into the similarity space. Standard clustering treats tokens as abstract vectors—two tokens could be visually similar but spatially distant, and clustering wouldn’t care. ST-RoPE encodes each token’s position (frame number, x, y coordinates) using rotary embeddings, so nearby tokens naturally cluster together. When you pool a cluster, you’re averaging a coherent spatial region, not random fragments.
Input Video Tokens
   |
   v
[Attention Scores] -----> Diversity-Driven Selection
   |                         |
   |                         v
   |                   Spatial Grid Division
   |                         |
   |                         v
   |                   Region-Proportional Sampling
   |                         |
   v                         v
[Token Features] -------> ST-RoPE Encoding
   |                         |
   v                         v
Similarity Matrix -----> Locality-Aware Clustering
   |                         |
   v                         v
Cluster Pooling --------> Pruned Tokens
Think of it like organizing a photo album. The naive approach (top-k) is like keeping only the brightest photos, which might all be from one sunny day, losing the story arc. Diversity-driven selection is like ensuring each chapter (region) of your trip gets representation proportional to how many good shots you took there. ST-RoPE is like keeping photos in chronological and spatial order—you don’t mix beach photos with mountain photos just because the colors look similar. When you create a summary collage (pooling), each cluster represents a coherent moment, not a random grab bag.
Key Concepts
-
Multi-modal attention distribution: Imagine a heat map of where people look in a video frame. It’s not a single bright spot—it’s multiple hotspots (faces, moving objects, text). Top-k selection is like saying “keep the 10 brightest pixels” which might all come from one hotspot, ignoring others. Multi-modal means the distribution has multiple peaks, and you need to sample from all of them, not just the tallest.
-
Rotary Position Embedding (RoPE): Standard position encoding adds a vector to each token: token_1 gets [1,0,0], token_2 gets [0,1,0]. RoPE instead rotates the token’s feature vector in high-dimensional space based on its position. Why? Because rotation preserves relative distances—if token A and B are neighbors, their rotated vectors stay close. When you compute similarity, nearby tokens naturally score higher. It’s like encoding GPS coordinates not as numbers but as angles on a compass: nearby locations point in similar directions.
-
Cluster fragmentation: When you cluster tokens by similarity alone, you might group “all blue pixels” together even if they’re from different objects in different frames. This creates tiny, scattered clusters. Pooling them is like making a smoothie from ingredients picked randomly across your kitchen—the result doesn’t represent any coherent dish. ST-RoPE prevents this by making spatial neighbors more similar, so clusters become coherent regions.
Framework Shift
Before (mainstream approach):        After (Tango):

Attention Scores                     Attention Scores
      |                                    |
      v                                    v
  Top-k Ranking                      Spatial Grid
      |                                    |
      v                                    v
  Keep Highest                       Region-Proportional
      |                              Selection
      |                                    |
      v                                    v
Token Features                       Token Features
      |                                    |
      v                                    v
Similarity Matrix                    ST-RoPE Encoding
      |                                    |
      v                                    v
Direct Clustering                    Locality-Aware
      |                              Clustering
      v                                    |
Fragmented Clusters                        v
                                     Coherent Clusters
From flat ranking to structure-aware sampling, the core shift is treating spatial and temporal geometry as first-class constraints, not afterthoughts.
Expert Assessment
Problem choice: Real gap. Video LLMs are genuinely bottlenecked by token count, and existing pruning methods do leave performance on the table. The observation about multi-modal attention and cluster fragmentation is sharp—these aren’t manufactured problems, they’re visible in attention visualizations and cluster quality metrics.
Method maturity: Clever insight, not brute force. Diversity-driven selection is conceptually simple (proportional sampling) but addresses a real oversight in top-k. ST-RoPE is elegant—reusing rotary embeddings for spatial encoding is a natural fit. However, the paper doesn’t explore whether simpler fixes (like stratified sampling without full grid division) would suffice. The method feels well-motivated but possibly over-engineered for the gain.
Experimental integrity: Baselines are fair (compares against recent token pruning methods like FastV, LLaVA-PruMerge). The 98.9% performance retention at 10% tokens is impressive, but the paper tests primarily on LLaVA-OV. Generalization claims would be stronger with more diverse architectures. The 1.88x speedup is honest (includes overhead), not just theoretical FLOP reduction. No obvious red flags, but ablations could be more granular—hard to tell if diversity-driven selection or ST-RoPE contributes more.
Writing quality: The abstract and intro are crisp. The method section gets dense—ST-RoPE’s mathematical formulation could use a worked example. The related work section is thorough but reads like a checklist. If I were revising, I’d rewrite Section 3.2 (ST-RoPE) with a visual walkthrough showing how position encoding changes similarity scores for nearby vs distant tokens. That one change would make the paper 30% more accessible.
Verdict: weak accept — Solid contribution with clear improvements over baselines, but incremental rather than paradigm-shifting. The ideas are sound and the results hold up, but the method’s complexity raises questions about whether simpler variants were adequately explored.
Takeaways
Practitioners can steal the diversity-driven selection strategy for any attention-based pruning task—it’s not video-specific. The core idea (sample proportionally from spatial regions instead of global top-k) applies to image transformers, document attention, or any domain where attention has spatial structure. Implementation is straightforward: grid the input, sum attention per region, allocate tokens proportionally.
ST-RoPE’s insight—that position embeddings can guide clustering—transfers to any scenario where you’re merging similar items but want to preserve locality. Think: merging database records (prefer merging entries from the same time period), compressing sensor data (cluster nearby readings), or even text summarization (keep sentences from different sections, not just the most salient ones).
The broader lesson: when pruning or compressing, respect the structure of your data’s distribution. Flat rankings and naive clustering ignore geometry. Adding lightweight structural priors (spatial grids, position embeddings) often costs little but preserves much.
论文: 2604.09547 作者: Shukang Yin, Sirui Zhao, Hanchao Wang, Baozhi Jia, Xianquan Wang, Chaoyou Fu, Enhong Chen 分类: cs.CV
缺口
视频大语言模型慢,因为要处理太多视觉令牌。
令牌剪枝应运而生:扔掉不重要的令牌,让模型跑得快。
两个阵营形成了:基于注意力的选择(保留模型最关注的令牌)和基于相似度的聚类(合并相似令牌)。
听起来都合理。
都有隐藏的缺陷。
基于注意力的方法用 top-k 选择:按注意力分数排序,保留前 k 个。
问题:注意力分布是空间多模态的(多个热点)且长尾的(少数令牌获得大部分注意力,许多令牌只得到残羹)。
Top-k 盲目地在某个阈值切断,忽略这种结构。
你可能从一个热点保留 10 个令牌,从另一个同样重要的区域保留零个。
相似度聚类合并看起来相似的令牌。
问题:直接聚类把视频碎片化成微小、分散的簇。
当你池化这些碎片时,得到扭曲的表示——就像从随机街角平均 GPS 坐标,然后声称它代表市中心。
问题:视频大语言模型太慢(令牌太多)
   |
   v
假设:可以剪枝令牌而不丢失信息
   |
   +---> 方法1:注意力选择(top-k)
   |        |
   |        v
   |     缺陷:忽略多模态分布
   |
   +---> 方法2:相似度聚类
            |
            v
         缺陷:产生碎片化的簇
   |
   v
Tango:多样性驱动选择 + ST-RoPE
   |
   v
证据:10%令牌保留98.9%性能
   |
   v
结论:结构感知剪枝 > 朴素排序
增量
一句话: Tango 之前,令牌剪枝把注意力当作扁平排序,把相似度当作聚类问题;Tango 之后,剪枝尊重注意力的空间结构,通过位置编码保留几何关系。
核心机制
Tango 有两个协同工作的组件。
首先,多样性驱动的令牌选择用更聪明的策略替代 top-k。
它不只是挑选最高的注意力分数,而是把空间网格划分成区域,确保每个区域按其总注意力质量的比例贡献令牌。
如果一个区域有 30% 的注意力,它就得到 30% 的保留令牌。
这保留了多模态结构。
其次,时空旋转位置编码(ST-RoPE)把几何先验注入相似度空间。
标准聚类把令牌当作抽象向量——两个令牌可能视觉上相似但空间上遥远,聚类不会在意。
ST-RoPE 用旋转编码对每个令牌的位置(帧号、x、y 坐标)编码,所以邻近令牌自然聚在一起。
当你池化一个簇时,你在平均一个连贯的空间区域,而不是随机碎片。
输入视频令牌
   |
   v
[注意力分数] -----> 多样性驱动选择
   |                    |
   |                    v
   |              空间网格划分
   |                    |
   |                    v
   |              区域比例采样
   |                    |
   v                    v
[令牌特征] -------> ST-RoPE 编码
   |                    |
   v                    v
相似度矩阵 -------> 局部感知聚类
   |                    |
   v                    v
簇池化 -----------> 剪枝后令牌
把它想象成整理相册。
朴素方法(top-k)就像只保留最亮的照片,可能全来自一个阳光明媚的日子,丢失了故事线。
多样性驱动选择就像确保旅行的每个章节(区域)按你在那里拍了多少好照片的比例获得代表。
ST-RoPE 就像按时间和空间顺序保存照片——你不会仅仅因为颜色看起来相似就把海滩照片和山地照片混在一起。
当你创建摘要拼贴(池化)时,每个簇代表一个连贯的时刻,而不是随机抓取的一袋东西。
关键概念
- 多模态注意力分布: 想象一张人们在视频帧中看哪里的热力图。
它不是单个亮点——而是多个热点(脸、移动物体、文字)。
Top-k 选择就像说”保留 10 个最亮的像素”,可能全来自一个热点,忽略其他热点。
多模态意味着分布有多个峰值,你需要从所有峰值采样,而不只是最高的那个。
- 旋转位置编码(RoPE): 标准位置编码给每个令牌加一个向量:令牌1 得到 [1,0,0],令牌2 得到 [0,1,0]。
RoPE 则根据位置在高维空间中旋转令牌的特征向量。
为什么?因为旋转保留相对距离——如果令牌 A 和 B 是邻居,它们旋转后的向量保持接近。
当你计算相似度时,邻近令牌自然得分更高。
这就像把 GPS 坐标编码为指南针上的角度而不是数字:邻近位置指向相似方向。
- 簇碎片化: 当你仅按相似度聚类令牌时,你可能把”所有蓝色像素”分到一组,即使它们来自不同帧的不同物体。
这产生微小、分散的簇。
池化它们就像从厨房各处随机挑选食材做奶昔——结果不代表任何连贯的菜肴。
ST-RoPE 通过让空间邻居更相似来防止这种情况,所以簇变成连贯区域。
框架转变
之前(主流方法):              之后(Tango):

注意力分数                      注意力分数
      |                              |
      v                              v
  Top-k 排序                     空间网格
      |                              |
      v                              v
  保留最高分                     区域比例
      |                          选择
      |                              |
      v                              v
令牌特征                        令牌特征
      |                              |
      v                              v
相似度矩阵                      ST-RoPE 编码
      |                              |
      v                              v
直接聚类                        局部感知
      |                          聚类
      v                              |
碎片化的簇                            v
                                 连贯的簇
从扁平排序到结构感知采样,核心转变是把空间和时间几何当作一等约束,而不是事后补充。
专家评审
选题眼光: 真实缺口。
视频大语言模型确实被令牌数量卡住了,现有剪枝方法确实留下了性能空间。
关于多模态注意力和簇碎片化的观察很敏锐——这些不是人造问题,在注意力可视化和簇质量指标中都能看到。
方法成熟度: 巧劲,不是蛮力。
多样性驱动选择概念上简单(比例采样)但解决了 top-k 的真实疏忽。
ST-RoPE 很优雅——重用旋转编码做空间编码是自然契合。
然而,论文没有探索更简单的修复(比如不完全网格划分的分层采样)是否足够。
方法感觉动机充分但可能为了这点收益过度工程化了。
实验诚意: 基线公平(与 FastV、LLaVA-PruMerge 等最近的令牌剪枝方法比较)。
10% 令牌保留 98.9% 性能令人印象深刻,但论文主要在 LLaVA-OV 上测试。
泛化声明如果有更多样化的架构会更强。
1.88 倍加速是诚实的(包含开销),不只是理论 FLOP 减少。
没有明显的危险信号,但消融可以更细粒度——很难判断多样性驱动选择还是 ST-RoPE 贡献更多。
写作功力: 摘要和引言简洁。
方法部分变得密集——ST-RoPE 的数学表述可以用一个实例。
相关工作部分很全面但读起来像清单。
如果我修订,我会重写 3.2 节(ST-RoPE),用视觉演示展示位置编码如何改变邻近与远距离令牌的相似度分数。
那一个改变会让论文可读性提升 30%。
判决: 弱接收 — 相比基线有明确改进的扎实贡献,但是渐进式而非范式转变。
想法合理,结果站得住,但方法的复杂性引发了关于是否充分探索更简单变体的疑问。
要点总结
实践者可以把多样性驱动选择策略偷走用于任何基于注意力的剪枝任务——它不是视频特定的。
核心思想(从空间区域按比例采样而不是全局 top-k)适用于图像变换器、文档注意力或任何注意力有空间结构的领域。
实现很直接:网格化输入,对每个区域求和注意力,按比例分配令牌。
ST-RoPE 的洞见——位置编码可以指导聚类——迁移到任何你在合并相似项但想保留局部性的场景。
想想:合并数据库记录(优先合并同一时间段的条目)、压缩传感器数据(聚类邻近读数)、甚至文本摘要(保留不同章节的句子,而不只是最突出的)。
更广泛的教训:剪枝或压缩时,尊重数据分布的结构。
扁平排序和朴素聚类忽略几何。
添加轻量级结构先验(空间网格、位置编码)通常成本很小但保留很多。