Paper: 2604.02292 Authors: Dimitrios Danopoulos, Enrico Lupi, Michael Kagan, Maurizio Pierini Categories: cs.LG, cs.AR
The Gap
Most softmax-approximation papers start from a generic question: can we avoid exponentials? This paper starts from a narrower and more useful one: on integer-heavy edge hardware, why are we still paying for a floating-point style primitive inside an otherwise quantized attention block?
Where prior work had already gone:
- Standard softmax is the quality reference, but it requires exponentiation and normalization, which are awkward on integer-native accelerators.
- LUT-based exponential approximations reduce exact exp cost, but still keep the same basic computational pattern: approximate exp, accumulate, divide. That means memory traffic, control complexity, or throughput limits.
- bfloat16 / floating-point implementations are straightforward, but they leave integer MAC hardware underused.
- Earlier softmax surrogates often use polynomial or other smooth approximations, but they are usually global approximations. They do not explicitly preserve the per-head statistics of attention heads, which matters more in small or heavily quantized transformers where each head can behave differently.
So the gap is not “nobody approximated softmax before.” The gap is:
- No int8-native surrogate tailored to AMD Versal AI Engines
- No head-specific calibration layer to compensate for the fact that different attention heads have different logit distributions
- No clear demonstration that a very cheap bounded monotone mapping can survive quantization-aware retraining and still be useful on real workloads
The paper’s move is logically clean: instead of approximating exp well everywhere, approximate the role softmax plays inside attention well enough, with operations the hardware actually likes.
[Problem]
softmax in MHA is expensive on edge hardware
|
v
[Assumption]
for small or quantized models
ranking stability and usable normalization
matter more than exact exp shape
|
v
[Method]
max center logits
then apply head calibrated clipped linear map
then normalize
|
v
[Evidence]
int8 mapping on AMD AI Engines
higher throughput than bf16 or LUT style refs
competitive task accuracy after QAT
|
v
[Conclusion]
replace exact softmax with a hardware shaped surrogate
when edge throughput is the real bottleneck
The Increment
One sentence: Before this paper, softmax replacement on edge transformers was mostly “approximate the math”; after this paper, it becomes “reshape the operation around int8 hardware and calibrate it per head.”
Core Mechanism
HCCS starts from a familiar softmax trick: max-center the logits. In ordinary softmax, subtracting the maximum logit improves numerical stability without changing the final probabilities. Here that same step is used for a different reason too: once the largest value becomes zero and everything else is non-positive, the authors can apply a very simple monotone mapping on a bounded range.
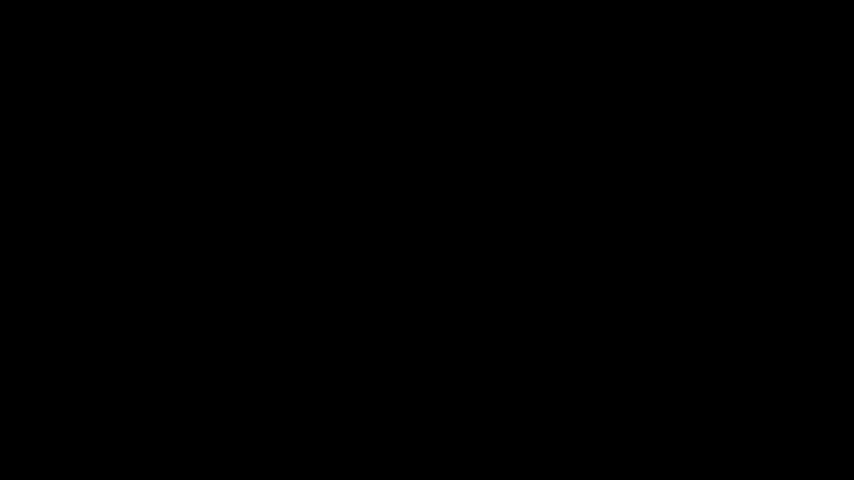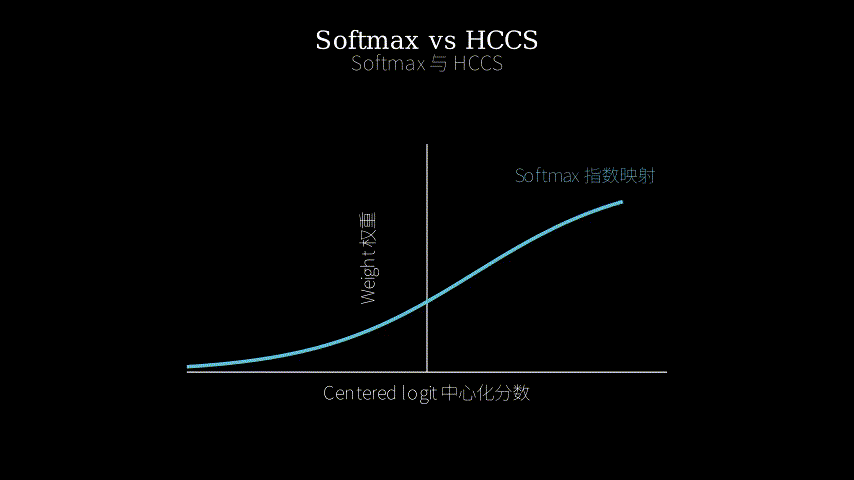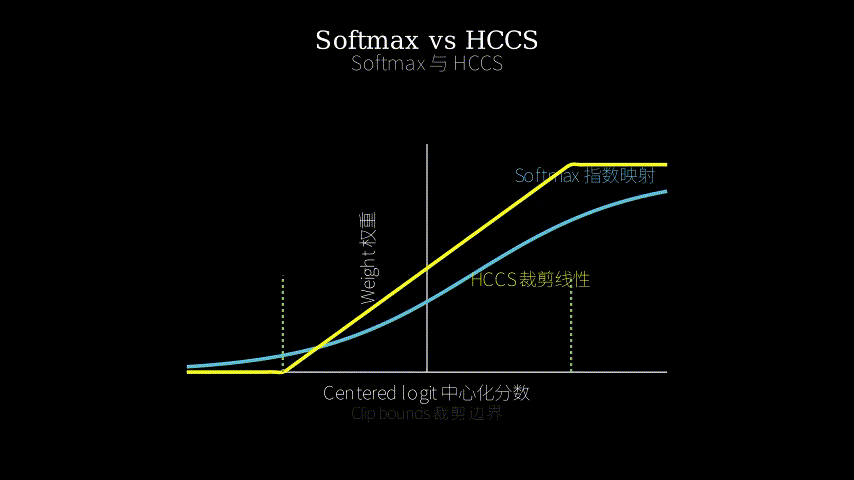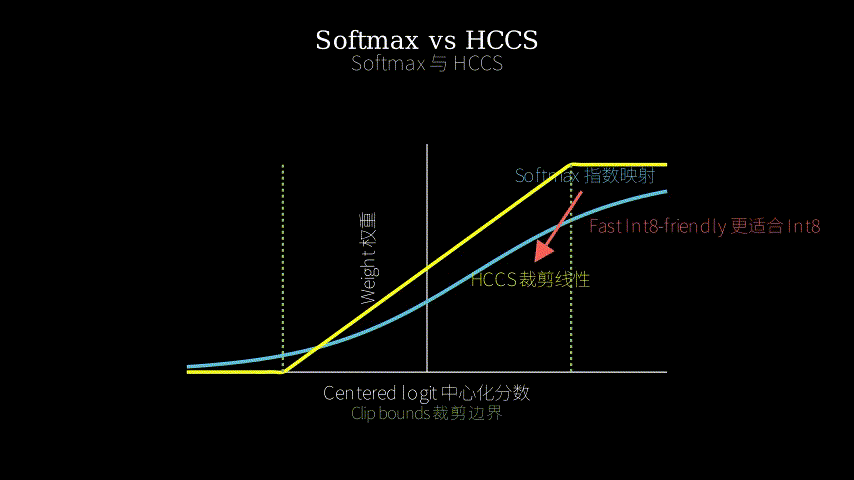
That mapping is the core surrogate: instead of exponentiating each centered logit, HCCS applies a clipped linear function. Large negative logits get clipped toward zero contribution; logits near the maximum keep proportionally larger weights. This gives three things the authors care about: non-negativity, preserved ordering, and a bounded output range that is easy to implement with integer arithmetic. After that, the outputs are normalized into a probability-like distribution.
The genuinely new ingredient is the head-calibrated part. The surrogate is not one universal line shared by every attention head. Each head gets lightweight calibration parameters, optimized offline on representative data so that the surrogate better matches that head’s statistical behavior. That matters because attention heads are not interchangeable little copies in practice; some are sharp, some diffuse, some operate in very different logit ranges. The paper’s claim is that this tiny bit of per-head customization closes enough of the quality gap to make the cheap surrogate viable.
[input logits per head]
|
v
[max over sequence]
|
v
[subtract max]
|
v
[head specific scale and offset]
|
v
[clipped linear map]
|
v
[non negative bounded scores]
|
v
[sum]
|
v
[divide by sum]
|
v
[attention weights]
A good structural metaphor here is a factory sorting line with adjustable gates.
Think of each attention head as its own conveyor belt carrying items of different sizes. Standard softmax is like sending every item through an expensive precision scanner that measures size with a fancy nonlinear instrument, then computing each item’s share exactly. That gives high fidelity, but it is slow and requires specialized machinery.
HCCS replaces that scanner with a cheap mechanical gate. First, the belt manager resets the tallest item to the reference height: that is max-centering. Then each item passes under a head-specific gate setting. Items close to the tallest one pass through with high score; much shorter items get partially counted or clipped away entirely. Finally, the line counts the surviving heights and converts them into shares. The key is that each conveyor belt has its own gate calibration, because one belt carries tiny screws and another carries bottles. A single gate setting for the whole factory would be crude; per-belt calibration is what makes the cheap mechanism usable.
Key Concepts
-
Max-centered logits: In attention, the raw scores can be shifted by the same constant without changing their relative probabilities after normalization. Subtracting the largest score makes the best token equal to zero and all others negative. Why is that useful? Because now you know the dynamic range and can design a cheap approximation on that range. Example: if logits are
[7, 5, 1], max-centering gives[0, -2, -6]. The winner stays the winner, but the numbers are now in a shape that is easier to handle safely. -
Clipped linear surrogate: Softmax uses
exp, which sharply rewards larger logits but never goes negative. A clipped linear map says: instead of a curve, use a line, and once values get too small, cut them off at zero. Example: maybe0maps to1,-1maps to0.7,-2maps to0.4, and anything below-3maps to0. This is not mathematically faithful toexp, but it preserves the rough idea that better logits get larger weights and very bad logits stop mattering. -
Per-head calibration: Different attention heads produce different score distributions. One head may usually emit logits in a tight band like
[-1, 1]; another may spread out to[-8, 2]. If you force both through the same surrogate, one of them gets distorted. Per-head calibration means fitting a tiny set of parameters for each head using representative data so the surrogate matches that head’s world better. It is the difference between one-size-fits-all shoes and measured insoles.
Framework Shift
Before (mainstream approach):        After (this paper):
[logits]                             [logits]
   |                                    |
   v                                    v
[max center]                         [max center]
   |                                    |
   v                                    v
[approx exp or LUT exp]              [head calibrate]
   |                                    |
   v                                    v
[sum exp]                            [clipped linear]
   |                                    |
   v                                    v
[divide]                             [sum]
   |                                    |
   v                                    v
[weights]                            [divide]
                                      |
                                      v
                                   [weights]
[One sentence: From approximating the exponential itself to approximating attention weighting in a hardware-native way, the core shift is algorithm shaped by datapath rather than datapath forced to emulate the old algorithm.]
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. In big-model discussions, softmax often looks negligible next to matrix multiplies; on edge devices and small models, that assumption breaks. The paper sits in an important part of the field’s trajectory: as transformers move into constrained hardware, “small leftovers” like softmax stop being leftovers.
Method maturity: The main idea is clever but not mystical. The clipped-linear surrogate itself is simple; the sharper insight is per-head offline calibration plus an implementation story that respects actual AI Engine hardware. That said, this is still a fairly specialized systems-paper move, not a general theory breakthrough. A reasonable concern is whether even simpler surrogates, or sparse attention-style heuristics, could get similar gains under the same retraining budget.
Experimental integrity: Based on the abstract, the baselines seem directionally fair: AMD reference paths using bf16 or LUT-style exponentials are the obvious comparisons. The strongest evidence is throughput plus end-task accuracy after quantization-aware retraining, because this is not a drop-in mathematical substitute. The caution flag is that the claim appears scoped to small or heavily quantized MHA workloads. That is fine, but it means you should not overgeneralize to large, accuracy-sensitive models without checking the full paper.
Writing quality: The hardware motivation is clear, and the paper likely knows exactly who it is for. Where papers like this often cut corners is in explaining why headwise calibration is sufficient, rather than just empirically effective. If I could rewrite one section, it would be the method section around calibration: I would want a crisper account of what is learned offline, what objective is used, how stable it is across datasets, and how much deployment friction that calibration introduces.
Verdict: weak accept — a narrow but meaningful contribution that solves the right practical problem with a hardware-conscious design, though its impact is bounded by deployment context.
Takeaways
There are a few concrete things practitioners can steal:
-
Approximate the function that matters operationally, not the formula literally. If hardware hates exp, stop trying to imitate exp globally. Ask what properties you actually need: ordering, non-negativity, boundedness, normalizability.
-
Calibrate by substructure, not only globally. The per-head idea generalizes. In quantized models, one layer or head often has a different distribution from another. Tiny local calibration parameters can outperform one global approximation.
-
Design surrogate nonlinearities around the arithmetic units you own. If your accelerator is best at int8 MACs, your nonlinear surrogate should look like scales, offsets, clipping, and reductions whenever possible.
-
QAT can legitimize rough approximations. A surrogate that looks crude in isolation may work surprisingly well once the whole model is retrained around it. That is a useful framing for other bottlenecks too, like GELU, layernorm approximations, or activation compression.
If you work on edge inference, this paper is worth reading. If you work on general transformer theory, probably not essential.
论文: 2604.02292 作者: Dimitrios Danopoulos, Enrico Lupi, Michael Kagan, Maurizio Pierini 分类: cs.LG, cs.AR
缺口
这篇论文抓的不是“softmax 能不能近似”这个老问题。
它抓的是一个更具体、也更工程化的问题:当 Transformer 已经大部分量化、而硬件本身又偏爱整数计算时,为什么注意力里还保留着一个对指数和归一化高度依赖的软肋?
已有工作的边界大概是这样:
- 标准 softmax 当然最准,但它要做指数、求和、再除法。
在边缘设备上,尤其是 int8 为主的数据通路上,这套流程并不友好。 - LUT 近似 exp 是常见路线。
它确实比精确指数便宜,但计算结构没变:还是在“想办法做 exp”。
所以吞吐、访存、控制复杂度这些问题并没有从根上消失。 - bf16 或浮点实现 很直接,但会让整数 MAC 单元吃不满。
这对 AMD Versal AI Engine 这类平台来说,是很实际的浪费。 - 以往 softmax surrogate 往往是全局性的函数逼近。
问题在于注意力头和注意力头之间,logit 分布并不一样。
小模型、重度量化模型里,这种差异会更明显。
一个“全头通用”的近似,往往会把某些头压坏。
所以它填的缺口不是“第一次有人不用 exp”。
而是三个更窄但更硬的缺口:
- 面向 AMD AI Engine 的 int8 原生 softmax 替代方案并不成熟。
- 此前方法很少把 attention head 当成需要分别校准的对象。
- 缺少证据说明:一个非常便宜、非常粗糙的单调有界映射,在 QAT 之后仍然够用。
论文的逻辑其实很朴素:
别再执着于“指数曲线长得像不像”。
改成问“在注意力里,softmax 需要完成哪些功能,而这些功能能否用整数友好的方式实现”。
[问题]
边缘端 MHA 里的 softmax 成本过高
|
v
[假设]
对小模型和重度量化模型
保序 稳定 非负 可归一化
比精确指数更重要
|
v
[方法]
logit 先减最大值
再做按头校准的截断线性映射
最后归一化
|
v
[证据]
可映射到 AMD AI Engine 的 int8 路径
吞吐高于 bf16 或 LUT 参考实现
QAT 后任务精度仍有竞争力
|
v
[结论]
在真实边缘瓶颈下
可用硬件友好 surrogate 替代 softmax
增量
一句话: 在这篇论文之前,softmax 近似更多是在“逼近 exp 这条数学曲线”;在这篇论文之后,重点变成了“按硬件数据通路重写注意力加权,并且按头校准”。
核心机制
HCCS 的第一步并不新,但很关键:先对每个注意力头的 logits 做 max-centering。
也就是把最大值减掉,让最大的 logit 变成 0,其他都变成不大于 0 的数。
在标准 softmax 里,这一步是为了数值稳定。
在这里,它还有第二层作用:把输入压进一个更可控的区间,方便后面用简单线性函数处理。
接下来是核心替代:不用 exp,而用 clipped linear map。
你可以把它理解成一根被截断的斜线。
离最大 logit 越近,映射值越大;太小的 logit 就直接压到 0。
这样做牺牲了 softmax 的细腻曲率,但保住了几件更重要的事:输出非负、顺序不乱、范围有上界,而且实现上天然适合整数运算。
真正让这篇论文不只是“又一个线性近似”的地方,在于 Head-Calibrated。
作者不是给所有头共用同一条线,而是给每个 attention head 配一组很轻的校准参数。
这些参数通过代表性数据离线优化,目的是让 surrogate 更贴近这个头自身的 logit 统计特性。
这点很重要,因为注意力头在真实模型里不是复制粘贴出来的同质模块。
有的头分数很尖,有的头很平,有的头动态范围很大。
如果你拿一把统一尺子去量所有头,误差会集中砸在最脆弱的那些头上。
[每个头的 logits]
|
v
[取最大值]
|
v
[减去最大值]
|
v
[按头缩放与偏移]
|
v
[截断线性映射]
|
v
[得到非负有界分数]
|
v
[求和]
|
v
[除以总和]
|
v
[注意力权重]
我觉得一个真正“承重”的比喻是:不同车道的收费站限高架。
把每个 attention head 想成一条独立车道。
标准 softmax 像是在每条车道前放一套精密激光扫描系统,逐车测量,再按复杂规则计费。
它很准,但又贵又慢。
HCCS 则像把激光系统换成了一个可调限高架。
先把每条车道里最高的那辆车当基准,这就是 max-centering。
然后根据这条车道平时跑的是轿车、货车还是面包车,单独调节限高架的位置,这就是 per-head calibration。
离“最高车”差不多的车,能拿到较高分;明显矮很多的车,会被压低甚至直接判成 0。
最后,再把留下来的分数做归一化,变成每辆车应占的权重。
这个比喻之所以承重,在于方法的每个零件都能对上号:
基准车对应最大 logit,限高架对应截断线性映射,车道单独调节对应按头校准,最后的收费分摊对应归一化。
你要复述这篇论文,完全可以说:它不是在精细模拟指数,而是在给每个注意力头装一个合适的机械门槛,让注意力分配更适合整数流水线。
关键概念
-
Max-centering:
注意力分数整体平移,并不会改变谁比谁更重要。
所以我们可以把最大 logit 减掉,让它变成 0。
例如原来是[7, 5, 1],减去最大值后变成[0, -2, -6]。
第一名还是第一名,但现在数值范围整齐多了。
这就像你比较几个人身高,不一定要知道他们绝对多高,只要知道他们和最高的人差多少就够了。 -
Clipped linear surrogate:
softmax 的直觉是“分数高一点,权重就大不少;分数差太多,基本就没戏”。
指数函数是实现这种效果的一种方式,但不是唯一方式。
截断线性做的是更粗暴的近似:靠近最好值的分数,按线性方式给权重;太差的,直接切到 0。
例如某条线可能规定:0映成1,-1映成0.7,-2映成0.4,低于-3统统归零。
它不精致,但很便宜,而且保留了“好一点就多给,差太多就别给”的核心行为。 -
Per-head calibration:
不同头的分数分布像不同班级的考试成绩。
有的班分数都挤在 80 到 90,有的班拉到 20 到 100。
你如果用同一套裁线去分等级,会对某些班极不公平。
按头校准就是给每个头单独定标尺。
代价很小,但能明显减少 surrogate 带来的失真。
框架转变
之前(主流方法):                之后(本文方法):
[logits]                           [logits]
   |                                  |
   v                                  v
[减最大值]                         [减最大值]
   |                                  |
   v                                  v
[近似 exp 或 LUT exp]              [按头校准]
   |                                  |
   v                                  v
[求 exp 和]                        [截断线性]
   |                                  |
   v                                  v
[除法归一化]                       [求和]
   |                                  |
   v                                  v
[权重]                             [除法归一化]
                                     |
                                     v
                                  [权重]
[一句话:从“尽量保住指数函数”到“保住注意力分配所需的结构属性并贴合整数硬件”,核心转变是算法为硬件重写,而不是硬件迁就旧算法。]
专家评审
选题眼光:
这是个真问题,不是硬造卖点。
在大模型语境里,softmax 经常被矩阵乘法的阴影盖住。
但在边缘推理、小模型、重度量化环境里,softmax 的占比会突然变得很扎眼。
所以这篇论文踩中的,是“模型下沉到端侧之后,经典组件开始重新洗牌”的趋势。
方法成熟度:
方法本身不玄。
截断线性这个想法并不神奇,真正有价值的是两点:一是它和 AMD AI Engine 的 int8 数据通路对得上;二是作者意识到要做 per-head calibration。
也就是说,它的贡献更像“把一个足够便宜的 surrogate 做到了可部署”,而不是“发现了一个全新的注意力理论”。
如果挑刺的话,还是要问一句:有没有更简单的稀疏化、top k、或更粗的重参数化方法,也能拿到接近收益?
这得看正文实验有没有认真排过。
实验诚意:
就摘要透露的信息看,基线选得还算对路。
拿 AMD 自己的 bf16 和 LUT 参考实现来比,是合适的。
而且作者没有只报吞吐,也提了 QAT 后的任务精度,这很关键。
因为这类 surrogate 根本不是“数学上等价替换”,必须看端到端训练后还能不能站住。
但我会保留一个谨慎点:论文似乎把适用范围限定在 small or heavily quantized MHA workloads。
这没问题,但读者不能顺手把结论扩展到大模型、高精度、对校准极敏感的场景。
写作功力:
硬件动机应该写得比较清楚。
但这类论文最容易偷懒的地方,是把“校准有效”写成实验事实,却没把“为什么按头校准足够有效”讲透。
如果让我挑一个最该重写的部分,我会选方法里的校准细节:
到底离线优化了哪些参数,目标函数是什么,对代表数据集有多敏感,部署时需不需要重新校准。
这些如果交代得更扎实,整篇论文的说服力会明显上一个台阶。
判决: 弱接收 — 贡献很窄,但问题选得对,方法贴硬件,且看起来不是只换来速度而完全丢掉精度。
要点总结
这篇论文对实践者最有价值的,不是“又一种 softmax 公式”,而是几个可以迁移走的设计习惯:
-
别死守原函数,先拆需求。
你未必要逼近 exp。
你真正需要的可能只是:保序、非负、可裁剪、可归一化。
一旦把需求拆开,替代空间会大很多。 -
按子结构做微校准,往往比全局统一近似更划算。
这里是 per-head。
换到别的模型里,也可以是 per-layer、per-channel、per-block。
小小一组局部参数,可能比换一个更复杂的全局函数更有效。 -
让 surrogate 长得像硬件喜欢的样子。
如果你的芯片最擅长的是 int8 MAC、缩放、裁剪、归约,那你的近似函数最好也由这些积木拼出来。
这比“先想数学,再勉强下沉”靠谱得多。 -
QAT 可以把粗糙近似驯化成可用系统。
单看函数图形,截断线性可能很糙。
但只要整个模型能围绕它重新适应,它未必不够用。
这个思路不只适用于 softmax,也能迁移到 GELU、LayerNorm,甚至激活压缩上。
如果你做的是端侧推理、量化部署、或者专用加速器上的 Transformer 优化,这篇值得读。
如果你关心的是通用注意力理论,它的重要性就没那么高。