Paper: 2602.24283 Authors: Zhengbo Wang, Jian Liang, Ran He, Zilei Wang, Tieniu Tan Categories: cs.LG, cs.AI, cs.CL
The Gap
Training billion-parameter language models requires optimizers like Adam or Muon that maintain momentum states—exponential moving averages of gradients and their squares. The problem? These momentum matrices are the same size as the model parameters themselves. For a 1B parameter model, Adam stores three copies: the parameters, first-order momentum, and second-order momentum. That’s 12GB just for optimizer state if you’re using float32. This memory wall hits hardest during pre-training, where you can’t afford to waste a single byte of GPU memory. Prior work like GaLore and ReLoRA attempted low-rank training, but they focused on parameter updates rather than optimizer states, leaving the momentum bottleneck untouched.
The Increment
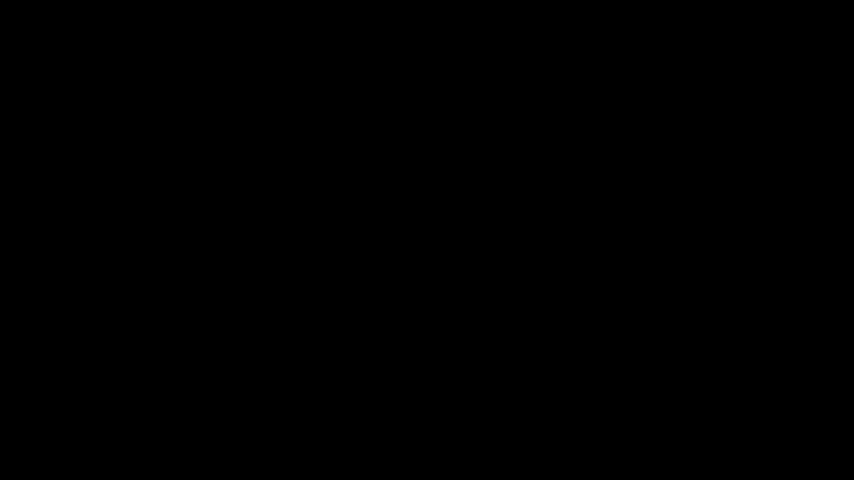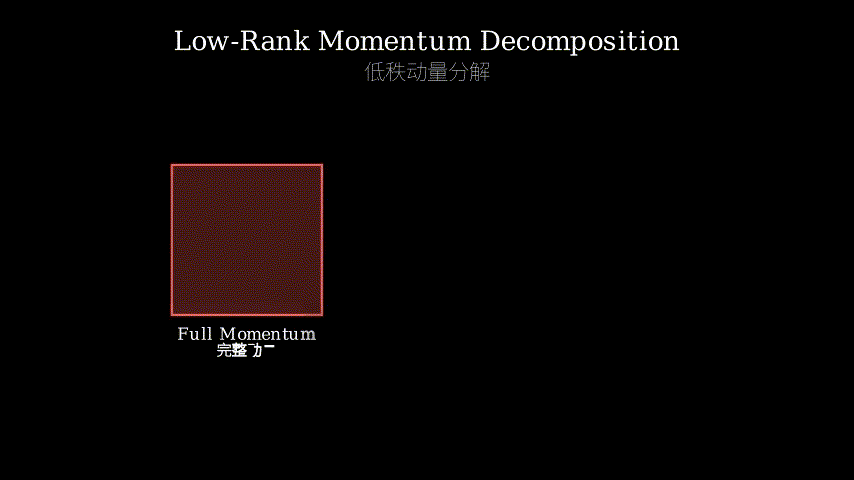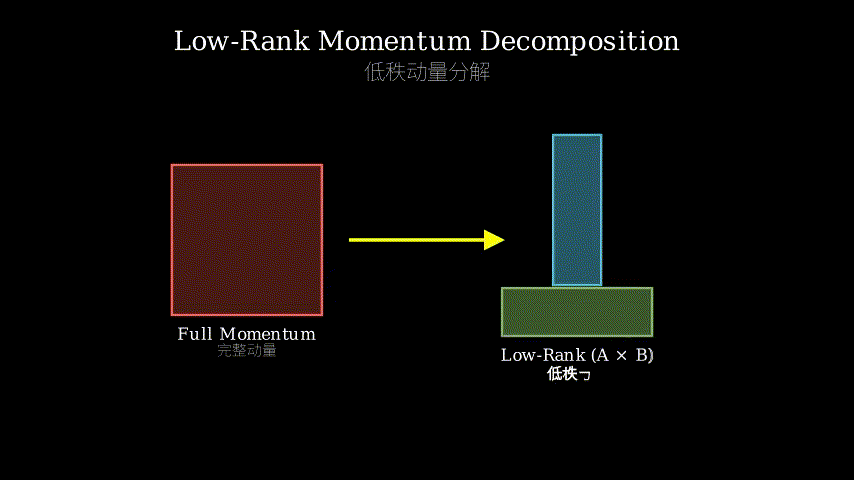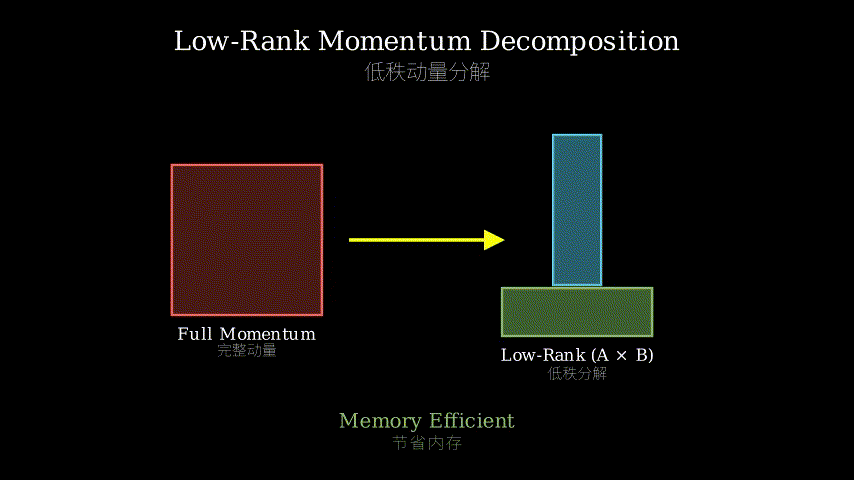
Before: Momentum states consume as much memory as the model itself, forcing practitioners to choose between optimizer quality and scale. After: LoRA-Pre compresses momentum into low-rank subspaces, cutting memory by 8× while matching or beating full-rank performance.
The core insight is elegant: exponential moving averages (EMAs) used in momentum are mathematically equivalent to training a linear regressor via online gradient descent. Think of momentum like a streaming data warehouse. Traditional optimizers (the warehouse) store every raw transaction (gradient) in full detail. LoRA-Pre instead maintains a compressed index—a low-rank projection that captures the essential patterns. The “query engine” (parameter updates) reconstructs what it needs on-the-fly from this compact representation. The projection matrices ( and ) are the index schema, the low-rank dimension is the compression ratio, and the online gradient flow is the incremental update protocol that keeps the index fresh without rebuilding from scratch.
Concretely, instead of storing momentum , LoRA-Pre decomposes it as where and with . The authors prove this decomposition emerges naturally when you view EMA as solving —a weighted least squares problem that admits a low-rank solution via online gradient descent on and .
Key Concepts
Exponential Moving Average as Regression: When Adam computes , it’s not just smoothing—it’s solving an optimization problem. Imagine you’re trying to predict tomorrow’s weather by averaging past observations, but recent days matter more. That’s EMA: a weighted average where weights decay exponentially (). The authors show this is equivalent to minimizing —finding the single vector that best approximates all past gradients , weighted by recency. This reframing is crucial because least squares problems have well-studied low-rank structure. If your gradients lie near a low-dimensional subspace (which they often do in neural networks), you don’t need the full -dimensional —a rank- approximation suffices.
Low-Rank Factorization via Online Gradient Flow: Instead of directly storing , LoRA-Pre maintains such that . But how do you update and as new gradients arrive? The trick is to apply gradient descent on the factorized objective: . This yields update rules: The beauty is that these updates are local—you never materialize the full matrix. It’s like updating a compressed JPEG by tweaking the frequency coefficients, not the raw pixels. The online gradient flow ensures tracks the true momentum without ever computing explicitly.
Rank Efficiency: The paper shows you can use (one-eighth the parameter dimension) and still match full-rank performance. Why? Neural network gradients exhibit low effective rank due to correlated parameter updates—layers learn similar features, creating redundancy. LoRA-Pre exploits this by projecting momentum onto the dominant directions. Think of it like principal component analysis (PCA) on the gradient history: most variance concentrates in a few eigenvectors. By keeping only those top- components, you discard noise while retaining signal. The 8× compression isn’t arbitrary—it’s where the eigenvalue spectrum drops off for typical LLM training runs.
Expert Assessment
Problem significance: This is a real pain point. Memory is the primary constraint in scaling LLM training, and optimizer states are low-hanging fruit—they’re necessary but not fundamental to the model. The affected community is large: anyone pre-training or fine-tuning models beyond a few billion parameters. However, the problem is more acute for pre-training than fine-tuning, where methods like LoRA already reduce parameter counts.
Method maturity: The theoretical foundation (EMA as regression) is solid, but the practical implementation raises questions. The authors don’t discuss how to choose rank adaptively—they test fixed ratios. What happens if the gradient subspace dimensionality changes during training (e.g., early vs. late stages)? The paper also lacks wall-clock time comparisons. Low-rank updates might save memory but add computational overhead from matrix multiplications. Is the memory-compute tradeoff favorable on real hardware? The experiments stop at 1B parameters; scaling to 70B+ models (where memory matters most) is unvalidated.
Experimental rigor: The baselines are fair—GaLore, ReLoRA, and standard LoRA are appropriate comparisons. The Llama architecture is a good testbed. However, the pre-training experiments use relatively small datasets (the paper doesn’t specify token counts clearly). Pre-training convergence is sensitive to hyperparameters; did they tune learning rates separately for each method, or use the same schedule? The fine-tuning results (3.14 and 6.17 point improvements) are impressive but lack error bars or multiple runs. One red flag: the paper claims “highest performance across all model sizes” but doesn’t show loss curves—only final perplexity. Did LoRA-Pre converge faster, or just to a better final point?
Verdict: Weak accept — The core idea is sound and addresses a real bottleneck, but the experimental validation is incomplete for production use at scale, and key practical details (adaptive rank selection, wall-clock efficiency) are underexplored.
Takeaways
Reframe accumulators as learnable systems: Momentum isn’t just a running average—it’s a model being trained. This perspective unlocks compression techniques from representation learning. Anywhere you maintain exponential moving averages (batch norm statistics, policy gradients in RL, Kalman filters), ask: can I factorize this accumulator?
Online gradient flow for streaming compression: The update rules for are a template for maintaining low-rank approximations of streaming data. If you’re building systems that aggregate high-dimensional signals over time (sensor networks, recommendation systems), this pattern—update factors incrementally rather than recompute the full matrix—is directly applicable.
Memory-compute tradeoffs are hardware-dependent: Low-rank methods save memory but add FLOPs. On memory-bound workloads (large batch training), this tradeoff favors compression. On compute-bound workloads (small batch inference), it might not. Always profile before assuming “fewer parameters = faster.”
Rank as a hyperparameter deserves more attention: The paper shows works, but doesn’t explore dynamic rank adaptation. In practice, you could monitor the reconstruction error (computed occasionally on a subset) and adjust mid-training. This adaptive approach could generalize beyond optimizers to any low-rank approximation problem.
论文: 2602.24283 作者: Zhengbo Wang, Jian Liang, Ran He, Zilei Wang, Tieniu Tan 分类: cs.LG, cs.AI, cs.CL
缺口
大语言模型训练依赖Adam、Muon等优化器维护动量状态——梯度及其平方的指数移动平均。这些动量矩阵与模型参数同等规模:一个10亿参数模型用Adam训练时,优化器状态本身就要占12GB显存(float32精度下存储参数、一阶动量、二阶动量三份拷贝)。这道内存墙在预训练阶段最为致命,每一字节显存都是稀缺资源。GaLore和ReLoRA等先前工作尝试低秩训练,但它们聚焦于参数更新而非优化器状态,动量瓶颈依然存在。
增量
此前: 动量状态消耗与模型等量的内存,迫使从业者在优化器质量与规模间二选一。此后: LoRA-Pre将动量压缩到低秩子空间,内存削减8倍的同时性能持平甚至超越全秩方法。
核心洞察简洁有力:动量中使用的指数移动平均(EMA)在数学上等价于通过在线梯度下降训练线性回归器。把动量想象成流式数据仓库。传统优化器(仓库本体)完整存储每笔原始交易(梯度)的全部细节。LoRA-Pre转而维护一个压缩索引——捕获关键模式的低秩投影。“查询引擎”(参数更新)按需从这个紧凑表示中重建所需信息。投影矩阵(和)是索引模式,低秩维度是压缩比,在线梯度流是增量更新协议,无需从头重建即可保持索引时效性。
具体而言,LoRA-Pre不直接存储动量,而是分解为,其中和且。作者证明当你将EMA视为求解时,这种分解自然涌现——这是一个加权最小二乘问题,通过对和的在线梯度下降可得低秩解。
关键概念
指数移动平均即回归问题: Adam计算时,不只是平滑处理——它在求解优化问题。设想你用历史观测预测明日天气,但近期数据权重更高。这就是EMA:权重按指数衰减()的加权平均。作者揭示这等价于最小化——寻找单个向量最佳近似所有历史梯度,按时效性加权。这个重构至关重要,因为最小二乘问题具有充分研究的低秩结构。若梯度接近低维子空间(神经网络中常见),你不需要完整的维——秩为的近似即可。
通过在线梯度流实现低秩分解: LoRA-Pre不直接存储,而是维护使得。但新梯度到来时如何更新和?诀窍是对分解后的目标应用梯度下降:。这产生更新规则: 妙处在于这些更新是局部的——你永远不需要具化完整的矩阵。就像更新压缩JPEG时调整频域系数而非原始像素。在线梯度流确保追踪真实动量,却无需显式计算。
秩效率: 论文显示使用(参数维度的八分之一)即可匹配全秩性能。为何?神经网络梯度因参数更新相关性而呈现低有效秩——各层学习相似特征,产生冗余。LoRA-Pre将动量投影到主导的个方向上利用这点。类比对梯度历史做主成分分析(PCA):多数方差集中在少数特征向量。仅保留前个分量,你丢弃噪声但保留信号。8倍压缩并非任意——这是典型LLM训练中特征值谱衰减的拐点。
专家评审
问题重要性: 这是真实痛点。内存是扩展LLM训练的首要约束,优化器状态是低垂果实——它们必需但非模型本质。受影响群体庞大:任何预训练或微调数十亿参数以上模型的人。但问题在预训练中比微调更严重,后者已有LoRA等方法减少参数量。
方法成熟度: 理论基础(EMA即回归)扎实,但实践实现存疑。作者未讨论如何自适应选择秩——他们测试固定比例。若梯度子空间维度在训练中变化(如早期vs后期阶段)会怎样?论文也缺乏实际运行时间对比。低秩更新或许节省内存但增加矩阵乘法的计算开销。在真实硬件上内存-计算权衡是否有利?实验止步于10亿参数;扩展到700亿+模型(内存最关键处)未经验证。
实验严谨性: 基线公平——GaLore、ReLoRA和标准LoRA是恰当对比。Llama架构是良好测试平台。但预训练实验使用相对小的数据集(论文未明确说明token数)。预训练收敛对超参敏感;他们是否为各方法分别调优学习率,还是用相同调度?微调结果(3.14和6.17点提升)令人印象深刻但缺少误差条或多次运行。一个警示:论文声称”所有模型规模最高性能”但未展示损失曲线——仅最终困惑度。LoRA-Pre是收敛更快,还是仅到达更好终点?
判决: 弱接收——核心思想可靠且针对真实瓶颈,但大规模生产使用的实验验证不完整,关键实践细节(自适应秩选择、实际运行效率)探索不足。
要点总结
将累加器重构为可学习系统: 动量不只是滑动平均——它是正在训练的模型。这个视角解锁表示学习的压缩技术。任何维护指数移动平均的场景(批归一化统计量、强化学习中的策略梯度、卡尔曼滤波器),都可追问:能否分解这个累加器?
流式压缩的在线梯度流: 的更新规则是维护流数据低秩近似的模板。若你构建随时间聚合高维信号的系统(传感器网络、推荐系统),这个模式——增量更新因子而非重算完整矩阵——可直接应用。
内存-计算权衡依赖硬件: 低秩方法省内存但增加浮点运算。在内存受限工作负载(大批量训练)上,权衡倾向压缩。在计算受限工作负载(小批量推理)上,可能不然。部署前务必性能分析,别假设”更少参数=更快”。
秩作为超参数值得更多关注: 论文显示有效,但未探索动态秩适应。实践中可监控重建误差(偶尔在子集上计算)并在训练中调整。这种自适应方法可推广到优化器之外的任何低秩近似问题。