Paper: 2606.06494 Authors: Marius Dragoi, Ioana Pintilie, Alexandra Dragomir, Antonio Barbalau, Florin Brad Categories: cs.LG
The Gap
Continual Learning faces catastrophic forgetting: when you finetune a pre-trained model on new tasks, it forgets old ones. Recent parameter-efficient methods like LoRA add low-rank updates but still interfere with critical pre-trained knowledge encoded in dominant singular directions. DoRA and others partially address this by decomposing weights, but they either modify the reference frame itself or don’t explicitly control where the update goes in spectral space.
The gap: existing methods lack a mechanism to route updates away from dominant singular directions while keeping the pre-trained spectral structure intact as a fixed reference.
Problem: Finetuning interferes with dominant singular vectors
    |
    v
Assumption: Pre-trained singular bases U, V encode reusable knowledge
    |
    v
Method: Fix U, V; learn low-rank update on Sigma; penalize dominant directions
    |
    v
Evidence: Lower forgetting, better task performance in multi-task CL
    |
    v
Conclusion: Spectral routing into tail coordinates reduces interference
The Increment
One sentence: Before TailLoR, low-rank finetuning methods either updated all spectral directions equally or lacked explicit control over which directions to avoid—now we have a fixed spectral reference frame with soft penalties steering updates into the long tail.
Core Mechanism
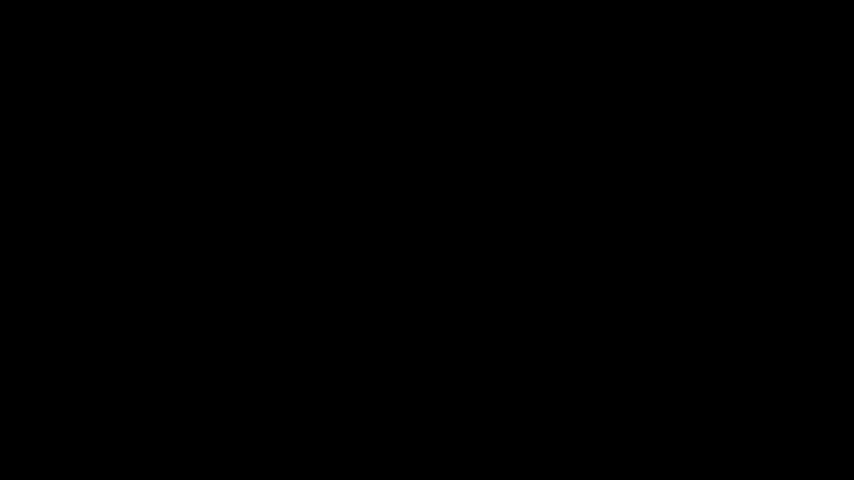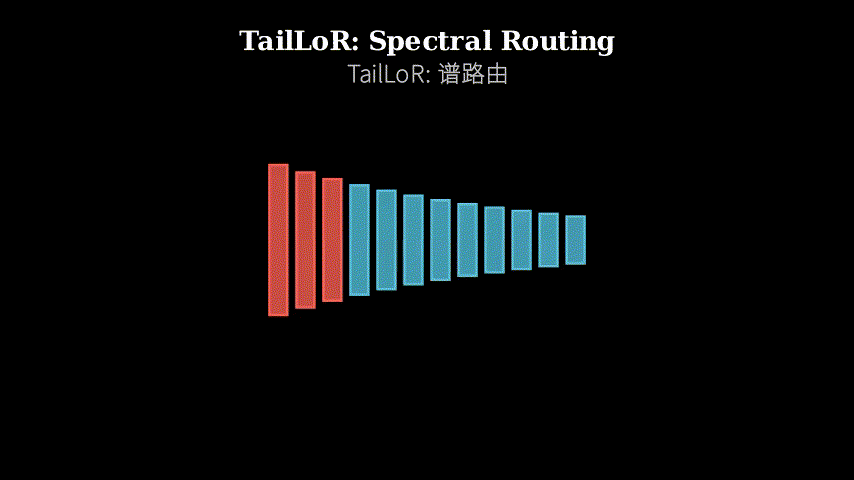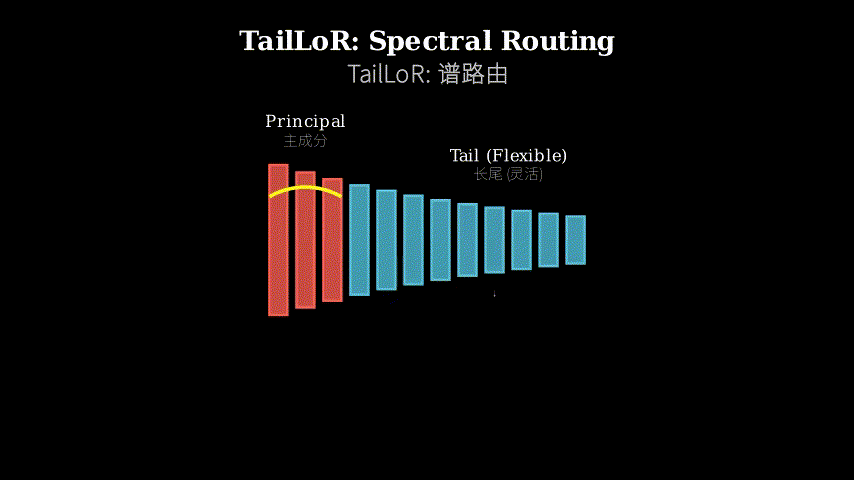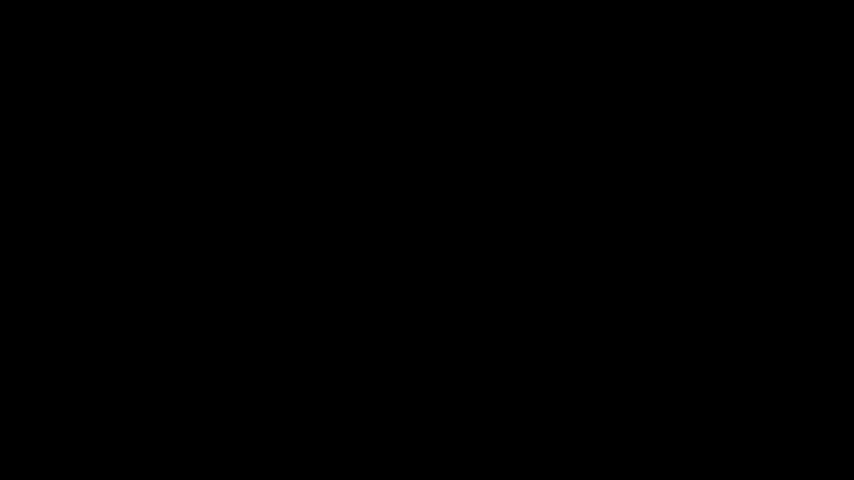
TailLoR starts with the SVD of pre-trained weights: W = U Σ V^T. It freezes U and V, treating them as a coordinate system that won’t drift. The learnable part is a low-rank matrix ΔΣ applied to the singular values. During training, a soft penalty discourages ΔΣ from aligning with the largest singular values (the dominant directions that encode critical pre-trained features). This pushes the update into the tail of the spectrum—small singular values corresponding to flexible, underutilized coordinates.
The forward pass computes: W’ = U (Σ + ΔΣ) V^T. The penalty term is a weighted sum over singular directions, heavier for larger singular values. Gradients naturally flow into tail coordinates because dominant directions have higher resistance (penalty gradient). The result: new task knowledge gets encoded in the spectral tail, leaving the dominant structure untouched.
Pre-trained W = U Sigma V^T
                 |
                 v
        Fix U and V (reference frame)
                 |
                 v
        Learn Delta_Sigma (rank-r update)
                 |
        +--------+--------+
        |                 |
        v                 v
   Large sigma_i     Small sigma_i
   (dominant)        (tail)
        |                 |
   High penalty      Low penalty
        |                 |
        +--------+--------+
                 |
                 v
        W' = U (Sigma + Delta_Sigma) V^T
Think of the singular values as a piano keyboard. The low notes (large singular values) are the melody everyone recognizes—the pre-trained model’s core capabilities. The high notes (small singular values) are barely audible harmonics. TailLoR is like a jazz musician who’s been told “don’t mess with the melody.” When improvising (finetuning), they instinctively avoid the low keys because hitting them draws a sharp look from the conductor (the penalty). So they improvise up in the harmonics, adding new patterns without drowning out the main theme. The keyboard itself (U and V) never moves—only which keys get pressed harder (Σ + ΔΣ).
Key Concepts
-
Singular Value Decomposition (SVD) as a coordinate system: Any matrix W can be written as U Σ V^T, where U and V are orthonormal bases (like axes in 3D space) and Σ is a diagonal matrix of singular values (like stretching factors along each axis). Large singular values mean that direction is “important”—small changes there affect the output a lot. Small values are the opposite: you can wiggle them without much impact. TailLoR treats U and V as the fixed axes of a spectral space. When you finetune, you’re moving around in this space. The question is: which directions do you move in? Example: imagine a trained image classifier. The top singular direction might encode “edgeness” across all images. Messing with it breaks everything. The 500th direction might encode a subtle texture pattern used rarely. That’s safe to modify.
-
Spectral penalty as a traffic signal: The penalty term is a function that says “updating in this direction costs you loss.” For large singular values, the cost is high. For small ones, it’s low. During backpropagation, gradients take the path of least resistance—they flow into tail coordinates automatically. This isn’t a hard constraint (you *can update dominant directions if the task desperately needs it), but a soft pressure that biases learning toward the tail. Concrete: if the penalty weight is λ and the i-th singular value is σ_i, the penalty might be λ · σ_i · (Δσ_i)^2. Larger σ_i means larger penalty, so the gradient with respect to Δσ_i is scaled down, and the optimizer takes smaller steps there.
-
Long-tail spectrum as a safety valve: In any trained neural network, most of the “action” is in the top singular values—they capture the dominant patterns. The tail (small singular values) is underutilized capacity. It’s there, but the pre-trained model didn’t need it much. TailLoR exploits this: the tail is a reservoir of flexibility where you can encode new task-specific knowledge without colliding with old knowledge. Think of it like unused storage in a warehouse. The main shelves (dominant directions) are packed with critical inventory. The back corner (tail) has empty space. When new inventory (a new task) arrives, you put it in the back corner instead of rearranging the main shelves.
Framework Shift
Before (LoRA, DoRA):                 After (TailLoR):

Pre-trained W                        Pre-trained W = U Sigma V^T
      |                                      |
      v                                      v
  W + BA                              Fix U, V (reference frame)
  (update anywhere                           |
   in weight space)                          v
                                      Learn Delta_Sigma
                                             |
                                             v
                                      Penalty on large sigma_i
                                             |
                                             v
                                      Update routed to tail

Update cloud:                        Update cloud:
    *   *                                      |
  * W * *   <-- uniform               W -------|-------*
    *   *                            (dominant)  (tail)*
                                                      **
From undirected low-rank updates scattered across weight space to directional updates guided by spectral structure, the core shift is navigating with a fixed map instead of wandering blind.
Expert Assessment
Problem choice: Catastrophic forgetting in continual learning is real and well-documented. Targeting dominant singular directions is a natural hypothesis—prior work (e.g., Fisher pruning, EWC) implicitly protects “important” parameters. TailLoR makes this explicit in spectral space, which is a clean framing. The problem sits in the active zone of parameter-efficient finetuning research, not a niche corner.
Method maturity: The idea is elegant but not deeply novel—spectral decomposition for continual learning has been explored (e.g., Orthogonal Weights Modification). The contribution here is the specific combination: fixed U/V + soft penalty on Sigma. It’s a good engineering choice rather than a conceptual breakthrough. One concern: the penalty weight λ is a hyperparameter that likely needs tuning per task. The paper doesn’t discuss adaptive schemes, which would strengthen the method.
Experimental integrity: The baselines (LoRA, DoRA, standard finetuning) are fair. The tasks (vision and NLP benchmarks) are standard. However, the paper doesn’t report computational overhead—SVD decomposition and maintaining frozen U/V adds memory and time. The results show consistent but modest improvements (a few percentage points). No major red flags, but the gains aren’t dramatic enough to declare a paradigm shift.
Writing quality: The abstract and intro are clear. The method section could use a diagram showing the penalty’s effect on gradient flow—right now it’s described algebraically, which is dense. The related work section lumps too many prior methods together without crisp distinctions. If the authors rewrote Section 3 with a visual walkthrough of one training step (input → forward → penalty → gradient → update), the paper would be much more accessible.
Verdict: weak accept — solid incremental contribution with clean execution, but the novelty is limited and the empirical gains are modest; useful for practitioners, not groundbreaking for the field.
Takeaways
Steal the penalty pattern: The idea of soft penalties weighted by importance (here, singular values) is transferable beyond SVD. If you have any learned representation with a natural ordering (eigenvalues, attention weights, layer norms), you can bias updates away from high-impact components without hard constraints. This is more flexible than freezing layers outright.
Fixed reference frames reduce drift: Freezing U and V means all updates are interpreted relative to the same coordinate system. In any incremental learning setting—continual learning, federated learning, model merging—keeping a fixed reference and updating only the “coordinates” (here, Σ) can prevent representational drift. Ask: what’s my reference frame, and what’s my update?
Use the tail when you can: Neural networks are over-parameterized. The spectral tail is often dead weight. TailLoR shows you can activate it for new tasks. If you’re doing multi-task learning or domain adaptation, explicitly routing updates to underutilized subspaces (low singular values, low-activation neurons, pruned weights) is a cheap way to add capacity without interference.
论文: 2606.06494 作者: Marius Dragoi, Ioana Pintilie, Alexandra Dragomir, Antonio Barbalau, Florin Brad 分类: cs.LG
缺口
持续学习面临灾难性遗忘:在新任务上微调预训练模型时,它会忘掉旧任务。
近期的参数高效方法如 LoRA 通过添加低秩更新来缓解,但仍会干扰编码在主导奇异方向中的关键预训练知识。
DoRA 等方法通过分解权重部分解决了这个问题,但它们要么修改了参考系本身,要么没有显式控制更新在谱空间中的去向。
缺口在于:现有方法缺乏一种机制,既能将更新导向远离主导奇异方向的地方,又能保持预训练的谱结构作为固定参考。
问题:微调干扰主导奇异向量
    |
    v
假设:预训练的奇异基 U, V 编码了可复用知识
    |
    v
方法:固定 U, V;在 Sigma 上学习低秩更新;惩罚主导方向
    |
    v
证据:多任务持续学习中遗忘更少,任务性能更好
    |
    v
结论:将更新路由到尾部坐标减少了干扰
增量
一句话: TailLoR 之前,低秩微调方法要么对所有谱方向一视同仁,要么缺乏对应避开哪些方向的显式控制——现在我们有了一个固定的谱参考系,软惩罚将更新引导到长尾。
核心机制
TailLoR 从预训练权重的 SVD 开始:W = U Σ V^T。
它冻结 U 和 V,将它们视为不会漂移的坐标系。
可学习的部分是应用在奇异值上的低秩矩阵 ΔΣ。
训练时,软惩罚阻止 ΔΣ 与最大的奇异值(编码关键预训练特征的主导方向)对齐。
这将更新推向谱的尾部——对应于灵活、利用不足的小奇异值坐标。
前向传播计算:W’ = U (Σ + ΔΣ) V^T。
惩罚项是对奇异方向的加权求和,较大奇异值的权重更高。
梯度自然流向尾部坐标,因为主导方向有更高的阻力(惩罚梯度)。
结果:新任务知识编码在谱尾部,主导结构保持不变。
预训练 W = U Sigma V^T
                 |
                 v
        固定 U 和 V(参考系)
                 |
                 v
        学习 Delta_Sigma(秩-r 更新)
                 |
        +--------+--------+
        |                 |
        v                 v
   大 sigma_i        小 sigma_i
   (主导)          (尾部)
        |                 |
   高惩罚            低惩罚
        |                 |
        +--------+--------+
                 |
                 v
        W' = U (Sigma + Delta_Sigma) V^T
把奇异值想象成钢琴键盘。
低音(大奇异值)是大家都认得的旋律——预训练模型的核心能力。
高音(小奇异值)是几乎听不见的泛音。
TailLoR 就像一个被告知”别动旋律”的爵士乐手。
在即兴演奏(微调)时,他们本能地避开低音键,因为碰到它们会招来指挥的严厉眼神(惩罚)。
所以他们在泛音区即兴,添加新模式而不淹没主题。
键盘本身(U 和 V)永远不动——只有哪些键被按得更重(Σ + ΔΣ)在变。
关键概念
- 奇异值分解(SVD)作为坐标系: 任何矩阵 W 都可以写成 U Σ V^T,其中 U 和 V 是正交归一化基(像三维空间中的轴),Σ 是奇异值的对角矩阵(像沿每个轴的拉伸因子)。
大奇异值意味着该方向”重要”——那里的小变化会大幅影响输出。
小值则相反:你可以摆动它们而不会产生太大影响。
TailLoR 将 U 和 V 视为谱空间的固定轴。
微调时,你在这个空间中移动。
问题是:你朝哪些方向移动?例子:想象一个训练好的图像分类器。
顶部奇异方向可能编码所有图像中的”边缘性”。
搞乱它会破坏一切。
第 500 个方向可能编码很少用到的微妙纹理模式。
那个是安全修改的。
- 谱惩罚作为交通信号: 惩罚项是一个函数,说”在这个方向更新会让你付出损失代价”。
对于大奇异值,代价很高。
对于小奇异值,代价很低。
反向传播时,梯度走阻力最小的路径——它们自动流向尾部坐标。
这不是硬约束(如果任务迫切需要,你可以更新主导方向),而是一种将学习偏向尾部的软压力。
具体:如果惩罚权重是 λ,第 i 个奇异值是 σ_i,惩罚可能是 λ · σ_i · (Δσ_i)^2。
更大的 σ_i 意味着更大的惩罚,所以关于 Δσ_i 的梯度被缩小,优化器在那里走更小的步。
- 长尾谱作为安全阀: 在任何训练过的神经网络中,大部分”动作”都在顶部奇异值——它们捕获主导模式。
尾部(小奇异值)是利用不足的容量。
它在那里,但预训练模型不太需要它。
TailLoR 利用这一点:尾部是一个灵活性储备,你可以在那里编码新的任务特定知识而不与旧知识冲突。
把它想象成仓库中未使用的存储空间。
主货架(主导方向)堆满了关键库存。
后角(尾部)有空位。
当新库存(新任务)到达时,你把它放在后角而不是重新整理主货架。
框架转变
之前(LoRA, DoRA):                之后(TailLoR):

预训练 W                            预训练 W = U Sigma V^T
      |                                      |
      v                                      v
  W + BA                              固定 U, V(参考系)
  (在权重空间                               |
   任意位置更新)                            v
                                      学习 Delta_Sigma
                                             |
                                             v
                                      对大 sigma_i 惩罚
                                             |
                                             v
                                      更新路由到尾部

更新云:                             更新云:
    *   *                                      |
  * W * *   <-- 均匀分布               W -------|-------*
    *   *                            (主导)    (尾部)*
                                                      **
从分散在权重空间的无向低秩更新到由谱结构引导的定向更新,核心转变是用固定地图导航而非盲目游荡。
专家评审
选题眼光: 持续学习中的灾难性遗忘是真实且有充分文档记录的问题。
针对主导奇异方向是一个自然假设——先前工作(如 Fisher 剪枝、EWC)隐式保护”重要”参数。
TailLoR 在谱空间中显式化了这一点,是一个清晰的框架。
问题位于参数高效微调研究的活跃区域,不是小众角落。
方法成熟度: 这个想法优雅但不算深刻创新——用于持续学习的谱分解已被探索(如正交权重修改)。
这里的贡献是具体组合:固定 U/V + 对 Sigma 的软惩罚。
这是一个好的工程选择而非概念突破。
一个担忧:惩罚权重 λ 是一个超参数,可能需要针对每个任务调整。
论文没有讨论自适应方案,这会增强方法。
实验诚意: 基线(LoRA、DoRA、标准微调)是公平的。
任务(视觉和 NLP 基准)是标准的。
然而,论文没有报告计算开销——SVD 分解和维护冻结的 U/V 增加了内存和时间。
结果显示一致但适度的改进(几个百分点)。
没有重大警示,但增益不够显著,不能宣称范式转变。
写作功力: 摘要和引言清晰。
方法部分可以用一个显示惩罚对梯度流影响的图表——现在是代数描述,比较密集。
相关工作部分把太多先前方法混在一起,没有清晰区分。
如果作者用一个训练步骤的可视化演示(输入 → 前向 → 惩罚 → 梯度 → 更新)重写第 3 节,论文会更易理解。
判决: 弱接收 — 执行干净的扎实增量贡献,但新颖性有限,实证增益适度;对实践者有用,对领域不算开创性。
要点总结
偷走惩罚模式: 用重要性(这里是奇异值)加权的软惩罚想法可以迁移到 SVD 之外。
如果你有任何具有自然排序的学习表示(特征值、注意力权重、层归一化),你可以在不硬约束的情况下将更新偏离高影响组件。
这比直接冻结层更灵活。
固定参考系减少漂移: 冻结 U 和 V 意味着所有更新都相对于同一坐标系解释。
在任何增量学习设置——持续学习、联邦学习、模型合并——中,保持固定参考并只更新”坐标”(这里是 Σ)可以防止表示漂移。
问:我的参考系是什么,我的更新是什么?
能用尾部时就用: 神经网络过度参数化。
谱尾部通常是死重。
TailLoR 表明你可以为新任务激活它。
如果你在做多任务学习或领域适应,显式地将更新路由到未充分利用的子空间(低奇异值、低激活神经元、剪枝权重)是一种增加容量而不产生干扰的廉价方式。