Paper: 2604.28181 Authors: Tao Ge, Baolin Peng, Hao Cheng, Jianfeng Gao Categories: cs.AI, cs.CL, cs.LG
The Gap
Existing agent training relies on short, context-free tasks. You ask an agent to “book a flight” or “summarize this document,” but real productivity work spans weeks, depends on accumulated context in your filesystem, and requires coordinating across multiple artifacts. Prior synthetic data methods generate isolated task episodes without the grounding environment where real work happens — your messy Downloads folder, that half-finished presentation from last week, the email thread buried in your inbox.
The boundary: we can train agents on toy tasks, but we can’t simulate the month-long project where success depends on remembering what’s in /projects/Q2_launch/drafts/ and coordinating with three colleagues across a dozen files.
Problem: Agents fail at long-horizon productivity work
   |
   v
Gap: No training data grounded in realistic user environments
   |
   v
Assumption: Synthetic computers + long simulations = rich training signal
   |
   v
Method: Generate 1000 computers -> Run month-long agent simulations
   |
   v
Evidence: 8+ hours runtime, 2000+ turns, performance gains in/out-of-domain
   |
   v
Conclusion: Scalable substrate for agent self-improvement
The Increment
One sentence: Before this paper, synthetic agent training happened in sterile task bubbles; after, we can generate entire user worlds with realistic filesystems and run month-long productivity simulations at scale.
Core Mechanism
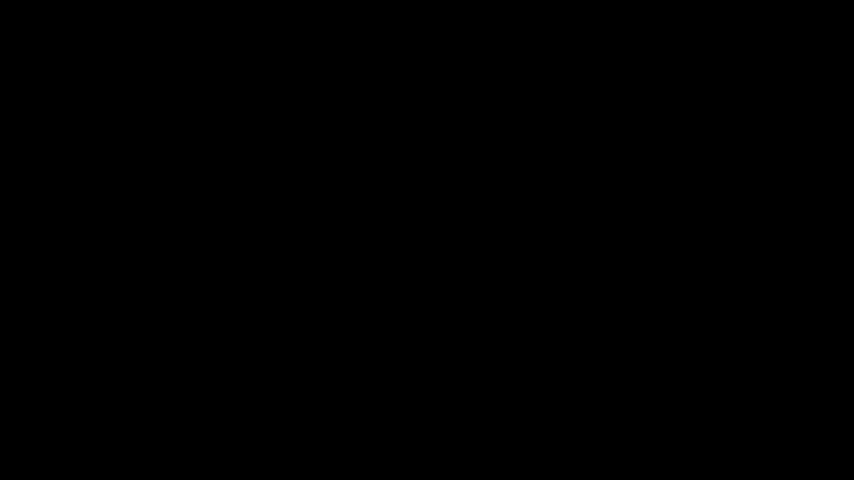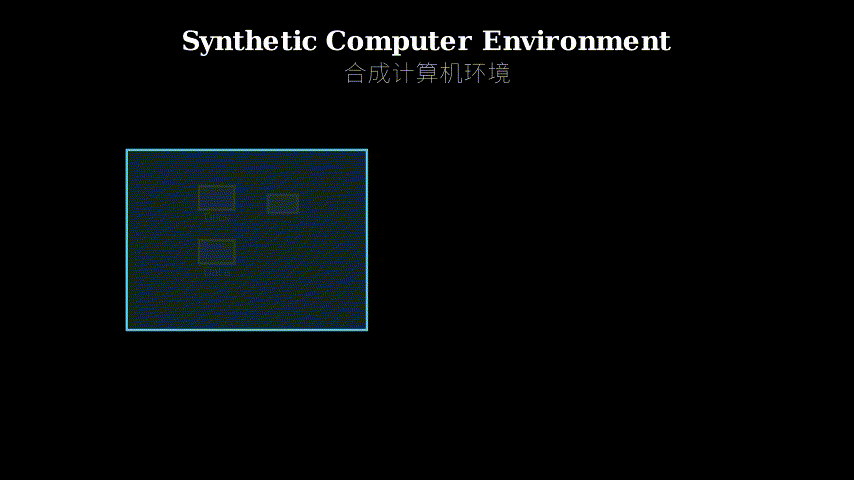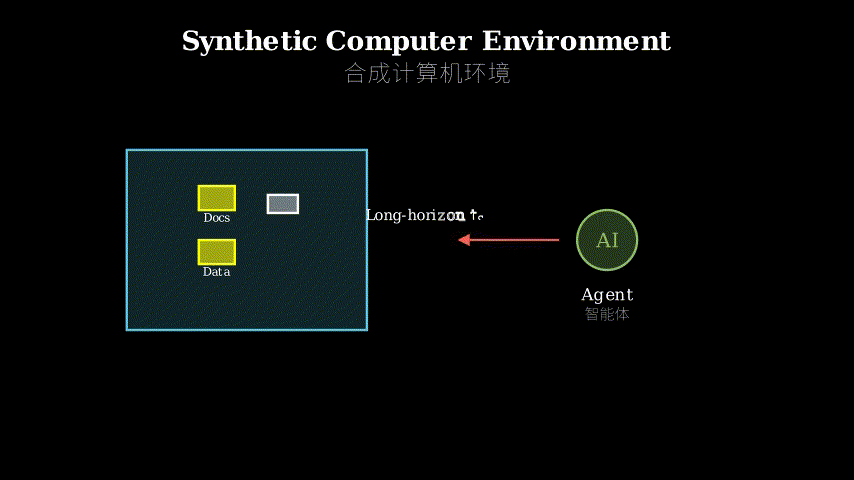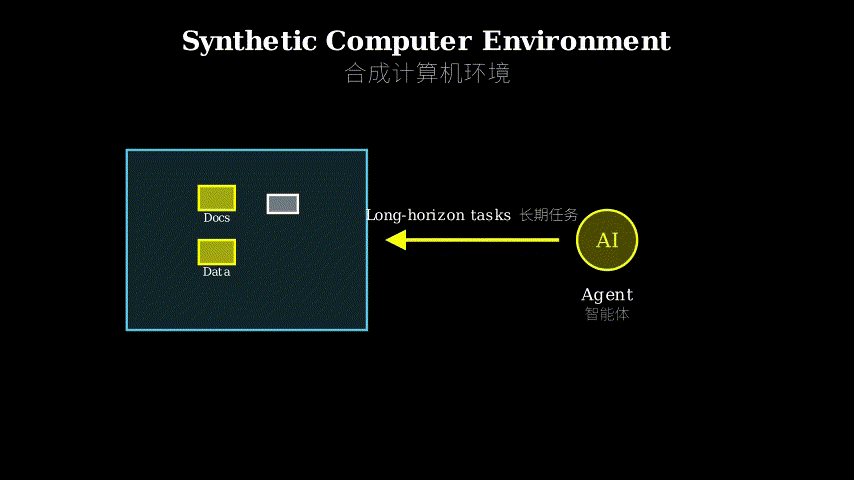
The system has two phases. First, synthetic computer generation: create a realistic user persona, then populate a filesystem with hierarchical folders and content-rich artifacts (Word docs, Excel sheets, PowerPoints) that reflect that user’s work context. Think marketing manager with /campaigns/, /budgets/, /competitor_analysis/ folders, each containing plausible documents.
Second, long-horizon simulation: one agent (the “objective creator”) examines the synthetic computer and generates a productivity goal requiring multiple deliverables and roughly a month of human work. Another agent (the “worker”) then acts as that user, navigating the filesystem for context, coordinating with simulated collaborators, editing documents, creating new artifacts, until the objective is complete. This runs for 8+ hours of agent time, spanning 2000+ turns.
Synthetic Computer Generation:
   Persona -> Folder Structure -> Content Artifacts
      |            |                    |
      v            v                    v
   [Marketing] [/campaigns/]  [budget_Q2.xlsx]
                [/reports/]   [competitor_brief.docx]
                              [deck_draft_v3.pptx]

Long-Horizon Simulation:
   Objective Creator                Worker Agent
         |                               |
         v                               v
   "Launch Q2 campaign"  ->  [Navigate filesystem]
   "Need: deck, budget,       [Read context docs]
    email draft"              [Edit artifacts]
                              [Coordinate w/ team]
                              [Produce deliverables]
                                      |
                                      v
                              [2000+ turns, 8+ hrs]
Think of it like a flight simulator for productivity work. Real pilots train in simulators that replicate cockpit layouts, instrument panels, and flight conditions. Here, the “cockpit” is a user’s computer environment — the filesystem is the instrument panel, documents are the controls, and the “flight conditions” are the messy, context-dependent nature of real work. You don’t train a pilot by having them press random buttons; you simulate realistic scenarios where they must coordinate multiple systems over hours. Similarly, this method doesn’t train agents on isolated tasks — it drops them into a realistic user world and makes them complete a month-long project by navigating accumulated context, just like a real user would.
Key Concepts
-
Synthetic Computer: Not just a folder tree, but a coherent user world. If the persona is a product manager at a SaaS company, the filesystem should contain
/roadmaps/,/user_research/,/sprint_planning/with realistic documents inside — not random Lorem Ipsum, but plausible content like “Q3 Feature Prioritization” with actual feature names, user quotes, and priority scores. The computer is “synthetic” because it’s generated, but “realistic” because it reflects how real professionals organize their work. The key insight: productivity work is strongly conditioned on environment. An agent can’t write a quarterly report without knowing what’s in/reports/2024_Q1/or what the team discussed in/meeting_notes/. -
Long-Horizon Simulation: Most agent benchmarks are short: 10 turns, 5 minutes. This paper runs simulations for 2000+ turns over 8+ hours of agent runtime, equivalent to weeks of human work compressed. Why does this matter? Because real productivity objectives require sustained context. You can’t “launch a marketing campaign” in 10 turns — you need to draft the deck, get feedback, revise, coordinate with design, update the budget, write the email announcement. Each step depends on prior steps. Long-horizon simulation forces the agent to maintain context, recover from mistakes, and coordinate across artifacts, generating training signal that short tasks can’t provide.
-
Experiential Learning Signal: The simulation produces trajectories showing how an agent navigates a complex environment to achieve a goal. These trajectories become training data. Unlike supervised learning (here’s input, here’s correct output), experiential learning captures the process: the agent tried reading
/old_campaigns/2023_launch/for inspiration, realized the budget format changed, navigated to/templates/, found the new format, then applied it. This process-level signal teaches not just what to do, but how to explore, recover, and adapt — skills that matter for long-horizon work.
Framework Shift
Before (mainstream approach):        After (this paper):

Task: "Book a flight"                Synthetic Computer:
  |                                    /home/user/
  v                                      /work/
Agent -> [Isolated action]  ->          /personal/
         [No context]                   /projects/Q2_launch/
         [Short episode]                  /drafts/
                                          /final/
Result: Works on toy tasks,              /meeting_notes/
        fails on real work
                                  Objective: "Complete Q2 launch"
                                    |
                                    v
                                  Agent -> [Navigate filesystem]
                                           [Read context]
                                           [Coordinate artifacts]
                                           [2000+ turns]

                                  Result: Learns grounded,
                                          long-horizon behavior
From isolated task episodes to grounded environment simulations, the core shift is training agents in the context where real work happens, not in a vacuum.
Expert Assessment
Problem choice: This is a real gap. The field has been stuck on short-horizon benchmarks (WebShop, ALFWorld) that don’t capture how professionals actually work. The insight that productivity is environment-dependent is obvious in hindsight but underexplored. The timing is right — we have capable enough base models to run these long simulations without collapsing immediately.
Method maturity: The approach is more engineering than algorithmic novelty, which is fine. The clever part is recognizing that persona abundance (billions of possible users) makes this scalable in principle. The brute force part is running 8-hour simulations per computer. I’d want to see ablations: does the realism of the synthetic computer matter, or would random folder structures work? How much does simulation length contribute vs. environment complexity?
Experimental integrity: The paper shows in-domain and out-of-domain improvements, which is good. But the baselines are unclear — what are they comparing against? Agents trained on short tasks? No training? The 1,000 computers is a proof-of-concept scale, not production scale. I’d want to see learning curves: does performance keep improving at 10K computers? 100K? The claim about “billions of synthetic user worlds” is aspirational, not demonstrated.
Writing quality: The abstract oversells (“foundational substrate”) before showing the evidence. The method section is clear, but the results section is thin — we get “significant improvements” without detailed breakdowns. The paper would benefit from a failure analysis: what kinds of objectives do agents still fail at after this training? Where does the method hit diminishing returns?
Verdict: weak accept — the core idea (synthetic computers + long simulations) is sound and addresses a real gap, but the execution feels like an early-stage proof-of-concept rather than a mature system. The experimental validation is promising but not thorough enough to justify the strong claims about scalability and foundational impact.
Takeaways
Steal the environment-first framing: If you’re building agents for any domain with accumulated context (customer support with ticket history, software engineering with codebases, research with paper libraries), don’t train on isolated tasks. Generate realistic environments first, then simulate work within them. The environment is not just context — it’s the substrate that makes long-horizon behavior possible.
Simulation length matters: The 2000+ turn, 8+ hour simulations aren’t just longer — they force qualitatively different behavior. Short tasks let agents get away with pattern matching; long tasks require memory, error recovery, and planning. If your domain has multi-step workflows, push simulation length until you see agents developing these capabilities.
Persona-conditioned generation scales: The insight that you can generate billions of diverse user worlds by varying personas is transferable. If you need diverse training data in any domain with user-specific context (personalized tutoring, custom workflows, individual preferences), condition generation on persona attributes rather than trying to manually create diversity.
论文: 2604.28181 作者: Tao Ge, Baolin Peng, Hao Cheng, Jianfeng Gao 分类: cs.AI, cs.CL, cs.LG
缺口
现有的智能体训练依赖短小的、无上下文的任务。
你让智能体”订机票”或”总结这份文档”,但真实的生产力工作跨越数周,依赖文件系统中积累的上下文,需要协调多个文件。
之前的合成数据方法生成孤立的任务片段,没有真实工作发生的基础环境——你乱糟糟的下载文件夹、上周写到一半的演示文稿、埋在收件箱里的邮件线程。
边界在于:我们能在玩具任务上训练智能体,但无法模拟那种长达一个月的项目,成功取决于记住 /projects/Q2_launch/drafts/ 里有什么,以及跨十几个文件与三位同事协调。
问题:智能体在长周期生产力工作上失败
   |
   v
缺口:没有基于真实用户环境的训练数据
   |
   v
假设:合成计算机 + 长周期模拟 = 丰富训练信号
   |
   v
方法:生成 1000 台计算机 -> 运行月度智能体模拟
   |
   v
证据:8+ 小时运行时间,2000+ 轮次,域内外性能提升
   |
   v
结论:智能体自我改进的可扩展基底
增量
一句话: 这篇论文之前,合成智能体训练发生在无菌的任务气泡里;之后,我们能生成带有真实文件系统的完整用户世界,并大规模运行月度生产力模拟。
核心机制
系统分两个阶段。
第一阶段是合成计算机生成:创建一个真实的用户画像,然后填充一个文件系统,包含层级文件夹和内容丰富的文件(Word 文档、Excel 表格、PowerPoint 演示),反映该用户的工作上下文。
想象一个市场经理,有 /campaigns/、/budgets/、/competitor_analysis/ 文件夹,每个文件夹里都有合理的文档。
第二阶段是长周期模拟:一个智能体(“目标创建者”)检查这台合成计算机,生成一个需要多个交付物、大约相当于一个月人类工作量的生产力目标。
另一个智能体(“工作者”)扮演该用户,浏览文件系统获取上下文,与模拟的协作者协调,编辑文档,创建新文件,直到目标完成。
这个过程运行 8+ 小时的智能体时间,跨越 2000+ 轮次。
合成计算机生成:
   画像 -> 文件夹结构 -> 内容文件
     |         |            |
     v         v            v
  [市场部] [/campaigns/]  [budget_Q2.xlsx]
           [/reports/]    [competitor_brief.docx]
                          [deck_draft_v3.pptx]

长周期模拟:
   目标创建者                工作者智能体
       |                         |
       v                         v
  "启动 Q2 活动"  ->  [浏览文件系统]
  "需要:演示稿、       [阅读上下文文档]
   预算、邮件草稿"      [编辑文件]
                       [与团队协调]
                       [产出交付物]
                             |
                             v
                       [2000+ 轮次,8+ 小时]
把它想象成生产力工作的飞行模拟器。
真实飞行员在模拟器中训练,模拟器复制驾驶舱布局、仪表盘和飞行条件。
这里,“驾驶舱”是用户的计算机环境——文件系统是仪表盘,文档是控制器,“飞行条件”是真实工作的混乱、依赖上下文的本质。
你不会让飞行员随机按按钮来训练;你模拟真实场景,让他们在数小时内协调多个系统。
同样,这个方法不在孤立任务上训练智能体——它把智能体扔进一个真实的用户世界,让它通过浏览积累的上下文来完成一个月的项目,就像真实用户那样。
关键概念
- 合成计算机: 不只是一个文件夹树,而是一个连贯的用户世界。
如果画像是一家 SaaS 公司的产品经理,文件系统应该包含 /roadmaps/、/user_research/、/sprint_planning/,里面有真实的文档——不是随机的 Lorem Ipsum,而是合理的内容,比如”Q3 功能优先级”,包含实际的功能名称、用户引用和优先级分数。
计算机是”合成的”因为它是生成的,但”真实的”因为它反映了真实专业人士如何组织工作。
关键洞察:生产力工作强烈依赖环境。
智能体无法在不知道 /reports/2024_Q1/ 里有什么或团队在 /meeting_notes/ 里讨论了什么的情况下写季度报告。
- 长周期模拟: 大多数智能体基准测试很短:10 轮,5 分钟。
这篇论文运行 2000+ 轮、8+ 小时智能体运行时间的模拟,相当于压缩的数周人类工作。
为什么这很重要?因为真实的生产力目标需要持续的上下文。
你无法在 10 轮内”启动营销活动”——你需要起草演示稿、获得反馈、修订、与设计协调、更新预算、写公告邮件。
每一步都依赖前面的步骤。
长周期模拟迫使智能体维护上下文、从错误中恢复、跨文件协调,生成短任务无法提供的训练信号。
- 经验学习信号: 模拟产生轨迹,展示智能体如何在复杂环境中导航以实现目标。
这些轨迹成为训练数据。
与监督学习(这是输入,这是正确输出)不同,经验学习捕获过程:智能体尝试阅读 /old_campaigns/2023_launch/ 寻找灵感,意识到预算格式变了,导航到 /templates/,找到新格式,然后应用它。
这种过程级信号不仅教会做什么,还教会如何探索、恢复和适应——这些技能对长周期工作很重要。
框架转变
之前(主流方法):              之后(本文方法):

任务:"订机票"                 合成计算机:
  |                              /home/user/
  v                                /work/
智能体 -> [孤立动作]  ->            /personal/
         [无上下文]                 /projects/Q2_launch/
         [短片段]                     /drafts/
                                     /final/
结果:在玩具任务上有效,              /meeting_notes/
      在真实工作上失败
                                目标:"完成 Q2 启动"
                                  |
                                  v
                                智能体 -> [浏览文件系统]
                                         [阅读上下文]
                                         [协调文件]
                                         [2000+ 轮次]

                                结果:学习基于环境的
                                      长周期行为
从孤立任务片段到基于环境的模拟,核心转变是在真实工作发生的上下文中训练智能体,而不是在真空中。
专家评审
选题眼光: 这是真缺口。
该领域一直困在短周期基准测试(WebShop、ALFWorld)上,无法捕捉专业人士的实际工作方式。
生产力依赖环境这个洞察事后看来显而易见,但探索不足。
时机合适——我们有足够强大的基础模型来运行这些长模拟而不会立即崩溃。
方法成熟度: 这个方法更多是工程而非算法创新,这没问题。
巧妙之处在于认识到画像丰富性(数十亿可能的用户)使这在原则上可扩展。
蛮力部分是每台计算机运行 8 小时模拟。
我想看消融实验:合成计算机的真实性重要吗,还是随机文件夹结构也行?模拟长度贡献多少 vs 环境复杂度?
实验诚意: 论文展示了域内和域外改进,这很好。
但基线不清楚——他们在与什么比较?在短任务上训练的智能体?没有训练?1000 台计算机是概念验证规模,不是生产规模。
我想看学习曲线:在 10K 台计算机时性能是否继续提升?100K 呢?关于”数十亿合成用户世界”的说法是愿景,不是已证明的。
写作功力: 摘要在展示证据之前过度推销(“基础性基底”)。
方法部分清晰,但结果部分单薄——我们得到”显著改进”而没有详细分解。
论文会受益于失败分析:经过这种训练后,智能体在什么类型的目标上仍然失败?方法在哪里遇到收益递减?
判决: 弱接收——核心想法(合成计算机 + 长模拟)是合理的,解决了真实缺口,但执行感觉像早期概念验证而非成熟系统。
实验验证有希望但不够彻底,无法证明关于可扩展性和基础性影响的强烈主张。
要点总结
偷走环境优先的框架: 如果你在为任何有积累上下文的领域构建智能体(有工单历史的客户支持、有代码库的软件工程、有论文库的研究),不要在孤立任务上训练。
先生成真实环境,然后在其中模拟工作。
环境不只是上下文——它是使长周期行为成为可能的基底。
模拟长度很重要: 2000+ 轮、8+ 小时的模拟不只是更长——它们强制产生质的不同行为。
短任务让智能体侥幸通过模式匹配;长任务需要记忆、错误恢复和规划。
如果你的领域有多步骤工作流,推动模拟长度直到你看到智能体发展出这些能力。
基于画像的生成可扩展: 通过变化画像可以生成数十亿多样化用户世界的洞察是可迁移的。
如果你在任何有用户特定上下文的领域需要多样化训练数据(个性化辅导、定制工作流、个人偏好),基于画像属性来条件生成,而不是试图手动创建多样性。