Paper: 2603.02193 Authors: Richard Freinschlag, Timo Bertram, Erich Kobler, Andreas Mayr, Günter Klambauer Categories: cs.LG, cs.AI, stat.ML
The Gap
Recurrent Reasoning Models (RRMs) like HRM and TRM can solve structured puzzles with just 2M parameters — way leaner than LLMs. But they have a dumb blindspot: swap “red” with “blue” in a puzzle, and the model treats it as a completely new problem. The fix? Generate thousands of color-permuted training examples. It works, but it’s wasteful — you’re teaching the same logical structure over and over with different paint jobs.
The core issue: RRMs learn symbol symmetries implicitly through brute-force data augmentation rather than encoding the mathematical fact that permuting symbols shouldn’t change the solution. This limits generalization — train on 9x9 Sudoku, and the model can’t extrapolate to 16x16 or 25x25 grids because it never learned that “the identity of symbols doesn’t matter, only their relationships.”
Problem: RRMs can't generalize across symbol permutations
   |
   v
Assumption: Symbol identity is irrelevant to logical structure
   |
   v
Method: Enforce permutation equivariance in architecture
   |
   v
Evidence: Generalize 9x9 -> 25x25 Sudoku, less augmentation needed
   |
   v
Conclusion: Explicit symmetry > implicit learning via data
The Increment
One sentence: Before, neural reasoners learned “red≠blue” through exhaustive examples; now they know “red=blue=any symbol” by construction.
Core Mechanism
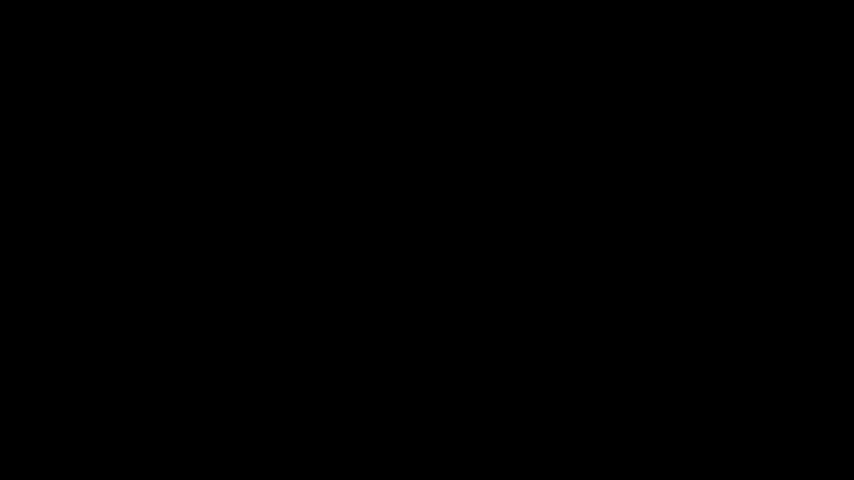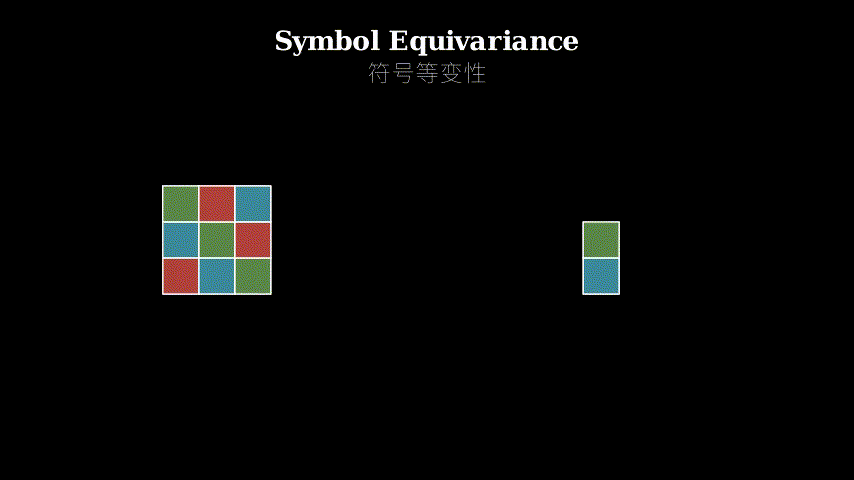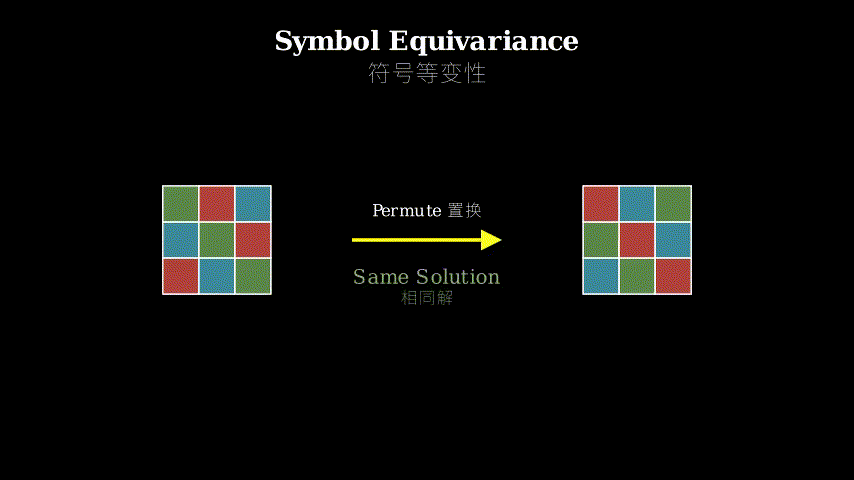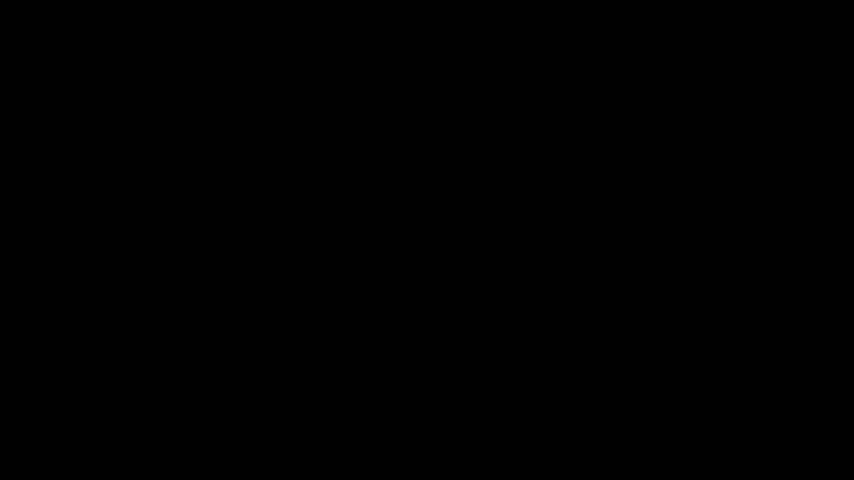
SE-RRM replaces standard neural layers with symbol-equivariant layers that guarantee: if you permute input symbols, the output permutes identically. The architecture has three parts: (1) a symbol-equivariant encoder that maps each symbol to a learned embedding, (2) recurrent reasoning layers where each step refines the solution using equivariant operations, and (3) a decoder that outputs symbol probabilities while preserving permutation structure.
The key trick is in how information flows. Standard layers mix symbol embeddings arbitrarily — “red” and “blue” can interact in ways that break if you swap their labels. SE-RRM layers use operations that treat all symbols symmetrically: pooling across symbol dimensions, broadcasting, and element-wise operations that don’t “see” which symbol is which. Think of it like processing a deck of cards where you can count suits and compare ranks, but you’re colorblind to whether hearts are red or purple.
The recurrent structure iteratively refines a “belief state” over possible solutions. Each reasoning step takes the current belief, applies equivariant transformations (like checking constraints or propagating information across grid cells), and outputs an updated belief. Because every operation respects symbol permutations, the entire reasoning chain is equivariant — swap symbols at the input, and the reasoning trace swaps identically.
Input Grid          Symbol-Equivariant         Recurrent Reasoning        Output
(symbols)           Encoder                    (iterative refinement)     (solution)

[1 _ 3]            [embed(1)]                 Step 1: Check constraints
[_ 2 _]    --->    [embed(2)]     --->        Step 2: Propagate info     --->  [1 4 3]
[3 _ 1]            [embed(3)]                 Step 3: Update beliefs           [4 2 5]
                   [embed(4)]                 ...                              [3 5 1]
                   [embed(5)]                 Step T: Converge
                        |
                        v
                   (all operations
                    treat symbols
                    symmetrically)
Think of SE-RRM like a referee who enforces rules without caring about team jerseys. The referee (model) sees players (symbols) making moves (constraints), but whether Team A wears red or blue is irrelevant — the rules apply the same. The encoder is like assigning each team a jersey number, the recurrent layers are like tracking game state (who can move where), and the decoder is like announcing the final score. Crucially, if you swap jersey colors mid-game, the referee’s decisions swap identically because they’re based on positions and rules, not colors. This is what “equivariance” means: the structure of reasoning is independent of symbol labels.
Key Concepts
-
Permutation Equivariance: Imagine you have a function that takes a list of numbers and outputs a list. The function is “permutation equivariant” if shuffling the input causes the output to shuffle in exactly the same way. Example: f([3,1,2]) = [6,2,4], then f([1,2,3]) must equal [2,4,6] — the outputs follow the same shuffle as inputs. For reasoning tasks, this means “if I swap ‘red’ and ‘blue’ in the puzzle, the solution swaps ‘red’ and ‘blue’ in the answer.” Standard neural nets don’t guarantee this — they might learn it from data, but SE-RRM enforces it architecturally, so it’s free.
-
Data Augmentation Tax: When your model doesn’t understand a symmetry, you pay a “tax” by generating augmented training data. For symbol permutations, if you have 9 symbols, there are 9! = 362,880 possible permutations. You can’t generate all of them, so you sample a few thousand and hope the model generalizes. This is expensive (more data to store and process) and incomplete (you never cover all permutations). SE-RRM eliminates this tax by building the symmetry into the architecture — one training example implicitly covers all permutations.
-
Extrapolation vs Interpolation: Interpolation is like filling in a smooth curve between points you’ve seen. Extrapolation is like predicting beyond your data range — way harder. Training on 9x9 Sudoku and testing on 16x16 is extrapolation: the grid is bigger, more symbols, more constraints. Standard RRMs fail here because they memorize patterns at the 9x9 scale. SE-RRM succeeds because it learns the abstract rule “symbols must be unique in each row/column/block” without tying it to a specific grid size or symbol set. The equivariance guarantee means the reasoning process scales naturally.
Framework Shift
Before (RRMs):                          After (SE-RRM):

Training Data                           Training Data
  |                                       |
  v                                       v
Generate 1000s of                       Single example
color permutations                      (all permutations
  |                                      covered by design)
  v                                       |
Train model on                            v
augmented dataset                       Train with
  |                                      equivariant layers
  v                                       |
Model learns                              v
"red in top-left                        Model learns
 means X"                               "symbol relationships
  |                                      define solution"
  v                                       |
Fails on new                              v
symbol sets or                          Generalizes to
grid sizes                              new sizes/symbols
From learning symbol-specific patterns through exhaustive examples to learning symbol-agnostic structure through architectural constraints, the core shift is implicit symmetry via data → explicit symmetry via design.
Expert Assessment
Problem choice: Real gap. Reasoning tasks have obvious symmetries that neural nets ignore, forcing wasteful workarounds. This sits at the intersection of geometric deep learning (encoding symmetries) and neurosymbolic AI (structured reasoning), both hot areas. Not manufactured — the Sudoku and ARC-AGI benchmarks are established, and the data augmentation problem is widely acknowledged.
Method maturity: Clever insight, not brute force. The idea of equivariant layers isn’t new (see group equivariant CNNs), but applying it to discrete symbol permutations in reasoning tasks is fresh. The execution is clean — they use standard building blocks (pooling, broadcasting) in a principled way. However, I’d want to see ablations on which equivariant operations matter most. The paper could be clearer on whether this approach extends beyond permutation symmetries (e.g., spatial symmetries in ARC-AGI).
Experimental integrity: Baselines are fair — they compare against prior RRMs (HRM, TRM) and show SE-RRM wins with less augmentation. The Sudoku extrapolation (9x9 → 25x25) is impressive and well-documented. ARC-AGI results are competitive but not dominant, which is honest. One red flag: they don’t compare against LLMs or other non-RRM approaches on ARC-AGI, so we don’t know if 2M parameters is actually efficient or just efficient-for-RRMs. Also, the paper doesn’t discuss failure modes — where does equivariance hurt?
Writing quality: Solid but dense. The intro motivates well, but the method section assumes familiarity with equivariant networks. The Sudoku experiments are clear; the ARC-AGI section feels rushed — they mention “competitive performance” without breaking down which task types benefit most. If I were reviewing, I’d ask for a table showing per-task ARC-AGI scores and a paragraph on when equivariance doesn’t help. The related work section is thorough but could be trimmed.
Verdict: weak accept — Solid contribution with clear experimental wins, but the scope is narrow (reasoning tasks with symbol symmetries) and the writing could better guide non-experts.
Takeaways
If you’re building models for structured tasks (games, puzzles, constraint satisfaction), steal this: identify the symmetries in your problem and bake them into the architecture rather than hoping the model learns them from data. Concretely, if your task has permutation symmetries (e.g., player order in a game, color labels in a diagram), use equivariant layers — they’re not hard to implement (pooling + broadcasting) and they cut your data needs dramatically.
Second, the extrapolation result (9x9 → 25x25 Sudoku) shows that architectural inductive biases enable generalization beyond your training distribution. If you’re stuck with limited data in one domain, think about what structural properties transfer to related domains and encode them explicitly.
Third, the “data augmentation tax” framing is useful. If you’re generating augmented data to teach a symmetry, ask: could I enforce this symmetry architecturally instead? It’s not always possible, but when it is, you get better generalization and faster training.
论文: 2603.02193 作者: Richard Freinschlag, Timo Bertram, Erich Kobler, Andreas Mayr, Günter Klambauer 分类: cs.LG, cs.AI, stat.ML
缺口
循环推理模型(RRMs)比如HRM和TRM,只用200万参数就能解结构化谜题——比大语言模型精简太多。
但它们有个愚蠢的盲点:把谜题里的”红色”和”蓝色”互换,模型就当成全新问题。
解决办法?生成几千个颜色排列的训练样本。
管用,但浪费——你在用不同配色反复教同一个逻辑结构。
核心问题:RRMs通过暴力数据增强隐式学习符号对称性,而不是编码这个数学事实:排列符号不应改变解法。
这限制了泛化能力——在9x9数独上训练,模型无法外推到16x16或25x25网格,因为它从未学到”符号的身份无关紧要,重要的是它们的关系”。
问题: RRMs无法跨符号排列泛化
   |
   v
假设: 符号身份与逻辑结构无关
   |
   v
方法: 在架构中强制排列等变性
   |
   v
证据: 从9x9泛化到25x25数独,减少增强需求
   |
   v
结论: 显式对称性 > 通过数据隐式学习
增量
一句话: 以前,神经推理器通过穷举样本学”红≠蓝”;现在它们通过构造就知道”红=蓝=任意符号”。
核心机制
SE-RRM用符号等变层替换标准神经层,保证:如果你排列输入符号,输出会同样排列。
架构有三部分:(1)符号等变编码器,把每个符号映射到学习的嵌入;(2)循环推理层,每步用等变操作精炼解;(3)解码器,输出符号概率同时保持排列结构。
关键技巧在信息流动方式。
标准层任意混合符号嵌入——“红”和”蓝”的交互方式在你互换标签时会崩溃。
SE-RRM层使用对所有符号对称的操作:跨符号维度池化、广播、以及不”看见”哪个是哪个符号的逐元素操作。
想象处理一副扑克牌,你能数花色、比大小,但你对红桃是红是紫色盲。
循环结构迭代精炼可能解的”信念状态”。
每个推理步骤接收当前信念,应用等变变换(比如检查约束或在网格单元间传播信息),输出更新的信念。
因为每个操作都尊重符号排列,整个推理链是等变的——在输入处互换符号,推理轨迹会同样互换。
输入网格          符号等变              循环推理              输出
(符号)            编码器                (迭代精炼)            (解)

[1 _ 3]          [embed(1)]            步骤1: 检查约束
[_ 2 _]  --->    [embed(2)]   --->     步骤2: 传播信息   --->  [1 4 3]
[3 _ 1]          [embed(3)]            步骤3: 更新信念         [4 2 5]
                 [embed(4)]            ...                     [3 5 1]
                 [embed(5)]            步骤T: 收敛
                      |
                      v
                 (所有操作
                  对称对待
                  符号)
把SE-RRM想象成裁判,执行规则但不在乎球队球衣。
裁判(模型)看到球员(符号)做动作(约束),但A队穿红还是蓝无关紧要——规则一视同仁。
编码器像给每队分配球衣号码,循环层像追踪比赛状态(谁能移动到哪),解码器像宣布最终比分。
关键是,如果你中途互换球衣颜色,裁判的决定会同样互换,因为它们基于位置和规则,不是颜色。
这就是”等变性”的意思:推理结构独立于符号标签。
关键概念
- 排列等变性: 想象你有个函数,输入数字列表输出列表。
如果打乱输入导致输出以完全相同方式打乱,这函数就是”排列等变”的。
例子:f([3,1,2]) = [6,2,4],那么f([1,2,3])必须等于[2,4,6]——输出跟随输入的同样打乱。
对推理任务,这意味着”如果我在谜题里互换’红’和’蓝’,解答里的’红’和’蓝’也互换”。
标准神经网络不保证这点——它们可能从数据学到,但SE-RRM在架构上强制执行,所以是免费的。
- 数据增强税: 当你的模型不理解对称性,你通过生成增强训练数据支付”税”。
对符号排列,如果有9个符号,有9! = 362,880种可能排列。
你无法全生成,所以采样几千个希望模型泛化。
这很昂贵(更多数据存储和处理)且不完整(你永远覆盖不了所有排列)。
SE-RRM通过把对称性构建进架构消除这个税——一个训练样本隐式覆盖所有排列。
- 外推vs内插: 内插像在你见过的点之间填平滑曲线。
外推像预测超出数据范围——难得多。
在9x9数独上训练在16x16上测试是外推:网格更大,更多符号,更多约束。
标准RRMs在这失败因为它们记忆9x9尺度的模式。
SE-RRM成功因为它学到抽象规则”符号在每行/列/块必须唯一”,不绑定到特定网格大小或符号集。
等变性保证意味着推理过程自然扩展。
框架转变
之前(RRMs):                         之后(SE-RRM):

训练数据                             训练数据
  |                                    |
  v                                    v
生成1000个                            单个样本
颜色排列                              (所有排列
  |                                    通过设计覆盖)
  v                                    |
在增强数据集                            v
上训练模型                             用等变层
  |                                    训练
  v                                    |
模型学到                                v
"左上角红色                            模型学到
 意味着X"                             "符号关系
  |                                    定义解"
  v                                    |
在新符号集或                            v
网格尺寸上失败                         泛化到新
                                      尺寸/符号
从通过穷举样本学习符号特定模式,到通过架构约束学习符号无关结构,核心转变是通过数据的隐式对称性 → 通过设计的显式对称性。
专家评审
选题眼光: 真缺口。
推理任务有明显对称性,神经网络却忽略,迫使浪费性变通。
这处于几何深度学习(编码对称性)和神经符号AI(结构化推理)的交叉点,都是热门领域。
不是人造的——数独和ARC-AGI基准是既定的,数据增强问题被广泛承认。
方法成熟度: 巧劲,不是蛮力。
等变层的想法不新(见群等变CNN),但应用到推理任务的离散符号排列是新鲜的。
执行干净——他们以原则性方式使用标准构建块(池化、广播)。
但我想看关于哪些等变操作最重要的消融实验。
论文可以更清楚这方法是否扩展到排列对称性之外(比如ARC-AGI中的空间对称性)。
实验诚意: 基线公平——他们与先前的RRMs(HRM、TRM)比较,显示SE-RRM用更少增强获胜。
数独外推(9x9 → 25x25)令人印象深刻且文档完善。
ARC-AGI结果有竞争力但不占主导,这很诚实。
一个警示:他们没在ARC-AGI上与LLMs或其他非RRM方法比较,所以我们不知道200万参数是真高效还是只是对RRMs高效。
另外,论文没讨论失败模式——等变性在哪里有害?
写作功力: 扎实但密集。
引言动机好,但方法部分假设熟悉等变网络。
数独实验清晰;ARC-AGI部分感觉仓促——他们提到”有竞争力的性能”但没分解哪些任务类型最受益。
如果我审稿,我会要求一个显示每任务ARC-AGI分数的表格,以及关于等变性何时无用的段落。
相关工作部分彻底但可以修剪。
判决: 弱接收 — 扎实贡献有清晰实验胜利,但范围窄(有符号对称性的推理任务),写作可以更好引导非专家。
要点总结
如果你在为结构化任务(游戏、谜题、约束满足)构建模型,偷这个:识别问题中的对称性并烧进架构,而不是希望模型从数据学到它们。
具体地,如果你的任务有排列对称性(比如游戏中的玩家顺序、图表中的颜色标签),使用等变层——它们不难实现(池化+广播),而且大幅削减数据需求。
第二,外推结果(9x9 → 25x25数独)显示架构归纳偏置使超出训练分布的泛化成为可能。
如果你在一个领域被有限数据困住,思考什么结构属性迁移到相关领域并显式编码它们。
第三,“数据增强税”框架有用。
如果你在生成增强数据来教对称性,问:我能否在架构上强制这个对称性?不总是可能,但可能时,你得到更好泛化和更快训练。