Paper: 2608.11204 Authors: Wenrui Bao, Tianyun Jiang, Zhiben Chen, Ser-Nam Lim, Peter D. Peng, Yuzhang Shang Categories: cs.RO, cs.AI, cs.CV
The Gap
Surgical robot learning has a data problem that is different in kind, not just degree, from general manipulation. To train a policy on a dVRK (da Vinci Research Kit), you need endoscopic video that is time-synchronized with joint kinematics. That means a teleoperation setup, a trained operator, a calibrated recording pipeline, and clinical or lab access. Meanwhile, endoscopic video exists in enormous quantity — surgical archives, training libraries, public datasets — with no action labels attached whatsoever.
The field has responded to this in two mostly separate camps. One camp builds surgical world models: video generators conditioned on text or coarse controls that produce plausible endoscopic futures. SurgSora, Endora, and similar work fall here. These models are impressive as generators and get used as neural simulators or as evaluation environments — you can score a policy against predicted rollouts. But they stop at prediction. Nothing in them emits torque, joint velocity, or gripper commands, so nothing closes the loop on hardware. The other camp builds surgical imitation policies — behavior cloning, diffusion policies, ACT-style action-chunking transformers — trained directly on the scarce synchronized data. These do close the loop, but their sample efficiency is exactly as bad as the demonstration count is small, and they degrade hardest on precisely the tasks that matter clinically: contact-rich tissue interaction and bimanual coordination.
Adjacent to both, the general robotics literature has been converging on world-action models — GR-1/GR-2, UniPi, Genie-style latent-action models, and NVIDIA’s Cosmos line — where a single generative backbone predicts both future frames and actions. Cosmos Policy in particular provides the architectural template this paper builds on. But nobody had run the experiment that surgery specifically demands: hold the action-labeled budget *fixed and ask whether action-free video pretraining buys you closed-loop performance. That is a narrow, falsifiable question, and it is the one this paper answers.
  PROBLEM
  [ dVRK video+kinematics pairs are scarce and expensive ]
  [ endoscopic video alone is cheap and abundant        ]
                     |
                     v
  PRIOR WORK SPLITS TWO WAYS
  [ surgical world models ]        [ surgical imitation ]
  [ predict video only    ]        [ closes loop, but   ]
  [ used as sim / eval    ]        [ data-starved       ]
        |                                  |
        +--------------+-------------------+
                       |
                       v
  ASSUMPTION
  [ visual dynamics of surgical scenes are a          ]
  [ transferable prior: knowing how tissue, needles,  ]
  [ and tools move constrains what actions make sense ]
                       |
                       v
  METHOD
  [ Surgical WAM on Cosmos Policy backbone            ]
  [ stage 1: action-free video pretraining            ]
  [ stage 2: fine-tune on FIXED action-labeled budget ]
  [ deploy: receding-horizon closed-loop controller   ]
                       |
                       v
  EVIDENCE
  [ 4 simulated surgical tasks                        ]
  [ 63.5% -> 77.8% average success                    ]
  [ PegTransfer +20 pts absolute                      ]
  [ largest gains on contact-rich / bimanual          ]
                       |
                       v
  CONCLUSION
  [ action-free video is a usable substitute for      ]
  [ some action supervision in surgical control       ]
The Increment
One sentence: Before this paper, surgical video models predicted futures you could watch and surgical policies acted on data you could not afford; after it, there is one model that learns dynamics from unlabeled video and then converts that knowledge into executable action chunks, with a controlled experiment showing the transfer is real under a fixed label budget.
Core Mechanism
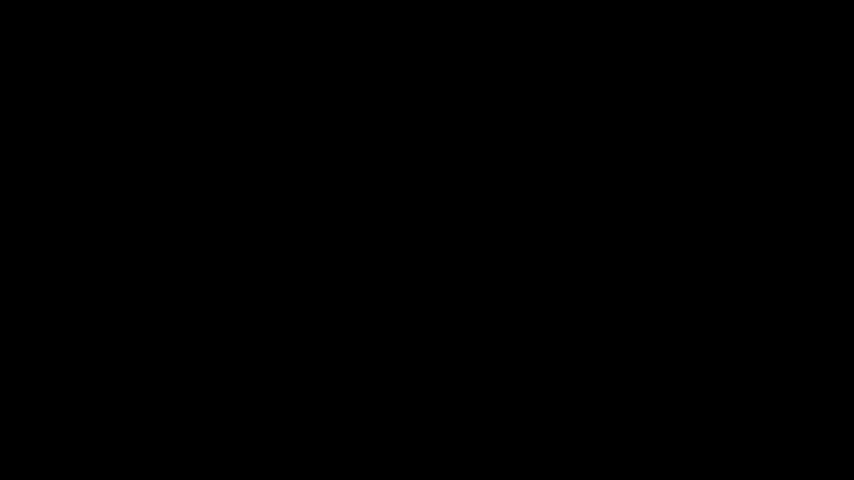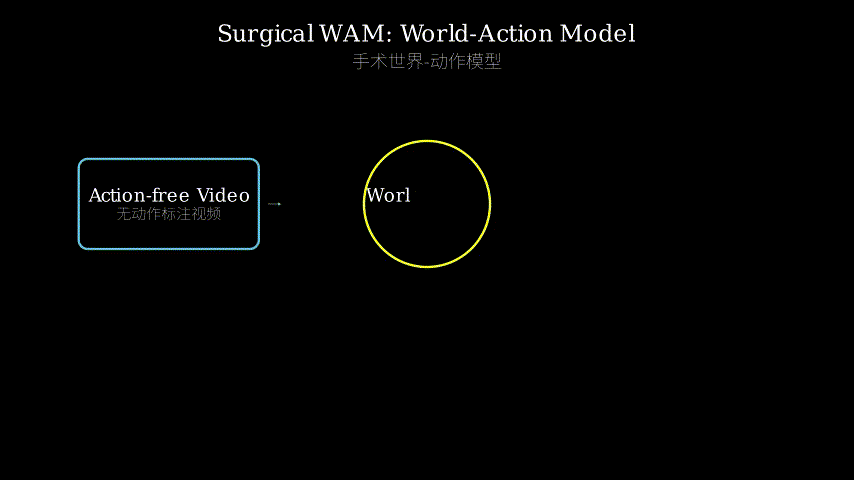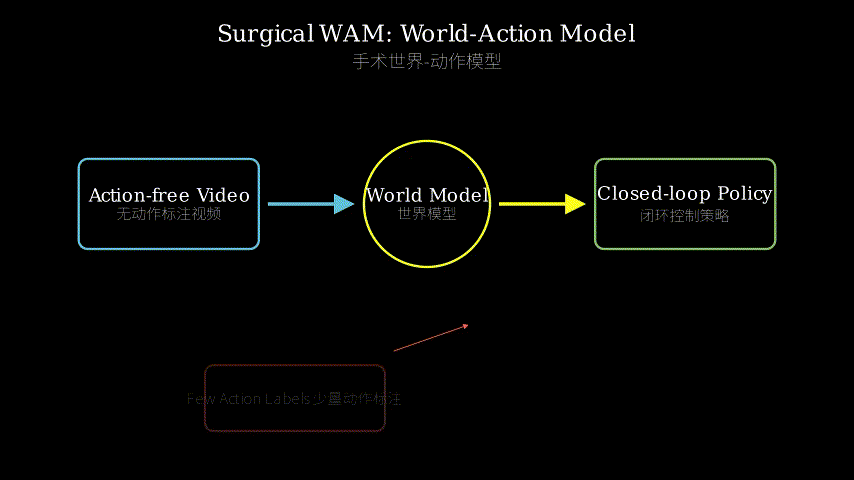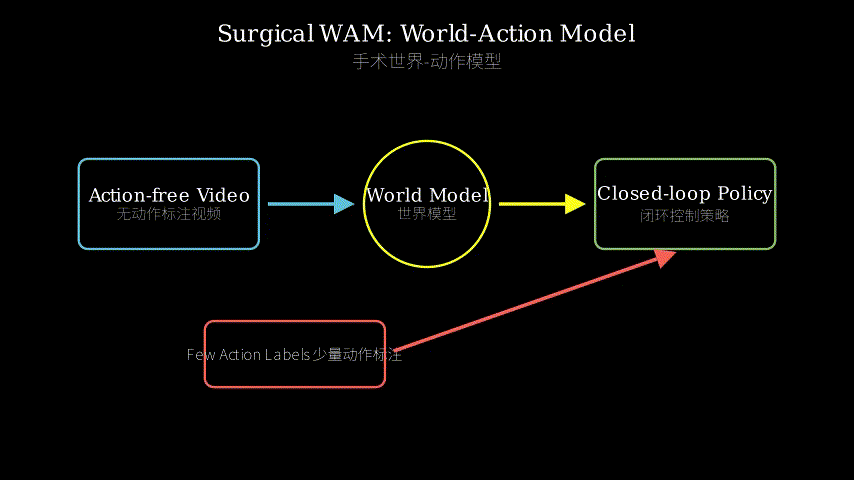
Surgical WAM is a single generative transformer with two output heads sharing one representation of the scene. Given a short history of endoscopic frames (plus a task instruction), the model predicts two things jointly: the next stretch of future observations, and an action chunk — a sequence of dVRK commands covering roughly the same time span. The joint prediction is the whole point. If the model is asked to say “the left grasper will close on the peg and the peg will lift” in pixels *and in joint coordinates simultaneously, the pixel objective forces the shared representation to encode contact, occlusion, and object motion, and the action head gets to reuse all of it.
Training runs in two stages. Stage one uses only action-free endoscopic video: no kinematics needed, so the data volume can be large. Here the model does pure future-frame prediction, learning that tissue deforms rather than translates rigidly, that instruments occlude and then reappear, that a grasped object follows the tool tip, that specular highlights move with the endoscope. Stage two switches on the action head and fine-tunes on the fixed, small budget of synchronized video-kinematics demonstrations. The action head is not learning surgical physics from scratch — it is learning a readout from an already-structured latent space into joint space. That is a much lower-dimensional learning problem, which is why a small budget suffices.
Deployment is receding-horizon control, the same idea as MPC. The model predicts an action chunk of length H, the controller executes only a short prefix of it (say the first k steps, k much less than H), then throws away the rest, observes the resulting frame, and replans from scratch. Predicting long chunks gives temporal coherence and lets the model commit to a multi-step plan like “approach, close, lift.” Executing only a prefix means every few steps the loop is corrected by real observation, so prediction error never compounds. This is the mechanism that turns a generative video model into an actual controller.
  TRAINING STAGE 1 -- action-free video (abundant)
  +---------------------------------------------------+
  |  endoscopic frames o_1..o_t                       |
  |            |                                      |
  |            v                                      |
  |   [ Cosmos Policy backbone / shared latent ]      |
  |            |                                      |
  |            v                                      |
  |   [ video head ] --> o_(t+1)..o_(t+H)             |
  |            ^                                      |
  |            +-- loss: future frame prediction      |
  |  (action head idle -- no labels exist)            |
  +---------------------------------------------------+
                      |
                      | weights carried over
                      v
  TRAINING STAGE 2 -- fixed action-labeled budget (scarce)
  +---------------------------------------------------+
  |  frames o_1..o_t  +  task instruction             |
  |            |                                      |
  |            v                                      |
  |   [ shared latent -- already knows dynamics ]     |
  |          /              \                         |
  |         v                v                        |
  |  [ video head ]     [ action head ]               |
  |   o_(t+1..t+H)       a_(t..t+H) chunk             |
  |         |                |                        |
  |   frame loss        action loss (dVRK kinematics) |
  +---------------------------------------------------+
                      |
                      v
  DEPLOYMENT -- receding horizon closed loop
  +---------------------------------------------------+
  |                                                   |
  |   observe o_t                                     |
  |       |                                           |
  |       v                                           |
  |   predict chunk a_t .. a_(t+H)                    |
  |       |                                           |
  |       v                                           |
  |   execute prefix a_t .. a_(t+k)   [ k << H ]      |
  |       |                                           |
  |       v                                           |
  |   discard tail, observe o_(t+k) ---+              |
  |                                    |              |
  |       +----------------------------+              |
  |       |  replan                                   |
  |       v                                           |
  |   (repeat until task complete)                    |
  +---------------------------------------------------+
The structural metaphor: a surgical resident who watched a thousand operations before ever holding an instrument.
Stage one is the resident in the observation gallery. They watch endoscopic footage for years. Nobody tells them the hand positions or the wrist angles — they have no access to the surgeon’s proprioception. But they absorb something enormous anyway: how tissue springs back, how blood pools, what a needle looks like a half-second before it bites, when a grasper is about to slip. This is pure visual dynamics, learned without a single motor command. That is exactly what action-free video pretraining is.
Stage two is the resident’s first supervised cases at the console. Now they get to move the instruments, and now — crucially — someone is recording what their hands did alongside what the camera saw. They only get a handful of cases; residency is short and cases are precious. But they are not learning surgery from these few cases. They are learning a mapping: “the thing I have watched a thousand times, and can already predict, corresponds to this pattern of wrist and grasper motion.” Learning a mapping from a rich existing model is fast. Learning surgery from twenty cases with no prior observation is not.
Deployment is the resident actually operating. They plan several moves ahead — “come in from the left, close on the peg, lift clear of the board, cross over” — because a plan with a horizon is smoother and safer than one twitch at a time. But they only commit to the first move or two before looking again. Tissue shifts, the peg was not quite where they thought, the endoscope drifted. Look, replan, commit briefly, look again. That is the receding horizon. A resident who executed a full ten-second plan blind would be dangerous; so would a model that ran its whole predicted chunk without re-observing.
And the paper’s headline result is the one every surgical educator already believes: the observation gallery pays off most on the hard stuff. Simple reach-and-place is learnable from a few reps. Contact-rich and bimanual work — where you need a physical intuition of how things push back and how two hands interfere — is where the thousand watched hours show up. PegTransfer gaining 20 points is exactly this pattern.
Key Concepts
-
Action-free video pretraining: Normally, teaching a robot means showing it paired data — “this is what the camera saw, and this is what the joints did.” The pairing is the expensive part. Action-free pretraining drops the second half: you show the model only what the camera saw, and ask it to predict what the camera will see next. No robot commands anywhere in the data. Why does this help control at all? Because to predict the next frame well, the model has to internally represent things that matter for acting: where the objects are, that the tool is about to touch something, that the tissue will deform when it does. It builds a physics-flavored understanding of the scene as a side effect of being a good video predictor. Later, when you finally give it a few labeled examples, it doesn’t need to discover that a grasped peg moves with the grasper — it already knows. It just needs to learn which joint numbers correspond to that motion. Concretely: it is the difference between teaching someone to drive who has spent years as a passenger versus someone who has never been in a car.
-
Action chunking: The naive way to run a policy is one step at a time: see a frame, output one command, repeat. This has two failure modes — the motion comes out jittery because consecutive decisions are made independently, and the policy can dither indefinitely in ambiguous states because nothing commits it to a plan. Action chunking instead outputs a whole *sequence of, say, 16 commands in one shot. The model has to decide “here is a coherent multi-step motion,” which naturally produces smooth trajectories and forces commitment. The cost is that a chunk is an open-loop plan: if step 3 goes wrong, steps 4 through 16 are predicting a world that no longer exists.
-
Receding-horizon execution: This is the fix for chunking’s open-loop problem, borrowed straight from model predictive control. You predict long, execute short. Predict 16 steps; run 4; throw away the other 12; look at the new frame; predict 16 fresh steps. You get chunking’s coherence and commitment, but errors are corrected every 4 steps instead of every 16, so drift cannot accumulate. The mental image is a driver planning the next two hundred meters of road while only actually steering the next twenty, then re-planning. The long plan shapes the short action; the short action keeps the long plan honest.
Framework Shift
Before (mainstream approach):          After (this paper):

TWO SEPARATE PIPELINES                 ONE MODEL, TWO STAGES

  cheap video                            cheap video
      |                                      |
      v                                      v
  [ world model ]                     [ pretrain visual dynamics ]
      |                                      |
      v                                      v  (same weights)
  predicted frames                    [ + action head, fine-tune ]
      |                                      ^
      v                                      |
  ( watch it / use as sim )            scarce action labels
  ( eval a policy against it )                |
                                              v
   ...dead end for control...          [ predict frames AND
                                          action chunks ]
  ------------------------------              |
                                              v
  scarce action labels                 execute prefix, replan
      |                                       |
      v                                       v
  [ imitation policy ]                 CLOSED LOOP ON ROBOT
      |
      v
  closed loop, but                     video is not a simulator,
  data-starved, fails on               it is a source of
  contact-rich + bimanual              transferable priors

  video and control never
  share a representation
One sentence: from video as a simulator you evaluate policies against to video as unlabeled pretraining data whose learned dynamics flow directly into the policy’s own weights, the core shift is treating endoscopic footage as a representation-learning corpus for control rather than a rendering target.
Expert Assessment
Problem choice: Real gap, and unusually well-posed. The scarcity of synchronized video-kinematics data in surgical robotics is not a manufactured constraint — it is the actual reason surgical imitation learning lags behind general manipulation. And the framing is disciplined: *under a fixed budget of action labels, does action-free video help? That phrasing rules out the cheap win of “we used more data and got better numbers.” Where it sits in the trajectory: this is the surgical instantiation of a broader move that GR-1/GR-2, UniPi, and the Cosmos line have been pushing in general robotics. The paper is not inventing the world-action-model idea; it is running the domain-specific experiment that the surgical community needed someone to run. That is a legitimate contribution, but it is an application-and-validation contribution, not a conceptual one, and the abstract could be more upfront about that.
Method maturity: This is clean engineering rather than a clever new mechanism. Cosmos Policy already gives you the joint video-plus-action architecture; the contributions are the surgical pretraining corpus, the two-stage recipe, and the receding-horizon deployment loop. All three are sensible and none are surprising. What I’d want to see argued against: cheaper baselines that might capture much of the gain. Plain visual representation pretraining — a frozen video encoder, R3M/VC-1-style, or a masked-autoencoder on endoscopic frames feeding a small ACT head — is far less compute and might get you most of the way. Latent-action approaches (LAPO, Genie-style inverse dynamics in latent space) are a closer competitor and would test whether *generative future prediction specifically is what matters, versus just good features. If those comparisons are absent, the paper shows that its pipeline works but not that the expensive part is doing the work.
Experimental integrity: The headline structure is right — fixed label budget, same architecture, pretraining as the single toggled variable. That is the correct ablation and it deserves credit. But four simulated tasks is thin, and everything here is simulation. Surgical robotics has a specific credibility problem: endoscopic sim-to-real is brutal (specular highlights, deformable tissue, smoke, blood, lighting), and the paper’s central claim is about visual dynamics priors — exactly the thing most likely to be sim-flavored. If the pretraining video is also simulated or drawn from the same simulator distribution, the result is much weaker than it reads: it becomes near-domain transfer rather than “cheap real video helps.” The abstract does not say, and that ambiguity is the single biggest thing I’d want resolved. Also: 63.5% to 77.8% averaged over four tasks means each task contributes ~25% of the average, so a +20-point swing on PegTransfer alone accounts for a third of the total gain. I want per-task numbers, seed variance, and confidence intervals before treating 77.8% as a stable figure. With four tasks and presumably tens of eval episodes each, the error bars could plausibly be ±5 points or worse. No dVRK hardware results is the honest limitation, and framing this as “a practical path toward scaling up surgical robot learning” is a stretch until something moves on real hardware.
Writing quality: The abstract is well-constructed and states a falsifiable question, which is more than most papers manage. The corner-cutting is almost certainly in the data description — the paper’s entire argument rests on what the action-free video corpus actually is (source, scale, domain gap to the eval tasks), and abstracts that stay vague there usually do so because the answer is less impressive than the framing. Rewriting the data and experimental-setup section with full transparency on corpus provenance, size, per-task breakdowns, and seed variance would elevate the whole paper from “plausible claim” to “settled result.” Second priority: a scaling curve. How does the gain vary with the action-label budget, and how does it vary with pretraining hours? Those two curves would turn this from a single data point into a usable finding others could plan around.
Verdict: weak accept — the question is right, the ablation is structured correctly, and the result is directionally valuable, but simulation-only evidence on four tasks with likely-missing cheaper baselines makes it a solid domain validation rather than a definitive one.
Takeaways
Things a practitioner can actually lift from this:
-
The fixed-budget framing is a template. Whenever you claim auxiliary data helps, hold the expensive supervision constant and toggle only the cheap data. It kills the confound that makes most “pretraining helps” claims uninterpretable. Steal this experimental design regardless of domain.
-
Predict long, execute short. The chunk-length-versus-execution-length gap is a free tuning knob that most people leave at 1
. Long chunks buy temporal coherence and commitment; short execution prefixes buy error correction. If your imitation policy is jittery or dithers in ambiguous states, this ratio is the first thing to tune, and it costs nothing to try. -
Video prediction as a proxy objective for physical understanding. The transferable insight is not “use Cosmos” — it is that forcing a model to predict pixels makes it encode contact, occlusion, and object permanence for free. Anywhere you have abundant unlabeled sensor streams and scarce action labels — industrial inspection, agricultural robotics, lab automation — the same two-stage recipe applies.
-
The gain concentrates on contact-rich and bimanual tasks. This is the most decision-relevant number in the paper. If your tasks are free-space reaching, video pretraining probably isn’t worth the compute. If they involve contact dynamics or coordinated multi-arm motion, that’s where the prior pays. Use this to triage whether to invest.
-
Read the data section before believing the result. Meta-lesson: for any paper claiming cheap-data-helps-expensive-task, the whole claim lives or dies on the domain gap between the cheap corpus and the eval environment. If a paper is vague about corpus provenance, treat the number as an upper bound.
论文: 2608.11204 作者: Wenrui Bao, Tianyun Jiang, Zhiben Chen, Ser-Nam Lim, Peter D. Peng, Yuzhang Shang 分类: cs.RO, cs.AI, cs.CV
缺口
手术机器人学习的数据困境跟通用机器人操作不是量级差别,而是性质差别。
要训练一个跑在 dVRK(达芬奇研究套件)上的策略,你需要的是内窥镜视频和关节运动学信号严格时间对齐的数据。 这意味着一整套遥操作装置、一个受过训练的操作者、一条校准好的采集链路,以及临床或实验室的准入。 而另一边,内窥镜视频本身多得是——手术录像库、教学素材、公开数据集——但一帧动作标签都没有。
领域里对此的回应基本分成两个互不搭理的阵营。 一派做手术世界模型:以文本或粗粒度控制信号为条件的视频生成器,产出看起来合理的内窥镜未来画面。 SurgSora、Endora 这类工作属于此列。 它们作为生成器确实惊艳,被当成神经仿真器或者策略评测环境用——你可以拿预测出的 rollout 给策略打分。 但它们到”预测”就停了。 模型里没有任何东西输出力矩、关节速度或夹持器指令,所以没有任何东西能在硬件上闭环。 另一派做手术模仿策略:行为克隆、扩散策略、ACT 式的动作分块 Transformer,直接在稀缺的同步数据上训。 这些确实能闭环,但样本效率差得跟演示数量的稀少程度完全成正比,而且退化最严重的恰恰是临床上最要紧的那类任务:富接触的组织交互,以及双臂协调。
在这两派旁边,通用机器人领域一直在向世界-动作模型收敛:GR-1/GR-2、UniPi、Genie 式的隐动作模型,以及 NVIDIA 的 Cosmos 系列——用一个生成骨干同时预测未来帧和动作。 其中 Cosmos Policy 正是本文的架构模板。 但没人做过手术领域真正需要的那个实验:把有动作标签的预算钉死不动,然后问无动作视频预训练到底能不能换来闭环性能的提升。 这是个窄而可证伪的问题,也正是本文回答的问题。
  PROBLEM
  [ dVRK 视频+运动学配对数据稀缺且昂贵 ]
  [ 纯内窥镜视频便宜且海量              ]
                     |
                     v
  PRIOR WORK 分成两路
  [ 手术世界模型     ]         [ 手术模仿学习     ]
  [ 只预测视频       ]         [ 能闭环但数据饥饿 ]
  [ 当仿真器 / 评测器 ]         [ 富接触双臂崩盘   ]
        |                              |
        +--------------+---------------+
                       |
                       v
  ASSUMPTION
  [ 手术场景的视觉动力学是可迁移的先验:      ]
  [ 知道组织/缝针/器械怎么动,               ]
  [ 就约束了什么动作是合理的                 ]
                       |
                       v
  METHOD
  [ Surgical WAM,基于 Cosmos Policy 骨干     ]
  [ 阶段一:无动作视频预训练                  ]
  [ 阶段二:在固定动作标注预算上微调          ]
  [ 部署:滚动时域闭环控制器                  ]
                       |
                       v
  EVIDENCE
  [ 4 个仿真手术任务                          ]
  [ 平均成功率 63.5% -> 77.8%                 ]
  [ PegTransfer 绝对提升 20 个点               ]
  [ 富接触 / 双臂任务增益最大                 ]
                       |
                       v
  CONCLUSION
  [ 无动作视频可以部分替代动作监督            ]
增量
一句话:这篇之前,手术视频模型预测的未来你只能看、手术策略需要的数据你买不起;这篇之后,有了一个模型能先从无标注视频里学动力学、再把这份知识转成可执行的动作块,并且用固定标签预算的受控实验证明这种迁移是真的。
核心机制
Surgical WAM 是单个生成式 Transformer,两个输出头共享同一份场景表征。 给定一小段内窥镜历史帧(外加任务指令),模型联合预测两样东西:接下来一段未来观测,以及一个动作块——覆盖大致相同时间跨度的 dVRK 指令序列。 “联合”是关键所在。 如果模型必须同时用像素和用关节坐标说出”左侧抓钳会合上钉子、钉子会被提起”,那么像素目标会逼迫共享表征把接触、遮挡、物体运动都编码进去,而动作头可以把这些全部拿来复用。
训练分两个阶段。 阶段一只用无动作视频:不需要运动学,所以数据量可以做大。 这里模型做纯未来帧预测,学到的是:组织是形变而非刚性平移,器械会遮挡然后重新出现,被抓住的物体跟着工具尖端走,镜面高光随内窥镜移动。 阶段二打开动作头,在固定的、少量的同步视频-运动学演示上微调。 动作头不是从零学手术物理——它学的是从一个已经结构化的隐空间到关节空间的读出映射。 这是个维度低得多的学习问题,所以小预算就够用。
部署是滚动时域控制,思路跟 MPC 一样。 模型预测长度为 H 的动作块,控制器只执行其中很短的前缀(比如前 k 步,k 远小于 H),剩下的直接扔掉,观察新得到的画面,然后重新规划。 预测长块带来时间上的连贯性,让模型敢于承诺一个多步计划,比如”接近、闭合、提起”。 只执行前缀意味着每隔几步循环就被真实观测纠偏一次,预测误差永远累积不起来。 正是这个机制把一个生成式视频模型变成了真正的控制器。
  训练阶段 1 -- 无动作视频(海量)
  +---------------------------------------------------+
  |  内窥镜帧 o_1..o_t                                |
  |            |                                      |
  |            v                                      |
  |   [ Cosmos Policy 骨干 / 共享隐表征 ]             |
  |            |                                      |
  |            v                                      |
  |   [ 视频头 ] --> o_(t+1)..o_(t+H)                 |
  |            ^                                      |
  |            +-- 损失:未来帧预测                    |
  |  (动作头闲置 -- 没有标签)                        |
  +---------------------------------------------------+
                      |
                      | 权重继承
                      v
  训练阶段 2 -- 固定动作标注预算(稀缺)
  +---------------------------------------------------+
  |  帧 o_1..o_t  +  任务指令                         |
  |            |                                      |
  |            v                                      |
  |   [ 共享隐表征 -- 已经懂动力学 ]                  |
  |          /              \                         |
  |         v                v                        |
  |  [ 视频头 ]         [ 动作头 ]                    |
  |   o_(t+1..t+H)       a_(t..t+H) 动作块            |
  |         |                |                        |
  |    帧损失           动作损失(dVRK 运动学)        |
  +---------------------------------------------------+
                      |
                      v
  部署 -- 滚动时域闭环
  +---------------------------------------------------+
  |   观察 o_t                                        |
  |       |                                           |
  |       v                                           |
  |   预测动作块 a_t .. a_(t+H)                       |
  |       |                                           |
  |       v                                           |
  |   执行前缀 a_t .. a_(t+k)    [ k << H ]           |
  |       |                                           |
  |       v                                           |
  |   丢弃尾部,观察 o_(t+k) -----+                   |
  |                               |                   |
  |       +-----------------------+                   |
  |       |  重新规划                                 |
  |       v                                           |
  |   (循环直到任务完成)                             |
  +---------------------------------------------------+
核喻:一个在观摩室里看了上千台手术、之后才第一次上台的住院医。
阶段一就是那个坐在观摩室里的住院医。 他看了好几年内窥镜录像。 没人告诉他术者的手在哪个位置、腕关节转了多少度——他拿不到主刀的本体感觉。 但他还是吸收了极大量的东西:组织怎么回弹,血怎么积,缝针在扎进去前半秒长什么样,抓钳快要滑脱时是什么征兆。 这是纯粹的视觉动力学,一条运动指令都没学过就掌握了。 这就是无动作视频预训练。
阶段二是这个住院医在控制台前的头几台带教手术。 现在他能动器械了,而且——这才是关键——有人在同步记录他的手做了什么、镜头看到了什么。 他只能拿到寥寥几台;住院期短,病例珍贵。 但他不是靠这几台学手术,他学的是一个映射:“我看过上千遍、并且已经能预测的那件事,对应的是这样一组腕部和抓钳动作。” 从一个丰富的既有模型里学映射很快。 毫无观摩基础、只靠二十台病例学手术,不行。
部署阶段就是这个住院医真正在开刀。 他会往前规划好几步——“从左侧进,合上钉子,抬离板面,跨过去”——因为有时域的计划比一抽一抽地动更平顺、更安全。 但他只承诺头一两步就会重新看一眼。 组织移位了,钉子不完全在他以为的位置,内窥镜漂了。 看、重规划、短暂承诺、再看。 这就是滚动时域。 一个闭着眼把十秒计划走完的住院医是危险的;一个不重新观察就把整个预测块跑完的模型同样危险。
而本文的头号结果,恰恰是每个手术教育者早就相信的事:观摩的回报,在难的地方最明显。 简单的抓取放置,练几遍就会。 富接触和双臂的活儿——你需要对东西怎么反推回来、两只手怎么互相干扰有物理直觉——才是那上千小时观摩显形的地方。 PegTransfer 涨 20 个点,正是这个模式。
关键概念
-
无动作视频预训练:通常教机器人要给成对数据——“镜头看到了这个,关节做了那个”。贵的地方正是这个”配对”。无动作预训练把后半截扔了:只给模型看镜头看到了什么,让它预测镜头接下来会看到什么。数据里没有任何机器人指令。这对控制为什么有用?因为要把下一帧预测好,模型内部就不得不表征那些对”动手”至关重要的东西:物体在哪,工具即将碰到什么,碰到时组织会怎么形变。它是作为”当一个好的视频预测器”的副产品,建立起了一种带物理味道的场景理解。等你终于给它几个带标签的例子时,它不需要重新发现”被抓住的钉子会跟着抓钳走”——它早就知道了,它只需要学会哪些关节数值对应这个运动。具体点说:这就像教一个当了多年副驾的人开车,和教一个从没坐过车的人开车,两者的差别。
-
动作分块(action chunking):跑策略最朴素的方式是一步一决策:看一帧,输出一条指令,重复。这有两个坏毛病——动作抖,因为相邻决策彼此独立;而且在模糊状态下策略会无限犹豫,因为没有任何东西迫使它承诺一个计划。动作分块改成一次性输出一整个序列,比如 16 条指令。模型必须决定”这是一段连贯的多步运动”,这自然产生平滑轨迹并强制承诺。代价是:一个块本质上是开环计划,如果第 3 步出了岔子,第 4 到 16 步预测的是一个已经不存在的世界。
-
滚动时域执行:这是给分块的开环毛病打的补丁,直接借自模型预测控制。预测得长,执行得短。预测 16 步,跑 4 步,其余 12 步扔掉,看新画面,再重新预测 16 步。你既拿到了分块的连贯性和承诺感,又把纠偏频率从每 16 步提到每 4 步,漂移攒不起来。心理图像是:司机规划前方两百米的路,但只真正操控接下来二十米,然后重新规划。长计划塑造短动作,短动作让长计划不至于脱离现实。
框架转变
之前(主流方法):                    之后(本文方法):

两条互不相通的管线                     一个模型,两个阶段

  便宜的视频                             便宜的视频
      |                                      |
      v                                      v
  [ 世界模型 ]                        [ 预训练视觉动力学 ]
      |                                      |
      v                                      v (同一份权重)
  预测出的帧                          [ 接上动作头,微调 ]
      |                                      ^
      v                                      |
  (拿来看 / 当仿真器)                稀缺的动作标签
  (拿来评测别的策略)                        |
                                              v
   ...对控制来说是死路...              [ 同时预测帧
                                          和动作块 ]
  ------------------------------              |
                                              v
  稀缺的动作标签                       执行前缀,重新规划
      |                                       |
      v                                       v
  [ 模仿策略 ]                         机器人上真正闭环
      |
      v
  能闭环,但数据饥饿                   视频不是仿真器,
  富接触 + 双臂任务崩盘                而是可迁移先验的来源

  视频与控制从不共享表征
一句话:从把视频当成用来评测策略的仿真器,到把视频当成无标注预训练语料、让学到的动力学直接流进策略自身的权重里,核心转变是把内窥镜录像视作面向控制的表征学习语料,而不是渲染目标。
专家评审
选题眼光:真缺口,而且问题提得罕见地干净。 手术机器人里同步视频-运动学数据的稀缺不是人造约束,它就是手术模仿学习落后于通用操作的真实原因。 而且提法很有纪律:在动作标签预算固定的前提下,无动作视频有没有用? 这个措辞排除了”我们多用了数据所以数字变好了”这种便宜的胜利。 在领域轨迹里的位置:这是 GR-1/GR-2、UniPi、Cosmos 系列在通用机器人上推的那套东西在手术域的落地。 本文没有发明世界-动作模型这个想法,它是把手术社区一直缺人来做的那个域内实验做了。 这是正当贡献,但属于”应用与验证”型贡献,不是概念型的,摘要在这点上可以更坦白一些。
方法成熟度:这是干净的工程,而非新颖机制。 Cosmos Policy 本身就给了你”视频+动作”的联合架构;本文的贡献是手术预训练语料、两阶段配方、以及滚动时域部署循环。 三样都合理,也都不让人意外。 我更想看到被反驳掉的是那些更便宜的基线:单纯的视觉表征预训练——冻结的视频编码器、R3M/VC-1 那一路,或者在内窥镜帧上做掩码自编码器,后面接一个小 ACT 头——算力少得多,可能就把大部分收益吃掉了。 隐动作方法(LAPO、Genie 式的隐空间逆动力学)是更贴近的竞争者,能验证到底是生成式未来预测本身重要,还是仅仅”特征好”就够了。 如果缺这些对比,这篇只证明了自己这条管线能跑通,没证明贵的那部分在真正起作用。
实验诚意:主结构是对的——固定标签预算、同一架构、只把预训练当作唯一开关变量。 这是正确的消融,值得肯定。 但四个仿真任务太薄,而且全部是仿真。 手术机器人有个特有的可信度问题:内窥镜的 sim-to-real 极其残酷(镜面高光、可形变组织、烟雾、血、光照),而本文的核心主张恰恰是关于视觉动力学先验——最容易带上”仿真味”的那个东西。 如果预训练视频本身也是仿真的、或者来自同一个仿真器分布,那这个结果比读起来要弱得多:它变成了近域迁移,而不是”便宜的真实视频有用”。 摘要没说,这个含糊之处是我最想被解答的一件事。 另外:63.5% 到 77.8% 是四个任务的平均,也就是每个任务贡献约四分之一,那么单靠 PegTransfer 的 +20 点就占了总增益的三分之一。 在把 77.8% 当作稳定数字之前,我要看逐任务数字、随机种子方差和置信区间。 四个任务、每个大概几十个评测 episode,误差棒完全有可能在 ±5 点甚至更差。 没有 dVRK 真机结果是诚实的局限,而在真机上跑出东西之前,把这个说成”扩展手术机器人学习的实用路径”是拉伸了。
写作功力:摘要写得结构清楚,提出了可证伪的问题,这已经比大多数论文强。 偷懒的地方几乎肯定在数据描述上——全文论证完全押在”无动作视频语料到底是什么”(来源、规模、与评测任务的域差距)上,而在这里含糊的摘要,通常含糊是因为答案没有措辞那么好看。 把数据与实验设置这一节重写成完全透明——语料来源、规模、逐任务拆分、种子方差——能把整篇论文从”看起来站得住的主张”提到”已经定案的结果”。 第二优先级是缩放曲线:增益随动作标签预算怎么变、随预训练时长怎么变。 这两条曲线能把单个数据点变成别人可以据此做规划的可用发现。
判决:弱接收 —— 问题问对了、消融结构搭对了、结果方向上有价值,但纯仿真、四任务、很可能缺更便宜的基线,使它是一次扎实的域内验证,而非定论。
要点总结
实践者能真正拿走的东西:
-
固定预算的实验框架本身就是模板。 任何时候你要声称辅助数据有用,就把贵的那份监督钉死不动,只切换便宜的那份数据。这能干掉让大多数”预训练有用”主张无法解读的混淆因子。不管你在哪个领域,这套实验设计值得直接抄。
-
预测得长,执行得短。 块长与执行长度之间的比例是个免费的调参旋钮,大多数人放着 1:1 不动。长块买来时间连贯性和承诺,短前缀买来纠偏能力。如果你的模仿策略在抖、或者在模糊状态下反复犹豫,这个比例是第一个该调的,而且试起来零成本。
-
把视频预测当作物理理解的代理目标。 可迁移的洞见不是”用 Cosmos”,而是:逼模型预测像素,会让它免费地把接触、遮挡、物体恒存性编码进去。任何”无标注传感器流海量、动作标签稀缺”的场合——工业检测、农业机器人、实验室自动化——同一套两阶段配方都适用。
-
增益集中在富接触和双臂任务上。 这是全文最能指导决策的数字。如果你的任务是自由空间里的伸手,视频预训练大概不值那份算力。如果涉及接触动力学或多臂协调运动,那才是先验回本的地方。拿这条来判断值不值得投入。
-
信结果之前先读数据一节。 元教训:任何声称”便宜数据帮到贵任务”的论文,整个主张的生死都取决于便宜语料与评测环境之间的域差距。如果一篇论文对语料来源含糊其辞,就把那个数字当上界看。