Paper: 2604.08477 Authors: Ashima Suvarna, Kendrick Phan, Mehrab Beikzadeh, Hritik Bansal, Saadia Gabriel (UCLA) Categories: cs.AI
The RLVR Ceiling
Reinforcement Learning with Verifiable Rewards (RLVR) has transformed reasoning in formal domains—mathematics and code—where ground truth is automatically verifiable. Models trained on MATH competitions and CodeForces now achieve +50% gains on benchmarks like AIME24. But expose those same models to general reasoning tasks requiring causal inference, temporal understanding, or pragmatic reasoning, and performance drops by −8% on Big-Bench Extra Hard (BBEH).
The problem isn’t the algorithm. It’s the data. RLVR needs high-quality, verifiable training examples that span diverse reasoning skills. STEM domains have this in abundance: human-verified competition problems, executable code tests, symbolic proofs. General reasoning doesn’t. Scraping the web for “domain-specific” QA pairs (science, business, history) doesn’t help—models score well on MMLU but still fail BBEH. The skills don’t transfer.
SUPERNOVA makes a different observation: instruction-tuning datasets like SuperNI and FLAN already contain thousands of expert-annotated tasks encoding rich reasoning patterns—event understanding, question generation, object counting, temporal graphs. They just weren’t designed for RLVR. Many tasks are open-ended (hard to verify), not all tasks elicit strong reasoning, and the principles for curating RLVR data from instructions remain unexplored.
The Framework
SUPERNOVA is a multi-stage pipeline for curating RLVR data from instruction datasets. It explores three design decisions through 100+ compute-matched RL experiments:
1. Task Selection
Starting with 83 candidate tasks from SuperNI, SUPERNOVA reformats open-ended instructions into verifiable formats (e.g., multiple-choice questions). For each task, it samples 8 rollouts from the model, computes per-question win-rate, and removes questions that are trivial (win-rate=1) or impossible (win-rate=0).
Tasks are ranked by utility: train the model on task Dk, evaluate on BBEH’s 23 sub-tasks, measure performance. The ranking reveals that source task selection has dramatic impact on downstream reasoning. Not all instruction tasks are created equal.
2. Task Mixing
Two strategies for combining top-ranked tasks:
- Macro Mixing: Select N tasks with highest average performance across all BBEH sub-tasks
- Micro Mixing: For each BBEH sub-task, select the top N tasks that improve it specifically, then take the union
Micro mixing consistently outperforms macro. Different reasoning skills benefit from different source tasks. A single “best on average” mixture leaves performance on the table.
3. Data Interventions
Can synthetic augmentations improve data quality? SUPERNOVA tests interventions that increase question difficulty while preserving verifiable answers: long-context dependencies, anti-prior prompts, needle-in-haystack constraints, multi-hop reasoning chains.
Surprising result: under a fixed training budget, augmenting original data with these interventions does not improve performance. The base instruction data, when properly selected and mixed, is already sufficient.
Results
SUPERNOVA curates 25K RLVR samples and trains Qwen3 models (0.6B–4B) for 5000 RL steps using GRPO.
BBEH-test (general reasoning):
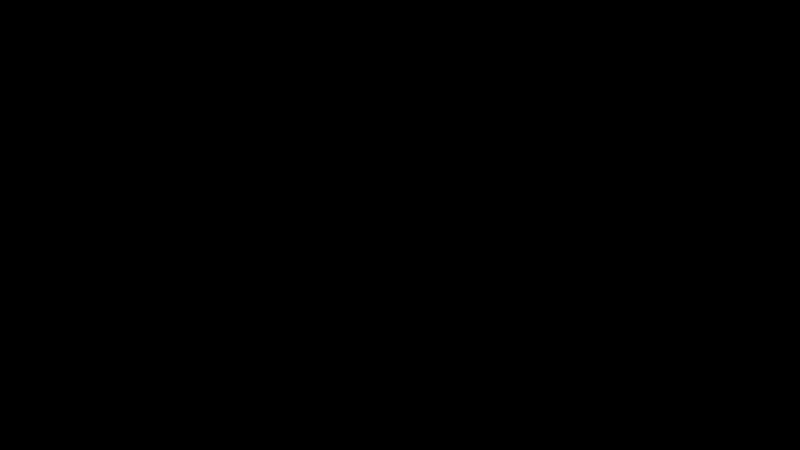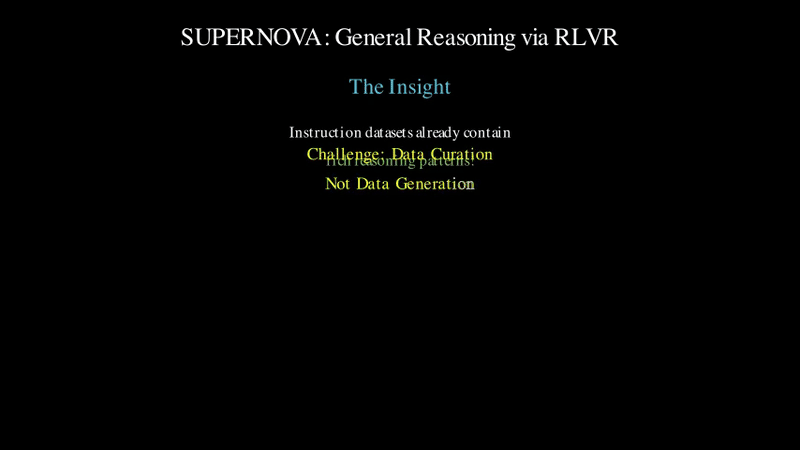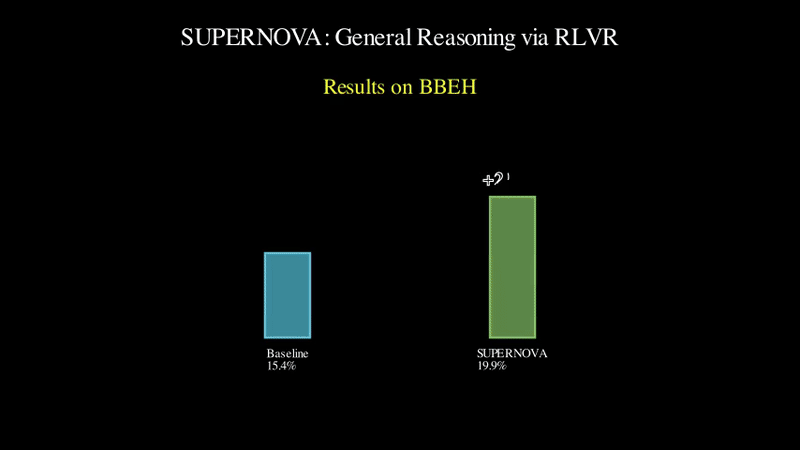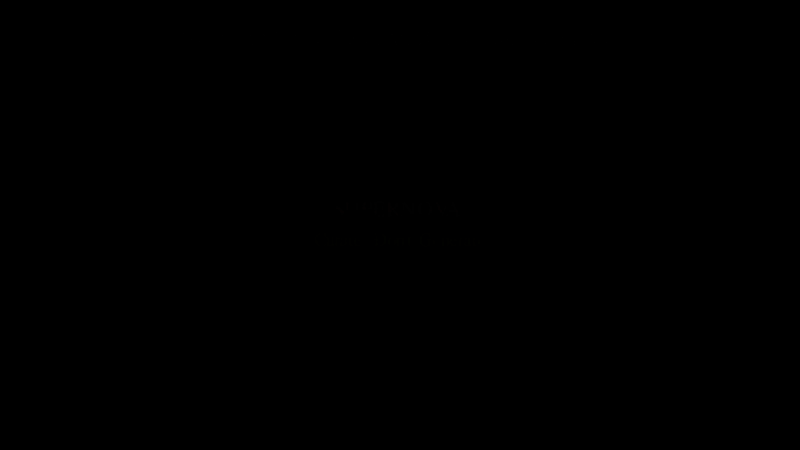
- Qwen3-4B baseline: pass@1 = 15.4%, pass@8 = 24.5%
- SUPERNOVA-4B: pass@1 = 19.9% (+29.4%), pass@8 = 35.0% (+42.9%)
- Relative improvement of up to 52.8% on BBEH across model sizes
Generalization to other benchmarks:
- BBH, MMLU-Pro, Zebralogic: +12.3% average improvement on pass@8
- SUPERNOVA-4B outperforms the larger Qwen3-8B by 8.2% on pass@8
Test-time compute scaling: Performance improves from pass@1 to pass@8, indicating the model explores more effectively during reasoning rather than memorizing answers.
Key Insights
-
Task selection is non-trivial: Training on the “wrong” instruction tasks can hurt general reasoning. Semantic similarity to the target benchmark is not predictive—empirical utility ranking via training is necessary.
-
Micro mixing beats macro mixing: Per-sub-task selection outperforms average-based selection. General reasoning is not monolithic; different skills require different training signals.
-
Quality over augmentation: Under fixed compute, carefully selected base data outperforms augmented data. The reasoning patterns in expert-annotated instructions are already rich—the bottleneck is selection, not synthesis.
-
RLVR extends beyond STEM: With principled data curation, RLVR can improve general reasoning capabilities. The key is repurposing existing human-annotated resources rather than generating new synthetic data or scraping the web.
Implications
SUPERNOVA demonstrates that the instruction-tuning datasets we already have—SuperNI, FLAN, and similar resources—contain latent reasoning structure that RLVR can exploit. The challenge is not data scarcity but data curation: identifying which tasks transfer, how to mix them, and when to stop adding complexity.
For practitioners: if you’re extending RLVR to a new domain, start with existing instruction datasets. Reformat for verifiability, rank by empirical utility, mix per-target-skill, and resist the urge to augment before you’ve exhausted selection.
For researchers: the 100+ ablation experiments in SUPERNOVA provide a template for principled data curation. The finding that micro mixing outperforms macro mixing suggests that reasoning is compositional at the skill level, not the task level—a hypothesis worth exploring in other domains.
论文: 2604.08477 作者: Ashima Suvarna, Kendrick Phan, Mehrab Beikzadeh, Hritik Bansal, Saadia Gabriel(加州大学洛杉矶分校) 分类: cs.AI
RLVR 的天花板
可验证奖励强化学习(RLVR)已经改变了形式化领域的推理——数学和代码——在这些领域中,真实答案可以自动验证。在 MATH 竞赛和 CodeForces 上训练的模型现在在 AIME24 等基准测试中实现了 +50% 的提升。但是,将这些相同的模型应用于需要因果推理、时间理解或实用推理的通用推理任务时,在 Big-Bench Extra Hard(BBEH)上的性能下降了 −8%。
问题不在于算法,而在于数据。RLVR 需要高质量、可验证的训练样本,涵盖多样化的推理技能。STEM 领域拥有丰富的此类数据:人工验证的竞赛问题、可执行的代码测试、符号证明。通用推理则没有。从网络上抓取”特定领域”的问答对(科学、商业、历史)并没有帮助——模型在 MMLU 上得分很高,但在 BBEH 上仍然失败。技能无法迁移。
SUPERNOVA 提出了不同的观察:像 SuperNI 和 FLAN 这样的指令调优数据集已经包含了数千个专家标注的任务,编码了丰富的推理模式——事件理解、问题生成、对象计数、时间图。它们只是不是为 RLVR 设计的。许多任务是开放式的(难以验证),并非所有任务都能激发强大的推理能力,而且从指令中策划 RLVR 数据的原则仍未被探索。
框架
SUPERNOVA 是一个从指令数据集中策划 RLVR 数据的多阶段流程。它通过 100 多个计算匹配的 RL 实验探索三个设计决策:
1. 任务选择
从 SuperNI 的 83 个候选任务开始,SUPERNOVA 将开放式指令重新格式化为可验证的格式(例如,多项选择题)。对于每个任务,它从模型中采样 8 个输出,计算每个问题的胜率,并删除琐碎的(胜率=1)或不可能的(胜率=0)问题。
任务按效用排序:在任务 Dk 上训练模型,在 BBEH 的 23 个子任务上评估,测量性能。排名揭示了源任务选择对下游推理有巨大影响。并非所有指令任务都是平等的。
2. 任务混合
组合排名靠前的任务的两种策略:
- 宏观混合:选择在所有 BBEH 子任务上平均性能最高的 N 个任务
- 微观混合:对于每个 BBEH 子任务,选择专门改进它的前 N 个任务,然后取并集
微观混合始终优于宏观混合。不同的推理技能受益于不同的源任务。单一的”平均最佳”混合会留下性能空间。
3. 数据干预
合成增强能否提高数据质量?SUPERNOVA 测试了在保留可验证答案的同时增加问题难度的干预措施:长上下文依赖、反先验提示、大海捞针约束、多跳推理链。
令人惊讶的结果:在固定的训练预算下,用这些干预措施增强原始数据并不能提高性能。基础指令数据在正确选择和混合后已经足够了。
结果
SUPERNOVA 策划了 25K 个 RLVR 样本,并使用 GRPO 训练 Qwen3 模型(0.6B–4B)5000 个 RL 步骤。
BBEH-test(通用推理):
- Qwen3-4B 基线:pass@1 = 15.4%,pass@8 = 24.5%
- SUPERNOVA-4B:pass@1 = 19.9%(+29.4%),pass@8 = 35.0%(+42.9%)
- 在各种模型大小上,BBEH 的相对改进高达 52.8%
泛化到其他基准测试:
- BBH、MMLU-Pro、Zebralogic:pass@8 平均提升 +12.3%
- SUPERNOVA-4B 在 pass@8 上比更大的 Qwen3-8B 高出 8.2%
测试时计算扩展: 性能从 pass@1 提高到 pass@8,表明模型在推理过程中更有效地探索,而不是记忆答案。
关键见解
-
任务选择并非微不足道:在”错误”的指令任务上训练可能会损害通用推理。与目标基准的语义相似性不具有预测性——通过训练进行经验效用排名是必要的。
-
微观混合优于宏观混合:每个子任务的选择优于基于平均值的选择。通用推理不是单一的;不同的技能需要不同的训练信号。
-
质量胜于增强:在固定计算下,精心选择的基础数据优于增强数据。专家标注指令中的推理模式已经很丰富——瓶颈在于选择,而不是合成。
-
RLVR 扩展到 STEM 之外:通过有原则的数据策划,RLVR 可以提高通用推理能力。关键是重新利用现有的人工标注资源,而不是生成新的合成数据或抓取网络。
影响
SUPERNOVA 证明了我们已经拥有的指令调优数据集——SuperNI、FLAN 和类似资源——包含 RLVR 可以利用的潜在推理结构。挑战不在于数据稀缺,而在于数据策划:识别哪些任务可以迁移、如何混合它们以及何时停止增加复杂性。
对于实践者:如果您要将 RLVR 扩展到新领域,请从现有的指令数据集开始。重新格式化以实现可验证性,按经验效用排序,按目标技能混合,并在耗尽选择之前抵制增强的冲动。
对于研究人员:SUPERNOVA 中的 100 多个消融实验为有原则的数据策划提供了模板。微观混合优于宏观混合的发现表明,推理在技能层面是组合的,而不是在任务层面——这是一个值得在其他领域探索的假设。