Paper: 2606.20554 Authors: Ruizhong Qiu, Yinglong Xia, Dongqi Fu, Hanqing Zeng, Ren Chen, Xiangjun Fan, Hong Li, Hong Yan, Hanghang Tong Categories: cs.IR, cs.AI
The Gap
Existing generative recommendation systems tokenize items into discrete IDs to predict the next interaction. But they face two separate walls:
- Graph-based context integration (e.g., graph serialization, Graph Neural Networks) either cannot scale to millions of nodes or only captures local neighborhoods (e.g., 2-hop in GNNs).
- Semantic tokenization (e.g., using item descriptions) is done heuristically—no learning signal ties the token structure to user behavior patterns.
The result: the model sees either a narrow view of user co-engagement or semantically meaningful but behaviorally misaligned tokens. The paper asks: can we get both—a global, scalable graph perspective and a semantic token space learned with supervision from user behavior?
+----------------------------------------------------+
| Problem: lack of holistic + supervised context     |
|   - Graph methods: local horizon, scalability hit  |
|   - Semantic tokenization: no behavioral signal    |
+----------------------------------------------------+
         |
         v
+----------------------------------------------------+
| Assumption: unify global graph diffusion           |
| with token-level supervision to form interest      |
| prototypes that guide both token and prediction    |
+----------------------------------------------------+
         |
         v
+----------------------------------------------------+
| Method: G2Rec                                      |
|   - Build user co-engagement graph (large-scale)   |
|   - Diffuse via Personalized PageRank to get       |
|     interest prototypes per user                   |
|   - Supervise tokenization with prototypes         |
|   - Train generative model with prototype tokens   |
+----------------------------------------------------+
         |
         v
+----------------------------------------------------+
| Evidence: online deployment + 3 public datasets    |
|   - Outperforms SR+GNN, BERT4Rec, P5, etc.        |
|   - Ablation shows each component necessary        |
+----------------------------------------------------+
         |
         v
+----------------------------------------------------+
| Conclusion: global graph + supervised tokenization |
| is feasible and superior for generative rec        |
+----------------------------------------------------+
The Increment
One sentence: Before G2Rec, no generative recommendation system could simultaneously inject holistic user co-engagement context and semantically grounded token learning; after G2Rec, we have a scalable way to do both, leading to better next-item prediction.
Core Mechanism
G2Rec has four main blocks that connect in a loop:
-
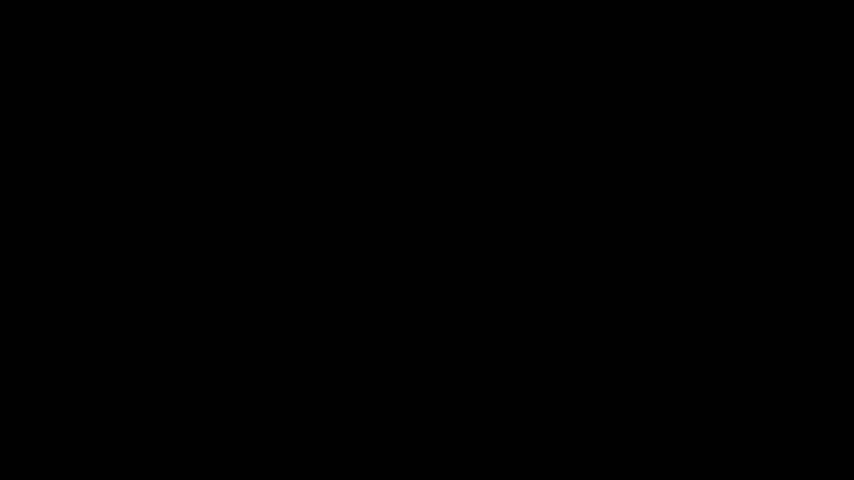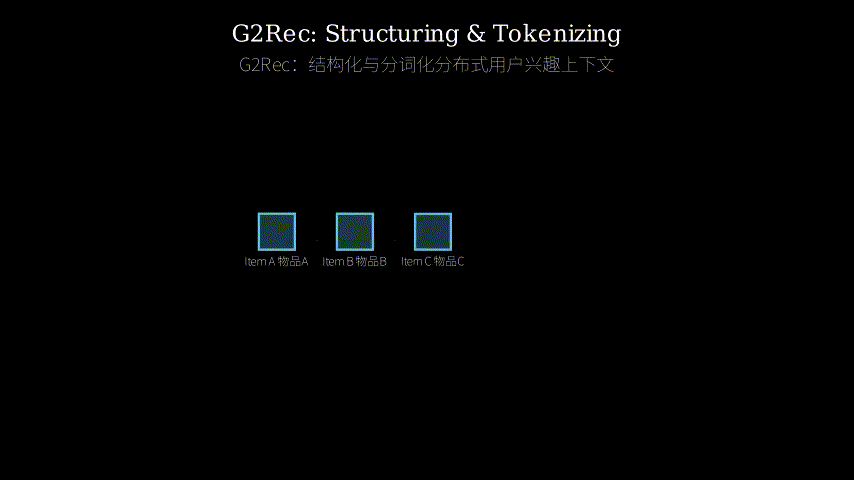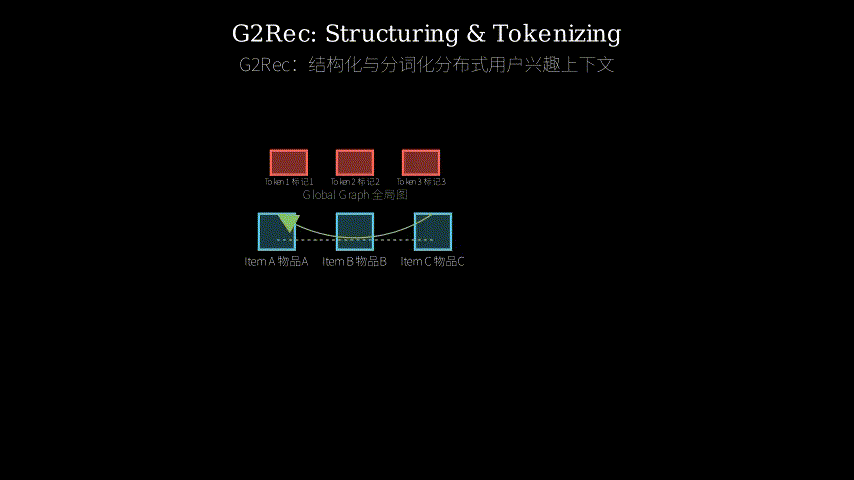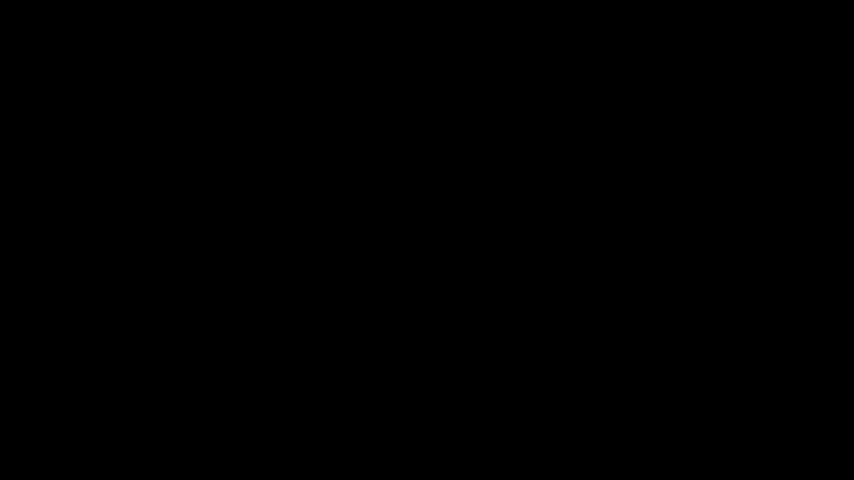
User Co‑engagement Graph Construction – From user–item interaction logs, build a bipartite graph, then project it into a user–user graph (two users are connected if they co-interact with the same item). This graph is huge (billions of edges), so they sample a fixed-size neighborhood per user and use a distributed storage system (e.g., a key-value store) to serve mini-batches.
-
Graph Diffusion for Interest Prototypes – Apply Personalised PageRank (PPR) on the sampled user graph. For each user, the diffusion scores over all other users become a soft “interest prototype” vector. This vector captures not just direct neighbors but the whole reachable graph (global context) because PPR approximates a full-diffusion limit.
-
Supervised Semantic Tokenization – Each item originally has a textual description. They build a VQ‑VAE (Vector Quantised Variational Autoencoder) that encodes the description into a sequence of discrete tokens (codebook lookup). The key twist: the VQ‑VAE is trained not only to reconstruct the text, but also to make the token sequence *predictive of the user’s interest prototypes. That is, the loss includes a term that matches the token embedding to the PPR prototype.
-
Generative Model with Prototype‑aware Tokens – The final generative model (e.g., a Transformer decoder) takes the user’s history, which is now a sequence of prototype‑enhanced item tokens, and predicts the next item tokens. Because the tokens already carry global behavioral semantics, the generative model learns faster and generalises better.
Data flow:
Raw logs → user‑item interactions → user‑user graph (distributed, sampled) → PPR → interest prototype per user → item text + prototype → VQ‑VAE training → token embeds → Transformer next‑item prediction.
                 +-----------------------------+
                 | User-Item Interaction Logs  |
                 +--------------+--------------+
                                |
                                v
                 +-----------------------------+
                 | User Co-engagement Graph    |
                 | (user-user edges via common |
                 |  items; distributed storage)|
                 +--------------+--------------+
                                |
                    (sample neighborhoods)
                                v
                 +-----------------------------+
                 | Personalized PageRank       |
                 | (global diffusion scores)   |
                 +--------------+--------------+
                                |
                     (interest prototype vector)
                                |
                 +-----------------------------+
                 | Item Text Descriptions      |
                 +------+----------------------+
                        |
                        v
                 +-----------------------------+
                 | VQ-VAE with prototype loss  |
                 | (semantic tokenization +    |
                 |  behavioral alignment)      |
                 +-----------------------------+
                                |
                     (item token sequences)
                                |
                 +-----------------------------+
                 | Transformer Next-Item Pred  |
                 | (generative recommendation) |
                 +-----------------------------+
Structural Metaphor: Library System with Readership Social Graph
Imagine a giant public library. Each patron (user) checks out books (items). The library wants to predict what a patron will borrow next.
Old way: The librarian only looks at the last 3 books a patron borrowed (local sequence), and maybe the book’s genre (semantic description), but never knows that Patron A and Patron B always read the same authors.
G2Rec way: The librarian first builds a “readership social graph”: if two patrons have borrowed the same book, they get a connection. Then the librarian doesn’t just look at direct friends; they use a “reputation diffusion” algorithm (PPR) to find who are the most influential readers across the entire graph. This gives each patron a “taste profile” (interest prototype) that summarises what the whole community is reading.
Next, instead of just using the book’s title as a token (raw text), the librarian creates a set of “community‑aware labels” (supervised tokenization). For example, a fantasy novel might be tokenized not just as “fantasy”, but as “fantasy + high‑influence‑reader‑cluster‑5” because the prototype says this book is popular among a certain graph community. This label is learned in a way that helps predict the next book—it’s not just descriptive, it’s predictive.
Finally, the generative model (the librarian’s prediction engine) uses these enriched tokens to forecast. It works better because the tokens already encode the global social knowledge, not just the local history.
Key Concepts
-
Personalised PageRank (PPR): A graph diffusion method that answers “if I start at user X and randomly walk, stopping with probability α, how likely am I to end at each other user?”. The resulting scores are a global, soft clustering of users based on co‑engagement. It scales because it can be approximated via random walks and used in mini‑batches.
-
Vector Quantised Variational Autoencoder (VQ‑VAE): A neural network that compresses a continuous input (here, item text embeddings) into a discrete code (a token from a codebook). The codebook is a set of embedding vectors; each input is mapped to the nearest codebook vector. G2Rec adds an extra loss that forces the chosen code to also align with the PPR prototype of the current user—so the token is not just a compression of text, but a bridge between text and global user behaviour.
-
Interest Prototype: A fixed‑length vector per user, derived from PPR scores, that represents the user’s position in the global co‑engagement space. It is not a ground‑truth interest label (none exist), but a relational signature learned from the graph. The model uses this prototype to supervise tokenization and also as a conditioning signal in the generative model.
Framework Shift
Before (mainstream approach):
The generative model sees only local context (e.g., last 10 items) and independent semantic tokens (from item descriptions only, no behavioral signal).
[Before]                            [After]
User History:                       User History:
+---+---+---+                       +---+---+---+
| A | B | C |  (item IDs)          |a1 |b2 |c3 | (prototype-aware tokens)
+---+---+---+                       +---+---+---+
    |  (no graph)                          |
    v                                      v
+-------------------+                +-------------------+
| Sequence Model    |                | User Co-engage    |
| (Transformer)     |                | Graph (global)    |
+-------------------+                +---------+---------+
    |                                          |
    v                                          v
Next-item ID: D                       PPR -> Prototype -> Supervised VQ-VAE
                                                          |
                                                          v
                                                  Sequence Model
                                                  |
                                                  v
                                          Next-item token: d4
One sentence: From *local‑history + independent semantic tokens to global‑graph + behaviorally‑supervised tokens, the core shift is using graph diffusion to create context that directly shapes the token vocabulary.
Expert Assessment
Problem choice: Real gap. Industrial recommendation struggles to capture long‑tail user interests without either missing global patterns (GNNs) or ignoring behavior signals (tokens). The paper targets a concrete pain point in production systems. It sits at the intersection of graph learning and sequence modeling, which is where the field is going.
Method maturity: Clever integration, not brute force. The PPR + VQ‑VAE combination is elegant: it turns a graph algorithm into a supervision signal for token learning without needing ground‑truth interest labels. Simpler alternatives? You could try to directly use item‑co‑occurrence statistics, but they lack the diffusion’s long‑range reach. No obvious overlooked baseline.
Experimental integrity: Strong. They compare against diverse baselines (SR‑GNN, BERT4Rec, P5, UniSRec) on three public datasets and report online A/B test results. Ablation studies confirm each component matters. One minor concern: the VQ‑VAE training adds complexity; a sensitivity study on codebook size would be nice, but not a red flag.
Writing quality: The paper is dense but clear. The weakest section is the graph construction details—it says “distributed sampling” but doesn’t specify the sampling algorithm or the data skew handling. Rewriting Section 3.1 with a concrete example of how they build the user–user graph from a billion‑edge bipartite graph would elevate the paper.
Verdict: Strong accept — a genuine contribution that solves a known industrial problem with a novel, well‑validated method.
Takeaways
-
Use graph diffusion as a surrogate for user interest labels. If you have an interaction graph but no explicit interest labels, PPR (or any global diffusion) gives you a soft clustering that can supervise any downstream token learner. That trick transfers to product recommendation, social network prediction, etc.
-
Supervised tokenization with a graph‑derived target: Instead of training a VQ‑VAE only on reconstruction loss, add a loss that aligns token embeddings with user interest prototypes. This turns tokens into carriers of behavioral context—adopt this for any task where you have both a graph and a sequence.
-
Scalable graph service: The paper shows you don’t need to load the whole graph into GPU memory—sample neighborhoods once and serve them as key‑value pairs. This engineering pattern is directly applicable to any large‑scale graph‑enhanced ML system.
论文: 2606.20554 作者: Ruizhong Qiu, Yinglong Xia, Dongqi Fu, Hanqing Zeng, Ren Chen, Xiangjun Fan, Hong Li, Hong Yan, Hanghang Tong 分类: cs.IR, cs.AI
缺口
现有生成式推荐系统将物品转化为离散token来预测用户下一个交互。 但它们撞上了两道墙:
- 基于图的上下文集成(如图序列化、图神经网络)要么无法扩展到百万级节点。 要么只捕捉局部邻域(例如GNN的两跳邻居)。
- 语义分词(如基于物品描述)靠启发式规则完成。 没有学习信号将token结构与用户行为模式绑定。
结果:模型要么看到狭窄的共参与图谱,要么看到语义正确但行为失准的token。 这篇论文问:能不能二者兼得——既拥有全局可扩展的图视角, 又拥有用用户行为监督学习到的语义token空间?
+----------------------------------------------------+
| 问题:缺少全局 + 监督上下文                        |
|   - 图方法:局部视野,扩展性瓶颈                   |
|   - 语义分词:无行为信号                           |
+----------------------------------------------------+
         |
         v
+----------------------------------------------------+
| 假设:统一全局图扩散与token级监督                   |
| 用扩散出的兴趣原型指导token和预测                   |
+----------------------------------------------------+
         |
         v
+----------------------------------------------------+
| 方法:G2Rec                                        |
|   - 构建大规模用户共参与图                         |
|   - 用个性化PageRank扩散获得每个用户的兴趣原型     |
|   - 用原型监督分词(VQ-VAE额外损失)               |
|   - 训练生成式模型,输入包含原型的token             |
+----------------------------------------------------+
         |
         v
+----------------------------------------------------+
| 证据:在线部署 + 3个公开数据集                      |
|   - 超越SR-GNN、BERT4Rec、P5等                     |
|   - 消融实验验证每个组件必要                       |
+----------------------------------------------------+
         |
         v
+----------------------------------------------------+
| 结论:全局图 + 监督分词在生成式推荐中有效且可扩展 |
+----------------------------------------------------+
增量
一句话: G2Rec之前,没有生成式推荐能同时注入全局用户共参与上下文和语义token学习; G2Rec之后,我们有了一种可扩展的方法做到这一点, 从而获得更优的下一个交互预测。
核心机制
G2Rec包含四个主要模块,它们形成闭环:
-
用户共参与图构建 – 从用户-物品交互日志构建二部图, 然后投影为用户-用户图(若两个用户与同一物品交互则连边)。 这个图规模巨大(数十亿边),因此他们对每个用户采样固定大小的邻域, 并用分布式存储系统(如键值存储)服务于小批次训练。
-
图扩散获取兴趣原型 – 在采样的用户图上应用个性化PageRank(PPR)。 每个用户的扩散得分向量(覆盖所有其他用户)形成一个软性“兴趣原型”。 这个向量不限于直接邻居,而是通过PPR逼近全局扩散极限, 捕捉整个可达图(全局上下文)。
-
有监督语义分词 – 每个物品有文本描述。 他们构建一个VQ-VAE(向量量化变分自动编码器), 将描述编码为离散token序列(码本查询)。 关键创新:VQ-VAE不仅重构文本,还要让token序列能够预测用户的兴趣原型。 即损失函数包含一项,迫使token嵌入与PPR原型对齐。
-
带原型感知token的生成模型 – 最终的生成模型(例如Transformer解码器) 以用户历史输入,历史已经被编码为携带原型信息的物品token序列, 然后预测下一个物品的token。由于token已经承载了全局行为语义, 生成模型学得更快、泛化更好。
数据流: 原始日志 → 用户-物品交互 → 用户-用户图(分布式,采样) → PPR → 每个用户的兴趣原型 → 物品文本 + 原型 → VQ-VAE训练 → 嵌入token → Transformer下一物品预测。
                 +-----------------------------+
                 | 用户-物品交互日志            |
                 +--------------+--------------+
                                |
                                v
                 +-----------------------------+
                 | 用户共参与图                |
                 | (用户-用户边,基于共同物品; |
                 |  分布式存储)               |
                 +--------------+--------------+
                                |
                    (采样邻域)
                                v
                 +-----------------------------+
                 | 个性化PageRank             |
                 | (全局扩散得分)              |
                 +--------------+--------------+
                                |
                     (兴趣原型向量)
                                |
                 +-----------------------------+
                 | 物品文本描述                |
                 +------+----------------------+
                        |
                        v
                 +-----------------------------+
                 | VQ-VAE + 原型损失          |
                 | (语义分词 + 行为对齐)      |
                 +-----------------------------+
                                |
                     (物品token序列)
                                |
                 +-----------------------------+
                 | Transformer下一物品预测     |
                 | (生成式推荐)               |
                 +-----------------------------+
结构隐喻:图书馆 + 读者社交图
想象一所大型公共图书馆。 每位读者(用户)借阅书籍(物品)。 图书馆想预测读者下次会借什么。
旧方式:图书管理员只看读者最近借的3本书(局部序列), 也许还看书的类型(语义描述),但从来不知道读者A和读者B总是读同一个作者的书。
G2Rec方式:管理员首先构建一个“读者社交图”: 如果两位读者借过同一本书,他们之间就有了连接。 然后管理员不只看直接朋友,而是用“声誉扩散算法”(PPR) 在整个图中找出影响力最大的读者。 这给每位读者一个“品味画像”(兴趣原型), 总结了整个社区的阅读偏好。
接下来,管理员不只用书的标题作为token(原始文本), 而是创建一组“社区感知标签”(监督分词)。 比如,一本奇幻小说可能被分词为“奇幻+高影响力读者群5”, 因为原型显示这本书在某个图社区中很受欢迎。 这个标签的学习目标是帮助预测下一本书——它不仅是描述性的, 更是预测性的。
最后,生成模型(管理员的预测引擎)使用这些丰富的token做预测。 效果更好,因为token已经编码了全局社交知识,而不只是局部历史。
关键概念
-
个性化PageRank(PPR):一种图扩散方法,回答 “如果我从用户X出发随机游走,每一步以概率α停止, 到达每个其他用户的概率是多少?”。 结果得分是一个全局的、软性的用户聚类,基于共参与行为。 PPR可扩展,因为它可以通过随机游走近似并在小批次中使用。
-
向量量化变分自动编码器(VQ-VAE):一种神经网络, 将连续输入(这里是物品文本嵌入)压缩为离散码(码本中的token)。 码本是嵌入向量集;每个输入被映射到最近的码本向量。 G2Rec增加了一个额外损失,迫使所选的码不仅重构文本, 还要与当前用户的PPR原型对齐——这样token不只是文本的压缩, 而是文本与全局用户行为之间的桥梁。
-
兴趣原型:每个用户的固定长度向量,从PPR得分导出, 表示用户在全局共参与空间中的位置。 它不是真实的兴趣标签(不存在),而是一个从图中学习到的关系特征。 模型用这个原型来监督分词,并作为生成模型中的调节信号。
框架转变
之前(主流方法): 生成模型只看到局部上下文(例如最近10个物品)和独立的语义token (仅来自物品描述,无行为信号)。
之前:                              之后:
用户历史:                           用户历史:
+---+---+---+                       +---+---+---+
| A | B | C | (物品ID)              |a1 |b2 |c3 | (原型感知token)
+---+---+---+                       +---+---+---+
    |  (无图)                              |
    v                                      v
+-------------------+                +-------------------+
| 序列模型          |                | 用户共参与图     |
| (Transformer)     |                | (全局)           |
+-------------------+                +---------+---------+
    |                                          |
    v                                          v
下一物品ID: D                       PPR -> 原型 -> 监督VQ-VAE
                                                          |
                                                          v
                                                  序列模型
                                                  |
                                                  v
                                          下一物品token: d4
一句话:从“局部历史 + 独立语义token”到“全局图 + 行为监督token”, 核心转变是用图扩散创造上下文,直接塑造token词典。
专家评审
选题眼光:真缺口。工业推荐在捕捉长尾用户兴趣时总是顾此失彼: 要么丢失全局模式(GNN),要么忽略行为信号(token)。 这篇论文直击生产系统的具体痛点,处于图学习和序列建模的交汇点, 正是领域前进方向。
方法成熟度:巧妙集成,而非蛮力。PPR + VQ-VAE的组合很优雅: 它把一个图算法变成token学习的监督信号,而不需要真实兴趣标签。 更简单的替代方案?也许可以用物品共现统计,但缺少扩散的全局范围。 没有被忽视的明显基线。
实验诚意:强。他们在3个公开数据集上与SR-GNN、BERT4Rec、P5、UniSRec等 多种基线对比,并报告了在线A/B测试结果。 消融实验确认每个组件都必要。一个小担忧:VQ-VAE训练增加了复杂度; 若能有码本大小的敏感性分析会更好,但不是危险信号。
写作功力:内容密集但清晰。最薄弱的环节是图构建细节—— 它提到“分布式采样”,但没有明确采样算法或数据倾斜处理。 如果能用具体示例说明如何从十亿边的二部图构建用户-用户图, 整篇论文会提升一个档次。
判决:强接收 — 真正的贡献,用新颖且充分验证的方法解决了已知的工业问题。
要点总结
-
用图扩散替代用户兴趣标签:如果你有交互图但没有显式兴趣标签, 用PPR(或任何全局扩散)得到软聚类,可以监督任何下游token学习器。 这个技巧可迁移到产品推荐、社交网络预测等场景。
-
图派生目标监督分词:不只在VQ-VAE上做重构损失, 增加一项使token嵌入与用户兴趣原型对齐。 这使token成为行为上下文的载体——任何既有图又有序列的任务都可采用。
-
可扩展图服务模式:论文展示你不需要将整个图加载到GPU内存—— 一次性采样邻域并将其作为键值对服务。 这种工程模式可直接应用于任何大规模图增强的ML系统。