Paper: 2603.08682 Authors: Simon Bing, Jonas Wahl, Jakob Runge Categories: stat.ML, cs.LG
The Gap
Causal inference in high-dimensional settings hits a wall: you need massive samples to estimate effects between, say, 10,000-dimensional images. Existing approaches split into two camps. Causal representation learning tries to discover latent variables that explain the data, but requires strong assumptions about the data-generating process. Causal abstraction learning maps high-level variables to low-level ones, but focuses on consistency rather than estimation efficiency. Neither directly addresses the practical question: what if causal effects only depend on a small part of the cause?
Problem: High-dim X -> High-dim Y needs huge samples
         |
         v
Assumption: Effect only depends on low-dim summary of X
         |
         v
Method: Learn bottleneck B = f(X), then Y = g(B, noise)
         |
         v
Evidence: Identifiable under conditions + works in transfer learning
         |
         v
Conclusion: Practical causal inference in high-dim via bottlenecks
The Increment
One sentence: Before, you either avoided high-dimensional causal inference or made strong assumptions about latent structure; now, you can explicitly model that effects flow through low-dimensional summaries while keeping estimation tractable.
Core Mechanism
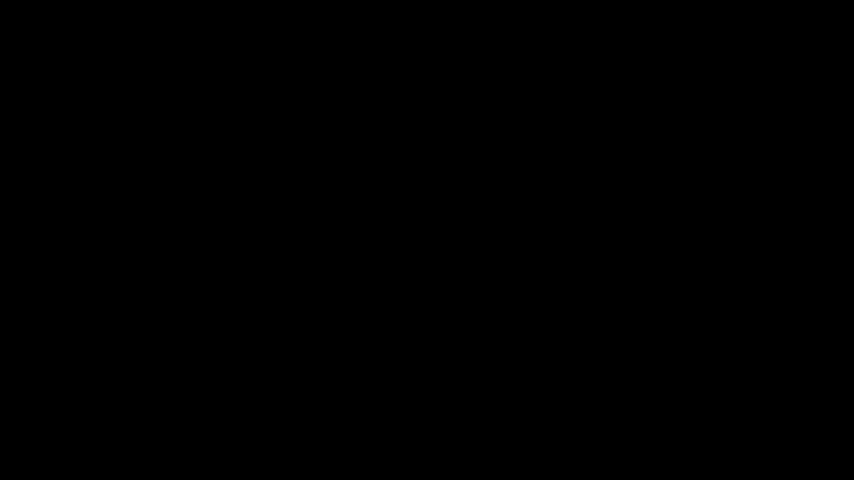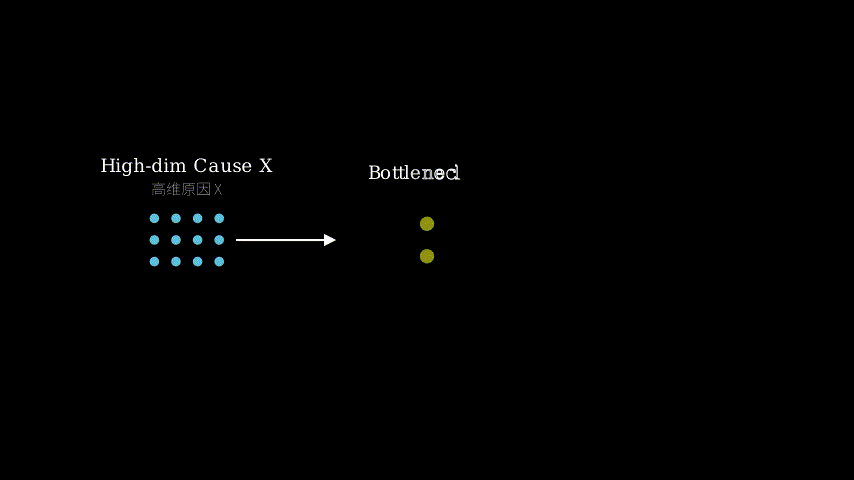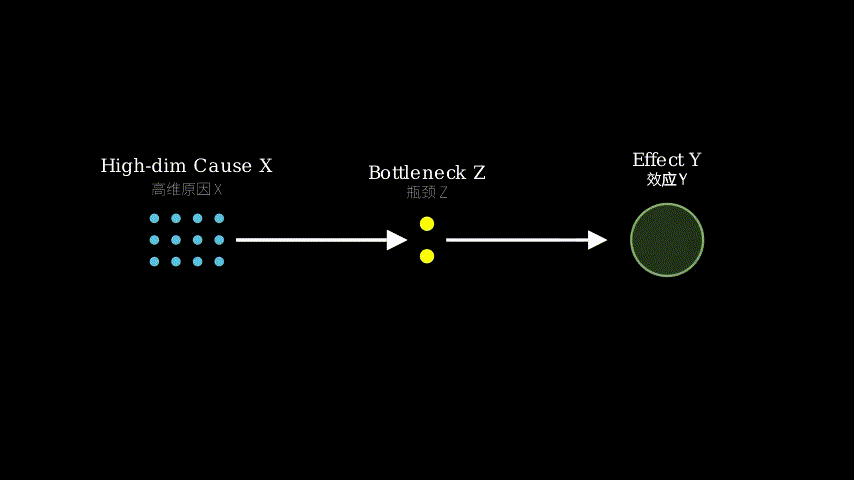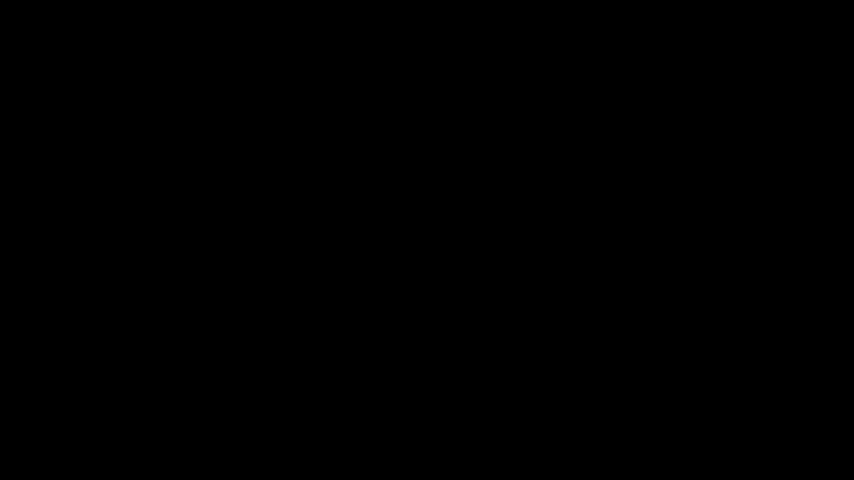
The method introduces a bottleneck layer between cause and effect. Instead of modeling Y = f(X, noise) directly where X is high-dimensional, you split it: first compress X into a low-dimensional bottleneck B = h(X), then model Y = g(B, noise). The key constraint is that B must be sufficient for predicting Y—all information X has about Y flows through B.
The framework allows task-specific bottlenecks. If you care about predicting Y₁, you learn bottleneck B₁. If you care about Y₂, you learn B₂. Different effects can have different bottlenecks, each capturing only what matters for that particular causal relationship. This contrasts with representation learning, which seeks one universal latent space.
Estimation uses standard algorithms: train neural networks to learn the bottleneck function h and effect function g jointly, with a dimensionality constraint on B. The authors connect this to information bottleneck theory—you’re finding the minimal sufficient statistic of X for predicting Y. For identifiability, they show that under certain conditions (like having multiple contexts or interventions), you can uniquely recover the bottleneck structure.
High-dim cause X                    Effect Y
    |                                  ^
    |                                  |
    v                                  |
[Encoder h]                            |
    |                                  |
    v                                  |
Low-dim bottleneck B ----------------[Decoder g]
    |
    +---> (Sufficient for Y)
    +---> (Minimal dimension)
Think of it like airport security screening. Thousands of passengers (high-dimensional X) pass through, but security only checks a few key things: ID, boarding pass, metal detector reading (low-dimensional bottleneck B). The decision to let you board (effect Y) depends only on these summaries, not on your entire life history. Different checkpoints might check different things—international flights add passport checks, while domestic flights don’t. Each checkpoint has its own bottleneck tailored to its specific decision. The system works because these summaries are sufficient: they capture everything relevant about you for that particular decision, even though they throw away most information.
Key Concepts
-
Causal Sufficiency vs Statistical Sufficiency: In statistics, a sufficient statistic captures all information in data about a parameter. Here, causal sufficiency means the bottleneck B captures all information X has about Y through the causal mechanism. Crucially, B might not be sufficient for predicting X from Y (the reverse direction), and it’s defined relative to a specific effect. Example: To predict if someone will get lung cancer (Y) from their medical history (X), smoking status and genetic markers (B) might be causally sufficient—you don’t need to know their childhood pet’s name, even though that’s in X.
-
Task-Specific Bottlenecks: Unlike representation learning which seeks one “true” latent space, SCBMs allow different bottlenecks for different causal questions. If X causes both Y₁ and Y₂, you might have B₁ = h₁(X) for predicting Y₁ and B₂ = h₂(X) for predicting Y₂, where B₁ and B₂ are different. Example: From a patient’s full medical record (X), predicting diabetes risk (Y₁) might only need BMI and blood sugar (B₁), while predicting heart disease risk (Y₂) needs blood pressure and cholesterol (B₂). Same cause, different bottlenecks.
Framework Shift
Before (causal representation learning):     After (SCBMs):

X (observed) -----> Y (observed)            X (observed) -----> Y (observed)
    ^                   ^                       |                   ^
    |                   |                       v                   |
    |                   |                   [Bottleneck B]          |
    +---[Latent Z]-----+                       |                   |
                                               +-------------------+
Goal: Find universal Z                     Goal: Find minimal B per task
Assumption: Z generates X and Y            Assumption: Effect flows through B
[One sentence: From seeking universal latent representations that generate all variables, to finding minimal task-specific summaries through which causal effects flow.]
Expert Assessment
Problem choice: Real gap. High-dimensional causal inference is genuinely hard, and the bottleneck assumption is reasonable for many domains—think image classification where only certain features matter, or genomics where effects operate through pathways. The positioning against causal representation learning is smart: they’re solving a different problem (estimation efficiency) rather than competing directly.
Method maturity: Mostly repackaging existing ideas (information bottleneck, sufficient statistics) in a causal framework, but that’s valuable. The identifiability analysis is solid though not groundbreaking—it requires multiple contexts or interventions, which is standard. The connection to information bottleneck is natural but not deeply exploited; they could push harder on rate-distortion tradeoffs.
Experimental integrity: Experiments are illustrative rather than comprehensive. The transfer learning demo is compelling but limited to synthetic data and one real dataset. Missing: comparisons with recent causal representation learning methods, ablations on bottleneck dimension selection, and failure cases. The paper reads more like a framework proposal than an empirical validation.
Writing quality: Clear exposition of the framework, but the related work section undersells how much this overlaps with existing sufficient dimension reduction and information bottleneck literature. The identifiability section is dense—moving some proofs to appendix and adding intuitive examples would help. The experimental section feels rushed; spending more space on when bottlenecks help vs hurt would strengthen the paper.
Verdict: weak accept — Solid conceptual contribution that clarifies the role of bottlenecks in causal inference, but needs stronger empirical validation and clearer positioning relative to existing dimension reduction methods.
Takeaways
Steal the task-specific bottleneck idea: when building causal models, don’t assume you need one representation for everything. Learn different low-dimensional summaries for different downstream tasks. This is especially useful in transfer learning—train a bottleneck on source domain, freeze it, adapt only the effect model on target domain with few samples.
Practical trick: when estimating high-dimensional causal effects, add an explicit bottleneck layer with dimensionality constraint rather than hoping your neural network learns sparse representations implicitly. This gives you control and interpretability.
The identifiability conditions tell you when you can trust your bottleneck: you need variation across contexts (different distributions) or interventions. If you only have observational data from one distribution, your bottleneck might be arbitrary.
论文: 2603.08682 作者: Simon Bing, Jonas Wahl, Jakob Runge 分类: stat.ML, cs.LG
缺口
高维环境下的因果推断遇到了瓶颈:要估计比如两个10000维图像之间的因果效应,需要海量样本。
现有方法分成两派。
因果表征学习试图发现解释数据的潜变量,但需要对数据生成过程做强假设。
因果抽象学习将高层变量映射到低层变量,但关注一致性而非估计效率。
两者都没有直接解决实际问题:如果因果效应只依赖于原因的一小部分怎么办?
问题:高维 X -> 高维 Y 需要巨量样本
         |
         v
假设:效应只依赖于 X 的低维摘要
         |
         v
方法:学习瓶颈 B = f(X),然后 Y = g(B, 噪声)
         |
         v
证据:特定条件下可识别 + 迁移学习有效
         |
         v
结论:通过瓶颈实现高维实用因果推断
增量
一句话: 以前要么回避高维因果推断,要么对潜在结构做强假设;现在可以显式建模效应通过低维摘要流动,同时保持估计可行。
核心机制
该方法在原因和效应之间引入瓶颈层。
不直接建模 Y = f(X, 噪声)(其中 X 是高维的),而是拆成两步:先把 X 压缩成低维瓶颈 B = h(X),再建模 Y = g(B, 噪声)。
关键约束是 B 必须足以预测 Y——X 关于 Y 的所有信息都通过 B 流动。
框架允许任务特定的瓶颈。
如果你关心预测 Y₁,就学习瓶颈 B₁。
如果关心 Y₂,就学习 B₂。
不同效应可以有不同瓶颈,每个只捕获对特定因果关系重要的东西。
这与表征学习不同,后者寻求一个通用的潜在空间。
估计使用标准算法:训练神经网络联合学习瓶颈函数 h 和效应函数 g,对 B 施加维度约束。
作者将此与信息瓶颈理论联系起来——你在寻找 X 预测 Y 的最小充分统计量。
对于可识别性,他们证明在特定条件下(如有多个上下文或干预),可以唯一恢复瓶颈结构。
高维原因 X                      效应 Y
    |                            ^
    |                            |
    v                            |
[编码器 h]                       |
    |                            |
    v                            |
低维瓶颈 B --------------------[解码器 g]
    |
    +---> (对 Y 充分)
    +---> (最小维度)
把它想象成机场安检。
成千上万的乘客(高维 X)通过,但安检只检查几个关键项:身份证、登机牌、金属探测器读数(低维瓶颈 B)。
让你登机的决定(效应 Y)只依赖这些摘要,而非你的整个人生历史。
不同检查点可能检查不同东西——国际航班加护照检查,国内航班不加。
每个检查点都有针对其特定决定的瓶颈。
系统有效是因为这些摘要是充分的:它们捕获了关于你对那个特定决定的所有相关信息,尽管丢弃了大部分信息。
关键概念
- 因果充分性 vs 统计充分性: 在统计学中,充分统计量捕获数据中关于参数的所有信息。
这里,因果充分性意味着瓶颈 B 捕获 X 通过因果机制关于 Y 的所有信息。
关键是,B 可能不足以从 Y 预测 X(反向),且它是相对于特定效应定义的。
例子:要从病史(X)预测某人是否得肺癌(Y),吸烟状态和遗传标记(B)可能是因果充分的——你不需要知道他们童年宠物的名字,尽管那在 X 里。
- 任务特定瓶颈: 与寻求一个”真实”潜在空间的表征学习不同,SCBM 允许不同因果问题有不同瓶颈。
如果 X 同时导致 Y₁ 和 Y₂,你可能有 B₁ = h₁(X) 用于预测 Y₁,B₂ = h₂(X) 用于预测 Y₂,其中 B₁ 和 B₂ 不同。
例子:从患者完整病历(X),预测糖尿病风险(Y₁)可能只需要 BMI 和血糖(B₁),而预测心脏病风险(Y₂)需要血压和胆固醇(B₂)。
同一原因,不同瓶颈。
框架转变
之前(因果表征学习):              之后(SCBM):

X (观测) -----> Y (观测)           X (观测) -----> Y (观测)
    ^               ^                  |               ^
    |               |                  v               |
    |               |              [瓶颈 B]            |
    +---[潜变量 Z]--+                  |               |
                                       +---------------+
目标:找通用 Z                      目标:找每个任务的最小 B
假设:Z 生成 X 和 Y                假设:效应通过 B 流动
[一句话:从寻求生成所有变量的通用潜在表征,到寻找因果效应流经的最小任务特定摘要。
]
专家评审
选题眼光: 真实缺口。
高维因果推断确实很难,瓶颈假设对许多领域合理——想想图像分类中只有某些特征重要,或基因组学中效应通过通路运作。
相对因果表征学习的定位很聪明:他们在解决不同问题(估计效率)而非直接竞争。
方法成熟度: 主要是在因果框架中重新包装现有想法(信息瓶颈、充分统计量),但这有价值。
可识别性分析扎实但不算突破——需要多个上下文或干预,这是标准要求。
与信息瓶颈的联系自然但未深入挖掘;他们可以在率失真权衡上推进更多。
实验诚意: 实验是说明性的而非全面的。
迁移学习演示有说服力但局限于合成数据和一个真实数据集。
缺失:与最近因果表征学习方法的比较、瓶颈维度选择的消融实验、失败案例。
论文读起来更像框架提案而非实证验证。
写作功力: 框架阐述清晰,但相关工作部分低估了这与现有充分降维和信息瓶颈文献的重叠程度。
可识别性部分很密集——把一些证明移到附录并添加直观例子会有帮助。
实验部分感觉仓促;花更多篇幅讨论瓶颈何时有帮助何时有害会加强论文。
判决: 弱接收 — 澄清瓶颈在因果推断中作用的扎实概念贡献,但需要更强的实证验证和相对现有降维方法更清晰的定位。
要点总结
偷走任务特定瓶颈的想法:构建因果模型时,不要假设你需要一个表征应对所有事情。
为不同下游任务学习不同的低维摘要。
这在迁移学习中特别有用——在源域训练瓶颈,冻结它,在目标域用少量样本只调整效应模型。
实用技巧:估计高维因果效应时,添加带维度约束的显式瓶颈层,而非期望神经网络隐式学习稀疏表征。
这给你控制和可解释性。
可识别性条件告诉你何时可以信任瓶颈:需要跨上下文(不同分布)或干预的变化。
如果只有来自一个分布的观测数据,你的瓶颈可能是任意的。