Paper: 2606.05158 Authors: Zhen Yang, Xiaogang Xu, Wen Wang, Cong Chen, Xander Xu, Ying-Cong Chen Categories: cs.CL, cs.AI, cs.MA
The Gap
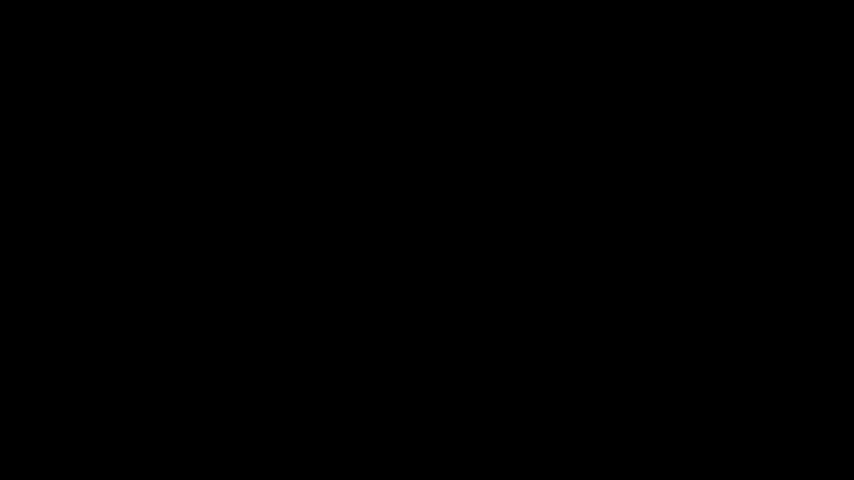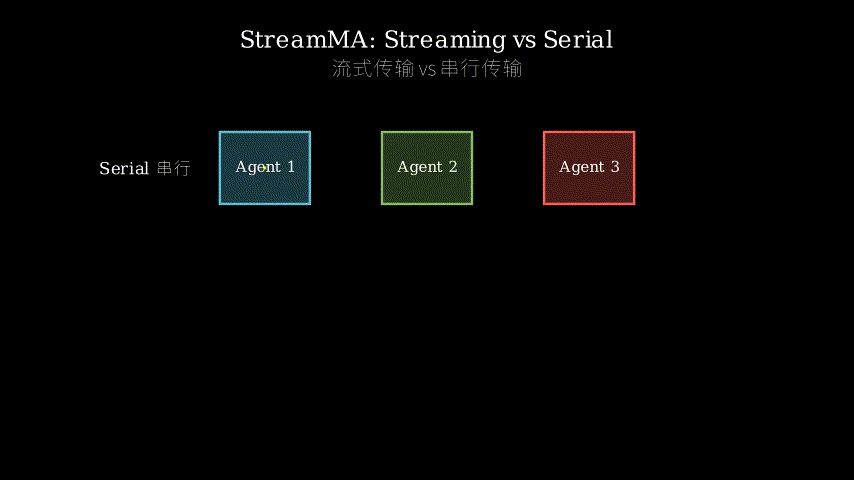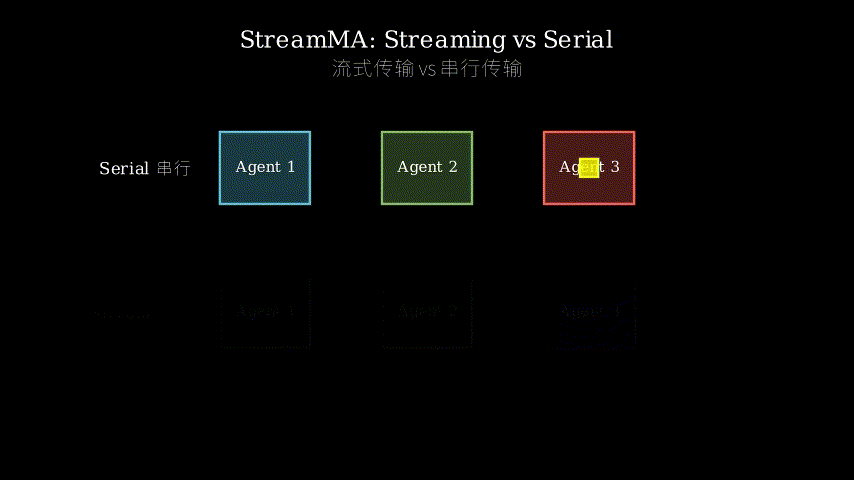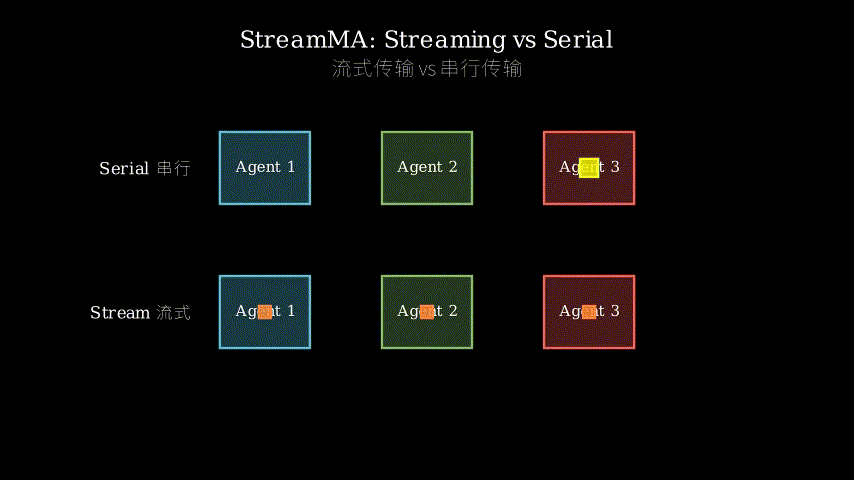
Multi-agent reasoning systems like Chain-of-Thought with multiple LLMs have adopted a serial “generate-then-transfer” paradigm: Agent 1 completes its full reasoning chain, then Agent 2 starts working on the complete output, and so on. This creates two problems. First, latency scales linearly with pipeline depth—each agent is a blocking stage. Second, when Agent 1 produces a long reasoning chain, errors accumulate toward the end, but Agent 2 must consume the entire chain including the unreliable tail.
Prior work focused on scaling agent count or improving individual reasoning quality, but ignored the pipeline structure itself. No one asked: what if agents could start working before their upstream dependency finishes?
Problem: Serial multi-agent pipeline
    |
    v
Observation: Early reasoning steps > late steps in quality
    |
    v
Hypothesis: Streaming partial results enables pipelining + filters bad steps
    |
    v
Method: StreamMA (stream each step as generated)
    |
    v
Evidence: -47% latency, +7.3pp accuracy across 8 benchmarks
    |
    v
Conclusion: Pipelining is both faster AND more effective
The Increment
One sentence: Before this paper, multi-agent systems blocked on full reasoning chains; after it, agents pipeline by consuming partial chains as they stream, gaining both speed and accuracy.
Core Mechanism
StreamMA replaces end-to-end generation with step-by-step streaming. When Agent 1 generates reasoning step 1, it immediately forwards that step to Agent 2 while continuing to generate step 2. Agent 2 starts processing step 1 before Agent 1 finishes the full chain. This continues recursively: Agent 2’s first output step streams to Agent 3, and so on.
The system has three key components. A step detector identifies reasoning step boundaries in the token stream (e.g., recognizing “Step 1:”, “Therefore,” or numbered items). A forward buffer holds completed steps and triggers downstream transmission. A consumption scheduler decides when downstream agents should start—either immediately upon receiving the first step (eager mode) or after accumulating a few steps (buffered mode).
Data flows like this: Agent 1 generates tokens → step detector identifies boundary → forward buffer releases step k → Agent 2 receives step k and begins processing → Agent 2’s step detector identifies its own boundaries → forward buffer releases to Agent 3. Each agent maintains its own generation thread and consumption thread, decoupling upstream latency from downstream progress.
Structural metaphor: Think of a restaurant kitchen with multiple stations (prep, grill, plating). Traditional multi-agent systems work like waiting for the entire prep station to finish chopping all vegetables before the grill station can start cooking anything. StreamMA is like mise en place pipelining: as soon as the prep station finishes chopping the first ingredient, it slides the cutting board to the grill station, which starts cooking immediately while prep continues chopping the next ingredient. The plating station doesn’t wait for all cooking to finish—it starts arranging the first cooked item while others are still on the grill. Each station works in parallel, and faster turnover means diners get served sooner. The surprise: this also improves quality, because if the prep station gets sloppy toward the end (say, unevenly chopped garlic), those bad ingredients arrive late and can be caught or adjusted by downstream stations, rather than being mixed into a single batch that ruins the whole dish.
Key Concepts
-
Step-level granularity: Traditional systems operate at task-level granularity—Agent 1 outputs a complete solution, Agent 2 consumes it whole. StreamMA operates at step-level granularity—Agent 1 outputs “Step 1: Define variables”, Agent 2 starts working with just that. This is like the difference between shipping a finished product versus shipping components as they roll off the assembly line. Finer granularity enables parallelism but requires identifying clean boundaries. The paper uses heuristics (numbered steps, logical connectives) and optionally trains a boundary detector.
-
Quality non-uniformity in reasoning chains: Not all steps in a reasoning chain are equally reliable. Empirically, early steps (problem setup, variable definitions, initial constraints) have higher accuracy because they’re more constrained by the problem statement. Late steps (algebraic manipulation, edge case handling) accumulate errors from earlier mistakes and introduce new errors through complex operations. StreamMA exploits this by letting downstream agents work with reliable early steps before the full chain completes. If Agent 1’s step 5 contains an error, Agent 2 has already correctly processed steps 1-4, whereas in serial mode, Agent 2 would wait and then consume the entire error-prone chain.
-
Closed-form latency analysis: The paper derives exact formulas for end-to-end latency under different protocols. For a chain of n agents where each generates k steps at rate r tokens/sec, serial latency is n × k/r (agents run sequentially). StreamMA latency is k/r + (n-1) × 1/r (first agent generates all k steps, then each subsequent agent adds only 1 step of delay because they start early). The speedup approaches n as k grows—adding more reasoning steps increases the benefit of pipelining. This is a rare closed-form result in LLM systems research, making the tradeoffs transparent.
Framework Shift
Before (serial generate-then-transfer):

Agent 1:  [========== generate all 10 steps ==========]
                                                        |
Agent 2:                                                [===== generate 5 steps =====]
                                                                                      |
Agent 3:                                                                              [=== gen 3 ===]

Timeline: |-------- A1 --------|----- A2 -----|-- A3 --|
Latency:  t1 = 10/r            t2 = 5/r       t3 = 3/r
Total:    18/r


After (StreamMA streaming):

Agent 1:  [Step1][Step2][Step3][Step4]...[Step10]
            |      |      |      |          |
Agent 2:    [S1   ][S2   ][S3   ][S4   ][S5   ]
              |      |      |      |      |
Agent 3:      [S1  ][S2  ][S3  ]

Timeline: |-- A1 starts --|
          |  A2 starts (after 1 step delay)
          |    A3 starts (after 1 step delay from A2)
Latency:  10/r + 1/r + 1/r = 12/r

Speedup:  18/12 = 1.5x
From blocking sequential execution to overlapping pipelined execution, the core shift is treating reasoning as a stream of incremental units rather than a monolithic output.
Expert Assessment
Problem choice: Real gap. Multi-agent systems are increasingly popular (ReAct, AutoGPT, MetaGPT), and latency is a first-order concern for production deployment. The observation that streaming could improve *both speed and accuracy is non-obvious—most streaming work trades quality for latency. The step-quality hypothesis is empirically grounded (they measure step-wise accuracy decay) rather than assumed.
Method maturity: Elegant in its simplicity. The core idea—stream partial results—requires minimal changes to existing multi-agent frameworks. The step detector is heuristic-based (regex on numbered steps), which feels brittle but works across diverse reasoning formats. A learned boundary detector would be more robust but adds complexity. The closed-form analysis is a major strength, rare in empirical LLM papers. One overlooked angle: what about error propagation? If Agent 1’s step 3 is wrong, Agent 2 builds on it immediately, potentially amplifying the error. The paper shows net improvement but doesn’t decompose when streaming helps versus hurts.
Experimental integrity: Baselines are fair—serial multi-agent and single-agent with extended reasoning. Eight benchmarks spanning math (MATH, AIME), science (GPQA), and code (HumanEval) provide breadth. Two frontier models (Claude Opus 4.6, GPT-5.4) and three topologies (chain, tree, graph) test generalization. The numbers are large: +22.4pp on HMMT 2026 is striking. One red flag: all experiments use the same step detector heuristics. Would a learned detector change the ranking? The cost analysis (API tokens) is honest—StreamMA uses more tokens due to overlapping generation, but the speedup justifies it.
Writing quality: Introduction and core mechanism are crisp. The closed-form analysis section is dense—burying key intuitions in lemmas. Rewriting Sections 3-4 to lead with the geometric insight (pipelining saves n-1 agent delays) before the math would help. The “step-level scaling law” claim in the abstract is under-supported—one figure shows the trend but doesn’t establish it as a law. The related work conflates streaming generation (existing) with streaming inter-agent communication (novel).
Verdict: strong accept — Solves a real problem with a simple, theoretically grounded method, and the experimental evidence is comprehensive.
Takeaways
-
Granularity as a design lever: When building pipelines (LLM or otherwise), ask whether coarse-grained blocking (wait for full output) is necessary or just habitual. Finer granularity enables parallelism if you can identify clean boundaries.
-
Quality non-uniformity is exploitable: If your process produces outputs of variable quality over time (e.g., early draft vs final polish, initial search results vs deep retrieval), consider exposing partial results to downstream consumers. They can make progress on high-quality parts while you refine the rest.
-
Step detection as a primitive: Reasoning step boundaries are a useful abstraction. Beyond streaming, they enable partial caching (reuse steps 1-5 if step 6 changes), selective refinement (re-generate only low-confidence steps), and interpretability (inspect step-level contributions). A robust step boundary detector could be a general-purpose tool.
-
Closed-form analysis pays dividends: In a field dominated by empirical ablations, deriving exact latency formulas lets you predict behavior on unseen configurations (e.g., “adding one more agent costs 1/r latency, so is it worth the quality gain?”). Invest in tractable models of your system.
论文: 2606.05158 作者: Zhen Yang, Xiaogang Xu, Wen Wang, Cong Chen, Xander Xu, Ying-Cong Chen 分类: cs.CL, cs.AI, cs.MA
缺口
像多 LLM 链式思考这样的多智能体推理系统采用了串行的”生成后传递”范式:智能体 1 完成完整推理链,然后智能体 2 才开始处理完整输出,依次进行。
这造成两个问题。
第一,延迟随流水线深度线性增长——每个智能体都是阻塞环节。
第二,当智能体 1 产生长推理链时,错误向尾部累积,但智能体 2 必须消费整条链,包括不可靠的尾部。
先前工作聚焦于扩展智能体数量或提升单个推理质量,但忽略了流水线结构本身。
没人问过:如果智能体能在上游依赖完成之前就开始工作呢?
问题:串行多智能体流水线
    |
    v
观察:早期推理步骤质量 > 后期步骤
    |
    v
假设:流式传输部分结果 = 流水线化 + 过滤坏步骤
    |
    v
方法:StreamMA(生成即流式传输每一步)
    |
    v
证据:延迟 -47%,8 个基准测试准确率 +7.3pp
    |
    v
结论:流水线化既更快又更准
增量
一句话:这篇论文之前,多智能体系统阻塞于完整推理链;之后,智能体通过消费流式传输的部分链实现流水线化,同时获得速度和准确率提升。
核心机制
StreamMA 用逐步流式传输替代端到端生成。
当智能体 1 生成推理步骤 1 时,立即转发该步骤给智能体 2,同时继续生成步骤 2。
智能体 2 在智能体 1 完成完整链之前就开始处理步骤 1。
这递归延续:智能体 2 的首个输出步骤流式传输给智能体 3,依此类推。
系统有三个关键组件。
步骤检测器识别 token 流中的推理步骤边界(例如识别”步骤 1:”、“因此”或编号项)。
前向缓冲区保存已完成步骤并触发下游传输。
消费调度器决定下游智能体何时启动——收到第一步立即启动(急切模式)或累积几步后启动(缓冲模式)。
数据流动如下:智能体 1 生成 token → 步骤检测器识别边界 → 前向缓冲区释放步骤 k → 智能体 2 接收步骤 k 并开始处理 → 智能体 2 的步骤检测器识别自己的边界 → 前向缓冲区释放给智能体 3。
每个智能体维护自己的生成线程和消费线程,解耦上游延迟和下游进度。
核喻:想象一个有多个工位(备菜、烧烤、摆盘)的餐厅厨房。
传统多智能体系统像等备菜工位切完所有蔬菜后烧烤工位才能开始烹饪。
StreamMA 像 mise en place 流水线化:备菜工位一切完第一个食材,就把砧板推给烧烤工位,烧烤工位立即开始烹饪,同时备菜继续切下一个食材。
摆盘工位不等所有烹饪完成——它在其他食材还在烤架上时就开始摆盘第一个熟品。
每个工位并行工作,更快的周转意味着食客更早得到服务。
意外之处:这还提升了质量,因为如果备菜工位后期变得马虎(比如大蒜切得不均匀),这些坏食材晚到达,可以被下游工位发现或调整,而不是混入单批次毁掉整道菜。
关键概念
- 步骤级粒度:传统系统在任务级粒度运作——智能体 1 输出完整解决方案,智能体 2 整体消费。
StreamMA 在步骤级粒度运作——智能体 1 输出”步骤 1:定义变量”,智能体 2 就用这个开始工作。
这就像运输成品和运输组件(组件一下生产线就发货)的区别。
更细粒度支持并行但需要识别清晰边界。
论文使用启发式规则(编号步骤、逻辑连接词),可选训练边界检测器。
- 推理链中的质量非均匀性:推理链中并非所有步骤都同样可靠。
经验上,早期步骤(问题设定、变量定义、初始约束)准确率更高,因为它们受问题陈述约束更强。
后期步骤(代数操作、边界情况处理)累积早期错误,并通过复杂操作引入新错误。
StreamMA 利用这一点,让下游智能体在完整链完成前就用可靠的早期步骤工作。
如果智能体 1 的步骤 5 有错,智能体 2 已经正确处理了步骤 1-4,而在串行模式下,智能体 2 会等待然后消费整条易错链。
- 闭式延迟分析:论文推导了不同协议下端到端延迟的精确公式。
对于 n 个智能体的链,每个生成 k 步,速率 r token/秒,串行延迟是 n × k/r(智能体顺序运行)。
StreamMA 延迟是 k/r + (n-1) × 1/r(第一个智能体生成全部 k 步,然后每个后续智能体只增加 1 步延迟,因为它们早启动)。
随着 k 增长,加速比接近 n——增加推理步骤增加流水线化的收益。
这是 LLM 系统研究中罕见的闭式结果,使权衡透明。
框架转变
之前(串行生成后传递):

智能体 1:[========== 生成全部 10 步 ==========]
                                                |
智能体 2:                                       [===== 生成 5 步 =====]
                                                                      |
智能体 3:                                                             [=== 生成 3 步 ===]

时间线:|-------- A1 --------|----- A2 -----|-- A3 --|
延迟:  t1 = 10/r            t2 = 5/r       t3 = 3/r
总计:  18/r


之后(StreamMA 流式传输):

智能体 1:[步骤1][步骤2][步骤3][步骤4]...[步骤10]
           |      |      |      |          |
智能体 2:  [S1   ][S2   ][S3   ][S4   ][S5   ]
             |      |      |      |      |
智能体 3:    [S1  ][S2  ][S3  ]

时间线:|-- A1 启动 --|
        |  A2 启动(1 步延迟后)
        |    A3 启动(从 A2 起 1 步延迟后)
延迟:  10/r + 1/r + 1/r = 12/r

加速比:18/12 = 1.5x
从阻塞顺序执行到重叠流水线执行,核心转变是将推理视为增量单元流,而非单体输出。
专家评审
选题眼光:真缺口。
多智能体系统日益流行(ReAct、AutoGPT、MetaGPT),延迟是生产部署的一阶关注点。
流式传输能同时改善速度和准确率的观察非显而易见——大多数流式工作是用质量换延迟。
步骤质量假设有经验基础(他们测量了步骤级准确率衰减)而非假定。
方法成熟度:简洁优雅。
核心思想——流式传输部分结果——对现有多智能体框架改动极小。
步骤检测器基于启发式(编号步骤的正则表达式),感觉脆弱但在多种推理格式上有效。
学习的边界检测器会更鲁棒但增加复杂度。
闭式分析是主要优势,在经验性 LLM 论文中罕见。
一个被忽视的角度:错误传播呢?
如果智能体 1 的步骤 3 错了,智能体 2 立即基于它构建,可能放大错误。
论文显示净改善但未分解何时流式有帮助何时有害。
实验诚意:基线公平——串行多智能体和扩展推理的单智能体。
八个基准测试涵盖数学(MATH、AIME)、科学(GPQA)和代码(HumanEval),提供广度。
两个前沿模型(Claude Opus 4.6、GPT-5.4)和三种拓扑(链、树、图)测试泛化。
数字很大:HMMT 2026 上 +22.4pp 很惊人。
一个值得警惕之处:所有实验使用相同的步骤检测器启发式规则。
学习的检测器会改变排名吗?
成本分析(API token)诚实——StreamMA 因重叠生成使用更多 token,但加速证明了合理性。
写作功力:引言和核心机制简洁。
闭式分析章节密集——关键直觉埋在引理里。
重写第 3-4 节,在数学之前先引出几何直觉(流水线化节省 n-1 个智能体延迟)会有帮助。
摘要中的”步骤级缩放律”主张支持不足——一张图显示趋势但未确立为定律。
相关工作混淆了流式生成(已有)和流式智能体间通信(新颖)。
判决:强接收 — 用简单的、理论有据的方法解决真实问题,实验证据全面。
要点总结
- 粒度作为设计杠杆:构建流水线(LLM 或其他)时,问问粗粒度阻塞(等待完整输出)是必需还是习惯。
更细粒度能支持并行,如果你能识别清晰边界。
- 质量非均匀性可被利用:如果你的过程随时间产生可变质量输出(例如早期草稿 vs 最终润色,初始搜索结果 vs 深度检索),考虑向下游消费者暴露部分结果。
他们可以在高质量部分上取得进展,同时你完善其余部分。
- 步骤检测作为原语:推理步骤边界是有用抽象。
超越流式传输,它们支持部分缓存(步骤 6 变化时复用步骤 1-5)、选择性精化(仅重新生成低置信度步骤)和可解释性(检查步骤级贡献)。
鲁棒的步骤边界检测器可能是通用工具。
- 闭式分析回报丰厚:在一个由经验消融主导的领域,推导精确延迟公式让你预测未见配置的行为(例如”增加一个智能体代价 1/r 延迟,所以质量提升值得吗?”
)。
投资于系统的可解模型。