Paper: 2608.07454 Authors: Daniel Armstrong, Xuan-Vu Nguyen, Octavian Susanu, Gabriel Gibberd, Théo A. Neukomm, Taddäus Strunden, Dan Forster, Morgane Delattre, Shawn Teh, Clément Rols Categories: cs.MA, cs.AI
The Gap
Computer-aided synthesis planning has been dominated for a decade by one architecture: a single-step retrosynthesis model (template-based like Synthia/Chematica and AiZynthFinder’s expansion policies, or template-free seq2seq/graph-edit models) wrapped in a tree search (MCTS, Retro*, A*-style best-first). You give it a target, it proposes one-step disconnections, recurses, and stops when every leaf is a purchasable compound. The reported numbers are excellent — solve rates in the high 90s on USPTO-190, Retro*-190, PaRoutes.
The problem is where those benchmarks come from. They are carved out of the same reaction databases (USPTO, Reaxys) that trained the models. So the evaluation asks: can you rediscover chemistry you were fitted to? Near-complete success on that question tells you almost nothing about the frontier. Complex natural products — densely functionalized, polycyclic, stereochemically loaded — are precisely the targets whose enabling steps are rare, bespoke, sometimes invented for that one molecule. Template libraries contain that chemistry least.
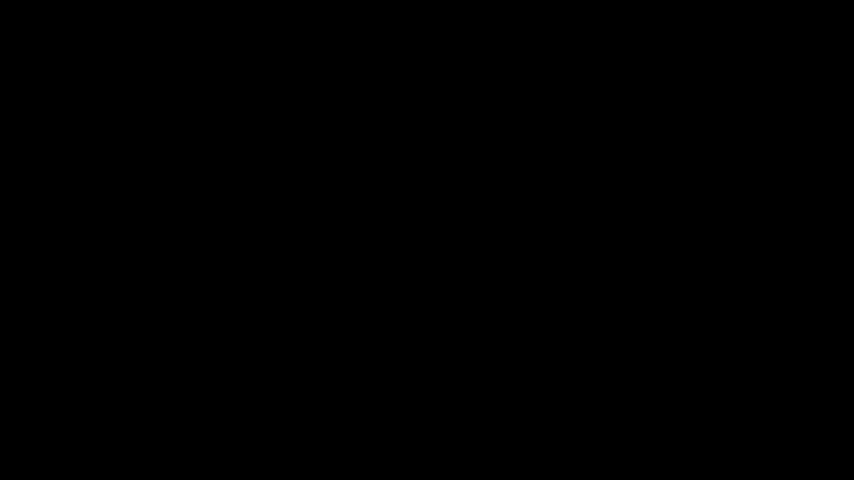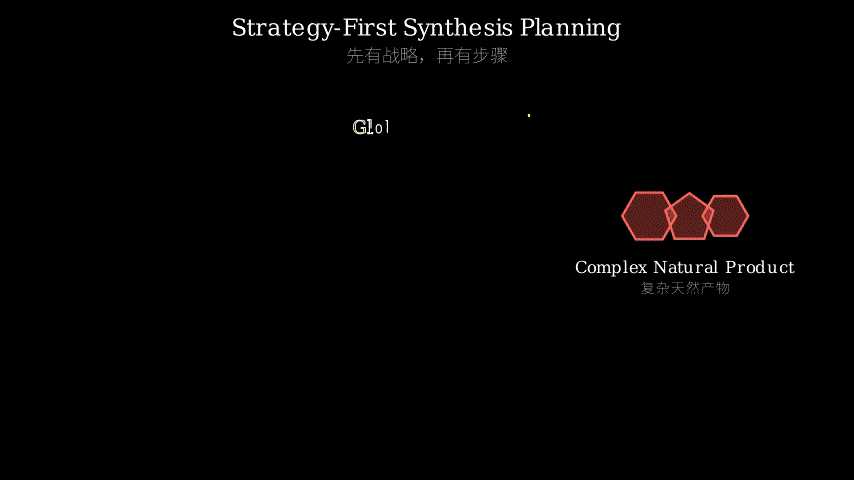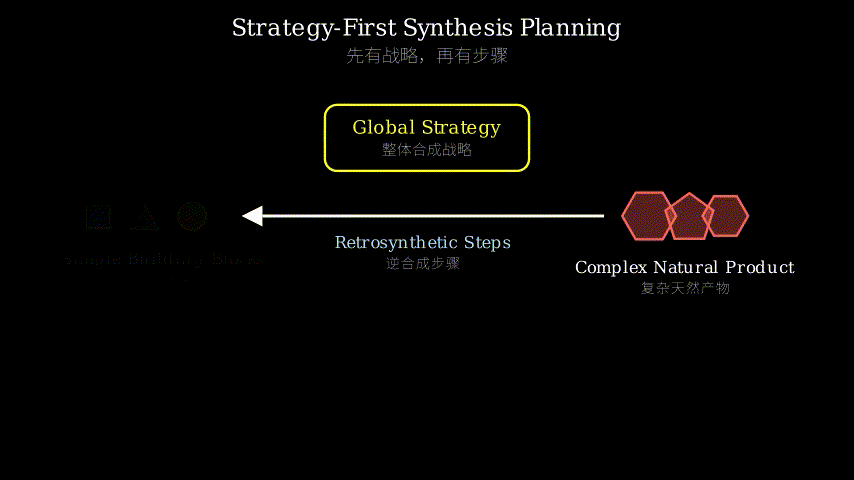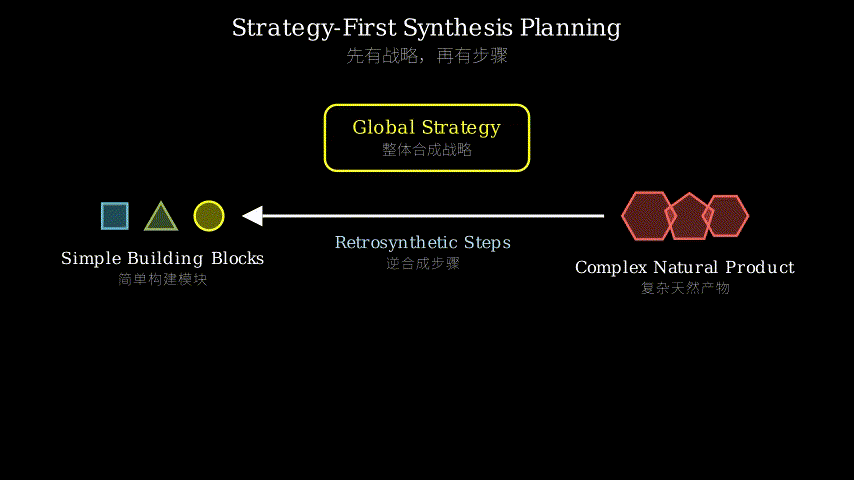
There is a second, subtler failure: these systems plan in the wrong unit. They reason one bond at a time, greedily, with no representation of strategy — no notion that this whole route hinges on a single transannular Diels-Alder, that a protecting group choice three steps back exists only to enable it, or that you want a fallback if the key step fails. Human chemists plan top-down: pick a strategic skeleton-forming disconnection first, then figure out how to get there. Nobody had shown a machine doing that convincingly.
PROBLEM
[ NP total synthesis needs inventive chemistry ]
[ template search covers only catalogued chemistry ]
                |
                v
DIAGNOSIS
[ benchmarks drawn from training corpus  ==>  circular evaluation ]
[ planning unit == single bond           ==>  no strategy layer   ]
                |
                v
ASSUMPTION
[ LLMs carry tacit strategic chemistry from text        ]
[ strategy is a better planning unit than the step      ]
                |
                v
METHOD
[ SynthEx : propose competing strategies > place key steps
             > fill routine steps > self-critique > revise ]
                |
                v
EVIDENCE
[ more convergent routes ] + [ wider reaction space ]
[ blinded experts: key steps ~ published human syntheses ]
[ SynthAtlas : 1000+ NP routes released ]
                |
                v
CONCLUSION
[ strategy-first agentic planning reaches targets
  that catalogue-based search cannot ]
The Increment
One sentence: Before, automated retrosynthesis produced route trees that experts skimmed and dismissed; after, an LLM agent produces plans whose *key steps experts mistake for and argue with as human work — and a thousand of them are now public for targets with no literature route.
Core Mechanism
SynthEx is an agentic loop, not a single model. The first stage is divergent: given a target structure, it proposes several competing strategies — high-level accounts of how the skeleton gets built, each committing to a different strategic disconnection and a different set of building blocks. This is the part existing tools have no vocabulary for. A tree search implicitly chooses a strategy by whichever branch scores best at depth one; SynthEx makes the strategy an explicit, nameable, comparable object before any step is committed.
The second stage is stratified execution. Within a chosen strategy, steps are split into key steps (the skeleton-forming, stereochemistry-setting, hard-to-find transformations that the route lives or dies by) and routine steps (functional group interconversions, protections, oxidation-state adjustments — chemistry that is well precedented and cheap to reason about). Reasoning effort is allocated asymmetrically: key steps get deep, targeted deliberation; routine steps get filled in as connective tissue. The route assembler then has to make these cohere — the routine steps must actually deliver the substrate the key step needs, with the right protecting groups and the right oxidation states.
The third stage is critique. The system reads back its own route and attacks it: chemoselectivity conflicts, stereochemical ambiguity, functional group incompatibility, missing protecting groups, implausible yields. Then it revises. This closes the loop that pure search architectures lack — search can only re-score branches, it cannot notice that a route is internally incoherent as a narrative.
                     [ TARGET STRUCTURE ]
                              |
              +---------------+---------------+
              |               |               |
        STRATEGY A      STRATEGY B      STRATEGY C
      (disconnect X)  (disconnect Y)  (disconnect Z)
              |               |               |
              +-------> [ COMPARE / SELECT ] <+
                              |
                              v
              [ DECOMPOSE INTO STEP TYPES ]
                     /                \
            KEY STEPS               ROUTINE STEPS
      (skeleton + stereo)      (FGI / protect / redox)
        deep reasoning            cheap precedent
                     \                /
                      v              v
                [ ROUTE ASSEMBLER ]
             checks substrate handoff
             checks PG + oxidation logic
                        |
                        v
                  [ CRITIC ]
        chemoselectivity . stereo . compatibility
                        |
              fails ----+---- passes
                |               |
                v               v
          [ REVISE ] ----> [ ROUTE + BACKUPS ]
             ^  |                   |
             +--+                   v
                              [ SynthAtlas ]
Think of it as a screenwriters’ room building a heist movie, and the mapping is tight. The target molecule is the vault. The competing strategies are competing loglines pitched in the room: go through the roof, bribe the guard, swap the truck — each a different theory of how the whole film works, argued *before anyone writes dialogue. The key steps are the set pieces: the two or three scenes the audience came for, the ones the director will spend half the budget on. The routine steps are the connective tissue — the car ride, the briefing, the walk down a corridor — necessary, but nobody agonizes over them, and they exist only to deliver the characters to the set piece in the right emotional and physical state. That handoff is the route assembler’s job: if your hero needs a keycard in the vault scene, an earlier scene has to have given it to him (that is what a protecting group is). The critic is the table read, where someone says “wait, he’s handcuffed in scene 4, how is he climbing in scene 6” — a continuity error, which is exactly what chemoselectivity and oxidation-state mismatches are. And the blinded expert panel is the test screening: not “did the plot obey the rules of screenwriting” but “did people sit forward and argue about it.”
A template-based tree search, in this metaphor, is a writer who only ever asks “what is the most common next scene given this scene?” — one shot at a time, from a corpus of produced films. It can assemble something shootable. It cannot pitch a heist.
Key Concepts
-
Benchmark circularity: Imagine grading a student by giving them back the exact textbook exercises they studied, then reporting 97% and calling them a mathematician. Retrosynthesis benchmarks are extracted from USPTO/Reaxys; the models were trained on USPTO/Reaxys. Any route the literature already contains is, by construction, reachable by recombining catalogued templates. So high solve rates measure *coverage of the record, not synthetic ability. The tell is that performance collapses on natural products, where the record is thinnest — and that is exactly where a chemist would say the interesting problems live. This paper’s response is to change the measurement instrument (blinded human experts, novel targets without literature routes), not just the model.
-
Key steps vs routine steps: In a 20-step total synthesis, maybe three steps decide whether the route works. Those are the ones that build the ring system, set the difficult quaternary stereocenter, or stitch two large fragments together. The other seventeen are bookkeeping: swap an alcohol for a bromide, protect a ketone, oxidize a primary alcohol to an aldehyde. Any competent chemist can do the seventeen; the three are where creativity and risk live. Existing planners treat all twenty as the same kind of object and spend the same search effort on each. SynthEx separates them and spends unequal effort — which is both a compute-allocation trick and a better model of how the problem is actually shaped.
-
Convergent vs linear routes: A linear route is a relay race — you carry one growing molecule through every step, so a failure at step 18 costs you everything upstream, and total yield is a product of twenty numbers. A convergent route builds two or three fragments in parallel and joins them late, like assembling a car from a chassis and a body made on separate lines. Convergence is a hallmark of good human route design: shorter longest-linear-sequence, better yield economics, easier troubleshooting. The paper reports SynthEx’s chemistry is *more convergent than existing tools produce — a meaningful signal, because fragment coupling requires reasoning about two subgoals at once, which single-step greedy expansion structurally discourages.
Framework Shift
Before (mainstream CASP):            After (SynthEx):

     [ target ]                          [ target ]
         |                                   |
   one-step model                  +---------+---------+
   proposes edits                  |         |         |
    /    |    \                  strat A   strat B   strat C
   v     v     v                    |
  p1    p2    p3                    v  (explicit compare)
   |     |     |               [ chosen strategy ]
  ...   ...   ...                    |
   |                        +--------+--------+
   v                        |                 |
 [ buyable leaves ]     key steps        routine steps
                        (deep think)     (cheap fill)
   scored by                    \           /
   template priors               v         v
   + reachability            [ assemble + check handoff ]
                                      |
                                      v
                                 [ critic ]
                                      |
                              revise <+> emit route
                                          + backups

  unit of planning: A BOND       unit of planning: A STRATEGY
  evaluated vs: THE CORPUS       evaluated vs: HUMAN CHEMISTS
  failure mode: no route         failure mode: plausible-looking
                found            but wrong chemistry
From bottom-up recombination of catalogued reactions to top-down commitment to a strategy that is then filled in and criticized, the core shift is moving the planning unit up one level of abstraction, from the step to the plan — which also moves the failure mode from “cannot find anything” to “found something that reads well,” and that is why the evaluation had to change too.
Expert Assessment
Caveat up front: I am working from the abstract and framing, not the full methods and SI. Treat the numbers-level judgments below as priors about this class of paper, not verified readings of their tables.
Problem choice: Real gap, and a well-chosen one. The circularity critique of retrosynthesis benchmarks has been muttered at conferences for years — everyone knows 97% on USPTO-190 does not mean the problem is solved — but few groups were willing to give up the leaderboard and go argue with chemists instead. Natural products are the right stress test: they are where the record is thin, where strategy dominates, and where a human expert can still tell the difference in thirty seconds. Sitting this in the trajectory of the field: this is the paper that says the last decade optimized the wrong objective.
Method maturity: The insight is architectural and genuinely good — plan in the space of strategies, stratify effort between key and routine steps, close a critique loop. That is a real modeling decision about the shape of the problem, not a prompt trick. But the implementation is orchestration: LLM calls, roles, a critic, retries. There is little here that could not be rebuilt by a competent team in a few months, and the paper’s performance is likely bounded by the underlying model’s chemistry knowledge more than by the scaffold. Two things I would want to see and suspect are thin: an ablation isolating how much of the gain comes from the strategy-first stage versus simply having a strong base model with a critic, and whether a cheaper baseline — an LLM proposing strategic disconnections that then *seed a conventional template search — recovers most of the benefit. That hybrid is the obvious simpler alternative and it deserves to be the headline baseline.
Experimental integrity: The blinded expert assessment is the right instrument and the strongest part of the contribution. It is also the softest evidence in the paper, and both things are true at once. “Judged comparable to published human syntheses” depends entirely on panel size, chemist seniority, target selection, and how the comparison was framed; those details decide whether this is a finding or an anecdote. The phrase “engaged with them as genuine synthesis plans” is doing rhetorical work — engagement is a real and interesting signal, but it is not feasibility. The reaction-space coverage claim needs the most scrutiny: an LLM will happily propose transformations outside the template corpus, and “outside the corpus” is indistinguishable from “wrong” without expert or experimental adjudication. Novelty metrics reward exactly the behavior that hallucination produces. And the elephant: zero wet-lab validation. Nobody ran a step. Until someone executes even one SynthEx key step at the bench, the ceiling on what this paper can claim is “expert-plausible,” not “correct.” Releasing SynthAtlas is the honest move here — it hands the community the material to falsify the claim.
Writing quality: The abstract is polished to a Nature-style shine, and that is itself a warning sign — “a response algorithmic route prediction has not previously accomplished” is a sentence optimized for a press release, not a claim you can check. The corner-cutting is almost certainly in the evaluation protocol: I would bet the blinding procedure, panel composition, target sampling, and scoring rubric are compressed into a paragraph and a supplementary table when they carry the entire load of the central claim. Rewrite that section as the paper’s spine — with per-target expert scores, inter-rater agreement, and the raw comparison prompts — and this goes from persuasive to hard to dismiss. Second suggestion: report the failure cases in the main text. A paper claiming expert-level plans that does not show its worst outputs is asking for trust it has not earned.
Verdict: weak accept — the reframing (strategy as the planning unit, human experts as the measuring instrument) is correct and overdue, and the released atlas is a genuine community asset; but the evidence is expert opinion on an unstated sample with no bench validation, and the ablation that would show the strategy-first stage is load-bearing appears to be missing.
Takeaways
Concrete things worth stealing:
- Diagnose your benchmark’s provenance before believing your score. If the eval set and the training corpus come from the same generative process, a high number measures memorization coverage. The generalizable move: identify the sub-population where the corpus is thinnest (here, natural products) and make that your test set. This applies to code generation, theorem proving, and every “we get 95% on X” claim.
- Choose your planning unit deliberately. Most agent frameworks plan at the granularity of the primitive action because that is what the environment exposes. This paper’s win is refusing that default: propose several complete *strategies, compare them explicitly, then commit. Transfers directly to code agents (propose competing architectures before writing functions), to research agents (propose competing experimental designs before running one), to any long-horizon task where early commitments dominate the outcome.
- Stratify reasoning effort by step criticality. Split your plan into the few steps that decide success and the many that are bookkeeping. Spend deep inference on the former, cheap templates on the latter. This is a better compute-allocation policy than uniform search depth, and it requires only that you can classify steps — which is often easy even when solving them is hard.
- Make the critic check narrative coherence, not just local validity. Their critic looks for cross-step incompatibilities: does step 12 actually deliver what step 13 needs. Most self-critique loops in agent systems validate each step in isolation. The interesting bugs live in the handoffs.
- When your outputs exceed your benchmark, change the instrument. Blinded expert comparison against human artifacts, with “did they engage with it seriously” as an outcome measure, is a reusable evaluation design for any generative system that has outgrown automated metrics. Just budget for the rigor — panel size, blinding, inter-rater agreement — or it becomes the weakest link, as it arguably is here.
- Ship the artifacts. Releasing a thousand routes for targets with no literature route converts an unfalsifiable claim into a standing invitation to falsify it. That is the strongest credibility move available to a paper whose main evidence is subjective.
论文: 2608.07454 作者: Daniel Armstrong, Xuan-Vu Nguyen, Octavian Susanu, Gabriel Gibberd, Théo A. Neukomm, Taddäus Strunden, Dan Forster, Morgane Delattre, Shawn Teh, Clément Rols 分类: cs.MA, cs.AI
缺口
计算机辅助合成设计(CASP)过去十年基本被一种架构垄断:单步逆合成模型(模板类的如 Synthia/Chematica、AiZynthFinder 的扩展策略,或无模板的 seq2seq、图编辑模型)外面套一层树搜索(MCTS、Retro*、最佳优先)。 给它一个目标分子,它提出一步拆键,递归下去,直到所有叶子都是可购买的原料。 报出来的数字非常漂亮——USPTO-190、Retro*-190、PaRoutes 上的求解率普遍在 90% 以上。
问题在于这些基准从哪来。 它们是从训练模型用的同一批反应数据库(USPTO、Reaxys)里切出来的。 所以评测实际在问:你能不能重新发现你被拟合过的化学? 在这个问题上接近满分,对真正的前沿几乎不提供信息。 复杂天然产物——高度官能化、多环、立体化学密集——恰恰是那类关键步骤稀有、定制、有时是为这一个分子专门发明出来的靶标。 而模板库里最缺的就是这种化学。
还有一层更隐蔽的失败:这些系统的规划单元错了。 它们一次只推理一根键,贪心地推,内部没有任何”战略”的表示——它不理解整条路线是押在某一步跨环 Diels-Alder 上的,不理解三步之前那个保护基的存在只是为了让这一步成立,也不会准备关键步失败时的备选方案。 人类化学家是自上而下规划的:先选一个战略性的骨架构建拆分,再倒推怎么走到那里。 此前没有人证明机器能令人信服地做到这件事。
问题
[ 天然产物全合成需要"发明性"化学 ]
[ 模板搜索只覆盖已编目的化学     ]
                |
                v
诊断
[ 基准取自训练语料   ==>  循环论证式评测 ]
[ 规划单元 == 单根键 ==>  缺少战略层     ]
                |
                v
假设
[ LLM 从文本中带有隐性的战略化学直觉 ]
[ "战略"比"步骤"是更好的规划单元     ]
                |
                v
方法
[ SynthEx : 提出竞争性战略 > 布置关键步
             > 填充常规步 > 自我批判 > 修订 ]
                |
                v
证据
[ 路线更"汇聚" ] + [ 反应空间更广 ]
[ 盲评专家: 关键步 ~ 已发表人类合成 ]
[ SynthAtlas : 公开 1000+ 条天然产物路线 ]
                |
                v
结论
[ 战略优先的智能体规划能触及
  编目式搜索到不了的靶标 ]
增量
一句话: 以前自动逆合成产出的是专家扫两眼就丢掉的路线树;现在一个 LLM 智能体产出的方案,其关键步能让专家误认为是人写的、并且愿意认真跟它争论——而且一千条这样的路线已经对文献无路线的靶标公开了。
核心机制
SynthEx 是一个智能体循环,不是单个模型。 第一阶段是发散的:给定目标结构,它提出若干条互相竞争的战略——关于骨架如何被搭起来的高层叙述,每条战略承诺一个不同的战略拆分点和一套不同的起始砖块。 这正是现有工具连词汇都没有的部分。 树搜索是”隐式”选战略的:哪个深度一的分支打分高就走哪条;SynthEx 把战略变成在任何步骤落地之前就可命名、可比较的显式对象。
第二阶段是分层执行。 在选定的战略内部,步骤被分成关键步(构建骨架、设定难做的立体中心、把大片段缝在一起的那几步,路线的生死全在这里)和常规步(官能团互换、上下保护基、氧化态调整——先例充足、推理成本低的化学)。 推理算力是不对称分配的:关键步得到深度、定向的思考;常规步作为连接组织填进去。 接着路线组装器必须让二者自洽——常规步真的要交付关键步所需要的底物,带对的保护基、对的氧化态。
第三阶段是批判。 系统回读自己的路线并进攻它:化学选择性冲突、立体化学歧义、官能团不兼容、缺失的保护基、不现实的收率。 然后修订。 这补上了纯搜索架构缺的那个闭环——搜索只能给分支重新打分,它无法察觉一条路线作为叙事在内部是不连贯的。
                     [ 目标结构 ]
                          |
              +-----------+-----------+
              |           |           |
           战略 A       战略 B      战略 C
         (拆 X 键)     (拆 Y 键)   (拆 Z 键)
              |           |           |
              +---> [ 显式比较 / 选择 ] <---+
                          |
                          v
                 [ 按步骤类型分解 ]
                    /            \
               关键步            常规步
        (骨架 + 立体化学)   (FGI / 保护 / 氧化态)
           深度推理             廉价先例
                    \            /
                     v          v
              [ 路线组装器 ]
           校验底物交接是否成立
           校验保护基 + 氧化态逻辑
                      |
                      v
                 [ 批判器 ]
       化学选择性 . 立体化学 . 兼容性
                      |
            不通过 ----+---- 通过
              |                |
              v                v
        [ 修订 ] ------> [ 路线 + 备选方案 ]
           ^  |                   |
           +--+                   v
                            [ SynthAtlas ]
换个说法,用登山探险队规划一条首登路线来理解,映射是一对一的。 目标分子是峰顶。 互相竞争的战略就是队里争论的几条路线方案:走南壁冰槽、走东北山脊、绕冰川再从背面上——每条都是关于”整座山怎么爬”的不同理论,在任何人打第一颗岩钉之前就要吵完。 关键步是那两三段”技术难点”:五级冰壁、横切一段刀刃脊,全队装备和体力预算都是为它准备的。 常规步是接近段:走冰川、建大营、搬物资——必需,但没人为它纠结,它存在的唯一意义是把队员以正确的状态送到难点脚下。 这个”交接”就是路线组装器的活:如果难点需要 8 颗冰锥,之前某一段必须把它们背上去(这就是保护基的作用)。 批判器是出发前的图上作业复盘,有人指出”第四天你们把绳子留在二号营了,第六天拿什么下降”——这是连续性错误,而化学选择性冲突和氧化态错配正是这一类错误。 而盲评专家组是老队员的评审:他们判断的不是”这份计划格式对不对”,而是”我看完会不会真的想跟你争这条线能不能走”。
在这个比喻里,模板式树搜索是那种只会问”从这一段地形出发,别人最常走的下一段是什么”的规划者——一段一段地照抄已完成的登山报告。 它能拼出一条能走的常规路线。 它提不出一条首登方案。
关键概念
-
基准的循环论证: 想象你把学生做过的课后习题原封不动当考卷,然后报出 97% 并宣布他是数学家。 逆合成基准是从 USPTO/Reaxys 抽出来的,而模型正是在 USPTO/Reaxys 上训练的。 任何文献里已经存在的路线,按构造就一定能靠重组已编目模板走通。 所以高求解率度量的是”对记录的覆盖度”,不是合成能力。 破绽在于:一旦换成天然产物——记录最薄的地方——性能就崩,而那恰恰是化学家眼里真问题所在的地方。 这篇论文的回应是换测量仪器(盲评专家、无文献路线的新靶标),而不只是换模型。
-
关键步 vs 常规步: 一条 20 步的全合成里,大概只有三步决定这条路线成不成。 就是搭出环系、建立那个难搞的季碳立体中心、或者把两个大片段接起来的那几步。 其余十七步是记账:把醇换成溴、把酮保护起来、把伯醇氧化成醛。 任何合格的化学家都能做那十七步;创造性和风险全在那三步里。 现有规划器把二十步当成同一种东西,给每步花同样的搜索预算。 SynthEx 把它们分开并且不平均分配算力——这既是一个算力分配技巧,也是对问题真实形状更准确的建模。
-
汇聚式 vs 线性路线: 线性路线像接力跑——你把同一个不断长大的分子扛过每一步,所以第 18 步炸了,上游全部作废,总收率是二十个数字的连乘。 汇聚式路线并行造两三个片段,晚期再拼起来,像底盘和车身在两条产线上做好再合装。 汇聚性是优秀人类路线设计的标志:最长线性序列更短、收率经济性更好、排查故障更容易。 论文报告 SynthEx 偏好的化学比现有工具更汇聚——这是个有意义的信号,因为片段偶联需要同时对两个子目标推理,而单步贪心扩展在结构上就不鼓励这件事。
框架转变
之前(主流 CASP):                  之后(SynthEx):

     [ 目标 ]                            [ 目标 ]
        |                                   |
   单步模型提出                   +---------+---------+
   候选拆分                       |         |         |
    /    |    \                 战略A     战略B     战略C
   v     v     v                   |
  p1    p2    p3                   v  (显式比较)
   |     |     |              [ 选定战略 ]
  ...   ...   ...                  |
   |                      +--------+--------+
   v                      |                 |
 [ 可购买叶子 ]         关键步            常规步
                      (深度推理)        (廉价填充)
  打分依据:                  \             /
  模板先验                    v           v
  + 可达性              [ 组装 + 校验交接 ]
                                |
                                v
                            [ 批判器 ]
                                |
                        修订 <--+--> 输出路线
                                        + 备选

  规划单元: 一根键               规划单元: 一条战略
  对标对象: 语料库               对标对象: 人类化学家
  失效模式: 找不到路线           失效模式: 看着像样
                                 但化学是错的
一句话:从”自下而上重组已编目反应”到”自上而下先承诺一条战略再填充和自我批判”,核心转变是把规划单元往上抬了一个抽象层级——从步骤抬到方案;顺带也把失效模式从”什么都找不到”变成了”找到一个读起来很顺的东西”,这就是为什么评测方式也必须一起换。
专家评审
先说清楚:我看的是摘要和整体框架,不是完整方法与补充材料。 下面涉及数字层面的判断,请当作对这一类论文的先验,而不是对他们表格的核对结果。
选题眼光: 真缺口,而且选得准。 逆合成基准的循环论证问题在会场上被嘀咕了好几年——大家都知道 USPTO-190 上 97% 不等于问题解决了——但很少有组愿意放弃排行榜、转身去跟化学家吵架。 天然产物是正确的压力测试:记录最薄、战略主导、而且真专家三十秒内就能分辨真假。 放到领域轨迹上看:这是那篇说”过去十年优化错了目标函数”的论文。
方法成熟度: 洞见是架构层面的,而且确实好——在战略空间里规划、按关键性分层分配推理、闭上批判回路。 这是关于问题形状的真实建模决策,不是提示词技巧。 但实现层面就是编排:LLM 调用、角色、批判器、重试。 里面没什么是一支像样的团队几个月做不出来的,而且它的表现天花板恐怕更多由底座模型的化学知识决定,而不是由这个脚手架决定。 两件我想看、且怀疑很薄的东西:一是消融实验,把”战略优先阶段”的贡献和”强底座模型 + 批判器”的贡献分开;二是更便宜的基线——让 LLM 只提出战略性拆分点,然后用它去播种传统模板搜索——能不能拿回大部分收益。 这个混合方案是最显然的更简单替代品,它应该当头号基线摆出来。
实验诚意: 盲评专家评估是对的仪器,也是全文最强的贡献。 同时它也是全文最软的证据,这两点同时成立。 “被判断为与已发表人类合成相当”完全取决于评审组规模、化学家资历、靶标选取、以及比较是怎么被框定的;这些细节决定它是一个发现还是一则轶事。 “engaged with them as genuine synthesis plans(把它当真正的合成方案来对待)“这句在做修辞工作——“愿意认真对待”是真实且有趣的信号,但它不是可行性。 反应空间覆盖度那个论断最需要审视:LLM 会非常乐意提出模板语料之外的转化,而在没有专家或实验裁决的情况下,“语料之外”和”错”是无法区分的。 新颖性指标奖励的,恰好就是幻觉会产生的行为。 还有那头大象:零湿实验验证。 没有人真的做过任何一步。 在有人把哪怕一个 SynthEx 关键步搬到台面上跑通之前,这篇论文能声称的上限是”专家看着可信”,不是”正确”。 公开 SynthAtlas 是这里最诚实的一手——它把足以推翻自己的材料交给了社区。
写作功力: 摘要被打磨得非常 Nature 味,而这本身就是个警报——“a response algorithmic route prediction has not previously accomplished”是一句为新闻稿优化的话,不是一个你能核查的断言。 偷懒的地方几乎肯定在评测协议:我打赌盲评流程、评审组构成、靶标抽样、评分量表被压缩进一段话加一张补充表,而它们承担着核心论断的全部重量。 把那一节重写成整篇论文的脊梁——给出逐靶标专家评分、评分者间一致性、以及原始的比较提示——这篇论文就会从”有说服力”变成”很难反驳”。 第二个建议:把失败案例写进正文。 一篇声称达到专家水准的论文却不展示自己最差的输出,是在索取它还没赚到的信任。
判决: 弱接收 —— 这个重构(把战略当规划单元、把人类专家当测量仪器)是正确且早该做的,公开的路线库是真正的社区资产;但证据是一个未说明样本上的专家意见,没有台面验证,而能证明”战略优先”这一步是承重结构的消融实验看起来是缺的。
要点总结
值得”偷”走的具体东西:
-
在相信自己的分数之前,先查基准的出身。 如果评测集和训练语料来自同一个生成过程,高分度量的是记忆覆盖度。 可迁移的动作:找出语料最薄的那个子群体(这里是天然产物),把它作为你的测试集。 这对代码生成、定理证明、以及每一个”我们在 X 上拿到 95%“的论断都适用。
-
有意识地选择规划单元。 多数智能体框架在原始动作的粒度上规划,因为环境暴露的就是那个粒度。 这篇论文的胜负手是拒绝这个默认值:先提出几条完整的战略,显式比较,再承诺。 可以直接迁移到代码智能体(写函数之前先提出几套竞争性架构)、研究智能体(跑实验之前先提出几套竞争性实验设计),以及任何早期承诺主导结果的长时程任务。
-
按步骤关键性分层分配推理算力。 把方案切成”决定成败的少数步”和”记账的多数步”,前者上深度推理,后者用廉价模板。 这比统一搜索深度是更好的算力分配策略,而它只要求你能分类步骤——即使解决它们很难,分类往往很容易。
-
让批判器检查叙事连贯性,而不只是局部合法性。 他们的批判器找的是跨步骤的不兼容:第 12 步是否真的交付了第 13 步需要的东西。 多数智能体系统的自我批判是孤立地校验每一步。 有意思的 bug 都住在交接处。
-
当输出超出基准能力时,换仪器。 以人类作品为对照的盲评比较,并把”他们是否愿意认真对待”当作结果指标,是任何已经长出自动指标的生成系统都能复用的评测设计。 但要为严谨性预留预算——评审组规模、盲化、评分者一致性——否则它就成了最弱一环,本文大概就是如此。
-
把产物公开出去。 为无文献路线的靶标发布一千条路线,把一个不可证伪的论断变成了一份公开的”欢迎来反驳”邀请。 对于主要证据是主观判断的论文来说,这是能拿到的最强的可信度动作。