Paper: 2603.16842 Authors: Jello Zhou, Vudtiwat Ngampruetikorn, David J. Schwab Categories: cs.LG, cond-mat.dis-nn, cond-mat.stat-mech, eess.SY, physics.bio-ph
The Gap
Stochastic resetting has a rich theory in statistical mechanics. The classic result: if you reset a random walker to its starting point at some rate r, you can dramatically reduce the mean first-passage time to a target. The optimal reset rate trades off “don’t interrupt a lucky run” against “don’t waste time on a lost cause.” This is well understood for static diffusive processes.
The problem is that reinforcement learning agents are not static diffusive processes. They learn. Their transition dynamics change as the policy updates. Every existing resetting theory assumes the underlying process is fixed — the math breaks down the moment the agent starts improving. So the question “does resetting help a learning agent, and if so, why?” had no answer.
The prior RL literature handles the related problem of long uninformative episodes mostly through temporal discounting (gamma<1), which biases the agent toward short-horizon rewards. That works, but it distorts the value function and can shift the optimal policy. Nobody had asked whether resetting — which doesn’t touch the reward structure — could do the same job more cleanly.
  Static diffusion theory          RL with adapting policy
  (resetting well understood)      (resetting = unknown territory)
         |                                   |
         v                                   v
  First-passage time               Policy convergence speed
  is the metric                    is the metric
         |                                   |
         +------- This paper bridges ---------+
                          |
                          v
         Assumption: resetting truncates long,
         low-value trajectories -> better credit assignment
                          |
                          v
         Method: tabular grid + deep RL experiments
         with controlled reset rates
                          |
                          v
         Evidence: faster convergence in tabular;
         improved sparse-reward deep RL
                          |
                          v
         Conclusion: resetting is a new optimization
         principle for learning, not just search
The Increment
One sentence: Before this paper, stochastic resetting was a tool for finding targets faster; after it, resetting is also a tool for learning policies faster — and the two mechanisms are provably distinct.
Core Mechanism
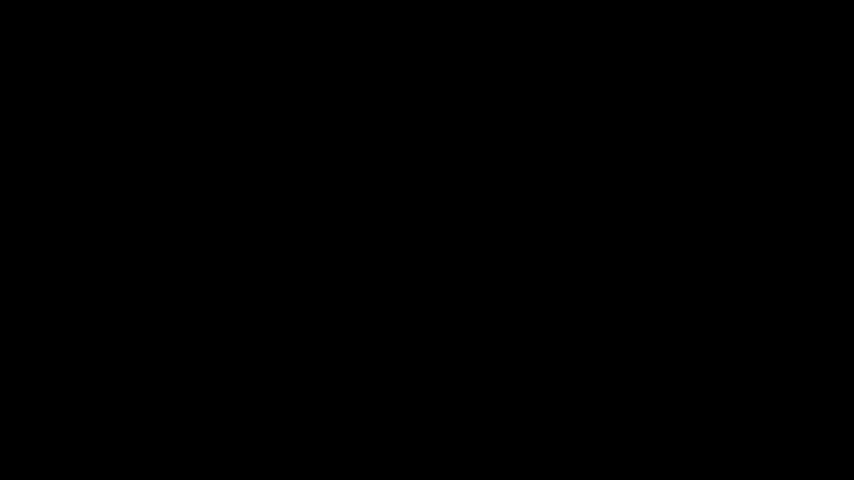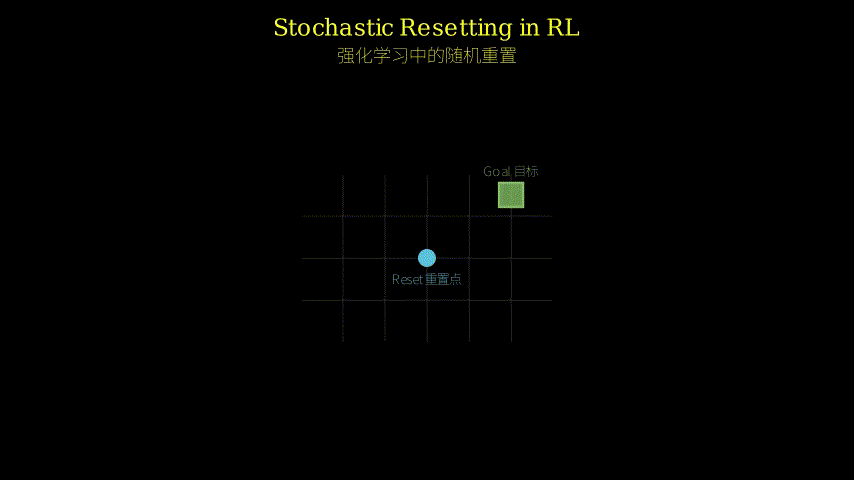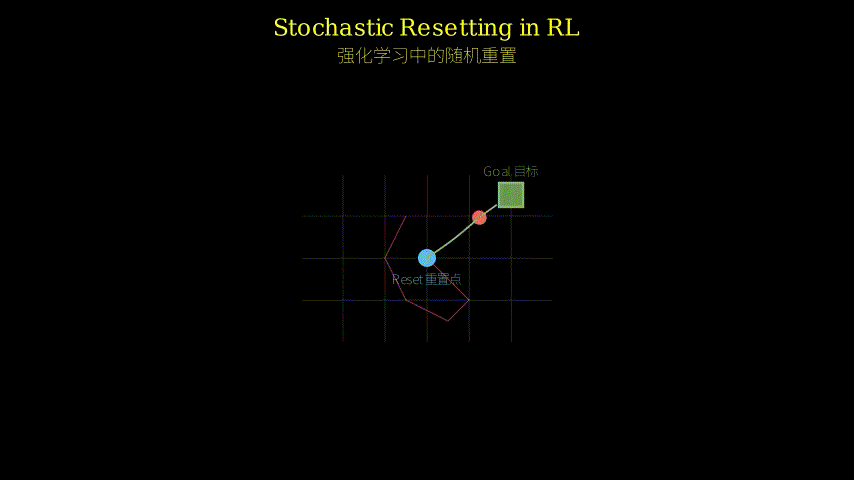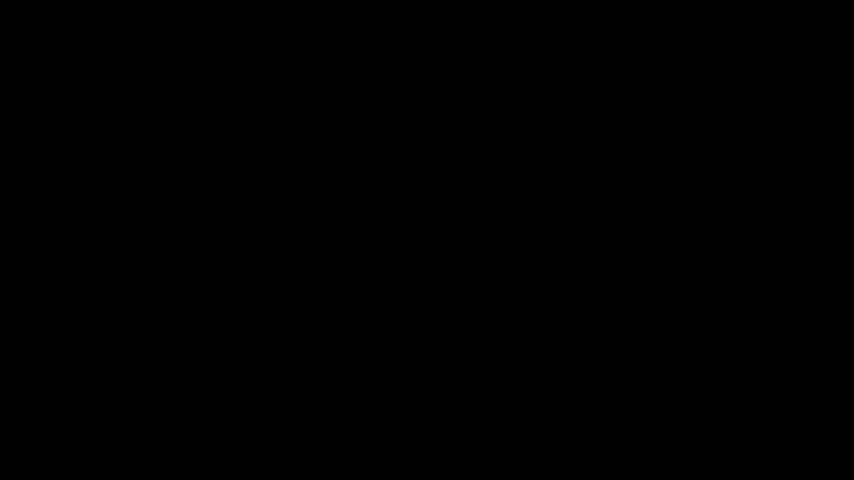
The setup is simple: during training, at each timestep there is a small probability r of resetting the agent back to a fixed reference state (typically the start state). The agent keeps learning from all experience, including the truncated episodes. The reset is not a penalty and does not change the reward function or the definition of the optimal policy.
In the tabular setting, the authors show that resetting accelerates value propagation. The key insight is about credit assignment: in a sparse-reward environment, the agent needs to connect distant states to the reward signal through Bellman backups. Long trajectories that wander away from the reward region contribute noise but little signal. Resetting prunes these trajectories, increasing the relative frequency of transitions near the reward, which speeds up value propagation from the reward outward. Crucially, they demonstrate this effect even in cases where resetting does not reduce the first-passage time of a purely diffusive (non-learning) agent — ruling out the classical mechanism.
In the deep RL setting (continuous control, sparse rewards), random resetting improves sample efficiency when exploration is hard. The neural network value function benefits from the same credit assignment argument: shorter, more informative rollouts reduce the variance of value targets. Unlike discounting, resetting doesn’t compress the effective horizon of the MDP, so the converged policy is the same optimal policy you’d get without resetting — you just get there faster.
  Episode start
       |
       v
  Agent acts -> transition (s, a, r, s')
       |
       |--- with prob (1-r): continue episode
       |
       +--- with prob r: RESET to s_0
                              |
                              v
                    Truncated episode stored
                    in replay / used for update
                              |
                              v
                    Value updates concentrate
                    near reward-rich regions
                              |
                              v
                    Bellman backups propagate
                    faster outward from reward

  Net effect:
  [long wandering traj]  ->  [short focused traj]
  low credit signal          high credit signal
  slow value spread          fast value spread
Think of it like a GPS rerouting system. You’re trying to learn the best route across a city. Without resetting, you sometimes end up in a dead-end neighborhood and spend 40 minutes wandering before the episode ends — you learn a lot about that dead end, but almost nothing about the route to your destination. With resetting, after a few minutes of wandering you’re teleported back to the start. You take more attempts, but each attempt either finds useful signal quickly or gets cut short. The map fills in around the destination first, then spreads outward. The GPS (value function) learns the good routes faster because it keeps getting fresh starts near the origin rather than exhausting itself in irrelevant corners.
Each component maps cleanly: the city is the state space, the destination is the reward, wandering in dead ends is uninformative trajectory, the teleport is the reset, and the map filling in is value propagation via Bellman backups.
Key Concepts
-
Stochastic resetting: Imagine a Roomba that, every few minutes, randomly teleports back to its charging dock regardless of where it is. That’s stochastic resetting. In physics, this is studied because it can make a random searcher find a target faster — if the searcher wanders too far, resetting it saves time. The rate r controls how often this happens. Too frequent and you never make progress; too rare and you waste time lost. There’s a sweet spot.
-
First-passage time vs. policy convergence: First-passage time is how long it takes a random walker to reach a target for the first time. Policy convergence is how many training steps it takes an RL agent to learn a good policy. These sound similar but are different: one is about a single trajectory of a fixed process, the other is about the aggregate learning dynamics across many trajectories of an improving process. This paper’s main conceptual contribution is showing these two metrics can decouple — resetting can help convergence even when it doesn’t help first-passage.
-
Credit assignment in sparse rewards: When rewards only appear at the end of a long sequence of actions, the agent has to figure out which early actions were responsible for the eventual reward. This is the credit assignment problem. Bellman backups propagate value estimates one step at a time, so in a large state space with sparse rewards, it can take an enormous number of updates before early states “know” there’s a reward out there. Resetting helps by keeping the agent close to the reward region more often, so the value signal doesn’t have to travel as far.
Framework Shift
Before (mainstream approach):        After (this paper):

  Long episode                         Short episode (reset)
  s0 -> s1 -> s2 -> ... -> sT          s0 -> s1 -> s2 -> s0
  |                         |          |              |
  reward only at sT         |          reward nearby  |
  |                         |          propagates fast |
  value backups crawl       |                         |
  from sT back to s0        |          + no policy    |
  (slow, noisy)             |            distortion   |
                            |                         |
  Fix: discount gamma<1     |          Fix: reset r   |
  (compresses horizon,      |          (truncates traj,
   shifts optimal policy)   |           preserves MDP)
From discounting-as-the-only-knob to resetting-as-an-orthogonal-knob, the core shift is: you can accelerate learning without touching the reward structure or distorting the optimal policy.
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. The statistical mechanics community has been developing resetting theory for about a decade, and the RL community has been largely unaware of it. Bridging these is a natural and timely move. The specific question — does resetting help learning, not just search? — is crisp and hadn’t been asked. That said, the problem sits at the intersection of two fields in a way that makes it feel more novel than it might be: episode truncation and early termination are already used in practice, and this paper is partly formalizing something practitioners do informally.
Method maturity: The tabular analysis is clean and the theoretical framing is solid. The deep RL experiments are more exploratory — the paper doesn’t give a principled method for choosing r, which is the main practical question. The claim that resetting “preserves the optimal policy” is correct but needs the caveat that the reset state distribution affects what the agent learns about, which can matter in practice. The connection to value propagation speed is intuitive but the formal treatment could be tighter.
Experimental integrity: The tabular experiments are well-controlled and the decoupling from first-passage time is convincingly demonstrated. The deep RL experiments are reasonable but limited in scope — a few environments, and the comparison to baselines like HER (hindsight experience replay) or curriculum learning is absent. Those are the natural competitors for sparse-reward exploration, and their omission is the biggest weakness. The numbers look honest; no obvious cherry-picking.
Writing quality: The paper is well-written for a physics-to-ML crossover. The weakest section is the deep RL experimental analysis — it reads more like “here’s what we tried and it worked” than a systematic investigation of when and why resetting helps in the neural network setting. A more careful ablation of reset rate r, environment difficulty, and network architecture would make the deep RL contribution much stronger and elevate the paper from “interesting observation” to “actionable method.”
Verdict: weak accept — the tabular contribution is solid and the conceptual framing is genuinely useful, but the deep RL experiments need more rigorous comparison to existing sparse-reward methods before the practical claims fully land.
Takeaways
If you’re working on sparse-reward RL, this paper gives you a concrete, zero-cost knob to try: add a reset probability r to your training loop and tune