Paper: 2604.02327 Authors: Jona Ruthardt, Manu Gaur, Deva Ramanan, Makarand Tapaswi, Yuki M. Asano Categories: cs.CV, cs.AI
The Gap
The paper sits between two lines of work that each solve only half the problem.
On one side, pretrained vision encoders like DINOv2 and MAE are very good generic feature extractors. You can throw them at retrieval, segmentation, classification, and a bunch of transfer tasks. But they are fundamentally passive: given an image, they decide for themselves what is salient. If the thing you care about is small, unusual, user-specific, or simply not the dominant object in the scene, the representation does not give you a clean knob to say, “no, attend to the red mug, not the whole kitchen.”
On the other side, vision-language models and multimodal LLMs do allow prompting. CLIP-style systems can align image and text, and MLLMs can answer targeted questions about images. But these systems usually steer through late fusion or language-aligned heads. That often makes the representation more useful for matching text and less useful as a strong, generic visual descriptor. In plain English: you can ask them what to look at, but the resulting feature space becomes too language-shaped.
So the gap is not “can language interact with vision?” We already know it can. The gap is: can a visual representation itself become steerable by language while still remaining a high-quality visual representation? That is a sharper and more interesting target.
The authors’ answer is to inject text inside the visual encoder using lightweight cross-attention, rather than bolt text on after image encoding. That is the key conceptual move.
[Problem]
generic ViT features focus on dominant cues
and cannot be directed

        |
        v

[Assumption]
if text enters only after visual encoding
late fusion steers outputs
but not the visual representation itself

        |
        v

[Method]
inject text into ViT layers
with lightweight cross attention
to make local and global features steerable

        |
        v

[Evidence]
new steerability benchmarks
plus anomaly detection
plus personalized object discrimination
plus OOD zero shot tests

        |
        v

[Conclusion]
language steerable features can target
desired concepts without giving up
strong generic visual utility
The Increment
One sentence: Before this paper, you could have either strong generic visual features or promptable language-conditioned outputs; after this paper, you can plausibly get a visual feature space that is both steerable and still broadly useful.
Core Mechanism
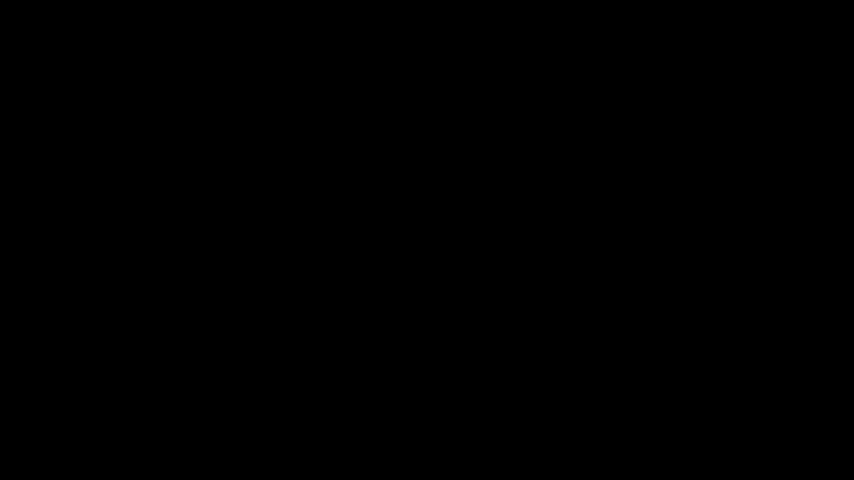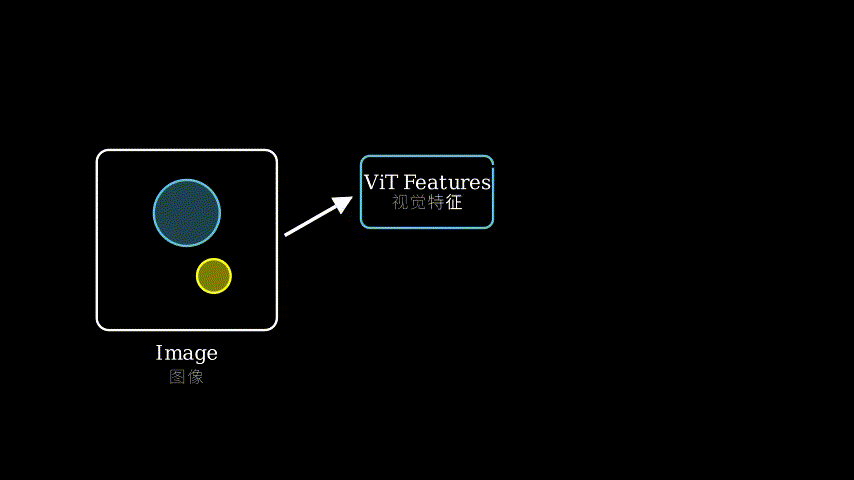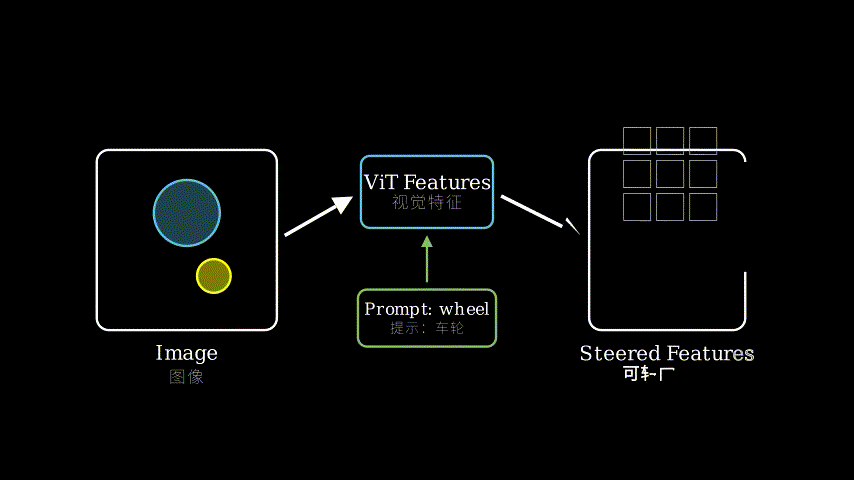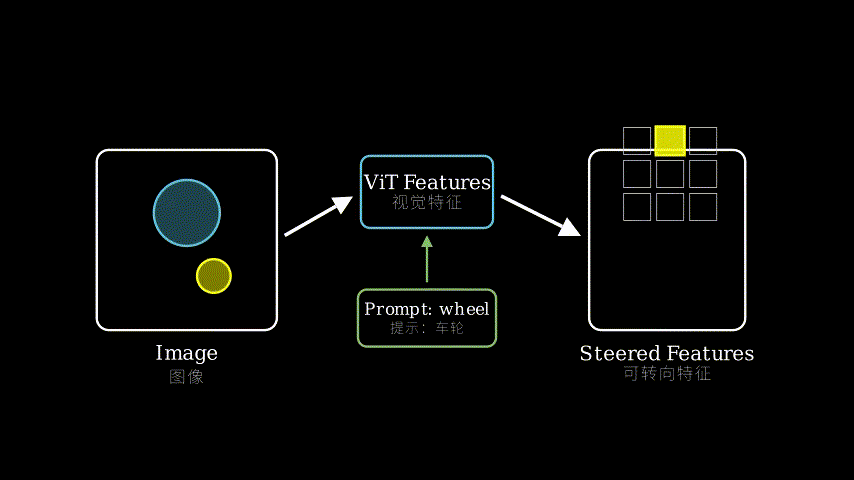
At a high level, the model starts from a pretrained ViT backbone in the DINOv2 or MAE family and adds a lightweight mechanism that lets text tokens interact with visual tokens during feature computation. That distinction matters. In late-fusion systems, the image encoder produces features first, and only afterward does text get compared or fused. Here, the text can nudge the internal representation as it is being built, layer by layer.
Concretely, the image is turned into patch tokens by the ViT, and the text prompt is embedded into text tokens. At selected transformer layers, the visual tokens attend to the text tokens through cross-attention. This gives the visual stream a way to bias itself toward prompt-relevant regions and attributes. Because the text injection is lightweight, the system does not have to rebuild the entire backbone into a giant multimodal model. The paper’s claim is that this preserves the backbone’s visual quality while adding controllability.
The result is not just a global “image embedding for prompt X,” but also local steerability: patch-level or region-level features can shift toward the concept named in the prompt. That is why the method can be used not only for semantic retrieval, but also for things like anomaly detection and personalized object discrimination, where the target concept can be subtle, local, and not the main semantic class of the image.
[Image] -> [Patch tokens] -> [ViT layer 1] -> [ViT layer 2] -> [ViT layer 3] -> [Global Local features]
                               ^               ^               ^
                               |               |               |
                            [Cross attn]    [Cross attn]    [Cross attn]
                               ^               ^               ^
                               \               |               /
                                \              |              /
                                 -> [Text tokens from prompt] ->
A good structural metaphor is a museum tour with a laser pointer.
Think of the pretrained ViT as an experienced museum visitor walking through a gallery. Left alone, this visitor notices the biggest, brightest, most famous pieces. That’s what DINOv2-like features do: they form a competent general impression of the room. Now add a guide holding a laser pointer and saying, “Look at the cracked glaze on that vase,” or “Ignore the central statue; focus on the tiny bird in the mural.” The guide is the text prompt. The laser pointer is the cross-attention injected into intermediate layers.
Late fusion is like letting the visitor walk through the whole museum alone, then asking afterward, “By the way, can you describe objects related to birds?” The answer may be okay, but the walk itself was not guided. Early fusion, in contrast, lets the guide intervene during the walk. Each time the visitor enters a room, the guide can redirect gaze. Crucially, the visitor still remains a trained observer of art, not a tourist who only hears the guide’s words. That is the paper’s balancing act: make the tour steerable without turning the whole experience into language-following only.
Key Concepts
-
Steerability: A representation is steerable if you can change what it emphasizes without changing the image itself. Imagine a photo of a desk with a laptop, a coffee mug, and a sticky note. A normal vision backbone gives one feature embedding for “the desk scene.” A steerable representation lets you ask for “the mug,” “the handwritten note,” or “possible defects on the laptop hinge,” and get features that reorganize around that target.
-
Early fusion vs late fusion: Late fusion means image features and text features are computed mostly separately and merged near the end. Early fusion means text influences the visual processing as features are being formed. A concrete analogy: late fusion is reading a book, then hearing the discussion question afterward; early fusion is hearing the discussion question before and during reading, so you notice different details.
-
Preserving representation quality: This sounds abstract, but it is simple. If adding prompt control makes the encoder bad at core visual tasks, then the method is not very useful. The paper’s real ambition is not just “make it promptable,” but “make it promptable without breaking retrieval, segmentation-like localization, or transfer strength.” That preservation claim is what separates this from just another multimodal adapter.
Framework Shift
Before (mainstream approach):        After (this paper):
[Image] -> [Visual encoder]          [Image] -> [Visual encoder with
              |                                   text injected inside]
              v                                   ^       ^       ^
         [Visual features]                        |       |       |
              |                                   |       |       |
[Text]  -> [Text encoder]                         \       |      /
              |                                    -> [Text] <-
              v
         [Late fusion]
              |
              v
      [Task specific output]
From post-hoc alignment to in-encoder guidance, the core shift is letting language shape the formation of visual features rather than only their interpretation.
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. The field has a lot of strong frozen visual backbones and a lot of promptable multimodal systems, but surprisingly little in the middle for “controllable visual features.” That matters for retrieval, robotics, inspection, and personalized perception. It also fits the trajectory of the field: people increasingly want representations that are not just general, but user-directable.
Method maturity: The core idea is clever rather than brute force. Early text injection via lightweight cross-attention is not conceptually outrageous, but it is exactly the kind of architectural nudge that can open a new operating point. That said, it is also a fairly natural idea in hindsight. One possible critique is that the paper may be benefiting from a smart problem framing as much as from a radically new mechanism. You could imagine simpler baselines, like feature modulation or prompt-conditioned adapters, being stronger than expected if tuned carefully.
Experimental integrity: Based on the abstract, the experiments are pointed in the right direction: they do not stop at “pretty attention maps,” but go into anomaly detection, personalized object discrimination, and OOD zero-shot transfer. That is the right way to argue the method is not a toy. The main thing I would inspect closely in the full paper is whether the baselines are truly competitive for both sides of the tradeoff: strong pure-vision baselines and strong multimodal baselines. This kind of paper lives or dies on whether the comparisons are set up fairly across representation quality and steerability.
Writing quality: The abstract is crisp and unusually clear about the thesis: promptable visual features without sacrificing generic utility. If there is a likely weak spot, it is probably around benchmark definition. “Steerability” can become slippery fast. The most valuable section to rewrite carefully would be the one that operationalizes steerability and explains why the proposed benchmarks measure the thing we actually care about, rather than just text-image compatibility.
Verdict: weak accept — a real and timely problem, a plausible architectural insight, and application-level evidence that could matter, though the case will depend heavily on how convincing and fair the steerability benchmarks are.
Takeaways
There are several practical ideas worth stealing:
-
If you want controllable features, inject control signals early, not only at the output.
This transfers beyond vision-language. In speech, robotics, time series, or video, conditioning often works better when it shapes intermediate representation building rather than only the final head. -
Treat steerability as a representation property, not just an interface feature.
A lot of systems are “promptable” in the weak sense that you can ask them for different outputs. This paper pushes a stronger idea: the underlying feature space itself should shift. That framing is useful in any domain where downstream tasks reuse embeddings. -
Benchmark the tradeoff explicitly.
If you add controllability, measure both: how much steering you gained and how much core representation quality you preserved. That is a very reusable evaluation principle. -
Lightweight cross-attention is a good compromise tool.
If you already have a strong pretrained backbone, you may not need a full multimodal retrain. Small cross-attention modules or adapters inserted into the backbone can create new capabilities at lower cost. -
Personalized and anomaly-style tasks are a good stress test.
If a method really can direct attention to non-salient concepts, these are exactly the tasks where it should shine. That is a useful evaluation design lesson in itself.
论文: 2604.02327 作者: Jona Ruthardt, Manu Gaur, Deva Ramanan, Makarand Tapaswi, Yuki M. Asano 分类: cs.CV, cs.AI
缺口
这篇论文卡在两个成熟方向之间,而且这个位置挑得挺准。
一边是 DINOv2、MAE 这类预训练视觉编码器。
它们已经被证明是很强的通用图像表征:检索、分类、分割、迁移学习,基本都能吃。
问题是它们的表征是“自作主张”的。
输入一张图,它会优先抓最显眼、最主导的视觉线索。
如果你真正关心的是小物体、边角细节、个性化目标,或者图里一个根本不显眼的异常点,这种特征就没有一个直接的控制旋钮。
你没法对它说:“别看整间厨房了,去看那个杯子把手上的裂纹。”
另一边是 CLIP 一类视觉语言模型,以及更广义的多模态大模型。
这类模型当然能被文本引导。
你可以下提示词,让它围绕某个概念做匹配、问答、推断。
但问题也很明显:它们的表示空间往往越来越“语言中心”。
一旦你把目标放在通用视觉特征本身,而不是文本对齐输出,这类方法就不一定占优。
说白了,它们很会“按话做题”,但不一定还是一个干净、稳健、泛化好的视觉特征提取器。
所以真正的缺口不是“语言能不能指导视觉”。
这个问题早就被回答了。
真正的缺口是:能不能让视觉表征本身被语言转向,同时又不失去它作为通用视觉表征的质量。
这就比“做个多模态头”要求高得多。
这篇论文的主张很明确:不要等图像编码完了再和文本做晚融合,而是把文本通过轻量 cross attention 早期注入视觉编码器内部。
这一步,就是它的核心增量。
[问题]
通用ViT特征只盯显著线索
无法按需求被引导

        |
        v

[假设]
如果文本只在编码后进入
那只能转向输出
转不动视觉表征本身

        |
        v

[方法]
在ViT内部多层注入文本
用轻量cross attention
让全局和局部特征可被转向

        |
        v

[证据]
新建可转向性基准
再加异常检测
个性化目标区分
以及OOD零样本测试

        |
        v

[结论]
可以让特征聚焦指定概念
同时保住原本的视觉表征能力
增量
一句话: 在这篇论文之前,大家基本是在“通用视觉特征”和“可提示的多模态输出”之间二选一;这篇论文之后,至少出现了一条可行路线:让视觉特征本身既能被语言转向,又不明显失真。
核心机制
先说骨架。
作者不是从零造一个巨型多模态模型,而是从已经很强的视觉骨干出发,比如 DINOv2、MAE 这类 ViT。
图像照常被切成 patch token,走视觉 Transformer。
与此同时,文本提示也被编码成 text token。
关键区别在于:这些 text token 不是等图像特征都算完了才拿来比对,而是在视觉编码的中间层,通过轻量 cross attention 插进去。
这样一来,视觉 token 在形成过程中就能被提示词“轻推一把”。
如果提示词是 “red mug”,那么中间层的视觉特征会更偏向杯子相关区域、颜色线索、形状细节。
如果提示词是 “defect on metal edge”,那么模型就更有机会把注意力推向边缘、裂痕、局部纹理异常,而不是整张图最显眼的主体。
这就是“转向”真正发生的地方:不是输出头在解释一个固定特征,而是特征本身在生成时就被重排了。
另一个值得注意的点是,它不只想做全局 embedding 的条件化。
从摘要看,作者强调的是 global and local features 都可以被转向。
这很重要。
因为如果只有全局图像表示可控,那它更像是一个文本条件下的分类或检索接口。
但如果局部特征也被转向,那很多需要空间敏感度的任务就有戏了,比如异常检测、个性化物体识别、区域级检索。
[图像] -> [Patch tokens] -> [ViT层1] -> [ViT层2] -> [ViT层3] -> [全局特征 局部特征]
                              ^            ^            ^
                              |            |            |
                          [Cross attn]  [Cross attn]  [Cross attn]
                              ^            ^            ^
                              \            |           /
                               \           |          /
                                -> [提示词Text tokens] ->
我觉得最合适的核喻是:一个训练有素的摄影师,加上一个现场导演的耳返系统。
把预训练 ViT 想成一个很有经验的摄影师。
他进入一个场景后,会自然地拍最显眼、最“值得拍”的东西。
这就像 DINOv2 这种表征,会稳定地抓住主导视觉语义。
现在问题来了:导演真正关心的,可能不是画面中央的人,而是角落里那只被碰翻的杯子,或者人物袖口上一个很小的徽章。
文本提示就是导演通过耳返发来的指令。
Cross attention 就是耳返在摄影过程中实时起作用,而不是拍完以后再补一句“对了,看看角落里有什么”。
如果是晚融合,相当于摄影师已经拍完整段素材了,导演事后才来问:“能不能从里面挑点和徽章有关的内容?”
这时当然也能做,但镜头语言、构图重心、细节捕捉都已经定了。
而早融合则不同:导演在每个拍摄阶段都能插话,“镜头往左一点”“焦点收在袖口”“别管背景大雕像”。
摄影师仍然是专业摄影师,不会变成只会背台词的人;但他的“看法”被持续引导了。
这个比喻为什么承重。
因为它精确对应了论文的结构:
视觉骨干 = 摄影师。
文本提示 = 导演意图。
中间层 cross attention = 耳返实时指令。
最终得到的 steerable visual representation = 被导演过、但摄影质量仍在线的素材。
你记住这套映射,基本就不会把这篇论文误解成“给 CLIP 再接个提示头”。
关键概念
-
可转向性 Steerability:
所谓“可转向”,不是输出文案变了,而是同一张图的特征重心能按指令改变。
想象一张办公桌照片,上面有电脑、便签、咖啡杯。
普通视觉特征会给你一个“这是办公桌场景”的总体表示。
可转向表征则允许你说:“看咖啡杯。”“看手写便签。”“看电脑转轴是不是有异常。”
图还是那张图,但特征在为不同目标重排。
这才叫可转向。 -
早融合 vs 晚融合:
晚融合是先各算各的,最后再合。
早融合是计算过程中就互相影响。
最直观的例子:你读一篇文章。
如果读完才听到讨论题,那你只能回忆哪些段落可能相关。
如果一开始就知道讨论题,而且阅读过程中不断被提醒重点,你注意到的细节会完全不同。
这篇论文的核心就是:让文本像“阅读中的问题意识”那样提前进入视觉编码。 -
保住表征质量:
很多方法一旦加了条件控制,马上就往“任务特化”方向滑。
结果是某个提示下输出更聪明了,但原本那套通用视觉特征被破坏了。
本文真正难的地方不在于“能不能加文本”,而在于“加了以后还能不能继续当一个好用的视觉 backbone”。
这决定了它是一个表示学习工作,还是只是一个多模态外挂。
框架转变
之前(主流方法):                之后(本文方法):
[图像] -> [视觉编码器]             [图像] -> [内部注入文本的视觉编码器]
            |                                      ^      ^      ^
            v                                      |      |      |
         [视觉特征]                                |      |      |
            |                                      \      |     /
[文本] -> [文本编码器]                              -> [文本] <-
            |
            v
         [晚融合]
            |
            v
        [任务输出]
一句话:从“先看完再解释”到“边看边被引导”,核心转变是让语言参与视觉特征的形成,而不只是参与特征的解释。
专家评审
选题眼光:
这是个真缺口,不是硬造出来的。
过去几年视觉领域一头是越来越强的通用 backbone,一头是越来越会听提示词的多模态模型。
但中间这块“可控的视觉表征”其实一直比较空。
尤其在工业检测、机器人感知、个性化检索、长尾目标发现这些场景里,用户往往不是要一个最泛的答案,而是要一个“请你看这个”的视觉系统。
所以这个问题选得顺,而且确实有用。
方法成熟度:
我会把它归到“巧劲明显”的工作。
早期注入文本这件事,事后看很自然,但自然不等于没价值。
很多好论文就是把别人心里模糊觉得“可能该这样”的事,做成了可训练、可验证、可复用的结构。
当然,也得承认它不是那种石破天惊的新范式。
如果一些更简单的条件化手段,比如 adapter、FiLM 式调制、prompt token 注入,被认真调到位,差距是否还这么大,这是我会继续追问的问题。
实验诚意:
从摘要看,作者至少没有只拿可视化热图糊弄过去。
他们把方法放到了异常检测、个性化目标区分、OOD 零样本场景里,这个方向是对的。
因为这些任务正好能检验:模型到底是真的学会“按需去看”,还是只是做了更好看的文本对齐。
不过我真正会盯的还是基线设置。
这种论文最容易出现的问题,是把“纯视觉表征质量”和“语言引导能力”拆成两个不对等的赛道来比。
如果基线没有同时覆盖强视觉 backbone 和强多模态方法,那结论就会偏软。
写作功力:
摘要写得挺利落,问题定义也清楚。
但这类论文最容易写虚的部分,是“steerability 到底怎么定义、怎么量化”。
如果这一块讲得不够硬,整篇文章会有点像在卖一个很好懂的直觉,却没把评价地基打牢。
所以如果要重写一节,我会优先重写 benchmark 和 metric 那部分。
把“什么叫被转向了”“为什么这个指标真的测到它”讲透,整篇文章的说服力会直接上一个台阶。
判决: 弱接收 — 问题真,方法也有味道,应用层证据方向正确;但这类工作能不能站稳,最终还是看可转向性基准是不是定义得足够硬。
要点总结
实践者其实能从这篇论文里偷走不少具体东西。
-
想做可控表征,控制信号最好尽早进骨干。
不要总想着最后一层接个条件头。
如果你的目标是“改变表征如何形成”,那条件信息就该在中间层介入。
这条原则不只适用于视觉,也适用于语音、时间序列、机器人策略网络。 -
把“可提示”升级成“表征可转向”。
很多系统所谓 promptable,只是输出接口会变。
本文提醒我们,一个更强也更实用的目标,是让 embedding 空间本身按需求重排。
只要你有下游复用特征的需求,这个框架就值得直接借。 -
评估时要把收益和代价绑在一起看。
新能力提升了多少。
原本的通用能力掉了多少。
这两个必须一起报。
这是个很实用的实验设计原则,别只报“我变得更可控了”,却不报“我是不是变笨了”。 -
轻量 cross attention 是很值得试的工程折中。
如果你已经有一个很强的预训练 backbone,不一定要推倒重来搞全量多模态预训练。
在中间层插一些小型 cross attention 模块,可能就能换来很强的条件控制能力。
这在成本和收益上很有吸引力。 -
异常检测和个性化目标任务,是检验“真转向”很好的试金石。
因为这些任务关心的常常不是显著主体,而是边角、小众、局部、长尾。
如果一个方法真能把视觉注意力按需转过去,它理应在这些场景先显出价值。
这个实验思路本身就可以被很多别的工作拿去用。