Paper: 2605.31593 Authors: Davis Brown, Samarth Bhargav, Arav Santhanam, Kasper Hong, Ivan Zhang, Matan Shtepel, Steffi Chern, Alexander Robey, Eric Wong, Hamed Hassani Categories: cs.CR, cs.AI
The Gap
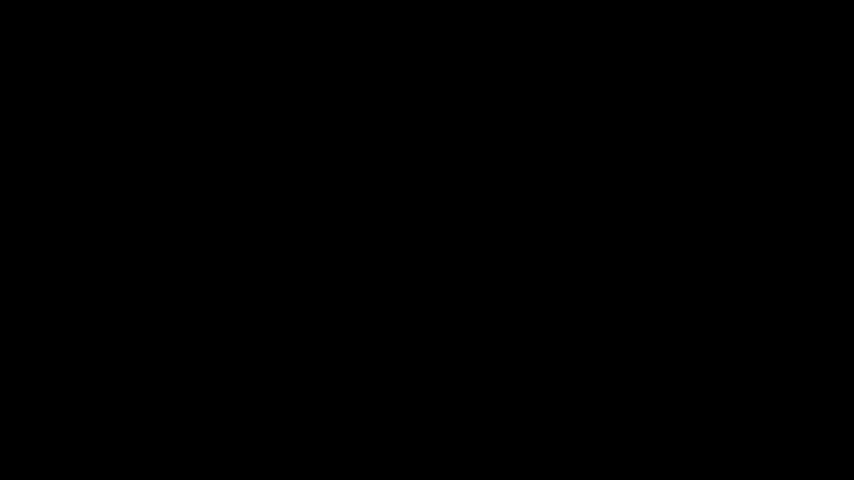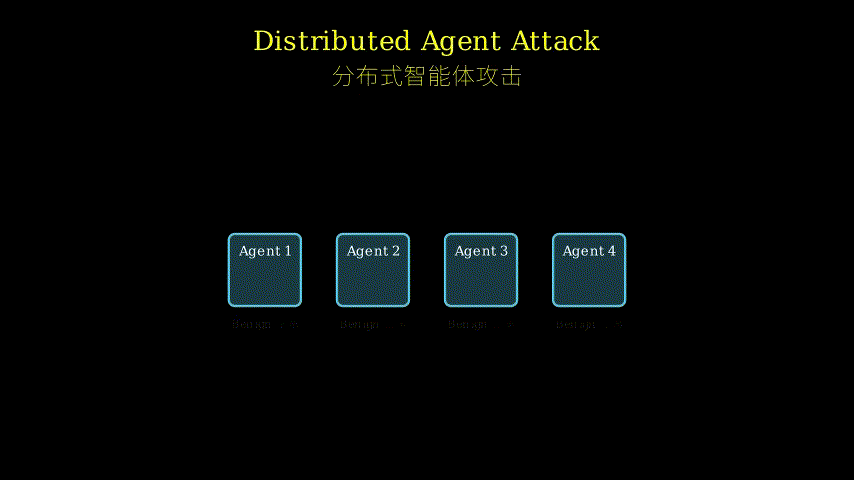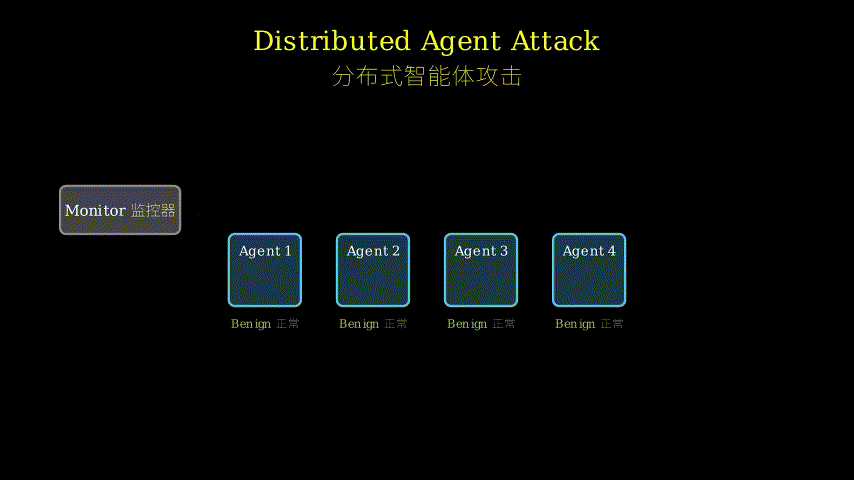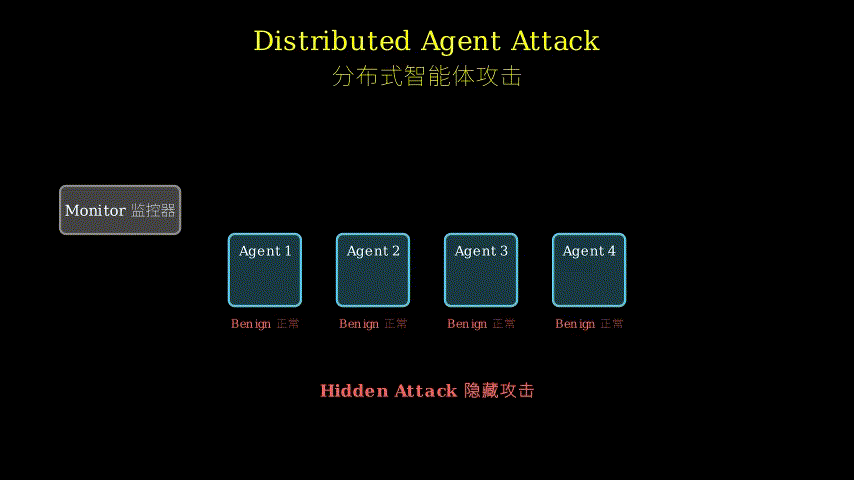
Language model safety monitors score individual conversations in isolation. They look at one user’s transcript, flag it as safe or harmful, and move on. This works when an attacker uses one account to do something bad. But attackers have figured out they can split a harmful task across many accounts—each conversation looks innocent, but together they accomplish the attack. Current monitors are structurally blind to this because they never look across users.
Prior work on agent misuse focuses on jailbreaks and prompt injection within single sessions. Multi-agent systems exist, but safety research treats each agent independently. No one has demonstrated that distributed attacks actually work, or built defenses that reason over groups of users rather than isolated transcripts.
Problem: Attacker splits harmful task across N accounts
   |
   v
Assumption: Weak signals exist in each transcript
   |          that correlate across accounts
   v
Method: Real-time clustering + cross-account LM judge
   |
   v
Evidence: Catches distributed attacks 30% earlier,
   |       5x better than per-session monitors
   v
Conclusion: Safety monitoring needs cross-user state
The Increment
One sentence: Before this paper, safety monitors were stateless and per-session; after, we have evidence that stateful cross-account monitoring catches a new class of distributed attacks that evade standard defenses.
Core Mechanism
The monitor maintains a rolling window of recent agent transcripts across all users. As new messages arrive, a lightweight classifier extracts suspiciousness signals—things like “user asked about vulnerabilities” or “agent discussed exploit code.” These signals are weak: individually they’re noisy and trigger on benign security research. But the key insight is that attackers reuse patterns across their distributed accounts.
The system clusters these signals in real-time using embeddings of the suspicious excerpts. When a cluster grows dense enough (many similar signals from different accounts in a short time window), the monitor escalates to a language model judge. This judge sees the aggregated evidence across accounts and decides whether it’s coordinated misuse or coincidental legitimate activity. The clustering acts as a filter: most benign traffic never reaches the expensive LM judge, keeping latency low.
User transcripts (streaming)
   |
   v
[Lightweight classifier] --> Suspiciousness signals
   |                          (per message, weak)
   v
[Real-time clustering] --> Group similar signals
   |                       across accounts
   v
[Density threshold] --> Trigger when cluster grows
   |
   v
[LM judge] --> Flag coordinated misuse
   |           (sees cross-account context)
   v
Alert or block
Think of it like airport security. A standard monitor is like checking each passenger’s bag individually—if one person carries a suspicious item, you catch them. But what if ten people each carry one innocent-looking component, and together they assemble something dangerous? You’d miss it unless you’re watching for patterns across passengers.
The stateful monitor is like having a system that notices “five people in the last hour all had metal tubes in their bags” and flags that correlation. The lightweight classifier is the X-ray machine (fast, noisy). The clustering is the pattern recognition (grouping similar findings). The LM judge is the human security officer who investigates only when the pattern looks serious (slow, accurate, used sparingly).
Key Concepts
-
Distributed agent attack: An attacker controls multiple user accounts and splits a harmful task (like finding zero-day vulnerabilities) across them. Each subagent gets a limited, benign-looking subtask: “research authentication in this codebase,” “check for input validation here.” No single transcript reveals the harmful intent, but the attacker coordinates the subagents’ outputs offline to complete the attack. Standard monitors see each conversation as safe because they lack the full context.
-
Stateful monitoring: Instead of scoring each conversation independently, the monitor maintains state across users and time. It remembers recent suspicious signals, clusters them, and reasons about whether patterns across accounts indicate coordinated misuse. “Stateful” means the decision for user A’s transcript can depend on what users B, C, and D did recently. This breaks the per-session isolation that lets distributed attacks hide.
-
Weak signal clustering: Individual suspiciousness signals are noisy—lots of false positives from legitimate security researchers, students learning about exploits, etc. But attackers reuse attack strategies across their accounts, creating correlated signals. Clustering groups similar signals (using embeddings of the suspicious text) so the monitor can detect “ten accounts all asked about SQL injection in the last hour” even if each individual query looked borderline. The cluster’s density becomes the strong signal.
Framework Shift
Before (per-session monitoring):        After (stateful cross-account):

User A --> [Monitor] --> Safe/Harmful   User A --\
User B --> [Monitor] --> Safe/Harmful   User B ---+--> [Clustering] --> [LM Judge]
User C --> [Monitor] --> Safe/Harmful   User C --/         |              |
                                         User D ------------|              v
(Each decision independent)                            (Shared state)   Alert if
                                                                        coordinated
From isolated per-session scoring to shared state across users, the core shift is treating safety as a collective property rather than an individual one.
Expert Assessment
Problem choice: This is a real gap. The authors built the first working distributed agent attack and showed standard monitors catch it only 20% of the time (vs. 100% for non-distributed attacks). The threat model is credible: attackers already distribute manual hacking across accounts to avoid rate limits and detection. As agents get better at cybersecurity tasks, this will matter.
Method maturity: The approach is pragmatic rather than elegant. Real-time clustering with a density threshold is straightforward, and the two-stage design (cheap classifier + expensive LM judge) is standard in production systems. The novelty is applying this to cross-account agent monitoring, not inventing new ML techniques. That’s fine—the contribution is showing the problem exists and that a simple defense works. I’d like to see ablations on the clustering algorithm (why embeddings? what about graph-based methods?) but the core idea is sound.
Experimental integrity: The evaluation uses simulated datacenter traffic, which is both a strength and weakness. Strength: they can control the attack/benign ratio and measure false positive rates at scale. Weakness: real attacker behavior might differ from their threat model (e.g., longer time delays between subagent calls, more sophisticated obfuscation). The baselines are fair—they compare against standard per-session monitors and show Pareto dominance. The 30% earlier detection claim holds up in their experiments, but the advantage narrows as benign traffic scales, which they acknowledge honestly.
Writing quality: The paper front-loads the threat (distributed attacks exist and evade defenses) before introducing the solution, which is good structure. The related work section is thin—more comparison to anomaly detection and fraud detection systems would strengthen the positioning. The red-teaming section (adaptive attackers reusing jailbreaks across accounts) is a nice touch but feels like an afterthought; it deserves more prominence since it shows the defense generalizes beyond the original threat model.
Verdict: weak accept — Solid problem identification and a working defense, but the method is incremental and the evaluation is simulation-heavy. The contribution is more “this problem is real and here’s a reasonable first solution” than “here’s a breakthrough technique.”
Takeaways
For practitioners building agent systems: Implement two-stage monitoring. Run a fast, noisy classifier on every request, then escalate only high-density clusters to a slow, accurate judge. This keeps latency low for 99% of traffic while catching coordinated misuse.
For security researchers: Attackers will distribute. If your threat model assumes one account per attacker, you’re missing a large attack surface. Start logging cross-account patterns now, even if you’re not actively monitoring them yet.
For ML safety teams: Stateful monitoring is underexplored. Most safety research focuses on making individual model calls safer (RLHF, input filters, output classifiers). This paper shows you also need to reason about usage patterns across users and time. The clustering approach here is simple; there’s room for better methods that handle adaptive attackers who add noise to decorrelate their signals.
Transferable technique: The weak-signal-clustering pattern applies beyond agent safety. Fraud detection, spam filtering, and abuse detection all face similar problems: individual signals are noisy, but coordinated actors create correlations. If you’re building any system where attackers can split their activity across accounts, consider maintaining cross-user state and clustering suspicious events in real-time.
论文: 2605.31593 作者: Davis Brown, Samarth Bhargav, Arav Santhanam, Kasper Hong, Ivan Zhang, Matan Shtepel, Steffi Chern, Alexander Robey, Eric Wong, Hamed Hassani 分类: cs.CR, cs.AI
缺口
语言模型安全监控器对单个对话进行孤立评分。
它们查看一个用户的对话记录,标记为安全或有害,然后继续处理下一个。
当攻击者使用一个账户做坏事时,这种方法有效。
但攻击者发现可以将有害任务分散到多个账户——每个对话看起来都无害,但合在一起就完成了攻击。
现有监控器在结构上对此视而不见,因为它们从不跨用户查看。
此前关于智能体滥用的研究聚焦于单会话内的越狱和提示注入。
多智能体系统已经存在,但安全研究将每个智能体独立对待。
没有人证明分布式攻击真的有效,也没有人构建能跨用户群体推理而非孤立对话的防御系统。
问题:攻击者将有害任务分散到 N 个账户
   |
   v
假设:每个对话记录中存在弱信号
   |    这些信号在账户间相关
   v
方法:实时聚类 + 跨账户语言模型判断
   |
   v
证据:提前 30% 捕获分布式攻击,
   |    比单会话监控器好 5 倍
   v
结论:安全监控需要跨用户状态
增量
一句话:这篇论文之前,安全监控器是无状态的、按会话的;之后,我们有证据表明有状态的跨账户监控能捕获一类新的分布式攻击,这类攻击能逃避标准防御。
核心机制
监控器维护一个滚动窗口,包含所有用户最近的智能体对话记录。
当新消息到达时,一个轻量级分类器提取可疑信号——比如”用户询问漏洞”或”智能体讨论了漏洞利用代码”。
这些信号很弱:单独看它们很嘈杂,会在良性安全研究上误报。
但关键洞察是攻击者会在其分布式账户间重用模式。
系统使用可疑片段的嵌入向量对这些信号进行实时聚类。
当一个簇变得足够密集(短时间窗口内来自不同账户的许多相似信号)时,监控器升级到语言模型判断器。
这个判断器看到跨账户的聚合证据,决定这是协同滥用还是巧合的合法活动。
聚类充当过滤器:大多数良性流量永远不会到达昂贵的语言模型判断器,保持低延迟。
用户对话记录(流式)
   |
   v
[轻量级分类器] --> 可疑信号
   |               (每条消息,弱信号)
   v
[实时聚类] --> 跨账户分组相似信号
   |
   v
[密度阈值] --> 簇增长时触发
   |
   v
[语言模型判断器] --> 标记协同滥用
   |                (看到跨账户上下文)
   v
警报或阻止
把它想象成机场安检。
标准监控器就像单独检查每个乘客的行李——如果一个人携带可疑物品,你能抓住他们。
但如果十个人每人携带一个看起来无害的组件,合在一起能组装成危险物品呢?
除非你在观察乘客间的模式,否则会错过。
有状态监控器就像有一个系统注意到”过去一小时内五个人的行李里都有金属管”并标记这种关联。
轻量级分类器是X光机(快速、嘈杂)。
聚类是模式识别(分组相似发现)。
语言模型判断器是人类安检员,只在模式看起来严重时才调查(慢速、准确、谨慎使用)。
关键概念
- 分布式智能体攻击:攻击者控制多个用户账户,将有害任务(如寻找零日漏洞)分散到这些账户。
每个子智能体得到一个有限的、看起来良性的子任务:“研究这个代码库中的身份验证”,“检查这里的输入验证”。
没有单个对话记录揭示有害意图,但攻击者离线协调子智能体的输出以完成攻击。
标准监控器将每个对话视为安全,因为它们缺少完整上下文。
- 有状态监控:监控器不是独立评分每个对话,而是维护跨用户和时间的状态。
它记住最近的可疑信号,对它们聚类,并推理跨账户的模式是否表明协同滥用。
“有状态”意味着对用户 A 对话记录的决策可以依赖于用户 B、C 和 D 最近做了什么。
这打破了让分布式攻击得以隐藏的单会话隔离。
- 弱信号聚类:单个可疑信号很嘈杂——来自合法安全研究人员、学习漏洞利用的学生等的大量误报。
但攻击者在其账户间重用攻击策略,产生相关信号。
聚类将相似信号分组(使用可疑文本的嵌入向量),这样监控器可以检测到”过去一小时内十个账户都询问了 SQL 注入”,即使每个单独的查询看起来处于边界。
簇的密度成为强信号。
框架转变
之前(单会话监控):                之后(有状态跨账户):

用户 A --> [监控器] --> 安全/有害   用户 A --\
用户 B --> [监控器] --> 安全/有害   用户 B ---+--> [聚类] --> [语言模型判断器]
用户 C --> [监控器] --> 安全/有害   用户 C --/       |            |
                                    用户 D -----------|            v
(每个决策独立)                              (共享状态)      如果协同
                                                              则警报
从孤立的单会话评分到跨用户的共享状态,核心转变是将安全视为集体属性而非个体属性。
专家评审
选题眼光:这是一个真实的缺口。
作者构建了第一个有效的分布式智能体攻击,并表明标准监控器只能在 20% 的时间捕获它(相比非分布式攻击的 100%)。
威胁模型可信:攻击者已经在跨账户分布手动黑客活动以避免速率限制和检测。
随着智能体在网络安全任务上变得更好,这将变得重要。
方法成熟度:这种方法务实而非优雅。
带密度阈值的实时聚类很直接,两阶段设计(廉价分类器 + 昂贵的语言模型判断器)在生产系统中是标准做法。
新颖之处在于将其应用于跨账户智能体监控,而非发明新的机器学习技术。
这没问题——贡献在于表明问题存在且简单防御有效。
我想看到关于聚类算法的消融实验(为什么用嵌入向量?基于图的方法呢?)但核心思想是合理的。
实验诚意:评估使用模拟数据中心流量,这既是优势也是劣势。
优势:他们可以控制攻击/良性比率并大规模测量误报率。
劣势:真实攻击者行为可能与他们的威胁模型不同(例如,子智能体调用之间更长的时间延迟,更复杂的混淆)。
基线是公平的——他们与标准单会话监控器比较并显示帕累托优势。
提前 30% 检测的声明在他们的实验中成立,但随着良性流量扩展优势缩小,他们诚实地承认了这一点。
写作功力:论文在引入解决方案之前先强调威胁(分布式攻击存在并逃避防御),这是好的结构。
相关工作部分较薄——与异常检测和欺诈检测系统的更多比较会加强定位。
红队部分(自适应攻击者跨账户重用越狱)是一个不错的点缀,但感觉像是事后补充;它值得更突出的位置,因为它表明防御超越了原始威胁模型。
判决:弱接收 — 扎实的问题识别和有效的防御,但方法是增量式的,评估以模拟为主。
贡献更多是”这个问题是真实的,这是一个合理的初步解决方案”而非”这是一个突破性技术”。
要点总结
对于构建智能体系统的实践者:实施两阶段监控。
对每个请求运行快速、嘈杂的分类器,然后只将高密度簇升级到慢速、准确的判断器。
这为 99% 的流量保持低延迟,同时捕获协同滥用。
对于安全研究人员:攻击者会分布。
如果你的威胁模型假设每个攻击者一个账户,你就错过了一个大的攻击面。
现在就开始记录跨账户模式,即使你还没有主动监控它们。
对于机器学习安全团队:有状态监控研究不足。
大多数安全研究聚焦于使单个模型调用更安全(RLHF、输入过滤器、输出分类器)。
本文表明你还需要推理跨用户和时间的使用模式。
这里的聚类方法很简单;有更好方法的空间来处理添加噪声以去相关其信号的自适应攻击者。
可迁移技术:弱信号聚类模式适用于智能体安全之外。
欺诈检测、垃圾邮件过滤和滥用检测都面临类似问题:单个信号嘈杂,但协同行为者产生关联。
如果你正在构建任何攻击者可以跨账户分割其活动的系统,考虑维护跨用户状态并实时聚类可疑事件。