Paper: 2608.12314 Authors: Yuyang Yin, Zixiang Li, Longxuan Deng, Hongkai Li, Shifang Zhao, Junnan Liu, Weirong Huang, Mengyu Wang, Tianxiao Fu, Yikai Wang Categories: cs.CV
The Gap
Previsualization — the rough animatic a director, level designer, or architect makes before anything expensive gets built — is fundamentally an iterative activity. You block a scene, look at it, move the chair two feet left, try a lower camera, look again. Twenty rounds later you have a shot list.
Generative video models are structurally bad at this, and not because they lack fidelity. Text-to-video and image-to-video systems (the Sora/Veo family), plus the camera-conditioned variants (MotionCtrl, CameraCtrl and successors), collapse everything — scene layout, object identity, motion, lens, trajectory — into a single conditioning vector consumed in one shot. The consequences are specific:
- No object identity across edits. “Same room, but move the lamp” is a fresh sample. The chair drifts, the wall texture changes, the window moves. There is nothing in the system that *is the lamp.
- Camera control is entangled and approximate. Trajectory conditioning is learned and soft; you cannot ask for a 35mm lens at exactly this dolly path and get it, and you certainly cannot know in advance whether that path clips a wall.
- Every edit costs a full regeneration. Even though 95% of the world is supposed to stay fixed, the model recomputes all of it — expensive and non-deterministic.
The 3D-generation line (Text2Room, LucidDreamer, WonderJourney, scene-graph-to-3D work) has persistence but historically weak editability and a single-shot construction pipeline: you get a world, not a world you can keep revising.
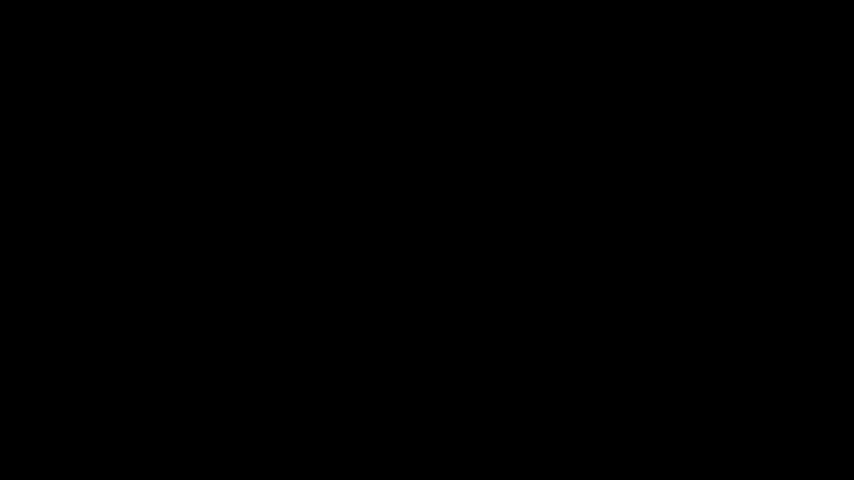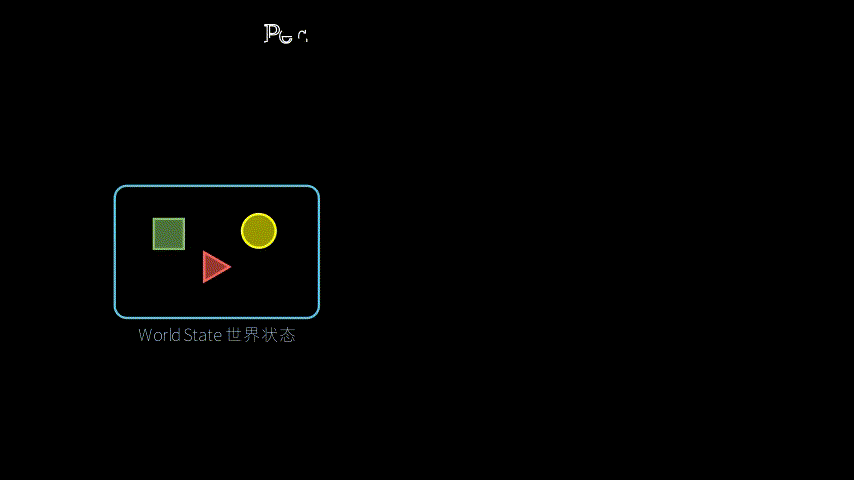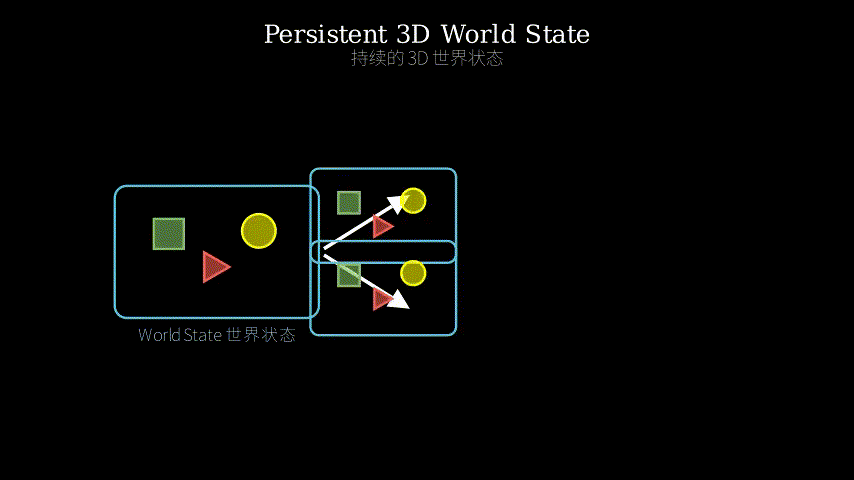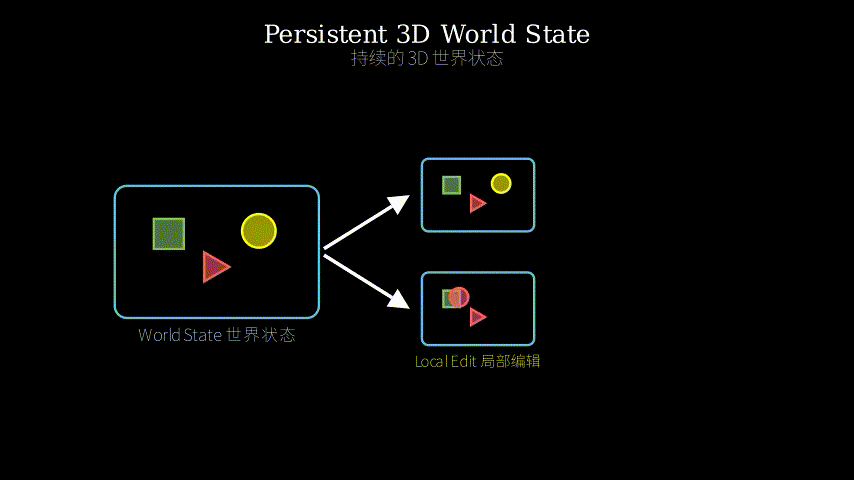
StateFlow’s claim is that the missing piece is not a better generator but a persistent working state — an explicit, structured 3D representation of scene elements plus camera configurations that survives between edits, and against which edits are *diffs rather than re-rolls.
   PROBLEM
   [ previsualization is iterative;  video models are stateless ]
        |
        v
   ASSUMPTION
   [ frames of a world are mostly the SAME state, ]
   [ locally modified or recombined              ]
        |
        v
   METHOD  (state-centric, 3 stages)
   +----------------+----------------+----------------+
   | CONSTRUCT      | EVOLVE         | ACCESS         |
   | 2D -> 3D via   | intent -> structured | camera plan +  |
   | dual-view init | state transition,    | render-feedback|
   | conflict-aware | keep world memory    | reflection     |
   +----------------+----------------+----------------+
        |
        v
   EVIDENCE
   [ video creation quality ]  [ game-like prototyping demos ]
   [ edits without full-scene regeneration ]
        |
        v
   CONCLUSION
   [ the working representation, not the sampler, ]
   [ is the controllability bottleneck            ]
The Increment
One sentence: Before, previsualization with generative models meant re-rolling a whole video for every note; after, there is an editable 3D world sitting on the table that you patch, and the video model is demoted to a finishing pass on top of renders.
Core Mechanism
The system is organized around one data structure and three verbs acting on it. The data structure is the world state: a set of scene elements, each carrying geometry, appearance, and attributes, plus a set of camera configurations. Everything else in the paper is an operation that writes to or reads from this state.
Construct. Generation still starts in 2D — that is where the good priors live — and the output is lifted into 3D. The interesting engineering is what the paper calls *prior-guided, conflict-aware dual-view initialization. A single image plus a monocular depth prior gives an underdetermined and locally inconsistent geometry: depth is ambiguous up to scale and warps badly at occlusion boundaries. Using two views constrains it, but now the two lifted reconstructions disagree — the same surface lands in two places. “Conflict-aware” means the initialization explicitly detects and adjudicates those disagreements instead of averaging them into mush, with generative/geometric priors guiding which view to trust where. The output is a coherent single world, not two point clouds stapled together.
Evolve. A user says “make it night, and have the character walk to the door.” Instead of re-prompting a generator, this is parsed into a *structured state transition: which elements are touched, what attributes change, what is added or removed. Untouched elements are simply reused — the paper’s “world memory.” This is the part that makes iteration cheap and identity stable, and it is also the part that quietly imposes a schema: the space of expressible edits is exactly the space of transitions the state supports.
Access. Cameras are planned (plausibly by a VLM given the scene and the user’s intent), but the paper’s point is that semantic planning alone produces trajectories that *read correct and look wrong: the dolly passes through geometry, the subject is occluded at frame 40, the framing is empty. So access is a closed loop — render the candidate trajectory, inspect the actual rendered frames, revise. Render output, not model confidence, is the arbiter. Finally, off-the-shelf video models take the geometrically correct but visually rough render and upgrade fidelity when needed.
  user intent (text)
        |
        v
  +----------------------------- STATE ACCESS -------------------+
  |  VLM camera plan --> render --> inspect frames --> revise    |
  |         ^                                          |         |
  |         +------------------ reflection ------------+         |
  +--------------------------------------------------------------+
        ^                                    |
        |  read                              v  rendered frames
        |                          [ off-the-shelf video model ]
        |                                    |
        |                                    v  final shots
  ==================================================
  ||            PERSISTENT 3D WORLD STATE         ||
  ||  elements: geometry / appearance / attrs     ||
  ||  cameras : pose / lens / trajectory          ||
  ==================================================
        ^ write (diff only)          ^ write (init)
        |                            |
  +--------------+          +---------------------------+
  | STATE EVOLVE |          | STATE CONSTRUCTION        |
  | intent ->    |          | 2D gen -> dual-view lift  |
  | structured   |          | prior-guided,             |
  | transition;  |          | conflict-aware merge      |
  | reuse rest   |          +---------------------------+
  +--------------+
The metaphor: a physical film set with a standing crew. This one carries the whole paper.
The world state is the set itself — a soundstage with real props at real positions. Not a photograph of a set: the actual furniture.
State construction is the carpentry crew building from concept art. Give them one painting and they will argue about how deep the room is; give them two paintings from different angles and they can triangulate — but the two paintings will contradict each other in places (a doorway that can’t exist in both). A good foreman doesn’t split the difference on a contradiction; he decides which drawing governs which wall. That decision procedure is “conflict-aware dual-view initialization.”
State evolution is the stagehands working from a change note. The note says “swap the lamp, kill the practicals, actor crosses to the door.” Nobody demolishes the set. Everything not on the note stays exactly where it was — that is world memory, and it is why the chair doesn’t drift between takes.
State access is the camera operator and the rehearsal take. He plans a dolly move on paper (the VLM plan), then walks it — and discovers the crane clips the doorframe and the lead is hidden behind a pillar at second three. He watches the monitor and adjusts. Nobody trusts the paper plan; the monitor is the ground truth. That’s render-feedback reflection.
And the video model is post-production: color, grain, atmosphere on top of a take whose blocking and camera are already locked. It makes things prettier. It is not allowed to decide where the lamp is.
Key Concepts
-
Persistent working state (vs. stateless sampling): Think of the difference between a spreadsheet and a screenshot of a spreadsheet. Both look the same on screen. But if you want cell B7 to say 42, one is a two-second edit and the other requires repainting the image and hoping the other 200 cells come out identical. Every current text-to-video model is the screenshot: the “world” exists only as pixels in an output, never as an object you can address. StateFlow’s whole bet is that previsualization needs the spreadsheet. The corollary, which is also the cost: you now need a schema, and anything your schema can’t express, your users can’t ask for.
-
Conflict-aware dual-view initialization: Close one eye and try to grab a mug — you’ll misjudge the distance, because one image doesn’t determine depth. Open both eyes and it’s easy. Now imagine your two eyes were painted by two different artists who didn’t coordinate: the mug’s handle is on the left in one and the right in the other. Naive stereo fusion averages them and you get a smeared handle. “Conflict-aware” means the system notices that the two views make incompatible claims about the same surface, and resolves the claim (pick one, or defer to a learned prior) rather than blending. The practical payoff is clean geometry at exactly the places that usually break: occlusion boundaries and disoccluded regions the second view invented.
-
Render-feedback reflection: Ask a language model “is this camera path good?” and it will answer from semantics — “yes, a slow push-in emphasizes the character’s isolation.” It has no idea the path goes through a wall, because it never looked. Reflection here means: don’t ask, *render. Execute the trajectory, get actual frames, check whether the subject is visible, whether geometry intersects, whether the framing is empty, then revise the plan from that evidence. It is the same move as compiling your code instead of asking an LLM whether it compiles — a cheap, exact verifier closing a loop around an expensive, fuzzy planner.
Framework Shift
  Before (mainstream approach):          After (this paper):

   prompt v1                              prompt
      |                                     |
      v                                     v
  [ big video model ]                 [ 2D gen + 3D lift ]
      |                                     |
      v                                     v
   video v1  ....... discard          ==================
                                      || WORLD  STATE ||<--+
   prompt v2 (+ "but move the lamp")   ==================   |
      |                                  |          ^       |
      v                                  |          |       | diff
  [ big video model ]                    | render   | patch |
      |                                  v          |       |
      v                             [ frames ]      +-------+
   video v2  ... everything            |             edit note
   drifted; lamp moved, so             v
   did the chair and the wall     [ video model: polish ]
                                       |
   state lives NOWHERE                 v
                                    shot v1, v2, v3 ...
                                    (same world, guaranteed)
From one-shot synthesis to a stateful edit loop, the core shift is that the world becomes the artifact and the video becomes a view of it — so controllability stops being a conditioning problem and becomes a data-structure problem.
Expert Assessment
Problem choice: Real gap, and a well-chosen concrete target. The diagnosis itself is not original — “video models have no persistent state” has been the standing complaint behind the whole world-model turn, and plenty of groups are converging on 3D-or-scene-graph intermediates. What’s good here is picking previsualization specifically: it’s a domain where users genuinely don’t need photoreal output, they need *the same world, twenty times, with small changes, and exact cameras. That’s a workflow where an explicit state pays for itself immediately, unlike general-purpose video generation where the fidelity tax of going through 3D is harder to justify. Sitting the paper at that spot is the smart move.
Method maturity: Mostly clever plumbing over off-the-shelf parts — 2D generator, depth/geometry priors, a VLM planner, a video enhancer — and I mean that as a mixed compliment. The architecture-level insight (state as first-class citizen; edits as transitions) is right and well-executed as a system. Each of the three stage-level contributions is a sensible patch on a known failure rather than a new formulation: dual-view conflict resolution addresses monocular lifting artifacts, world memory addresses regeneration cost, reflection addresses VLM ungroundedness. The reflection loop is the cleanest of the three and generalizes best. The overlooked simpler baseline that deserves a straight answer: an LLM writing Blender/Unreal scripts over a library of assets *already gives persistent state, exact cameras, and cheap diffs. StateFlow’s advantage has to come entirely from generative asset/scene creation for things no library has — which means the honest comparison is “our lifted world vs. retrieved-and-scripted assets,” and I’d want that in the paper. The abstract also doesn’t commit to a representation (mesh? splats? hybrid?), and that choice determines nearly everything about edit expressiveness.
Experimental integrity: This is where I’d push hardest, and where I have to hedge: the abstract only promises “high-quality 3D worlds for video creation and game-like prototyping” and names no metric, so my read here is provisional. Two structural risks. First, baseline asymmetry: a three-stage pipeline with a VLM planner and a video-model finishing pass, compared against a bare text-to-video model, is not a controlled comparison — the fair peers are other 3D-scene-generation plus camera-control pipelines, plus that scripted-3D baseline above. Second, and more important, the paper’s central claim is about *iteration, and iteration is not measured by FVD or a single-shot user preference. The load-bearing experiment is a multi-round editing protocol with quantitative identity preservation (do untouched elements stay bit-identical? metrically identical?), edit latency versus regeneration, and drift accumulated over ten sequential edits. If the evaluation is single-shot quality metrics plus a user study on cherry-picked demos, the framing is asserted rather than demonstrated. I’d also want failure cases for the reflection loop — what happens when no feasible trajectory exists, and does it terminate?
Writing quality: The abstract spends a lot of its budget on framing prose (“we argue that the missing component is an explicit and persistent working state”) and very little on mechanism, and the three stage names are branding, not description. The section that would most elevate the paper if rewritten is state representation and evolution: give me the actual schema — what an element is, what fields it carries, and the closed set of transition operators the system supports — and the reader can immediately reason about what the system can and cannot do. Right now “structured state transitions” could mean a rich typed operator algebra or three hardcoded edit types, and the difference is the difference between a framework and a demo. A second-order fix: state plainly what is learned versus what is prompted, since a lot of this pipeline is likely training-free orchestration and that’s fine to admit.
Verdict: weak accept — right problem, well-structured system, genuinely useful framing, but the contribution is integration-level and the central iteration claim needs to be measured rather than argued.
Takeaways
Things that transfer out of the paper’s specific domain:
-
Render as the verifier for a planner. Any time you have an LLM/VLM proposing a plan in a domain where a cheap exact executor exists, close the loop with the executor instead of a second model call. Here it’s rendering camera paths; the same pattern is a compiler for code, a physics step for robot plans, a query planner for SQL, a layout engine for UI generation. The general form: *semantic plausibility and executable feasibility are different predicates, and only one of them can be checked cheaply and exactly. Spend your verifier budget there.
-
Make the diff the primitive, not the artifact. If your users iterate, the interface should accept change descriptions against a persistent state, not full re-specifications. This sounds obvious and almost no generative system does it, because it forces you to define a schema. Worth the cost the moment average sessions exceed ~3 rounds.
-
Adjudicate contradictions instead of averaging them. The dual-view lesson generalizes to any multi-source fusion: when two sources make incompatible claims about the same entity, blending produces artifacts that are worse than picking wrong. Detect the conflict, then arbitrate with a prior. This applies to sensor fusion, multi-annotator labels, and ensembling retrieval results.
-
Demote the expensive model to a finishing pass. Structure (layout, identity, camera) gets decided in a cheap controllable representation; the heavy generative model only handles appearance at the end. This is a reusable architecture for controllability-vs-fidelity tradeoffs generally, and it also means you can swap the heavy model out next quarter without touching your system.
What I would not take on faith yet: that going through an explicitly lifted 3D world is worth the geometric-artifact tax for anything beyond rough previsualization. The paper picks a domain where it clearly is. Extrapolating past that domain is on you.
论文: 2608.12314 作者: Yuyang Yin, Zixiang Li, Longxuan Deng, Hongkai Li, Shifang Zhao, Junnan Liu, Weirong Huang, Mengyu Wang, Tianxiao Fu, Yikai Wang 分类: cs.CV
缺口
预演(previsualization)就是导演、关卡设计师、建筑师在真正花钱之前做的那版粗糙动态分镜。 它的本质是反复改:先摆一遍场景,看一眼,把椅子往左移两尺,换一个更低的机位,再看一眼。 二十轮之后,你才拿到一份可用的镜头表。
生成式视频模型在这件事上结构性地不行,问题不在画质。 文生视频、图生视频(Sora/Veo 这一脉),加上带相机条件的变体(MotionCtrl、CameraCtrl 及后续工作),把场景布局、物体身份、运动、镜头、轨迹全部压缩进一次性的条件输入里。 后果很具体:
-
跨编辑没有物体身份。 「同一个房间,把台灯挪一下」在系统里就是重新采样一次。 椅子飘了,墙面材质变了,窗户位置也动了。 因为系统里根本没有任何东西「是」那盏台灯。
-
相机控制既纠缠又近似。 轨迹条件是学出来的软约束,你没法要求「35mm 镜头沿这条精确的推轨路径」并真的拿到它;更别说事先知道这条路径会不会穿墙。
-
每一次修改都是一次全量重算。 哪怕世界的 95% 本该原封不动,模型还是把全部重新算一遍——贵,而且不可复现。
3D 生成那一脉(Text2Room、LucidDreamer、WonderJourney、场景图转 3D 等)有持久性,但历史上可编辑性弱,而且构建流程本身也是一次性的:你得到的是一个世界,不是一个可以持续修改的世界。
StateFlow 的主张是:缺的不是更好的生成器,而是一个持久的工作状态——由场景元素与相机配置组成的显式结构化 3D 表示,它在两次编辑之间存活下来;于是编辑变成对它打补丁,而不是重摇一次骰子。
   PROBLEM
   [ 预演是迭代的;  视频模型是无状态的 ]
        |
        v
   ASSUMPTION
   [ 一个世界的不同帧, 大部分是同一份状态, ]
   [ 只是被局部修改或重新组合             ]
        |
        v
   METHOD  (以状态为中心, 三阶段)
   +----------------+----------------+----------------+
   | CONSTRUCT      | EVOLVE         | ACCESS         |
   | 2D -> 3D       | 意图 -> 结构化 | 镜头规划 +     |
   | 双视图初始化   | 状态迁移;      | 渲染反馈       |
   | 冲突感知       | 保留世界记忆   | 反思修正       |
   +----------------+----------------+----------------+
        |
        v
   EVIDENCE
   [ 视频创作质量 ]  [ 类游戏原型 demo ]
   [ 修改无需全场景重生成 ]
        |
        v
   CONCLUSION
   [ 可控性的瓶颈在于工作表示, ]
   [ 而不在于采样器           ]
增量
一句话:以前用生成模型做预演,导演每提一条意见你就得把整段视频重摇一次;现在桌上摆着一个可编辑的 3D 世界,你对它打补丁,而视频模型被降级成渲染结果之上的精修环节。
核心机制
整个系统围绕一个数据结构和作用于它的三个动词来组织。 数据结构就是「世界状态」:一组场景元素(每个带几何、外观、其他属性)加一组相机配置。 论文里其他所有东西,都是往这个状态里写、或者从它里面读的操作。
构建(Construct)。 生成仍然从 2D 开始——好的先验都长在那里——然后把输出抬升到 3D。 真正有工程含量的是论文所谓的「先验引导、冲突感知的双视图初始化」。 单张图加单目深度先验给出的几何是欠定的,而且局部不自洽:深度只在相差一个尺度的意义下确定,在遮挡边界处还会严重扭曲。 用两个视图能加约束,但新问题来了——两次抬升的结果彼此矛盾,同一个表面落到了两个位置。 「冲突感知」的意思是:显式地检测并裁决这些矛盾,而不是把它们平均成一团糊,同时用生成/几何先验决定在哪个区域该信哪个视图。 输出是一个自洽的单一世界,不是两片点云硬拼在一起。
演化(Evolve)。 用户说「改成夜晚,让角色走到门口」。 系统不去重新 prompt 生成器,而是把这句话解析成一次结构化状态迁移:哪些元素被触及、哪些属性改变、增加什么、删除什么。 没被触及的元素直接复用——这就是论文说的「世界记忆」。 这一段是迭代变便宜、身份变稳定的原因,同时它也悄悄引入了一个 schema:用户能表达的编辑,恰好等于状态支持的迁移集合。
访问(Access)。 相机是被规划出来的(大概率由 VLM 结合场景与用户意图给出),但论文的关键判断是:纯语义规划产出的轨迹读起来对、看起来错——推轨穿过几何体、第 40 帧主体被挡住、构图空了。 所以访问是一个闭环:渲染候选轨迹,检查真实渲出的画面,再修正。 仲裁者是渲染结果,不是模型的自信。 最后,现成视频模型接手这份几何正确但画面粗糙的渲染,在需要更高保真时提升观感。
  用户意图 (文本)
        |
        v
  +----------------------------- STATE ACCESS -------------------+
  |  VLM 镜头规划 --> 渲染 --> 检查画面 --> 修正                 |
  |         ^                                    |               |
  |         +--------------- reflection ---------+               |
  +--------------------------------------------------------------+
        ^                                    |
        |  读                                v  渲染帧
        |                          [ 现成视频模型 ]
        |                                    |
        |                                    v  最终镜头
  ==================================================
  ||           持久 3D 世界状态                   ||
  ||  元素: 几何 / 外观 / 属性                    ||
  ||  相机: 位姿 / 镜头 / 轨迹                    ||
  ==================================================
        ^ 写 (只写 diff)             ^ 写 (初始化)
        |                            |
  +--------------+          +---------------------------+
  | STATE EVOLVE |          | STATE CONSTRUCTION        |
  | 意图 ->      |          | 2D 生成 -> 双视图抬升     |
  | 结构化迁移;  |          | 先验引导 + 冲突感知融合   |
  | 其余复用     |          +---------------------------+
  +--------------+
核喻:一座实体摄影棚,配一支常驻剧组。 这个比喻能承住整篇论文。
世界状态就是那座棚——舞台上真实道具摆在真实位置。 不是舞台的照片,是那些家具本身。
状态构建是木工组照着概念图搭景。 只给他们一张画,他们会为「这房间有多深」吵起来;给两张不同角度的画,他们就能三角化定位——但两张画在某些地方必然互相矛盾(一道门在两张图里不可能同时成立)。 好的工头遇到矛盾不会取中间值,他会决定「这面墙以哪张图为准」。 这套裁决程序,就是「冲突感知双视图初始化」。
状态演化是场务照着一张改动通知单干活。 单子上写着「换台灯、关掉现场光、演员横移到门口」。 没人去拆棚。 不在单子上的一切原地不动——这就是世界记忆,也是为什么两条不同的 take 之间椅子不会飘。
状态访问是摄影师和他的走位排练。 他先在纸上设计一个推轨(VLM 规划),然后真的走一遍——发现摇臂会撞到门框,而第 3 秒主角被柱子完全挡住。 他盯着监视器改。 没人信纸上的方案,监视器才是真理。 这就是渲染反馈式反思。
而视频模型是后期:在走位和机位都已锁定的素材上做调色、加颗粒、加氛围。 它让画面更好看。 它没有资格决定台灯在哪。
关键概念
-
持久工作状态(相对于无状态采样): 想想「一份 Excel」和「一张 Excel 的截图」的区别。 屏幕上看起来一样。 但你想让 B7 单元格变成 42,一个是两秒钟的编辑,另一个要重画整张图,还得祈祷其余 200 个格子跟原来一模一样。 今天所有的文生视频模型都是那张截图:所谓「世界」只以输出像素的形式存在,从来不是一个你能寻址的对象。 StateFlow 的全部赌注是:预演需要的是 Excel。 代价也随之而来——你现在必须定义 schema,而 schema 表达不了的东西,用户就问不出来。
-
冲突感知双视图初始化: 闭上一只眼去抓杯子,你会抓偏,因为单张图不决定深度。 两只眼睁开就很容易。 现在设想你的两只眼睛是两位没商量过的画家画的:杯柄在一张图里朝左,在另一张里朝右。 朴素的立体融合会把它们平均掉,你得到一个糊成一团的杯柄。 「冲突感知」就是让系统意识到「两个视图对同一表面给出了不兼容的断言」,然后裁决这个断言(选一个,或交给学到的先验),而不是混合。 实际收益恰好落在最容易崩的地方:遮挡边界,以及第二视图凭空补出来的去遮挡区域。
-
渲染反馈式反思: 你问语言模型「这条镜头路径好吗」,它会从语义上回答——「好,缓慢推近强化了角色的孤立感」。 它完全不知道这条路径穿过了一面墙,因为它从来没看。 这里的反思是:别问,渲。 执行轨迹,拿到真实帧,检查主体是否可见、几何是否相交、构图是否空掉,再据此修正方案。 这跟「把代码编译一下」而不是「问 LLM 这段代码能不能编译」是同一个动作:用一个便宜且精确的验证器,去闭合一个昂贵且模糊的规划器。
框架转变
  之前(主流方法):                    之后(本文方法):

   prompt v1                              prompt
      |                                     |
      v                                     v
  [ 大视频模型 ]                     [ 2D 生成 + 3D 抬升 ]
      |                                     |
      v                                     v
   视频 v1  ....... 丢弃              ==================
                                      ||   世界状态    ||<--+
   prompt v2 (+ "台灯挪一下")          ==================    |
      |                                  |          ^        |
      v                                  |  渲染    | 补丁   | diff
  [ 大视频模型 ]                         v          |        |
      |                             [ 画面帧 ]      +--------+
      v                                  |            改动单
   视频 v2  ... 全都飘了;               v
   台灯动了, 椅子和墙            [ 视频模型: 精修 ]
   也一起动了                           |
                                        v
   状态存在于  无处               镜头 v1, v2, v3 ...
                                  (保证是同一个世界)
一句话:从一次性合成到有状态的编辑循环,核心转变是**「世界」成为产物、视频退化为它的一个视图**——于是可控性不再是条件注入问题,而是数据结构问题。
专家评审
选题眼光: 真缺口,而且落点选得聪明。 诊断本身不新——「视频模型没有持久状态」是整个 world model 转向背后的公共抱怨,不少组也都在往 3D 或场景图中间层收敛。 好的地方在于它专门挑了预演:这个场景里用户真的不需要照片级真实,他们要的是同一个世界、重复二十次、每次小改,加上精确机位。 在这种工作流里,显式状态的成本立刻回本;而在通用视频生成里,绕一趟 3D 所付的保真度税就难以justify。 把论文放在这个位置,是明智的。
方法成熟度: 基本是在现成零件(2D 生成器、深度/几何先验、VLM 规划器、视频增强器)之上做聪明的管路工程——我这句话是褒贬各半。 架构层面的洞见(状态作为一等公民、编辑即迁移)是对的,作为系统也执行得不错。 但三个阶段级贡献,每一个都是针对已知失效模式打的合理补丁,而不是新的学习形式化:双视图冲突裁决对治单目抬升伪影,世界记忆对治重生成开销,反思对治 VLM 的无接地。 其中最干净、最可迁移的是反思闭环。 被忽略的、需要一个正面回答的简单基线:让 LLM 写 Blender/Unreal 脚本、配一个资产库,本身就已经提供持久状态、精确机位和便宜的 diff。 StateFlow 的优势必须全部来自「库里没有的东西」的生成式创建——那么诚实的对比就是「我们抬升出的世界 vs 检索+脚本化的资产」,我希望在正文里看到它。 另外摘要没有交代到底用什么表示(mesh?splat?混合?),而这个选择几乎决定了编辑表达力的上限。
实验诚意: 这是我最想追问的地方,同时我必须说明前提:摘要只承诺了「高质量 3D 世界,用于视频创作与类游戏原型」,没有点出任何指标,所以以下判断是暂定的。 两个结构性风险。 第一,基线不对称:一个带 VLM 规划器和视频精修的三阶段流水线,去比一个裸的文生视频模型,这不是受控对比;公平的同侪是其他「3D 场景生成 + 相机控制」流水线,以及上面那条脚本化 3D 基线。 第二,也更重要:论文的中心主张关于迭代,而迭代不是 FVD 或一次性用户偏好能测的。 真正承重的实验是多轮编辑协议——未触及元素是否逐位/度量上保持不变(可量化的身份保持)、单次编辑延迟 vs 全量重生成、连续十次编辑后累积的漂移。 如果评测只是单次质量指标加上精挑 demo 的用户研究,那这个 framing 是被断言的,不是被证明的。 我还想看反思闭环的失败案例:当不存在可行轨迹时会发生什么,它会不会终止。
写作功力: 摘要把大量预算花在立论修辞上(「我们认为缺失的是显式持久的工作状态」),留给机制的篇幅很少;三个阶段的命名是品牌,不是描述。 重写后最能让整篇升档的是状态表示与演化那一节:把真实 schema 给出来——一个元素是什么、带哪些字段、系统支持的迁移算子是哪一个闭集——读者立刻就能推理这套系统能做什么、不能做什么。 现在「结构化状态迁移」既可能是一套丰富的带类型算子代数,也可能是三种硬编码的编辑类型,而这两者的差距就是「框架」和「demo」的差距。 次一级的修补:明确说清什么是训练出来的、什么是 prompt 出来的;这条流水线很可能大部分是免训练编排,而这没什么不好承认的。
判决:弱接收 —— 问题选得对,系统结构完整,framing 确有价值;但贡献停在集成层面,而关于迭代的核心主张需要被测量,而不是被论证。
要点总结
能从这篇论文里「偷」走、并且跨域可用的东西:
-
用「执行」给「规划」做验证器。 只要你让 LLM/VLM 在一个存在便宜精确执行器的领域里出方案,就用执行器闭环,而不是再调一次模型。 这里是渲染相机路径;同构的场景有:编译器验证代码、物理步进验证机器人动作、查询规划器验证 SQL、布局引擎验证生成的 UI。 一般形式是:语义合理性和可执行可行性是两个不同的谓词,而其中只有一个能被便宜且精确地检查。 验证器预算就该花在那一个上面。
-
把 diff 当原语,而不是把成品当原语。 如果用户会迭代,接口就该接受「针对持久状态的改动描述」,而不是每次重新完整指定。 这听起来是常识,但几乎没有生成系统这么做,因为它逼你定义 schema。 只要平均会话超过三轮,这个代价就值得付。
-
裁决矛盾,而不是平均矛盾。 双视图那一课可以推广到任何多源融合:当两个来源对同一实体给出不兼容断言时,混合产生的伪影比「选错一个」更糟。 先检测冲突,再用先验仲裁。 这条对传感器融合、多标注者标签、检索结果集成同样适用。
-
把最贵的模型降级成精修环节。 结构(布局、身份、机位)在一个便宜可控的表示里定下来,重型生成模型只负责最后的外观。 这是处理「可控性 vs 保真度」权衡的一种可复用架构;顺带的好处是下个季度换掉那个重模型时,你的系统本体不用动。
我暂时不会照单全收的一点:为了显式抬升的 3D 世界去付几何伪影这笔税,在粗糙预演之外是否还划算。 这篇论文挑的领域里显然划算。 往外推,就得你自己担了。