Paper: 2605.02860 Authors: Mohamad Khajezade, Fatemeh H. Fard, Mohamed Sami Shehata Categories: cs.AI, cs.LG, cs.SE
The Gap
Cross-language code clone detection (X-CCD) asks: are these two code snippets in different languages semantically equivalent? Prior approaches fall into two camps. Traditional methods use hand-crafted features or learned embeddings but struggle with semantic equivalence across language boundaries. Recent LLM-based methods (GPT-4, DeepSeek) show promise but are black boxes—expensive, non-reproducible, privacy-concerning, and prone to formatting issues that break downstream parsing.
Compact open-source models (Phi3, Qwen-Coder) could solve the deployment problems, but they fail at reasoning-oriented tasks. When prompted to explain why two code snippets are clones, they either refuse to follow instructions or produce inconsistent output formats that can’t be reliably mapped to binary labels. The gap: we need the reasoning power of large models in the body of small models, with stable, parseable outputs.
Problem: X-CCD needs semantic reasoning across languages
   |
   v
Limitation: LLMs work but are impractical (cost/privacy/format)
             Compact models are practical but can't reason reliably
   |
   v
Assumption: Reasoning capability can be distilled from teacher to student
            Output instability can be fixed with structural constraints
   |
   v
Method: Distill DeepSeek-R1 reasoning into Phi3/Qwen + stabilization heads
   |
   v
Evidence: Improved reliability (response rate) + performance on distribution shift
   |
   v
Conclusion: Reasoning distillation + stabilization makes compact models viable for X-CCD
The Increment
One sentence: Before this paper, you chose between powerful-but-impractical LLMs or practical-but-unreliable compact models for X-CCD; after, you can distill reasoning into compact models and stabilize their outputs with classification heads.
Core Mechanism
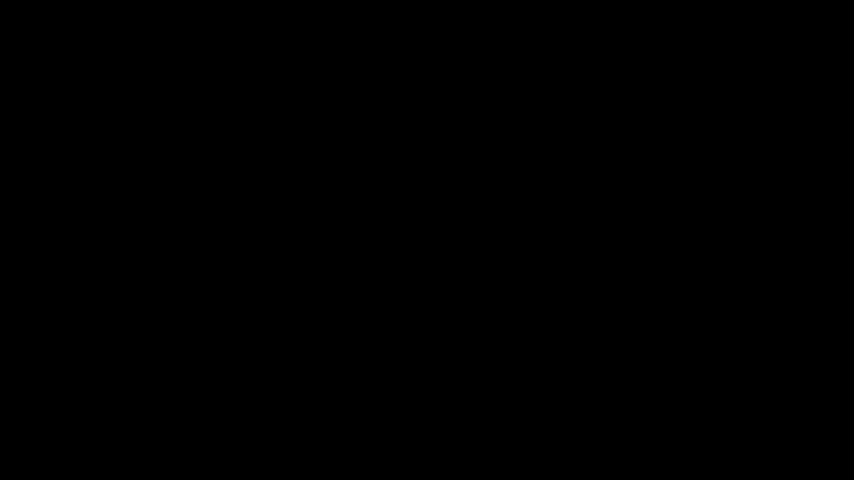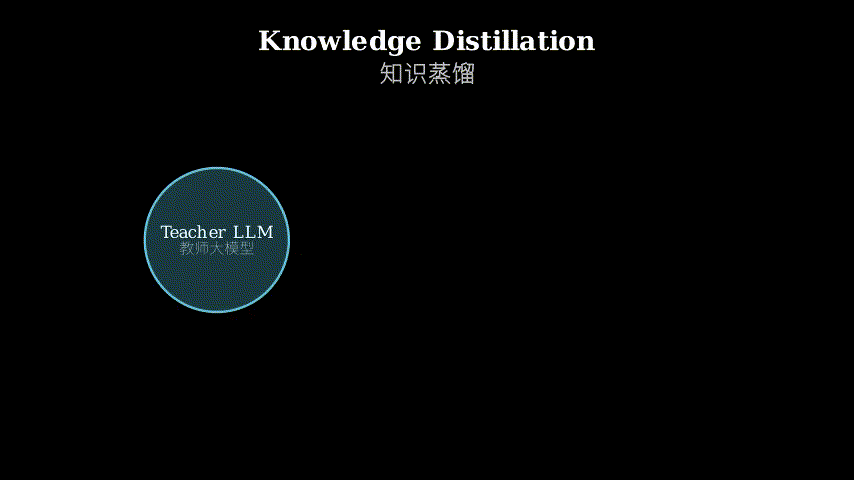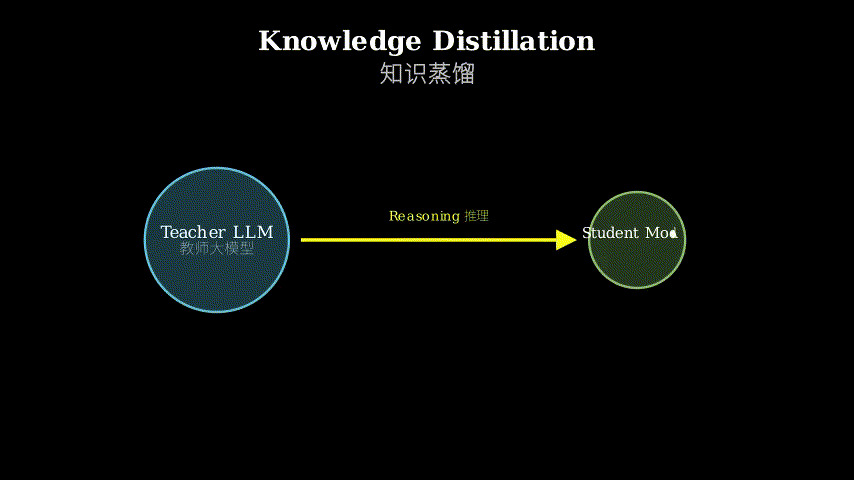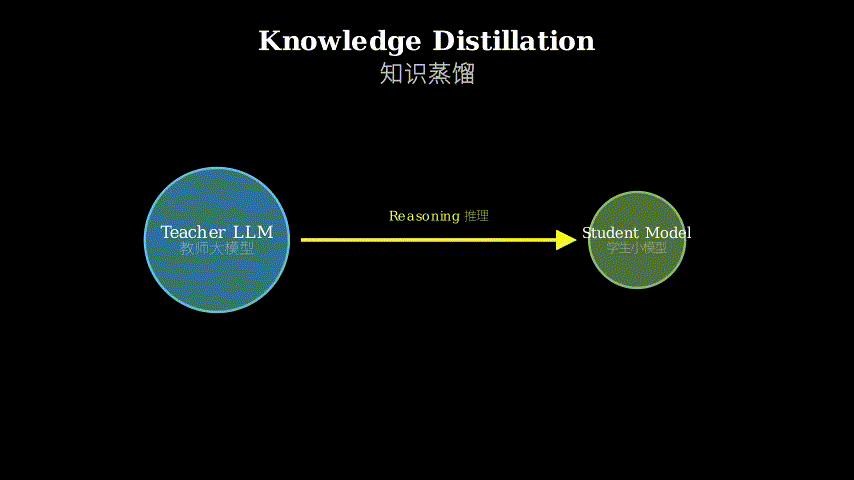
The method has three stages. First, synthetic data generation: use DeepSeek-R1 (the teacher) to generate reasoning traces for cross-language code pairs from Project CodeNet. The teacher explains *why two snippets are or aren’t clones, producing chain-of-thought rationales. Second, knowledge distillation: fine-tune compact student models (Phi3, Qwen-Coder) on these reasoning traces using LoRA adapters, teaching them to mimic the teacher’s reasoning process. Third, response stabilization: add structural constraints to ensure consistent outputs—forced conclusion prompting (append “Therefore, the answer is:” to force a decision), a binary classification head (map hidden states directly to clone/not-clone), or a contrastive classification head (learn to separate clone pairs from non-clone pairs in embedding space).
Teacher (DeepSeek-R1)
   |
   | generates reasoning traces
   v
Synthetic Dataset: <code_pair, reasoning, label>
   |
   | fine-tune with LoRA
   v
Student (Phi3/Qwen) + Reasoning Capability
   |
   | add stabilization layer
   v
Output: Reliable binary prediction
   ^
   |
   +-- Forced conclusion prompt
   +-- Binary classification head
   +-- Contrastive classification head
Think of this like training a junior engineer. The senior engineer (teacher) doesn’t just label code pairs as “clone” or “not clone”—they walk through the logic: “These two functions both implement quicksort, but one uses recursion and the other uses a stack. The algorithmic structure is identical, so they’re clones.” The junior (student) learns by studying these explanations. But juniors sometimes freeze up or give vague answers, so you add scaffolding: force them to end every analysis with “Therefore, clone or not clone” (forced conclusion), or give them a checklist that maps directly to a decision (classification head). The scaffolding doesn’t replace understanding—it channels it into a consistent format.
Key Concepts
-
Knowledge Distillation for Reasoning: Traditional distillation transfers a model’s output probabilities (soft labels) to a smaller model. Reasoning distillation transfers the *process—the chain of thought. Imagine teaching someone to solve math problems. You could just show them answers (soft labels), but they’d struggle with new problems. Instead, you show them worked examples: “First identify the variables, then set up the equation, then solve step-by-step.” They learn the method, not just the answers. Here, DeepSeek-R1 generates reasoning traces (“These functions differ in syntax but share control flow structure…”), and the student learns to produce similar reasoning before making a prediction.
-
Response Stabilization: Compact models often produce outputs that can’t be parsed into binary labels—they might refuse to answer, give ambiguous text, or format inconsistently. Stabilization methods constrain the output space. Forced conclusion prompting is like adding “Circle your final answer” to an exam—it doesn’t help if the student doesn’t know the material, but it prevents them from leaving the answer blank or burying it in prose. Classification heads bypass text generation entirely: the model’s internal representation (hidden states) is mapped directly to a binary decision via a learned linear layer. It’s faster and more reliable because there’s no text parsing step to fail.
-
Distribution Shift in X-CCD: The model is trained on certain language pairs (e.g., Python-Java) but tested on others (e.g., Rust-Ruby). This tests whether the model learned general semantic reasoning or just memorized surface patterns. If you train a model to recognize clones in Python and Java, does it understand “semantic equivalence” or just “Python loops that look like Java loops”? Testing on Rust-Ruby reveals whether the reasoning generalizes. The paper shows distilled models handle this shift better, suggesting they learned transferable reasoning rather than language-specific heuristics.
Framework Shift
Before (mainstream approach):        After (this paper):

LLM (black box)                      Teacher LLM
   |                                    |
   | prompt with code pair              | generate reasoning traces
   v                                    v
"Are these clones?"                  Synthetic dataset
   |                                    |
   | parse unreliable text              | distill into student
   v                                    v
Binary label (maybe)                 Student model + reasoning
                                        |
                                        | stabilization head
                                        v
                                     Reliable binary label

OR

Compact model                        (Same as above, but student
   |                                  is compact from the start)
   | prompt with code pair
   v
Inconsistent/no response
From treating models as opaque predictors to explicitly teaching them reasoning processes, then constraining their outputs structurally rather than hoping text generation succeeds.
Expert Assessment
Problem choice: Real gap. X-CCD is a genuine pain point in software engineering (code reuse detection, plagiarism, refactoring analysis), and the LLM deployment issues (cost, privacy, reproducibility) are not manufactured concerns—they’re blockers for production use. The problem sits at the intersection of program analysis and LLM practicality, which is timely.
Method maturity: Solid engineering rather than deep novelty. Knowledge distillation and LoRA fine-tuning are established techniques; the contribution is applying them to reasoning transfer and adding stabilization mechanisms. The classification head idea is straightforward but effective—it’s the kind of “why didn’t we just do this earlier” solution that works. No simpler approach is being overlooked; the paper systematically explores the design space (generation vs classification, different head architectures).
Experimental integrity: Baselines are fair (comparing against the teacher model and vanilla students). The use of Project CodeNet is appropriate—it’s a standard benchmark with verified cross-language equivalences. The distribution shift experiments (training on one language pair, testing on another) are the strongest evidence that reasoning was actually transferred, not just surface patterns. One weakness: no comparison against traditional X-CCD methods (AST-based, embedding-based), so we don’t know if distilled models beat non-LLM approaches. The paper focuses on making LLMs practical, not proving they’re necessary.
Writing quality: Clear structure, but the related work section is thin—doesn’t position the work against recent X-CCD literature beyond LLMs. The ablation studies (Table 3) are well-designed, showing the contribution of each component. The response rate metric is crucial and often ignored in LLM papers—kudos for measuring it. The paper could be elevated by adding a failure analysis: when do distilled models still fail, and why?
Verdict: Weak accept — Solid engineering contribution that makes LLMs practical for X-CCD, with good experimental design, but limited novelty in the core techniques.
Takeaways
Reasoning distillation is a deployment strategy: If you have a task where LLMs work but are impractical, generate synthetic reasoning traces from a strong teacher, then fine-tune a compact student. This transfers capability without ongoing API costs or privacy leaks. The key is generating *reasoning, not just labels—the student learns the process.
Stabilization heads are underused: When LLM text generation is unreliable, bypass it. Add a classification head that maps hidden states directly to structured outputs. This is faster (no text generation) and more reliable (no parsing failures). Applicable beyond X-CCD—any task where you need binary/categorical decisions from LLMs.
Test on distribution shift, not just in-distribution: If your model is supposed to learn a general concept (semantic equivalence, sentiment, causality), test it on data that shares the concept but differs in surface features. If performance collapses, you trained a pattern matcher, not a reasoner. The Rust-Ruby experiments here are a model for this kind of evaluation.
论文: 2605.02860 作者: Mohamad Khajezade, Fatemeh H. Fard, Mohamed Sami Shehata 分类: cs.AI, cs.LG, cs.SE
缺口
跨语言代码克隆检测(X-CCD)要回答的问题是:两段不同语言的代码在语义上是否等价?
此前的方法分两派。
传统方法使用手工特征或学习到的嵌入,但在跨语言边界的语义等价性上表现不佳。
最近的大语言模型方法(GPT-4、DeepSeek)显示出潜力,但它们是黑盒——成本高、不可复现、有隐私顾虑,且容易产生格式问题导致下游解析失败。
紧凑的开源模型(Phi3、Qwen-Coder)可以解决部署问题,但它们在需要推理的任务上失败了。
当提示它们解释为什么两段代码是克隆时,它们要么拒绝遵循指令,要么产生不一致的输出格式,无法可靠地映射到二元标签。
缺口在于:我们需要在小模型的身体里装入大模型的推理能力,并且输出要稳定、可解析。
问题:X-CCD 需要跨语言的语义推理
   |
   v
局限:大语言模型有效但不实用(成本/隐私/格式)
      紧凑模型实用但推理不可靠
   |
   v
假设:推理能力可以从教师蒸馏到学生
      输出不稳定可以用结构约束修复
   |
   v
方法:将 DeepSeek-R1 的推理蒸馏到 Phi3/Qwen + 稳定化头
   |
   v
证据:可靠性提升(响应率)+ 分布偏移下的性能提升
   |
   v
结论:推理蒸馏 + 稳定化使紧凑模型在 X-CCD 上可行
增量
一句话: 这篇论文之前,你要在强大但不实用的大语言模型和实用但不可靠的紧凑模型之间选择;
之后,你可以将推理蒸馏到紧凑模型中,并用分类头稳定它们的输出。
核心机制
方法分三个阶段。
第一,合成数据生成:使用 DeepSeek-R1(教师)为 Project CodeNet 的跨语言代码对生成推理轨迹。
教师解释为什么两段代码是或不是克隆,产生思维链式的理由。
第二,知识蒸馏:在这些推理轨迹上用 LoRA 适配器微调紧凑的学生模型(Phi3、Qwen-Coder),教它们模仿教师的推理过程。
第三,响应稳定化:添加结构约束以确保输出一致——强制结论提示(在末尾追加”因此,答案是:“以强制决策)、二元分类头(将隐藏状态直接映射到克隆/非克隆)、或对比分类头(学习在嵌入空间中分离克隆对和非克隆对)。
教师(DeepSeek-R1)
   |
   | 生成推理轨迹
   v
合成数据集:<代码对, 推理, 标签>
   |
   | 用 LoRA 微调
   v
学生(Phi3/Qwen)+ 推理能力
   |
   | 添加稳定化层
   v
输出:可靠的二元预测
   ^
   |
   +-- 强制结论提示
   +-- 二元分类头
   +-- 对比分类头
把这想象成培训初级工程师。
资深工程师(教师)不只是给代码对打上”克隆”或”非克隆”的标签——他们会走一遍逻辑:“这两个函数都实现了快速排序,但一个用递归,另一个用栈。
算法结构是相同的,所以它们是克隆。
“初级工程师(学生)通过研究这些解释来学习。
但初级工程师有时会卡住或给出模糊的答案,所以你添加脚手架:强制他们在每次分析结束时说”因此,是克隆或不是克隆”(强制结论),或者给他们一个直接映射到决策的检查清单(分类头)。
脚手架不替代理解——它把理解引导到一致的格式中。
关键概念
- 推理的知识蒸馏:传统蒸馏将模型的输出概率(软标签)转移到更小的模型。
推理蒸馏转移的是过程——思维链。
想象教某人解数学题。
你可以只展示答案(软标签),但他们在新问题上会挣扎。
相反,你展示解题过程:“首先识别变量,然后建立方程,然后逐步求解。
“他们学到的是方法,而不只是答案。
这里,DeepSeek-R1 生成推理轨迹(“这些函数在语法上不同但共享控制流结构…”),学生学习在做出预测前产生类似的推理。
- 响应稳定化:紧凑模型经常产生无法解析为二元标签的输出——它们可能拒绝回答、给出模糊文本、或格式不一致。
稳定化方法约束输出空间。
强制结论提示就像在考试中加上”圈出你的最终答案”——如果学生不懂材料它帮不上忙,但它防止他们留空或把答案埋在散文里。
分类头完全绕过文本生成:模型的内部表示(隐藏状态)通过学习到的线性层直接映射到二元决策。
它更快更可靠,因为没有可能失败的文本解析步骤。
- X-CCD 中的分布偏移:模型在某些语言对上训练(如 Python-Java)但在其他语言对上测试(如 Rust-Ruby)。
这测试模型是学到了通用的语义推理还是只记住了表面模式。
如果你训练一个模型识别 Python 和 Java 中的克隆,它理解的是”语义等价”还是只是”看起来像 Java 循环的 Python 循环”?
在 Rust-Ruby 上测试揭示推理是否泛化。
论文显示蒸馏模型更好地处理这种偏移,表明它们学到了可迁移的推理而非特定语言的启发式。
框架转变
之前(主流方法):                之后(本文方法):

大语言模型(黑盒)                教师大语言模型
   |                                |
   | 用代码对提示                    | 生成推理轨迹
   v                                v
"这些是克隆吗?"                   合成数据集
   |                                |
   | 解析不可靠的文本                | 蒸馏到学生
   v                                v
二元标签(也许)                   学生模型 + 推理
                                     |
                                     | 稳定化头
                                     v
                                  可靠的二元标签

或

紧凑模型                          (同上,但学生
   |                               从一开始就是紧凑的)
   | 用代码对提示
   v
不一致/无响应
从把模型当作不透明的预测器,到显式地教它们推理过程,然后用结构约束它们的输出,而不是寄希望于文本生成成功。
专家评审
选题眼光:真实的缺口。
X-CCD 是软件工程中的真实痛点(代码复用检测、抄袭、重构分析),而大语言模型的部署问题(成本、隐私、可复现性)不是人造的顾虑——它们是生产使用的阻碍。
问题位于程序分析和大语言模型实用性的交叉点,很及时。
方法成熟度:扎实的工程而非深刻的新颖性。
知识蒸馏和 LoRA 微调是成熟的技术;
贡献在于将它们应用于推理转移并添加稳定化机制。
分类头的想法很直接但有效——是那种”我们为什么不早点这么做”的解决方案。
没有被忽略的更简单方法;
论文系统地探索了设计空间(生成 vs 分类,不同的头架构)。
实验诚意:基线公平(与教师模型和原始学生比较)。
使用 Project CodeNet 是合适的——它是有验证过的跨语言等价性的标准基准。
分布偏移实验(在一个语言对上训练,在另一个上测试)是推理确实被转移而非只是表面模式的最强证据。
一个弱点:没有与传统 X-CCD 方法(基于 AST、基于嵌入)比较,所以我们不知道蒸馏模型是否击败了非大语言模型方法。
论文专注于让大语言模型实用,而非证明它们是必需的。
写作功力:结构清晰,但相关工作部分单薄——没有将工作定位在除大语言模型之外的最近 X-CCD 文献中。
消融研究(表3)设计良好,显示了每个组件的贡献。
响应率指标至关重要且在大语言模型论文中经常被忽略——值得称赞的是测量了它。
论文可以通过添加失败分析来提升:蒸馏模型何时仍然失败,为什么?
判决:弱接收 — 扎实的工程贡献,使大语言模型在 X-CCD 上实用,实验设计良好,但核心技术的新颖性有限。
要点总结
推理蒸馏是一种部署策略:如果你有一个大语言模型有效但不实用的任务,从强教师生成合成推理轨迹,然后微调紧凑学生。
这在没有持续 API 成本或隐私泄露的情况下转移能力。
关键是生成推理,而不只是标签——学生学到的是过程。
稳定化头被低估了:当大语言模型文本生成不可靠时,绕过它。
添加一个将隐藏状态直接映射到结构化输出的分类头。
这更快(无文本生成)且更可靠(无解析失败)。
适用于 X-CCD 之外——任何需要从大语言模型获得二元/分类决策的任务。
在分布偏移上测试,而不只是分布内:如果你的模型应该学习一个通用概念(语义等价、情感、因果关系),在共享概念但表面特征不同的数据上测试它。
如果性能崩溃,你训练的是模式匹配器,而非推理器。
这里的 Rust-Ruby 实验是这种评估的范例。