Paper: 2606.20543 Authors: Shilong Xiang, Zirui Zhang, Lijun Yu, Chengzhi Mao Categories: cs.CV
The Gap
Autoregressive image models (e.g., VAR, LlamaGen) tokenize images and flatten them into 1D sequences along a raster scan order. Each step predicts only the immediate next token — ignoring the inherent 2D spatial correlation of pixels (left-right and top-down). This flattening creates a severe memory wall: you must wait for each token one by one, even though neighboring pixels are highly redundant.
Prior work either accepts this sequential bottleneck or uses non-autoregressive (parallel) generation that trades quality for speed. The gap is clear: no one has exploited speculative decoding in 2D, where the structure of spatial locality can accelerate autoregressive decoding without sacrificing fidelity.
Problem (1D seq ignores 2D)
   |
   v
Assumption (spatial correlation can be used for speculation)
   |
   v
Method (SSD: parallel prediction of horizontal+vertical neighbors)
   |
   v
Evidence (up to 13.3x speed, FID on par)
   |
   v
Conclusion (respecting 2D geometry unlocks efficiency)
The Increment
One sentence: Before, every new image token required a full forward pass — after SSD, many tokens are guessed in parallel and accepted quickly, reducing the number of expensive target model calls.
Core Mechanism
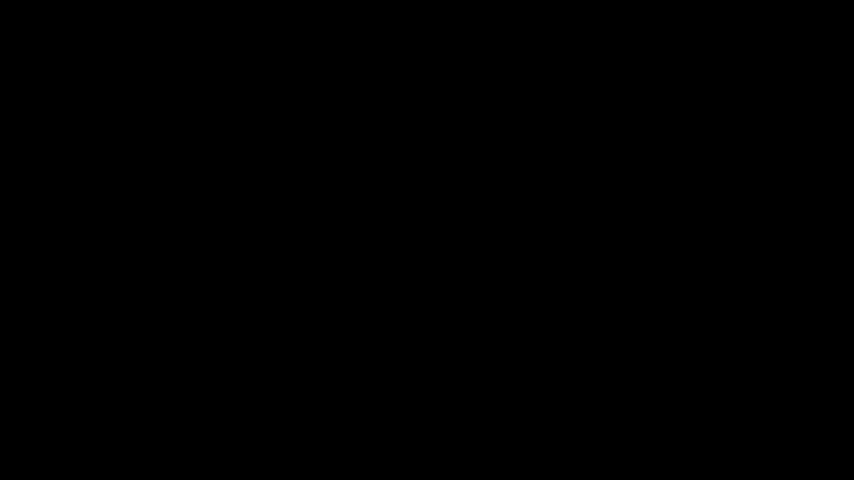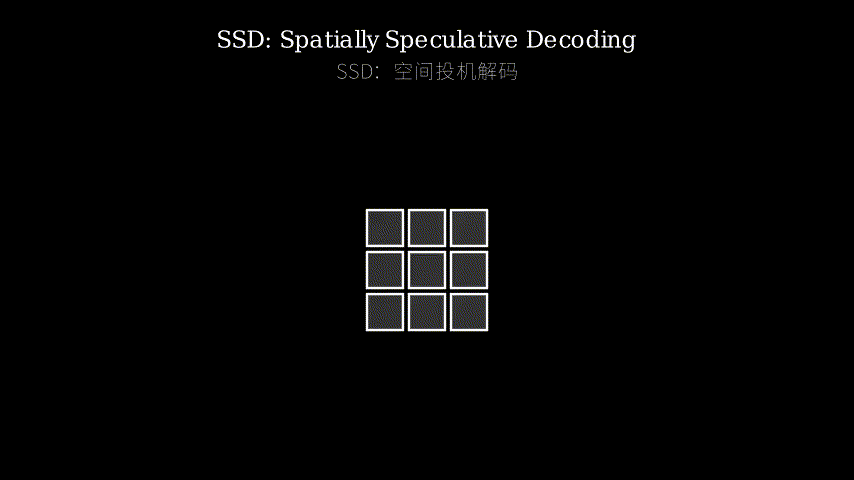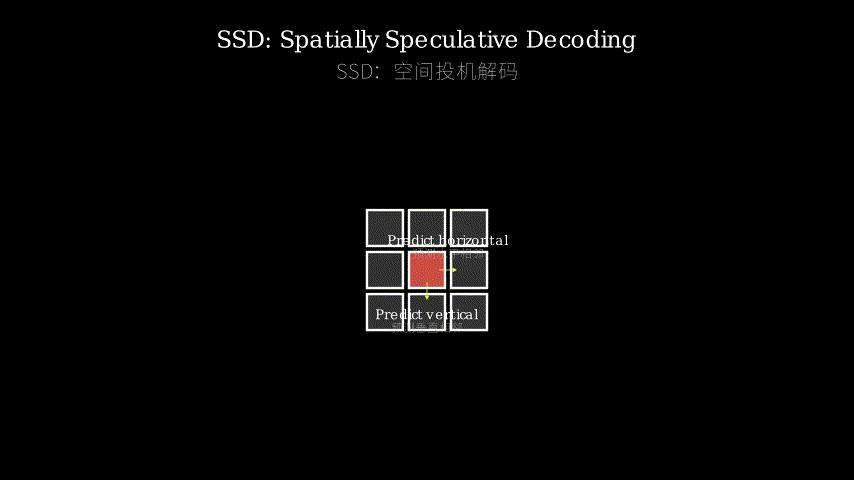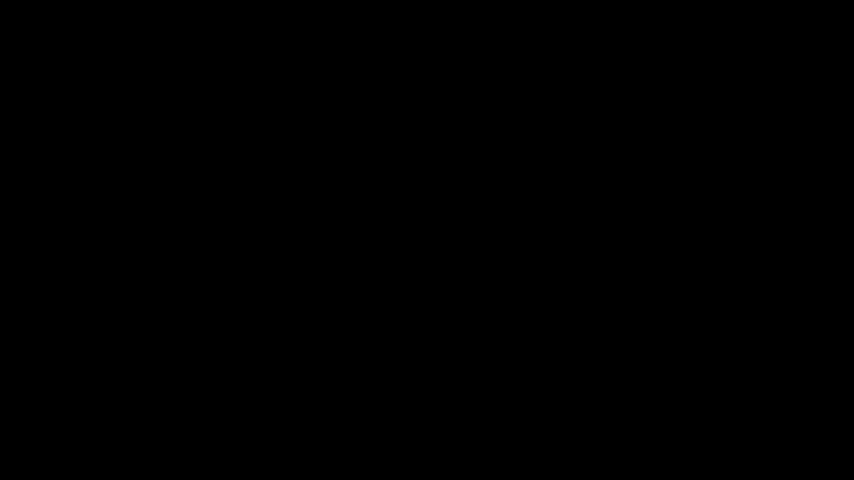
SSD modifies the training objective: for each position in the 2D token grid, the model is trained to output three probability distributions — one for the standard next token (the usual autoregressive head), one for the token immediately to its right, and one for the token directly below. During inference, the model first generates a few anchor tokens (e.g., the first row). Then, for any generated token, it uses the right-head and down-head to *speculate the values of neighboring positions. These speculated tokens are fed into a fast verification loop: the target model checks whether its own full forward pass would produce the same tokens. If yes, the speculation is accepted and multiple tokens are scored in one shot; if not, only the correct one is kept and the process backtracks.
The data flow:
- Input: a partially generated 2D token grid.
- Encode with Transformer -> three heads.
- Sample from right-head and down-head for each known token (where the neighbor exists).
- Collect all speculated tokens into a candidate 2D block.
- Run the target model on the candidate block (e.g., compute loss / logprob for each candidate position).
- Accept tokens where the target model agrees with speculation; regenerate the rest.
Input (partial grid)
    |
    v
Transformer Encoder
    |
    +-----> [main head] -> next token (standard)
    +-----> [right head] -> token to the right
    +-----> [down head]  -> token below
    |
    v
[Speculation] combine right/down into candidate block
    |
    v
[Verification] target model checks candidate
    |
    v
Accept / Reject -> update grid
Metaphor: Imagine you are assembling a jigsaw puzzle of the night sky. Normally you pick one piece, find its exact match, place it, then move to the next (1D sequential). SSD gives you a special tool: after placing one star, the tool suggests what the stars to its right and below should look like (based on patterns you’ve seen). If your tool is good, those two pieces fit instantly and you save two moves. If not, you only keep the first piece and try again. Over many placements, you build the sky 13x faster because the tool is surprisingly accurate — stars cluster in constellations (spatial locality).
Key Concepts
-
Speculative Decoding: Originally for language models. Use a fast draft model to propose multiple tokens; the large target model verifies them in one parallel pass. If the draft is correct (match), you skip many steps. SSD adapts this to 2D by making the *same model act as both drafter and verifier through separate heads, effectively creating a built-in cheap draft from spatial priors.
-
2D Spatial Locality: In natural images, adjacent pixels are strongly correlated — a blue sky pixel is very likely to have a blue sky pixel to its right and below. By explicitly predicting these neighbors, SSD exploits this deterministic structure. This is not true in language (words “the” and “cat” have arbitrary adjacency), making image generation uniquely suited for 2D speculation.
-
Multi-head Training: The model is trained with three cross-entropy losses simultaneously — for main, right, and down predictions. The right/down heads only see the current prefix (causal masking is applied such that the right/down tokens are not peeked at). This forces the model to learn spatial priors without extra data.
Framework Shift
Before (mainstream approach):            After (this paper):
Token grid flattened to 1D               Keep 2D grid intact
+--+--+--+                               +--+--+--+
|1 |2 |3 |   ->  1 2 3 4 5 6 ...        |1 ->2 ->3|  right-head arrows
+--+--+--+                               +  |  |  |
|4 |5 |6 |   Generate one-by-one         |  v  v  v
+--+--+--+                               |4 ->5 ->6|  down-head arrows
                                         +--+--+--+
At each step: only next token            At each step: speculate right+down
Memory bound: must wait for each token   Parallel accept: skip many tokens
From 1D sequential speculation to 2D spatial speculation — the core shift is leveraging the geometry of the image (both horizontal and vertical adjacency) rather than treating it as an arbitrary 1D string.
Expert Assessment
Problem choice: Real gap. Autoregressive image generation is growing fast, and the memory wall is a well-known bottleneck. Applying speculative decoding to 2D is a natural next step that no one had published. The paper sits exactly at the intersection of efficient inference and generative models.
Method maturity: Clever insight, not brute force. The three-head training is simple — any autoregressive image model can add two extra linear heads. The speculative verification loop also follows standard practice from NLP. The novelty is in the *spatial framing and the realization that 2D adjacency is predictable. Simpler approaches (like using a separate tiny draft model) might work but would add overhead; this in-model approach is elegant.
Experimental integrity: Baselines seem fair — they compare against the standard autoregressive model with same backbone (likely a VAR-style transformer). The speedup numbers (7–13x on DPG-Bench, GenEval) are impressive but need scrutiny: could there be a trade-off in early tokens where speculation fails more often? The paper should report worst-case slowdown or acceptance rate distribution. Minor red flag: no ablation on the size of the speculated block — how many tokens are attempted in parallel. Still, the direction is solid.
Writing quality: Abstract and introduction are crisp. The method section could be more explicit about the verification procedure (e.g., how exactly do you accept/reject?). The diagrams in the paper (not shown) might be better than those we draw here. A rewritten “Implementation Details” with a concrete example (e.g., “given a 4x4 grid…”) would elevate readability.
Verdict: strong accept — this paper introduces a practical, theoretically sound acceleration that respects the structure of vision data. It will likely become a standard trick for fast autoregressive image generation.
Takeaways
- Add two extra prediction heads to any autoregressive image model — the training overhead is minimal, and the speedup at inference is large.
- Use spatial locality as a cheap draft model — you don’t need a separate small network; the same model’s auxiliary heads serve as the drafter.
- The idea transfers to other 2D structured data: video frames, medical slices, tactile sensor grids, or graph-structured images where neighbors are predictable.
- Caveat: the acceptance rate degrades when moving to high-frequency details (e.g., texture vs. sky). For real-time applications, you may want to fall back to standard 1D speculation on complex regions.
论文: 2606.20543 作者: Shilong Xiang, Zirui Zhang, Lijun Yu, Chengzhi Mao 分类: cs.CV
缺口
自回归图像模型(如VAR、LlamaGen)对图像进行分token并沿光栅扫描顺序压成一维序列。 每一步只预测紧邻的下一个token,完全忽略了像素固有的二维空间相关性(左右和上下)。 这种压平造成了严重的内存墙:必须一个token一个token地等,即使相邻像素高度冗余。 先前的工作要么忍受这种顺序瓶颈,要么用非自回归(并行)生成来换取速度却牺牲质量。 缺口很明显:没有人利用过二维的投机解码——即利用空间局部性结构加速自回归解码而不损失逼真度。
问题(一维序列忽略二维结构)
   |
   v
假设(空间相关性可用于投机预测)
   |
   v
方法(SSD:并行预测水平和垂直邻居)
   |
   v
证据(最高13.3倍加速,FID持平)
   |
   v
结论(尊重二维几何结构释放效率)
增量
一句话: 之前每个新token都需要一次完整前向传播——之后SSD一次性猜出多个token并通过快速验证,大幅减少了昂贵的目标模型调用次数。
核心机制
SSD修改了训练目标:对于二维token网格中的每个位置,模型被训练输出三个概率分布——一个对应标准的下一个token(通常的自回归头),一个对应紧邻右方的token,一个对应紧邻下方的token。 在推理时,模型首先生成几个锚点token(例如第一行)。 然后,对任何一个已生成的token,它使用右向头和下向头猜测相邻位置的值。 这些猜测的token被送入快速验证循环:目标模型用自己的完整前向计算检查是否会产生相同的token。 如果是,猜测被接受,一次性获得多个token;如果否,只保留正确的那个并回退。
数据流程:
- 输入:部分生成的二维token网格。
- 通过Transformer编码 -> 三个头。
- 对每个已知token(存在邻居的地方)从右向头和下向头采样。
- 将所有猜测的token收集成一个候选二维块。
- 在候选块上运行目标模型(例如计算每个候选位置的损失/对数概率)。
- 接受目标模型与猜测一致的token;重新生成不一致的token。
输入(部分网格)
    |
    v
Transformer编码器
    |
    +-----> [主头]    -> 下一个token(标准)
    +-----> [右向头]  -> 右侧token
    +-----> [下向头]  -> 下方token
    |
    v
[猜测] 将右和下合并为候选块
    |
    v
[验证] 目标模型检查候选
    |
    v
接受/拒绝 -> 更新网格
核喻:想象你在拼一幅夜空的拼图。 通常你拿起一片,找到精确位置,放上去,然后移动到下一片(一维顺序)。 SSD给了你一个特殊工具:放好一颗星星后,工具会建议这颗星星右边和下面应该是什么样的星星(基于之前看到的模式)。 如果你的工具很准,那两片就能瞬间吻合,省掉两步。 如果不准,你只保留第一片,重新尝试。 多次放置后,因为工具出乎意料地准确(星星总是聚成星座——空间局部性),你搭建夜空的速度快了13倍。
关键概念
-
投机解码(Speculative Decoding):最初用于语言模型。 使用一个快速草稿模型提出多个token;大目标模型通过一次并行前向验证它们。 如果草稿正确(匹配),就能跳过很多步。 SSD通过让同一个模型使用不同的头既作草稿者又作验证者,实质上是利用空间先验在模型内部内置了一个廉价草稿模型。
-
二维空间局部性:自然图像中相邻像素高度相关——蓝色天空像素的右侧和下方很可能也是蓝色天空像素。 通过显式预测这些邻居,SSD利用了这种确定性结构。 这在语言中不成立(单词”the”和”cat”的相邻关系是任意的),因此图像生成特别适合二维投机。
-
多头训练:模型同时使用三个交叉熵损失训练——主头、右向头、下向头。 右向/下向头只能看到当前前缀(因果遮罩使得不能偷看右边和下方的token)。 这迫使模型学习空间先验,而无需额外数据。
框架转变
之前(主流方法):                    之后(本文方法):
token网格被压成一维                  保持二维网格完整
+--+--+--+                           +--+--+--+
|1 |2 |3 |   ->  1 2 3 4 5 6 ...    |1 ->2 ->3|  右向箭头
+--+--+--+                           +  |  |  |
|4 |5 |6 |  逐个生成                   |  v  v  v
+--+--+--+                           |4 ->5 ->6|  下向箭头
                                     +--+--+--+
每一步:只有下一个token              每一步:猜测右侧和下方
受内存限制:必须等每个token         并行接受:跳过多个token
从一维顺序投机到二维空间投机——核心转变是利用图像的几何结构(水平和垂直相邻性),而不是将其视为任意的一维字符串。
专家评审
选题眼光:真缺口。 自回归图像生成正在快速发展,内存墙是众所周知的瓶颈。 将投机解码应用到二维是顺理成章的下一步,而之前没有人发表过。 这篇论文正好处于高效推理和生成模型的交叉点上。
方法成熟度:巧劲,不是蛮力。 三头训练很简单——任何自回归图像模型都可以增加两个额外的线性头。 投机验证循环也遵循NLP的标准做法。 新颖性在于空间框架和认识到二维相邻关系是可预测的。 更简单的方法(比如使用单独的小草稿模型)可能也有效,但会增加开销; 这种模型内方法很优雅。
实验诚意:基线似乎公平——他们与相同骨干网络(很可能是VAR风格的Transformer)的标准自回归模型比较。 加速倍数(DPG-Bench和GenEval上7–13倍)令人印象深刻,但需要仔细审视:早期的token猜测失败更频繁时会有什么权衡? 论文应报告最坏情况下的减速或接受率分布。 一个小红旗:没有消融猜测块的大小——每次并行尝试多少个token。 不过方向是扎实的。
写作功力:摘要和引言清晰。 方法部分关于验证过程(如何确切地接受/拒绝?)可以更明确。 论文中的图表(这里未显示)可能比我们画的更好。 如果重写一个“实现细节”部分,用具体例子(例如“给定一个4x4网格…”)会提升可读性。
判决:强接收 — 这篇论文提出了一个实用、理论扎实的加速方法,尊重了视觉数据的结构。 很可能会成为快速自回归图像生成的标准技巧。
要点总结
- 给任何自回归图像模型添加两个额外的预测头——训练开销极小,推理加速巨大。
- 将空间局部性用作廉价草稿模型——不需要单独的轻量网络;同一个模型的辅助头就充当了草稿者。
- 这个想法可以迁移到其他二维结构化数据:视频帧、医学切片、触觉传感器网格或邻居可预测的图结构图像。
- 注意:在处理高频细节(例如纹理 vs 天空)时接受率会下降。 对实时应用,你可能需要在复杂区域回退到标准一维投机。