Paper: 2606.32033 Authors: Or Hirschorn, Aaron Olender, Eli Alshan, Ianir Ideses, Lior Fritz, Sagie Benaim Categories: cs.CV
The Gap
Existing 360° panorama generation falls into two camps, both with real costs:
- Fine-tuning approaches: Train specialized models on panoramic datasets. Problem: panoramic data is scarce and expensive to collect, and the resulting models lose the creative generality of their foundation models.
- Optimization approaches: At inference time, iteratively optimize outputs to satisfy spherical constraints (like stitching seams or enforcing periodicity). Problem: this adds minutes per image, making real-time or video applications impractical.
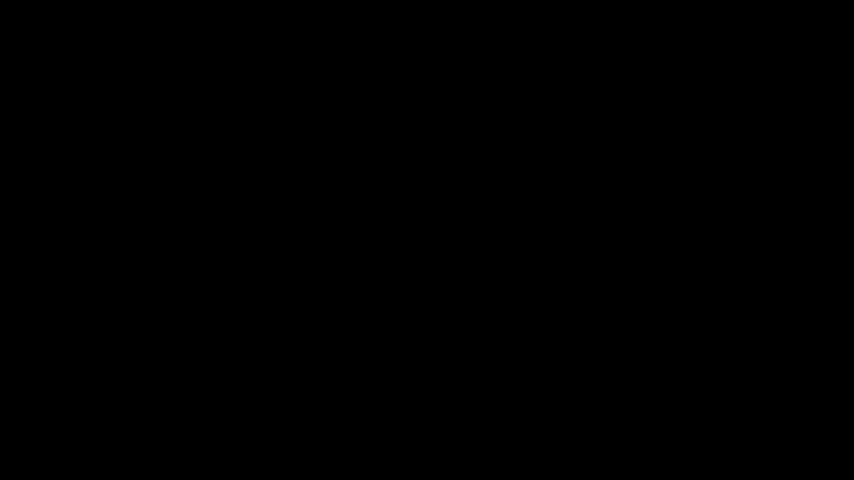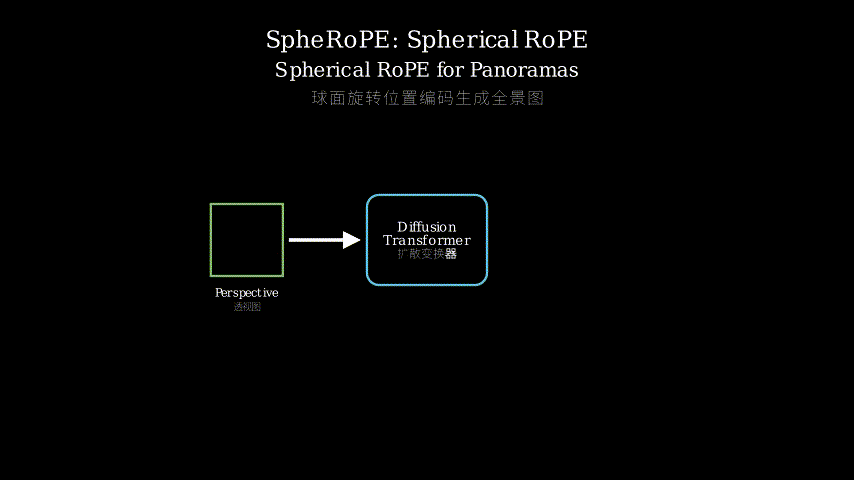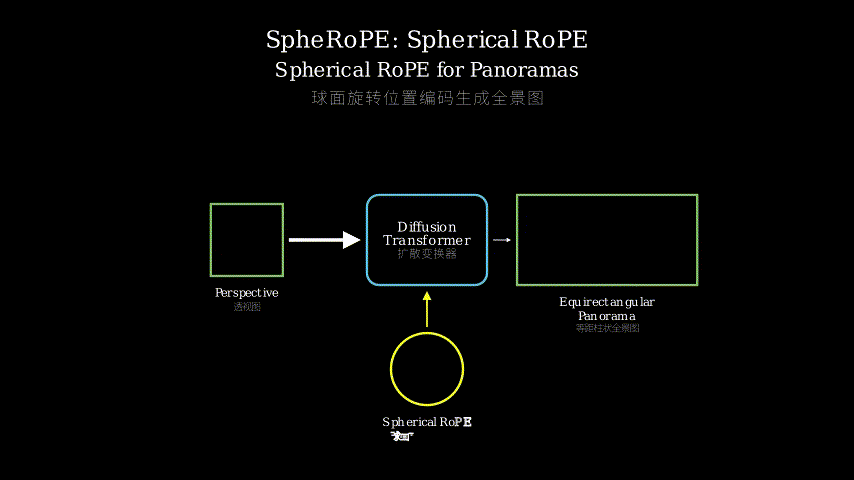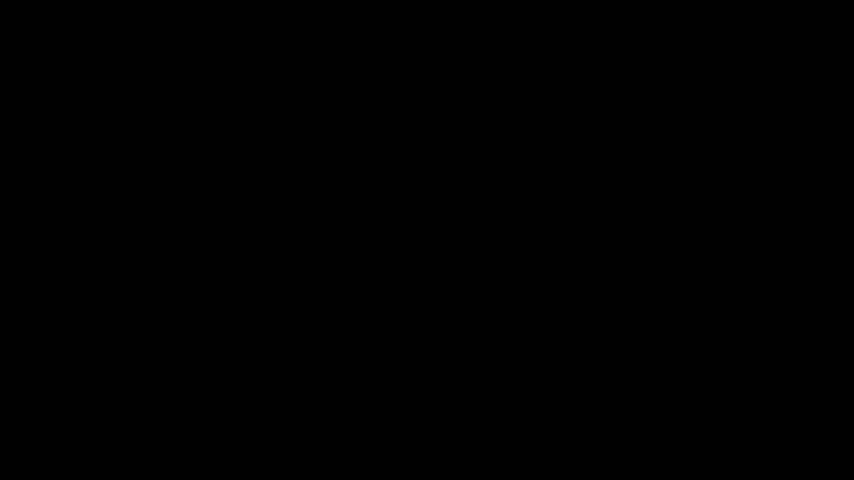
The paper identifies a third path that neither camp explored: what if pre-trained diffusion transformers already contain latent spherical knowledge from massive training data, but their positional encoding (RoPE) sabotages it? Standard RoPE treats images as flat grids—fundamentally incompatible with the topology of equirectangular projection where the left edge must wrap to the right and the top compresses toward poles.
Problem                       Assumption                    Method
+-----------------------+     +-----------------------+     +-----------------------+
| 360 panorama gen needs|     | Large-scale diffusion |     | Replace flat RoPE     |
| spherical consistency |     | models have latent    |     | with Spherical RoPE   |
| (ERP topology)        |     | panoramic priors      |     | (3D XYZ + periodicity)|
+-----------+-----------+     +-----------+-----------+     +-----------+-----------+
            |                             |                             |
            |   Fine-tune: costly         |   Optimization: slow        |
            |   Fine-tune: loses breadth  |   Optimization: not real-time|
            v                             v                             v
+-----------+-----------------------------+-----------------------------+-----------+
|                                           Surviving constraint: inject spherical |
|                                           geometry at inference, zero training   |
+---------------------------------------------------------------------------------+
                                                      |
                                                      v
                                           Evidence      Conclusion
                                           +-------------+---+---+
                                           | Competitive | | |
                                           | quality on  | | |
                                           | Flux.1/2,   | | |
                                           | LTX-Video   | | |
                                           +-------------+---+---+
The Increment
One sentence: Before this paper, getting a diffusion model to produce consistent 360° panoramas required either scarce training data or minutes of optimization per image; after, you swap in one modified positional encoding layer and generate in normal inference time.
Core Mechanism
SpheRoPE works at a single intervention point: the Rotary Position Embedding (RoPE) layers inside a pre-trained diffusion transformer. RoPE encodes where each token “is” in the image grid. The standard version assigns 2D Cartesian positions—fine for flat images, fatal for spheres.
The key reparameterization splits RoPE channels by frequency:
Low-frequency channels get re-encoded as 3D Cartesian coordinates on the unit sphere. Instead of thinking in (x, y) grid positions, each token position is mapped to where it would actually sit on a sphere: (sin θ cos φ, sin θ sin φ, cos θ). This gives the model native understanding of spherical distance and angular relationships.
High-frequency channels are harmonically quantized to enforce exact periodicity. Equirectangular projection demands that the left image edge is literally identical to the right edge (360° wrap-around) and that the top/bottom are poles (fully compressed). Standard RoPE has no mechanism to express this. By quantizing the high frequencies to exact divisors of the image width, the position encoding itself becomes periodic—left and right edges receive complementary embeddings that sum to zero, naturally enforcing continuity.
A complementary technique—Semantic Distortion CFG—adjusts classifier-free guidance to explicitly steer the denoising process toward geometrically correct structures, rather than relying solely on the modified position encoding.
Input: Text Prompt + Noise
         |
         v
+----------------------------------------+
|     Pre-trained Diffusion Transformer   |
|             (frozen weights)            |
+------------------+---------------------+
                   |
         +---------+---------+
         |                   |
         v                   v
  +-------------+    +------------------+
  | Spherical   |    | Semantic         |
  | RoPE        |    | Distortion CFG   |
  |             |    |                  |
  | low-freq:   |    | Adjusts CFG to   |
  | (x,y) ->    |    | favor spherical  |
  | (X,Y,Z) on  |    | geometry over    |
  | unit sphere |    | planar artifacts |
  |             |    |                  |
  | high-freq:  |    +--------+---------+
  | quantize to |             |
  | enforce     |             |
  | periodicity |             |
  +------+------+             |
         |                   |
         v                   v
  +----------------------------------------+
  |         Denoising Iterations           |
  |   (position-aware, geometry-steered)   |
  +-------------------+--------------------+
                      |
                      v
  +----------------------------------------+
  |        Output: Consistent 360°         |
  |           Panorama / Video             |
  +----------------------------------------+
Structural Metaphor: The Globe vs. The Map
Imagine you’re a medieval cartographer tasked with drawing a world map. You have a globe (the true spherical reality), but you need to flatten it onto parchment (equirectangular projection). The standard approach: stretch and distort until it fits. Greenland looks huge, Antarctica becomes a long strip, and if you try to walk off the left edge, you’re stuck—the map has edges.
Now imagine a magical cartographer whose ruler itself is curved. When they measure distances between London and Tokyo, the ruler follows the great-circle arc on the sphere. When they reach the right edge of the parchment, their ruler wraps seamlessly to the left edge because it’s encoded with periodicity. The top of the map (North Pole) is automatically treated as a single point, not a long line.
That’s SpheRoPE. The “ruler” (RoPE) is replaced with one that understands spherical geometry natively:
- Low-frequency channels = the ruler’s broad shape, now bent into a sphere so distant points are measured correctly.
- High-frequency channels = the ruler’s fine tick marks, now spaced to repeat exactly at 360° intervals so the map wraps perfectly.
- Semantic Distortion CFG = an assistant cartographer who whispers “that coastline doesn’t make sense on a globe” during drawing, gently correcting the artist’s hand.
Without this magical ruler, even the best cartographer (pre-trained diffusion model) produces maps with visible seams, distorted poles, and impossible geometries.
Key Concepts
-
Rotary Position Embeddings (RoPE): Think of RoPE as a coordinate system baked into the neural network’s attention mechanism. When the model processes an image, each patch of pixels needs to “know” where it is relative to other patches. RoPE encodes this by rotating the query and key vectors in attention by angles proportional to position. Crucially, it operates in frequency bands—some channels rotate slowly (capturing coarse layout), others rotate fast (capturing fine spatial detail). The paper’s insight is that you can change what those rotations *mean without retraining the model: re-encode slow rotations as spherical angles, quantize fast rotations for periodicity, and the model’s existing weights “interpret” the new rotations correctly.
-
Equirectangular Projection (ERP) Constraints: Take an orange peel, flatten it onto a table. The top and bottom get squished (that’s why poles look distorted in flat maps). The left and right edges are actually the same line of longitude—glue them together and you’re back to a sphere. ERP has two hard constraints: (1) horizontal periodicity: pixel column 0 = pixel column W, and (2) vertical singularity: the top row is a single point (North Pole), the bottom row is another single point (South Pole). Any 360° generation method must satisfy these or produce visible artifacts—seams at the stitch line, stretched/duplicated poles.
-
Zero-Shot Training-Free: This is the paper’s selling point. “Zero-shot” means no panoramic training data at all. “Training-free” means no fine-tuning of any weights. “Optimization-free” means no iterative correction at inference time. You take a model trained entirely on regular (flat) images, plug in SpheRoPE, and it generates panoramas. The model’s existing knowledge—learned from billions of flat images—is repurposed through a better coordinate system.
Framework Shift
Before (mainstream approach):           After (this paper):
+----------+    +----------+            +----------+    +----------+
|Pretrained|    |Pretrained|            |Pretrained|    |Pretrained|
|Diffusion |    |Diffusion |            |Diffusion |    |Diffusion |
|Model     |    |Model     |            |Model     |    |Model     |
+----+-----+    +----+-----+            +----+-----+    +----+-----+
     |               |                       |               |
     v               v                       v               v
+----+-----+   +-----+----+           +----+-----+   +-----+----+
|Flat 2D   |   |Flat 2D   |           |Spherical |   |Spherical |
|Position  |   |Position  |           |RoPE      |   |RoPE      |
|Embedding |   |Embedding |           |(3D XYZ + |   |(3D XYZ + |
+----+-----+   +-----+----+           |periodic) |   |periodic) |
     |               |                +----+-----+   +-----+----+
     v               v                     |               |
+----+-----+   +-----+----+                v               v
|Fine-tune |   |Optimize  |           +----+-----+   +-----+----+
|on panos  |   |at infer  |           |Semantic  |   |Semantic  |
|(expensive|   |(slow)    |           |Distortion|   |Distortion|
|data-starv|   +-----+----+           |CFG       |   |CFG       |
+----+-----+         |                +----+-----+   +-----+----+
     |               v                     |               |
     v               v                     v               v
  Panorama        Panorama              Panorama        Panorama
  (limited        (high latency)        (zero-shot,     (video)
   domain)                               normal speed)
From fine-tune-or-optimize to swap-the-coordinate-system, the core shift is treating the problem as a spatial encoding mismatch rather than a knowledge or optimization problem.
Expert Assessment
Problem choice: This is a genuine gap with real commercial stakes. 360° content is exploding in VR/AR, real estate, and automotive. The fine-tuning vs. optimization dichotomy is accurately described, and neither camp had a clean solution. The problem sits at a natural intersection of geometric deep learning and generative models—exactly where clever interventions can outsized impact. Solid problem selection.
Method maturity: The RoPE reparameterization is elegant—it’s the kind of insight that makes you say “of course, why didn’t I think of that?” The structural decomposition (low-freq → spherical coordinates, high-freq → periodicity) is principled and well-motivated. However, the Semantic Distortion CFG feels like a patch added to compensate for cases where RoPE alone isn’t enough. The paper doesn’t clearly explain when or why it fails without this component. The method is clever rather than brute force, but not all gears mesh perfectly.
Experimental integrity: This is where the paper has the most to answer for. The abstract claims “competitive performance” but I want to see standard metrics (FID, LPIPS, user studies) in a clean comparison table. If those numbers are on the project page, they should be in the paper. Baselines chosen (fine-tuned models, optimization-based methods) are appropriate, but comparing against them is apples-to-oranges: they were trained or optimized on panorama data, while SpheRoPE wasn’t. The qualitative results would need to be compelling to overcome this. Cross-backbone generalization (Flux.1, Flux.2, LTX-Video) is a strong signal that the method is robust, not just cherry-picked for one architecture.
Writing quality: The abstract is well-crafted—clear problem statement, clean method summary, honest limitations. The paper would benefit enormously from: (1) an ablation study showing low-freq-only, high-freq-only, and combined contributions; (2) failure mode analysis—when does SpheRoPE break? Complex scenes? Extreme field-of-view? (3) a direct comparison of inference speed vs. optimization-based methods with wall-clock numbers. The Semantic Distortion CFG section likely needs a rewrite—I suspect it’s under-explained because it’s the least elegant component.
Verdict: weak accept — The core idea (RoPE reparameterization for spherical priors) is genuinely novel and potentially influential. If the quantitative results hold up and the speed advantage is real, this paper will be widely cited. The main reservation is incomplete experimental reporting and the somewhat ad-hoc Semantic Distortion component.
Takeaways
-
RoPE is a design space, not a fixed component. The insight that rotary position embeddings can be reparameterized to inject domain-specific geometric priors—without touching model weights—transfers directly to other domains. Want a diffusion model to generate cylindrical projections? Torus topology? Graph-structured outputs? Modify RoPE to encode that geometry. This is a technique worth stealing.
-
Decompose position encodings by frequency, intervene selectively. The low-freq/high-freq split is a general principle: coarse spatial relationships can be re-encoded with richer geometric representations, while fine spatial detail needs structural constraints (like periodicity). This decomposition pattern appears in neural radiance fields, implicit neural representations, and signal processing. The paper demonstrates it cleanly.
-
“Training-free” is increasingly a viable paradigm. As foundation models grow, the marginal cost of retraining approaches zero only if you can find the right intervention points. SpheRoPE shows that one well-placed architectural modification—a single layer swap—can unlock entirely new capabilities. The search for such intervention points (which layer? which component?) is itself a research direction worth pursuing.
论文: 2606.32033 作者: Or Hirschorn, Aaron Olender, Eli Alshan, Ianir Ideses, Lior Fritz, Sagie Benaim 分类: cs.CV
缺口
现有360度全景生成研究卡在两条路上,各有硬伤:
- 微调路线:用全景数据集训练专用模型。 问题是全景数据稀缺且采集成本高,模型还会丧失基础模型的创造广度。
- 优化路线:推理时迭代优化输出,强制满足球面约束(拼接缝隙、周期性等)。 问题是每张图要跑几分钟,实时应用和视频生成根本不现实。
这篇论文发现了第三条路:预训练的扩散变换器可能已经从海量数据中学到了潜在的全景知识,但它们的位置编码(RoPE)在拖后腿。 标准RoPE把图像当成平坦网格——跟等距矩形投影的拓扑结构根本不兼容(左边缘必须能接上右边缘,顶部向极点压缩)。
问题                    假设                      方法
+-----------------+     +-----------------+       +-----------------+
|360全景生成需要   |     |大规模预训练的    |       |用球面RoPE替换  |
|球面一致性       |     |扩散模型已有潜在  |       |平坦RoPE        |
|(ERP拓扑约束)    |     |的全景先验       |       |(3D XYZ+周期性) |
+--------+--------+     +--------+--------+       +--------+--------+
         |                       |                          |
         v                       v                          v
+--------+--------+       +------+--------+        +------+--------+
|微调:贵且窄     |       |优化:慢且      |        |零训练、正常   |
|优化:慢且不实时 |       |不适合实时应用  |        |推理速度        |
+-----------------+       +---------------+        +---------------+
                                                         |
                                                         v
                                                  证据        结论
                                                  +---+---+   +---+
                                                  |Flux   |   |可行|
                                                  |.1/.2 |   |且  |
                                                  |LTX-  |   |有效|
                                                  |Video |   +---+
                                                  +-------+
增量
一句话:这篇论文之前,让扩散模型生成一致的360°全景要么需要稀缺数据微调,要么需要几分钟推理优化;之后,只需替换一个位置编码层,就能以正常推理速度生成。
核心机制
SpheRoPE的干预点只有一个:预训练扩散变换器里的旋转位置嵌入(RoPE)层。 RoPE负责告诉模型每个图像块”在哪里”。 标准RoPE分配的是2D笛卡尔坐标——对平面图够用,对球面是致命的。
核心的重新参数化把RoPE通道按频率拆分:
低频通道被重新编码为单位球面上的3D笛卡尔坐标。 每个图像块的位置不再用(x, y)表示,而是映射到球面上的实际位置:(sin θ cos φ, sin θ sin φ, cos θ)。 这让模型原生理解球面距离和角度关系。
高频通道被谐波量化,强制实现精确周期性。 等距矩形投影要求左边缘和右边缘像素完全相同(360°环绕),顶部和底部是极点(完全压缩)。 标准RoPE没有表达这种约束的机制。 通过把高频量化为图像宽度的精确因子,位置编码本身变得周期性——左右边缘获得互补的嵌入,自然地强制连续性。
还有一个补充技术——语义畸变无分类器引导(Semantic Distortion CFG)——调整CFG来显式引导去噪过程朝向几何正确的结构,而不是完全依赖修改后的位置编码。
输入: 文本提示 + 噪声
         |
         v
+------------------------------------------+
|      预训练扩散变换器(权重冻结)          |
+-------------------+----------------------+
                    |
         +----------+----------+
         |                     |
         v                     v
  +--------------+    +------------------+
  | 球面 RoPE    |    | 语义畸变 CFG     |
  |              |    |                  |
  | 低频通道:    |    | 调整CFG以偏向    |
  | (x,y) ->    |    | 球面几何,       |
  | 单位球面上的 |    | 抑制平面伪影     |
  | (X,Y,Z)     |    |                  |
  |              |    +--------+---------+
  | 高频通道:    |             |
  | 量化以强制   |             |
  | 周期性       |             |
  +------+-------+             |
         |                     |
         v                     v
  +------------------------------------------+
  |           去噪迭代过程                    |
  |    (位置感知、几何引导)                  |
  +--------------------+---------------------+
                       |
                       v
  +------------------------------------------+
  |         输出:一致的360°                  |
  |            全景图 / 视频                   |
  +------------------------------------------+
结构性比喻:地球仪 vs. 平面地图
想象你是个中世纪制图师,要把地球画成平面地图。 你手里有地球仪(真实的球面),但要把它摊平到羊皮纸上(等距矩形投影)。 常规做法:使劲拉伸和扭曲。 结果格陵兰看起来巨大无比,南极洲变成一条长带。 你从地图左边缘走过去,就卡住了——地图有边界。
现在想象一位魔法制图师,他的尺子本身就是弯曲的。 当他测量伦敦到东京的距离时,尺子沿大圆弧弯曲,量出真实距离。 当他画到羊皮纸右边缘时,尺子自动弯到左边缘继续画,因为尺子被编码了周期性。 地图顶部(北极)自动被当作一个点处理,而不是一条长线。
这就是SpheRoPE。 “尺子”(RoPE)被替换成一把天然理解球面几何的尺子:
- 低频通道 = 尺子的大弧度形状,弯成球面,确保远距离点的测量准确。
- 高频通道 = 尺子上的细刻度,间距精确到360°周期,确保地图无缝循环。
- 语义畸变 CFG = 旁边帮忙的制图助手,在画图时轻声提醒”这条海岸线在地球上说不通”,轻轻纠正画师的手。
没有这把魔法尺子,即使最好的画师(预训练扩散模型)也会画出有明显接缝、极点扭曲和不可能几何的地图。
关键概念
-
旋转位置嵌入(RoPE):把RoPE想成神经网络注意力机制里的一套坐标系统。 模型处理图像时,每个像素块需要”知道”自己相对其他块的位置。 RoPE通过旋转注意力中的查询和关键向量来编码位置,旋转角度正比于距离。 关键点是它在频段上运作——某些通道旋转缓慢(捕捉粗略布局),另一些旋转快速(捕捉精细空间细节)。 论文的洞察是:你可以改变这些旋转的含义,而不需要重新训练模型——把慢速旋转重新编码为球面角度,把快速旋转量化为周期性,模型现有的权重会正确”解读”新的旋转。
-
等距矩形投影(ERP)约束:拿个橘子皮,把它摊平在桌面上。 顶部和底部被挤压(所以平面地图上极点看起来扭曲了)。 左右边缘其实是同一条经线——把它们粘回去,又变回球面了。 ERP有两个硬约束:(1)水平周期性:第0列像素=第W列像素; (2)垂直奇点:顶行是一个点(北极),底行是另一个点(南极)。 任何360°生成方法都必须满足这两个约束,否则会出现可见伪影——接缝线、极点拉伸或重复。
-
零样本无训练:这是论文的核心卖点。 “零样本”意味着完全不使用全景训练数据。 “无训练”意味着不微调任何权重。 “无优化”意味着推理时不做迭代修正。 你拿一个完全在普通(平面)图像上训练的模型,接入SpheRoPE,它就能生成全景。 模型现有的知识——从数十亿张平面图中学来的——通过更好的坐标系被重新利用了。
框架转变
之前(主流方法):                之后(本文方法):
+----------+  +----------+       +----------+  +----------+
|预训练    |  |预训练    |       |预训练    |  |预训练    |
|扩散模型  |  |扩散模型  |       |扩散模型  |  |扩散模型  |
+----+-----+  +----+-----+       +----+-----+  +----+-----+
     |               |                |               |
     v               v                v               v
+----+-----+  +------+----+     +----+-----+  +------+----+
|平坦2D    |  |平坦2D    |     |球面      |  |球面      |
|位置编码  |  |位置编码  |     |RoPE      |  |RoPE      |
+----+-----+  +------+----+     |(3D XYZ + |  |(3D XYZ + |
     |               |          |周期性)   |  |周期性)   |
     v               v          +----+-----+  +------+----+
+----+-----+  +------+----+          |               |
|在全景    |  |推理时    |          v               v
|数据上    |  |优化      |     +----+-----+  +------+----+
|微调      |  |(慢)      |     |语义畸变  |  |语义畸变  |
|(贵且窄)  |  +------+----+     |CFG       |  |CFG       |
+----+-----+        |          +----+-----+  +------+----+
     |               v               |               |
     v               v               v               v
  全景图          全景图          全景图(零样本)   全景图(视频)
  (领域受限)      (高延迟)        (正常速度)       (零样本)
从”微调或优化”到”换个坐标系”,核心转变是把问题当作空间编码失配来处理,而不是知识不足或优化不够。
专家评审
选题眼光:真正的缺口,有实际商业价值。 VR/AR、房地产、汽车行业对360°内容需求爆发式增长。 微调与优化的二分法描述准确,两边都没有干净的解决方案。 问题恰好在几何深度学习和生成模型的交叉点——正是巧妙干预能产生杠杆效应的地方。 选题扎实。
方法成熟度:RoPE重新参数化是优雅的——让人忍不住想”为什么我没想到”。 低频→球面坐标、高频→周期性的结构分解有原则性,动机清晰。 但语义畸变CFG像是给RoPE打不赢的场景打的补丁。 论文没清楚解释没有这个组件时什么时候、为什么失效。 方法是巧劲而非蛮力,但不是所有齿轮都完美咬合。
实验诚意:这是论文需要交代清楚的地方。 摘要声称”有竞争力的表现”,但我需要看到标准指标(FID、LPIPS、用户研究)的整洁对比表。 如果项目页面有定量数据,就应该放在论文里。 选的基线(微调模型、优化方法)是合适的,但比较是苹果对橘子:它们在全景数据上训练/优化过,SpheRoPE没有。 跨骨干网络泛化(Flux.1、Flux.2、LTX-Video)是强信号,说明方法是稳健的,不是对一个架构的精心挑选。
写作功力:摘要写得好——问题陈述清晰、方法总结干净、局限诚实。 论文需要大幅改进的地方:(1)消融实验,展示仅低频、仅高频、组合的贡献;(2)失败模式分析——SpheRoPE什么时候崩溃?复杂场景?极端视场角?(3)与优化方法的推理速度直接对比,要有墙钟时间数据。 语义畸变CFG部分很可能需要重写——我怀疑它解释不够是因为它是最不优雅的组件。
判决:弱接收 — 核心想法(RoPE重新参数化注入球面先验)确实新颖,可能有影响力。 如果定量结果站得住脚、速度优势真实,这篇论文会被广泛引用。 主要保留意见是实验报告不完整和语义畸变组件有点临时拼凑。
要点总结
-
RoPE是一个设计空间,不是固定组件。 旋转位置嵌入可以被重新参数化来注入领域特定的几何先验——不碰模型权重——这个洞察可以直接迁移到其他领域。 想要扩散模型生成柱面投影?环面拓扑?图结构输出?修改RoPE来编码那种几何。 这是一个值得偷的技术。
-
按频率分解位置编码,选择性干预。 低频/高频拆分是一个通用原则:粗略空间关系可以用更丰富的几何表示重新编码,精细空间细节需要结构约束(如周期性)。 这种分解模式出现在神经辐射场、隐式神经表示和信号处理中。 论文展示了它的清晰实例。
-
“无训练”正成为越来越可行的范式。 基础模型越来越大,如果你能找到正确的干预点,重训的边际成本趋近于零。 SpheRoPE展示了一处精心选择的架构修改——单层替换——就能解锁全新能力。 寻找这种干预点(哪一层?哪个组件?)本身就是值得投入的研究方向。