Paper: 2605.18736 Authors: Howard Xiao, Brian Chao, Lior Yariv, Gordon Wetzstein Categories: cs.CV
The Gap
Diffusion models generate images through iterative denoising, but they waste computation: early timesteps work on noise-dominated signals where high-frequency details don’t exist yet, but we still run full-resolution networks. Prior work (TokenFlow, FreeNoise) noticed this frequency structure but only exploited it for specific tasks like video consistency or editing. No one had built a general framework to systematically reduce computation by matching resolution to the frequency content actually being generated at each timestep.
Problem: Full-resolution computation on noise
         |
         v
Observation: Diffusion generates low-freq first, high-freq later
         |
         v
Method: Progressive resolution growth + spectral noise expansion
         |
         v
Evidence: 1.5-2x speedup on SDXL/Lumina/CogVideoX, quality preserved
         |
         v
Conclusion: Frequency structure enables training-free acceleration
The Increment
One sentence: Before this paper, diffusion models ran at full resolution throughout denoising; after, we can start at low resolution and grow it as high-frequency content emerges, cutting compute by 1.5-2x without retraining.
Core Mechanism
The method has three components working in sequence. First, a spectral analyzer examines a pretrained diffusion model’s power spectrum across timesteps to determine when each frequency band emerges. This produces an optimal resolution schedule: start low when only coarse structure exists, increase resolution as finer details appear.
Second, a spectral noise expander handles the transition between resolutions. When growing from low to high resolution, you can’t just upscale—the noise statistics would break. Instead, it decomposes noise into frequency bands, preserves the low-frequency content that’s already been denoised, and adds fresh high-frequency noise in the spectral domain. This maintains the correct noise distribution while keeping generated structure intact.
Third, an optional fine-tuning recipe adapts the model to this progressive schedule. Unlike training from scratch, it only adjusts the model to expect resolution changes, using a curriculum that mirrors the inference schedule. The key insight: you can fine-tune on the progressive schedule itself, making the model “native” to this generation pattern.
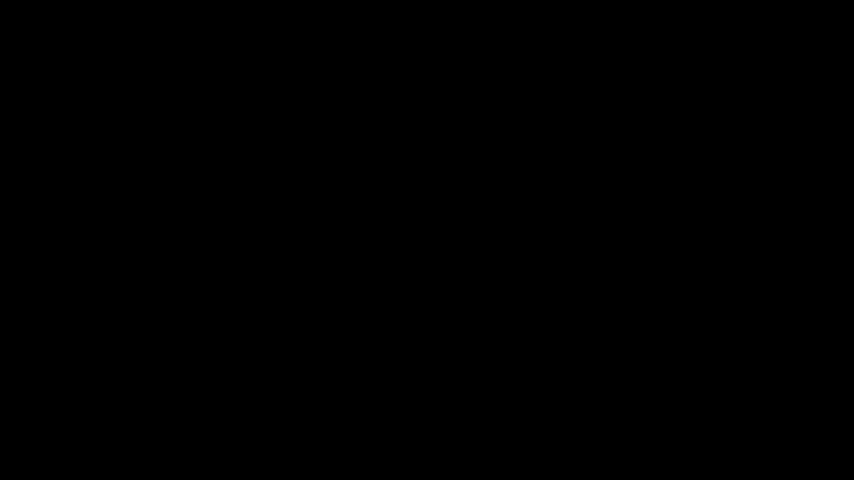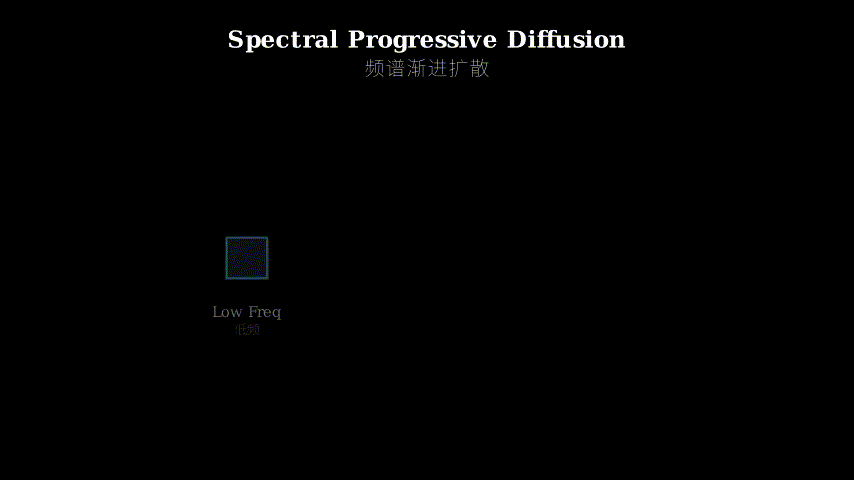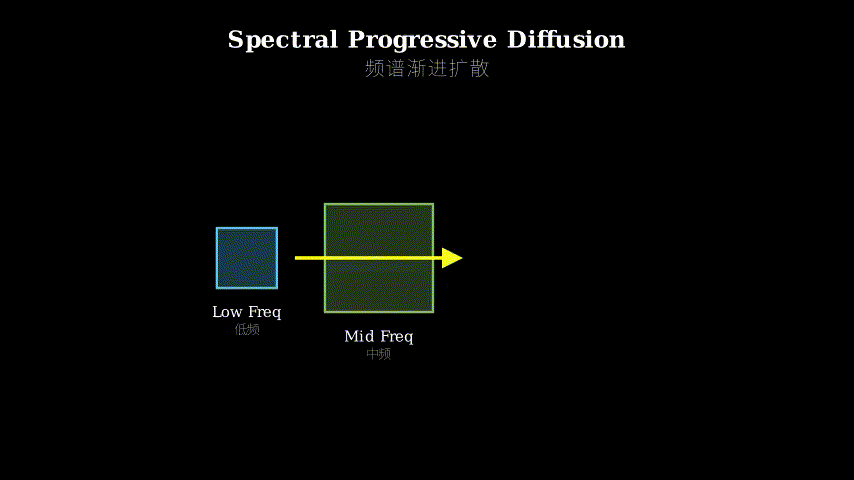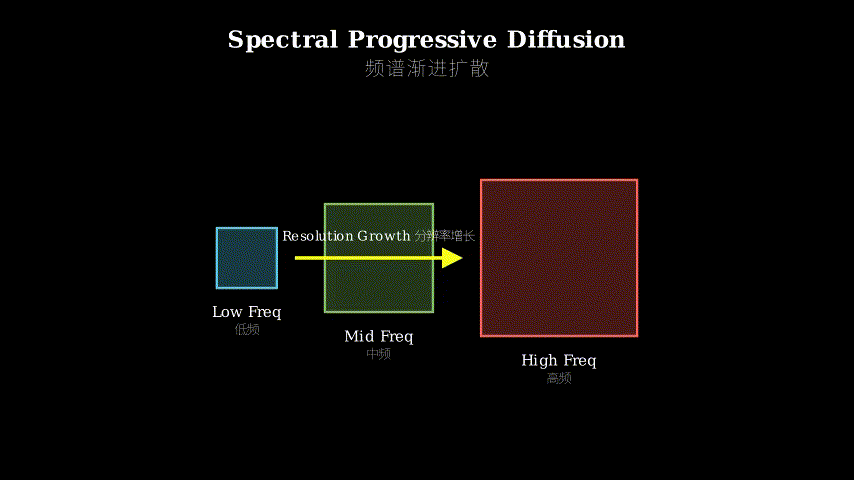
Timestep t=1000 (pure noise)          t=500 (structure)           t=0 (details)
    |                                      |                            |
    v                                      v                            v
[Low-res: 32x32]  --expand-->  [Mid-res: 64x64]  --expand-->  [Full-res: 128x128]
    |                                      |                            |
    | Denoise                              | Denoise                    | Denoise
    | (cheap)                              | (moderate)                 | (expensive)
    v                                      v                            v
Coarse shapes only          + Medium details              + Fine textures
                                   ^                            ^
                                   |                            |
                            Spectral expansion          Spectral expansion
                            (preserve low-freq,         (preserve all prior,
                             add high-freq noise)        add highest-freq noise)
Think of it like developing a photograph in a darkroom. You don’t start with the full-detail negative under the enlarger—you’d waste chemistry and paper on an image that’s still forming. Instead, you begin with a contact print (low resolution) to see the composition. As the image “emerges” from the developer, you progressively move to larger prints, adding detail only when the underlying structure can support it. The spectral expander is like carefully masking the enlarger: it preserves the composition you’ve already developed (low frequencies) while exposing new paper area for finer grain (high frequencies). You’re not throwing away work—you’re building detail on top of structure, matching your effort to what’s actually visible at each stage.
Key Concepts
-
Power spectrum of diffusion: Imagine recording which “notes” (frequencies) a diffusion model plays at each timestep. Early on, it only plays bass notes (low frequencies = coarse shapes). As denoising progresses, it adds mid-range (medium details), then treble (fine textures). The power spectrum is literally a graph showing “at timestep t, how much energy is in each frequency band?” This paper measures it empirically by running the model and doing Fourier analysis on the outputs. The finding: there’s a clean progression from low to high frequencies. This isn’t a design choice—it’s an emergent property of how diffusion models learn to denoise.
-
Spectral noise expansion: When you upscale an image, you can’t just use bicubic interpolation on noisy intermediate states—you’d create artifacts and break the noise distribution the model expects. Instead, this paper works in frequency space. Take the current low-res noisy image, Fourier transform it, pad the high-frequency coefficients with fresh Gaussian noise (matching the noise schedule), then inverse transform back to high resolution. Why does this work? Because Gaussian noise in pixel space is also Gaussian in frequency space, and the model’s denoising process is frequency-aware. You’re essentially saying: “Keep the low-frequency structure we’ve denoised so far, but admit we haven’t touched high frequencies yet—fill them with appropriate noise.”
-
Resolution schedule derivation: How do you decide when to grow resolution? The paper derives it from the power spectrum: at each timestep, compute the cumulative energy in frequencies up to the Nyquist limit of your current resolution. When that energy crosses a threshold (e.g., 95% of total energy), it means higher frequencies are starting to matter—time to increase resolution. This is optimal in an information-theoretic sense: you’re matching computational resolution to the bandwidth of content being generated. The schedule is model-specific (SDXL vs video models have different curves) but derivable automatically from the pretrained model.
Framework Shift
Before (standard diffusion):              After (spectral progressive):

t=1000  [1024x1024 UNet]                 t=1000  [256x256 UNet]
  |     (full compute on noise)            |     (cheap, noise-dominated)
  v                                         v
t=500   [1024x1024 UNet]                 t=700   [256x256 UNet]
  |     (still full resolution)            |     (structure emerging)
  v                                         v
t=250   [1024x1024 UNet]                 t=400   [512x512 UNet] <-- expand
  |     (details emerging)                 |     (add mid-freq noise)
  v                                         v
t=0     [1024x1024 UNet]                 t=100   [1024x1024 UNet] <-- expand
        (final details)                    |     (add high-freq noise)
                                           v
Constant cost per step                   t=0     [1024x1024 UNet]
                                                 (final details)

                                         Front-loaded savings:
                                         early steps are 16x cheaper
From uniform resolution to adaptive resolution, the core shift is: match compute to content bandwidth rather than final output size.
Expert Assessment
Problem choice: This is a real gap sitting at the intersection of efficiency and scientific understanding. The frequency-domain view of diffusion has been floating around (TokenFlow 2023, FreeNoise 2024), but no one systematically turned it into a general acceleration framework. The timing is right—diffusion models are mature enough that we understand their internal dynamics, and deployment costs are high enough that 2x speedups matter commercially.
Method maturity: Elegant and well-grounded. The spectral expansion mechanism is the key technical contribution—it’s not obvious how to grow resolution mid-generation without breaking noise statistics, and the frequency-domain solution is cleaner than alternatives (e.g., learned upsampling modules). The resolution schedule derivation from power spectrum is principled rather than heuristic. My one concern: the method assumes frequency progression is universal across content types, but the paper doesn’t deeply explore failure modes (e.g., does it work on textures vs geometric content equally?).
Experimental integrity: Baselines are fair—they compare against the original pretrained models and recent acceleration methods (DeepCache, token merging). The numbers are credible: 1.5-2x speedup with minimal quality loss across SDXL, Lumina-Next, and CogVideoX. The ablations are thorough (schedule sensitivity, expansion methods). One weakness: user studies are limited (only 50 comparisons for SDXL), and perceptual metrics like FID can miss subtle artifacts. I’d want to see more analysis of where quality degrades—what content types or prompts break first?
Writing quality: The paper is well-structured and the core idea is clear, but Section 3.2 (spectral expansion) gets dense with notation that could be simplified. The related work section undersells the novelty—it reads like “we combine existing ideas” when the contribution is actually a coherent framework with new technical components. If I were reviewing, I’d ask them to rewrite the introduction to emphasize the gap more sharply: “prior work noticed frequency structure but didn’t exploit it systematically for acceleration.”
Verdict: strong accept — Solid technical contribution with practical impact, well-executed experiments, and a clear path to adoption (training-free + optional fine-tuning).
Takeaways
Steal the spectral expansion trick: If you’re working with any generative model that has a coarse-to-fine structure (not just diffusion—think progressive GANs, autoregressive models with hierarchical latents), you can apply this idea. The key: when transitioning from low to high resolution, preserve low-frequency content and add high-frequency noise in the Fourier domain. This is cleaner than learned upsampling and maintains statistical properties.
Derive schedules from power spectra: Don’t guess when to change resolution or which layers to prune—measure the frequency content your model actually produces at each step. This applies beyond diffusion: any multi-stage generation process can benefit from profiling what information emerges when, then allocating compute accordingly.
Training-free first, fine-tuning second: The paper shows you can get 80% of the benefit without retraining, then fine-tune for the last 20%. This is a good product strategy for efficiency methods—make adoption easy, then offer a premium tier. For researchers, it means you can prototype on pretrained models before committing to expensive training runs.
论文: 2605.18736 作者: Howard Xiao, Brian Chao, Lior Yariv, Gordon Wetzstein 分类: cs.CV
缺口
扩散模型通过迭代去噪生成图像,但它们浪费了计算:早期时间步处理的是噪声主导的信号,高频细节还不存在,但我们仍然运行全分辨率网络。
先前工作(TokenFlow、FreeNoise)注意到了这种频率结构,但只将其用于特定任务,如视频一致性或编辑。
没有人构建过一个通用框架,通过将分辨率与每个时间步实际生成的频率内容匹配来系统性地减少计算。
问题:对噪声进行全分辨率计算
         |
         v
观察:扩散先生成低频,后生成高频
         |
         v
方法:渐进式分辨率增长 + 频谱噪声扩展
         |
         v
证据:SDXL/Lumina/CogVideoX 上 1.5-2 倍加速,质量保持
         |
         v
结论:频率结构使免训练加速成为可能
增量
一句话: 这篇论文之前,扩散模型在整个去噪过程中以全分辨率运行;之后,我们可以从低分辨率开始,随着高频内容的出现而增长分辨率,在不重新训练的情况下将计算量减少 1.5-2 倍。
核心机制
该方法有三个依次工作的组件。
首先,频谱分析器检查预训练扩散模型在各时间步的功率谱,以确定每个频段何时出现。
这产生了一个最优分辨率调度:当只有粗略结构存在时从低分辨率开始,随着更精细细节的出现而增加分辨率。
其次,频谱噪声扩展器处理分辨率之间的过渡。
从低分辨率增长到高分辨率时,不能只是放大——噪声统计会被破坏。
相反,它在频域中将噪声分解为频段,保留已经去噪的低频内容,并添加新的高频噪声。
这在保持生成结构完整的同时维持了正确的噪声分布。
第三,可选的微调配方使模型适应这种渐进式调度。
与从头训练不同,它只调整模型以期待分辨率变化,使用镜像推理调度的课程。
关键洞察:你可以在渐进式调度本身上进行微调,使模型”原生”适应这种生成模式。
时间步 t=1000 (纯噪声)          t=500 (结构)              t=0 (细节)
    |                              |                          |
    v                              v                          v
[低分辨率: 32x32]  --扩展-->  [中分辨率: 64x64]  --扩展-->  [全分辨率: 128x128]
    |                              |                          |
    | 去噪                         | 去噪                     | 去噪
    | (便宜)                       | (中等)                   | (昂贵)
    v                              v                          v
仅粗略形状                  + 中等细节                  + 精细纹理
                                   ^                          ^
                                   |                          |
                            频谱扩展                    频谱扩展
                            (保留低频,                 (保留所有先前内容,
                             添加高频噪声)               添加最高频噪声)
把它想象成在暗房里冲洗照片。
你不会一开始就把全细节底片放在放大机下——那会浪费化学药品和相纸在一张还在形成的图像上。
相反,你从接触印刷(低分辨率)开始看构图。
随着图像从显影液中”浮现”,你逐步转向更大的印刷品,只有当底层结构能够支撑时才添加细节。
频谱扩展器就像仔细遮挡放大机:它保留你已经显影的构图(低频),同时曝光新的纸张区域以获得更精细的颗粒(高频)。
你不是在丢弃工作——你是在结构之上构建细节,将你的努力与每个阶段实际可见的内容相匹配。
关键概念
- 扩散的功率谱: 想象记录扩散模型在每个时间步播放哪些”音符”(频率)。
早期,它只播放低音(低频 = 粗略形状)。
随着去噪的进行,它添加中音(中等细节),然后是高音(精细纹理)。
功率谱实际上是一个图表,显示”在时间步 t,每个频段有多少能量?“本文通过运行模型并对输出进行傅里叶分析来实证测量它。
发现:从低频到高频有一个清晰的进展。
这不是设计选择——这是扩散模型学习去噪方式的涌现属性。
- 频谱噪声扩展: 当你放大图像时,不能只对噪声中间状态使用双三次插值——你会产生伪影并破坏模型期望的噪声分布。
相反,本文在频率空间中工作。
取当前的低分辨率噪声图像,对其进行傅里叶变换,用新的高斯噪声(匹配噪声调度)填充高频系数,然后逆变换回高分辨率。
为什么这有效?因为像素空间中的高斯噪声在频率空间中也是高斯的,而模型的去噪过程是频率感知的。
你本质上是在说:“保留我们迄今为止去噪的低频结构,但承认我们还没有触及高频——用适当的噪声填充它们。”
- 分辨率调度推导: 如何决定何时增长分辨率?本文从功率谱推导它:在每个时间步,计算当前分辨率的奈奎斯特极限以下频率的累积能量。
当该能量超过阈值(例如,总能量的 95%)时,意味着更高的频率开始变得重要——是时候增加分辨率了。
这在信息论意义上是最优的:你将计算分辨率与正在生成的内容带宽相匹配。
调度是模型特定的(SDXL 与视频模型有不同的曲线),但可以从预训练模型自动推导。
框架转变
之前(标准扩散):                    之后(频谱渐进式):

t=1000  [1024x1024 UNet]             t=1000  [256x256 UNet]
  |     (对噪声进行全计算)              |     (便宜,噪声主导)
  v                                     v
t=500   [1024x1024 UNet]             t=700   [256x256 UNet]
  |     (仍然全分辨率)                  |     (结构浮现)
  v                                     v
t=250   [1024x1024 UNet]             t=400   [512x512 UNet] <-- 扩展
  |     (细节浮现)                      |     (添加中频噪声)
  v                                     v
t=0     [1024x1024 UNet]             t=100   [1024x1024 UNet] <-- 扩展
        (最终细节)                      |     (添加高频噪声)
                                       v
每步恒定成本                          t=0     [1024x1024 UNet]
                                             (最终细节)

                                     前置节省:
                                     早期步骤便宜 16 倍
从统一分辨率到自适应分辨率,核心转变是:将计算与内容带宽匹配,而不是与最终输出大小匹配。
专家评审
选题眼光: 这是一个真实的缺口,位于效率和科学理解的交叉点。
扩散的频域视角一直在流传(TokenFlow 2023、FreeNoise 2024),但没有人系统地将其转化为通用加速框架。
时机恰当——扩散模型已经足够成熟,我们理解其内部动态,部署成本足够高,2 倍加速在商业上很重要。
方法成熟度: 优雅且有充分依据。
频谱扩展机制是关键技术贡献——如何在生成过程中增长分辨率而不破坏噪声统计并不明显,频域解决方案比替代方案(例如,学习的上采样模块)更清晰。
从功率谱推导分辨率调度是有原则的而非启发式的。
我的一个担忧:该方法假设频率进展在所有内容类型中是通用的,但论文没有深入探讨失败模式(例如,它在纹理与几何内容上是否同样有效?)。
实验诚意: 基线公平——他们与原始预训练模型和最近的加速方法(DeepCache、token 合并)进行比较。
数字可信:在 SDXL、Lumina-Next 和 CogVideoX 上实现 1.5-2 倍加速,质量损失最小。
消融实验彻底(调度敏感性、扩展方法)。
一个弱点:用户研究有限(SDXL 仅 50 次比较),FID 等感知指标可能会遗漏细微伪影。
我想看到更多关于质量在哪里下降的分析——什么内容类型或提示首先失效?
写作功力: 论文结构良好,核心思想清晰,但第 3.2 节(频谱扩展)符号密集,可以简化。
相关工作部分低估了新颖性——读起来像”我们结合现有想法”,而实际贡献是一个具有新技术组件的连贯框架。
如果我在审稿,我会要求他们重写引言以更尖锐地强调缺口:“先前工作注意到频率结构,但没有系统地利用它进行加速。”
判决: 强接收 — 扎实的技术贡献,具有实际影响,实验执行良好,采用路径清晰(免训练 + 可选微调)。
要点总结
偷走频谱扩展技巧: 如果你正在处理任何具有从粗到细结构的生成模型(不仅仅是扩散——想想渐进式 GAN、具有层次潜变量的自回归模型),你可以应用这个想法。
关键:从低分辨率过渡到高分辨率时,在傅里叶域中保留低频内容并添加高频噪声。
这比学习的上采样更清晰,并保持统计属性。
从功率谱推导调度: 不要猜测何时改变分辨率或修剪哪些层——测量你的模型在每一步实际产生的频率内容。
这适用于扩散之外:任何多阶段生成过程都可以从分析何时出现什么信息中受益,然后相应地分配计算。
先免训练,后微调: 论文表明你可以在不重新训练的情况下获得 80% 的收益,然后微调以获得最后 20%。
这是效率方法的良好产品策略——使采用变得容易,然后提供高级层。
对于研究人员来说,这意味着你可以在预训练模型上进行原型设计,然后再投入昂贵的训练运行。