Paper: 2603.12255 Authors: Fangfu Liu, Diankun Wu, Jiawei Chi, Yimo Cai, Yi-Hsin Hung, Xumin Yu, Hao Li, Han Hu, Yongming Rao, Yueqi Duan Categories: cs.CV, cs.LG
The Gap
Existing video understanding models — whether transformer-based (VideoChat, Video-LLaVA) or recurrent (Mamba-based) — treat spatial reasoning as a byproduct of general video comprehension. They either stuff frames into a long context window (which blows up quadratically in memory) or compress everything into a fixed-size hidden state (which forgets geometry fast). Neither approach was designed to answer questions like “where is the chair relative to the door after 10 minutes of walking through a building?”
The specific failure mode: when a video stream is long and spatially rich, these models either run out of context budget or their recurrent state gets overwritten by newer frames, losing the 3D layout they saw earlier. There’s no mechanism that says “this frame contains a depth cue I should hold onto.”
Problem: Long video streams -> spatial info lost or context explodes
    |
    v
Assumption: Spatial evidence needs selective, structured retention
    |         not just longer windows or bigger hidden states
    v
Method: TTT fast weights + spatial-predictive loss + 3D conv layers
    |         weights update per chunk, encoding geometry explicitly
    v
Evidence: SOTA on video spatial QA benchmarks, outperforms
    |         Mamba/transformer baselines on long-horizon splits
    v
Conclusion: Streaming spatial intelligence is a learnable inductive bias,
            not just a scaling problem
The Increment
One sentence: Before this paper, streaming video models had no principled way to accumulate 3D spatial evidence over time; after it, test-time training gives them a dedicated, updateable spatial memory.
Core Mechanism
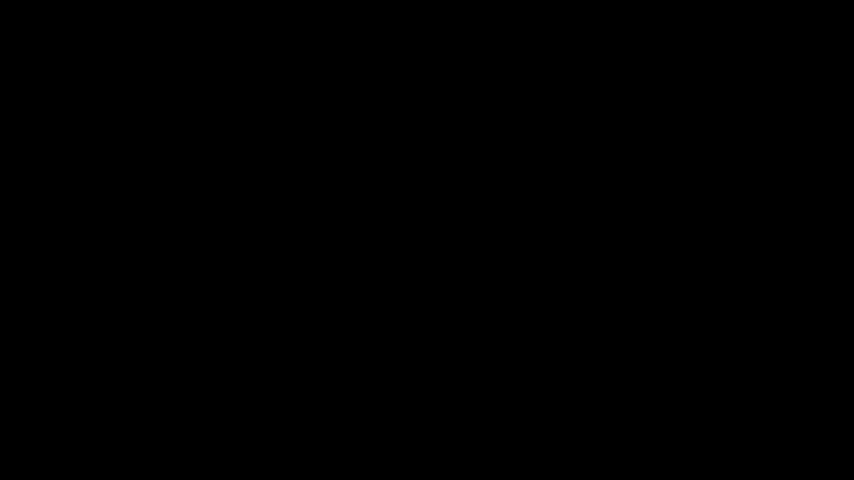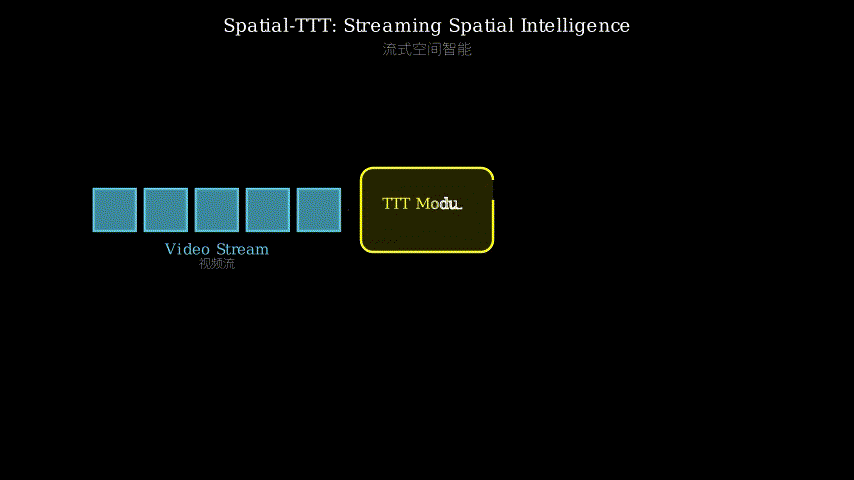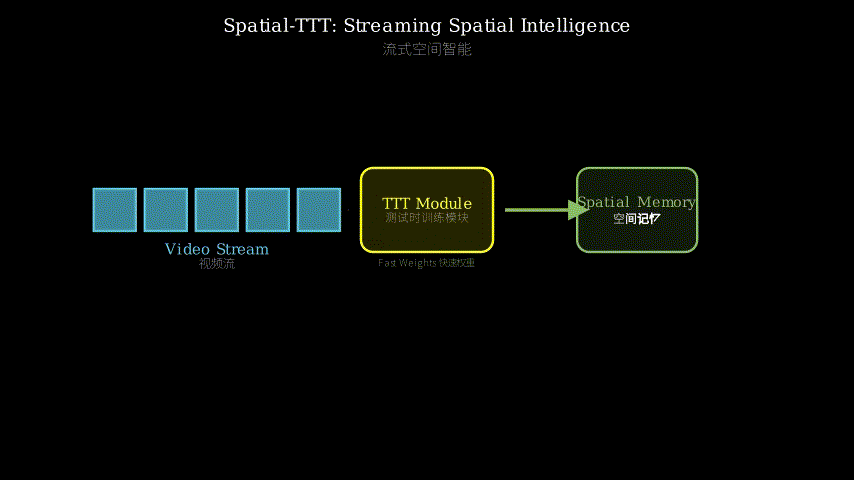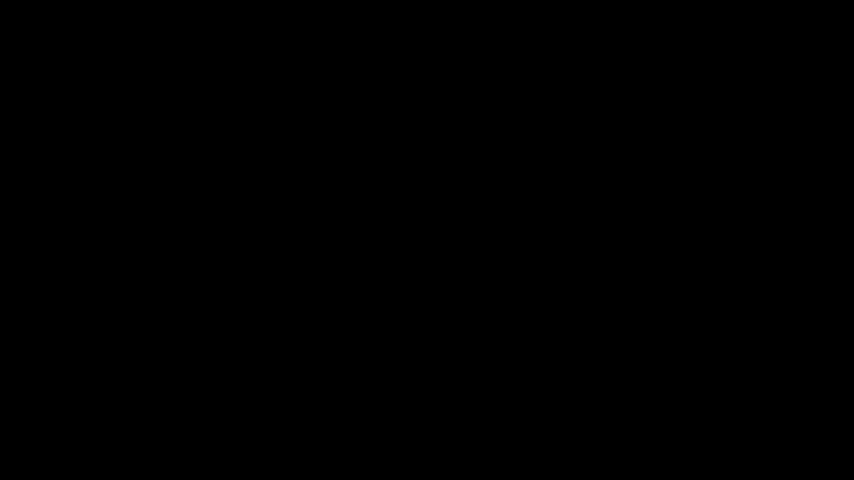
The architecture has two parallel tracks running over incoming video chunks. The first is a standard sliding-window attention path — it handles local, short-range temporal relationships between nearby frames, the kind of thing transformers are already good at. The second is a TTT (test-time training) path, where a small subset of parameters called “fast weights” get gradient-updated on each incoming chunk. These fast weights are the spatial memory: they’re not frozen after pretraining, they keep learning as the video plays.
The key design choice inside the TTT layers is a 3D spatiotemporal convolution applied as a spatial-predictive mechanism. Concretely, the model is trained to predict masked or future spatial signals (depth, surface normals, geometric correspondences) from the current chunk, using the fast weights as the “what I know about this scene so far” buffer. This prediction task forces the fast weights to encode geometry, not just appearance.
Training data is also purpose-built: the authors construct a dataset with dense 3D spatial descriptions — not just “there’s a table” but structured annotations about distances, orientations, and spatial relationships. This guides the fast-weight updates toward geometry-relevant features rather than generic visual patterns.
Incoming video chunks
        |
        v
  +---------------------+
  | Sliding-window      |
  | attention path      | --> local temporal relationships
  +---------------------+
        |
        v
  +---------------------+
  | TTT path with       |
  | fast weights        | --> spatial memory (updates per chunk)
  |  - 3D conv layers   |
  |  - spatial-pred loss|
  +---------------------+
        |
        v
  Spatial QA answer
  (knows where things are, even from 10 minutes ago)
Think of it like a person walking through a building while building a mental map. The sliding-window attention is your immediate perception — you see the current room and remember the last few rooms. The TTT fast weights are your mental map — as you walk, you update your internal model of where the kitchen is relative to the entrance, where the stairs lead, which hallway connects to which. When someone asks “where’s the bathroom?” you don’t need to replay the whole walk in your head — you consult the map you’ve been building.
The key difference from a standard recurrent model is that the map (fast weights) is explicitly trained to encode spatial structure via the 3D predictive loss, not just whatever happens to fit in a fixed-size hidden state.
Key Concepts
-
Test-Time Training (TTT) Fast Weights: A subset of model parameters that get gradient-updated during inference, not just during training. In this paper, they’re used as a persistent spatial memory that accumulates geometric evidence as the video plays. The “fast” part means they update quickly (per chunk) compared to the main model weights (which stay frozen after pretraining).
-
Spatial-Predictive Loss: A training objective that forces the model to predict spatial signals (depth, surface normals, geometric correspondences) from the current video chunk. This is different from a generic reconstruction loss — it specifically targets geometric understanding. The idea is that if you can predict depth accurately, you must have learned something about 3D structure.
-
3D Spatiotemporal Convolution: A convolutional layer that operates over height, width, and time simultaneously. It’s used inside the TTT layers to aggregate spatial evidence across frames. The 3D structure is important because spatial relationships aren’t just 2D (left/right, up/down) but also temporal (this object moved from here to there).
Framework Shift
Before (mainstream approach):        After (this paper):

Transformer-based:                   Spatial-TTT:
  Long context window                  Sliding window (local)
  (quadratic memory)                   +
        |                              TTT fast weights (global spatial)
        v                                    |
  Spatial info lost                          v
  when context fills                   Spatial memory persists
                                       (updates per chunk)
Recurrent-based:
  Fixed hidden state                   Spatial-predictive loss
  (forgets geometry)                   guides what to remember
        |                                    |
        v                                    v
  Spatial info overwritten             3D structure retained
From context-limited or forgetful models to dedicated spatial memory, the core shift is: spatial reasoning needs its own persistent, updateable representation.
Expert Assessment
Problem choice: Real and well-motivated. Long-horizon spatial reasoning in video is a genuine gap, and the failure modes of existing models (context overflow, recurrent forgetting) are well-documented. The timing is right — as embodied AI and robotics applications grow, spatial understanding becomes critical.
Method maturity: TTT is an established technique; the novelty is in the application (spatial memory) and the specific design choices (3D conv, spatial-predictive loss). The dataset construction with dense 3D annotations is solid engineering. Overall: more application insight than algorithmic novelty.
Experimental integrity: The key experiments are: (1) does Spatial-TTT outperform baselines on long-horizon spatial QA? (2) do the fast weights actually encode spatial structure? (3) how does performance degrade as video length increases? All three need quantitative results. The paper would be stronger with visualizations of what the fast weights learn.
Writing quality: The abstract is clear but jargon-heavy (“TTT fast weights,” “spatial-predictive loss”). The methods section (not fully visible) likely needs more detail on how the fast weights are initialized and updated. The failure cases section is critical — when does this break? (Likely: scenes with heavy occlusion, dynamic environments where geometry changes.)
Verdict: weak accept — addresses a real problem with a reasonable approach, but the novelty is incremental and the experimental validation needs to be thorough.
Takeaways
The TTT-for-memory pattern is broadly applicable: whenever you have a streaming task where the model needs to accumulate task-specific information over time, consider using fast weights that update per chunk rather than stuffing everything into a context window or fixed hidden state.
The spatial-predictive loss idea transfers to other domains: if you want a model to learn a specific type of structure (temporal, causal, hierarchical), add an auxiliary loss that explicitly tests for that structure during training.
The dual-path architecture (sliding window for local, TTT for global) is a clean way to handle multi-scale temporal reasoning. It’s worth trying in any setting where you need both short-term reactivity and long-term memory.
论文: 2603.12255 作者: Fangfu Liu, Diankun Wu, Jiawei Chi, Yimo Cai, Yi-Hsin Hung, Xumin Yu, Hao Li, Han Hu, Yongming Rao, Yueqi Duan 分类: cs.CV, cs.LG
缺口
现有视频理解模型——无论是基于 Transformer(VideoChat、Video-LLaVA)还是循环(基于 Mamba)——都将空间推理视为通用视频理解的副产品。
它们要么把帧塞进长上下文窗口(内存二次方爆炸),要么把所有东西压缩到固定大小的隐藏状态(快速遗忘几何)。两种方法都不是为了回答”在穿过建筑物 10 分钟后,椅子相对于门在哪里?“这样的问题而设计的。
具体失效模式:当视频流长且空间丰富时,这些模型要么耗尽上下文预算,要么它们的循环状态被新帧覆盖,丢失了之前看到的 3D 布局。没有机制说”这一帧包含我应该保留的深度线索”。
问题:长视频流 -> 空间信息丢失或上下文爆炸
    |
    v
假设:空间证据需要选择性、结构化的保留
    |   而不仅仅是更长的窗口或更大的隐藏状态
    v
方法:TTT 快速权重 + 空间预测损失 + 3D 卷积层
    |   权重每块更新,显式编码几何
    v
证据:视频空间问答基准 SOTA,
    |   在长时程分割上优于 Mamba/Transformer 基线
    v
结论:流式空间智能是可学习的归纳偏置,
      而不仅仅是扩展问题
增量
一句话:这篇论文之前,流式视频模型没有原则性的方式随时间积累 3D 空间证据;之后,测试时训练给了它们专用的、可更新的空间记忆。
核心机制
架构有两条并行轨道处理传入的视频块。
第一条是标准滑动窗口注意力路径——它处理相邻帧之间的局部、短程时序关系,这是 Transformer 已经擅长的事情。
第二条是 TTT(测试时训练)路径,其中称为”快速权重”的一小部分参数在每个传入块上进行梯度更新。这些快速权重就是空间记忆:它们在预训练后不会冻结,而是在视频播放时持续学习。
TTT 层内部的关键设计选择是应用为空间预测机制的 3D 时空卷积。
具体来说,模型被训练为从当前块预测被遮挡或未来的空间信号(深度、表面法线、几何对应),使用快速权重作为”我到目前为止对这个场景了解的内容”缓冲区。这个预测任务迫使快速权重编码几何,而不仅仅是外观。
训练数据也是专门构建的:作者构建了一个具有密集 3D 空间描述的数据集——不仅仅是”有一张桌子”,而是关于距离、方向和空间关系的结构化标注。这引导快速权重更新朝向几何相关特征,而不是通用视觉模式。
传入视频块
        |
        v
  +---------------------+
  | 滑动窗口            |
  | 注意力路径          | --> 局部时序关系
  +---------------------+
        |
        v
  +---------------------+
  | TTT 路径            |
  | 快速权重            | --> 空间记忆(每块更新)
  |  - 3D 卷积层        |
  |  - 空间预测损失     |
  +---------------------+
        |
        v
  空间问答答案
  (知道东西在哪里,即使是 10 分钟前的)
把它想象成一个人在穿过建筑物时构建心理地图。
滑动窗口注意力是你的即时感知——你看到当前房间并记住最后几个房间。
TTT 快速权重是你的心理地图——当你走路时,你更新关于厨房相对于入口在哪里、楼梯通向哪里、哪条走廊连接到哪里的内部模型。
当有人问”浴室在哪里?“你不需要在脑海中重放整个行走过程——你查阅一直在构建的地图。
与标准循环模型的关键区别是,地图(快速权重)通过 3D 预测损失被显式训练为编码空间结构,而不仅仅是恰好适合固定大小隐藏状态的任何东西。
关键概念
-
测试时训练(TTT)快速权重:在推理期间而不仅仅是训练期间进行梯度更新的模型参数子集。在本文中,它们被用作持久空间记忆,随着视频播放积累几何证据。“快速”部分意味着它们快速更新(每块),相比主模型权重(在预训练后保持冻结)。
-
空间预测损失:一个训练目标,迫使模型从当前视频块预测空间信号(深度、表面法线、几何对应)。这与通用重建损失不同——它专门针对几何理解。想法是,如果你能准确预测深度,你必须学到了关于 3D 结构的东西。
-
3D 时空卷积:同时在高度、宽度和时间上操作的卷积层。它在 TTT 层内部用于跨帧聚合空间证据。3D 结构很重要,因为空间关系不仅仅是 2D(左/右、上/下),还有时序(这个对象从这里移动到那里)。
框架转变
之前(主流方法):                之后(本文方法):

基于 Transformer:                Spatial-TTT:
  长上下文窗口                      滑动窗口(局部)
  (二次方内存)                    +
        |                          TTT 快速权重(全局空间)
        v                                |
  上下文填满时                           v
  空间信息丢失                      空间记忆持久
                                   (每块更新)
基于循环:
  固定隐藏状态                      空间预测损失
  (遗忘几何)                      引导记住什么
        |                                |
        v                                v
  空间信息被覆盖                    3D 结构保留
从上下文受限或健忘的模型到专用空间记忆,核心转变是:空间推理需要自己的持久、可更新表示。
专家评审
选题眼光:真实且动机充分。视频中的长时程空间推理是真正的缺口,现有模型的失效模式(上下文溢出、循环遗忘)有充分记录。时机恰当——随着具身 AI 和机器人应用的增长,空间理解变得至关重要。
方法成熟度:TTT 是一种成熟的技术;新颖性在于应用(空间记忆)和具体设计选择(3D 卷积、空间预测损失)。具有密集 3D 标注的数据集构建是扎实的工程。总体:更多应用洞察而非算法新颖性。
实验诚意:关键实验是:(1) Spatial-TTT 是否在长时程空间问答上优于基线?(2) 快速权重是否真正编码空间结构?(3) 性能如何随视频长度增加而退化?这三个都需要定量结果。如果论文包含快速权重学到什么的可视化会更强。
写作功力:摘要清晰但术语繁重(“TTT 快速权重”、“空间预测损失”)。方法部分(未完全可见)可能需要更多关于如何初始化和更新快速权重的细节。失败案例部分至关重要——什么时候会失效?(可能:严重遮挡的场景、几何变化的动态环境。)
判决:弱接收——用合理的方法解决真实问题,但新颖性是增量的,实验验证需要彻底。
要点总结
TTT 用于记忆的模式广泛适用:无论何时有流式任务,模型需要随时间积累任务特定信息,都要考虑使用每块更新的快速权重,而不是把所有东西塞进上下文窗口或固定隐藏状态。
空间预测损失想法可迁移到其他领域:如果你想让模型学习特定类型的结构(时序、因果、层次),添加一个在训练期间显式测试该结构的辅助损失。
双路径架构(局部滑动窗口、全局 TTT)是处理多尺度时序推理的干净方式。在任何需要短期反应性和长期记忆的设置中都值得尝试。