Paper: 2608.09887 Authors: Seongjin Choi Categories: cs.CV, cs.CY, cs.LG
The Gap
Football analytics has spent a decade pricing on-ball actions. Expected threat (xT) puts a value on each pitch zone and scores a pass by how much it raises your chance of scoring soon. VAEP scores every action by how it shifts both scoring and conceding probability. On-ball value models generalize this. All of them share a design commitment: value is attached to an action taken by a player with the ball.
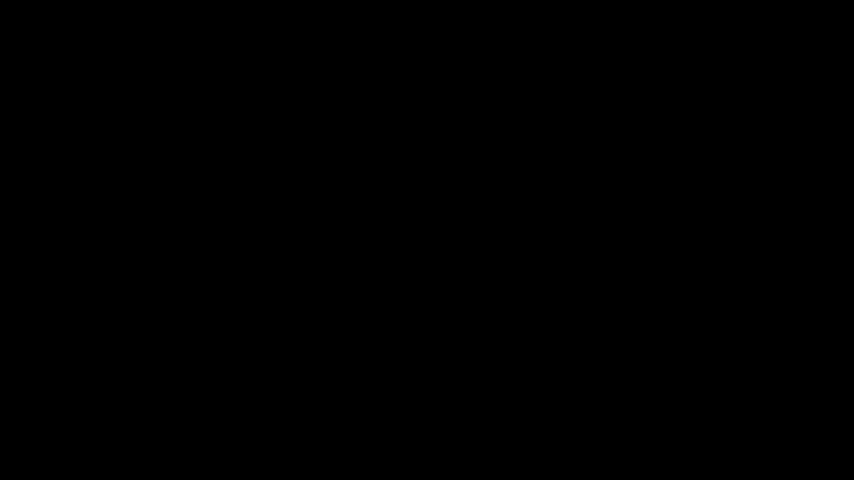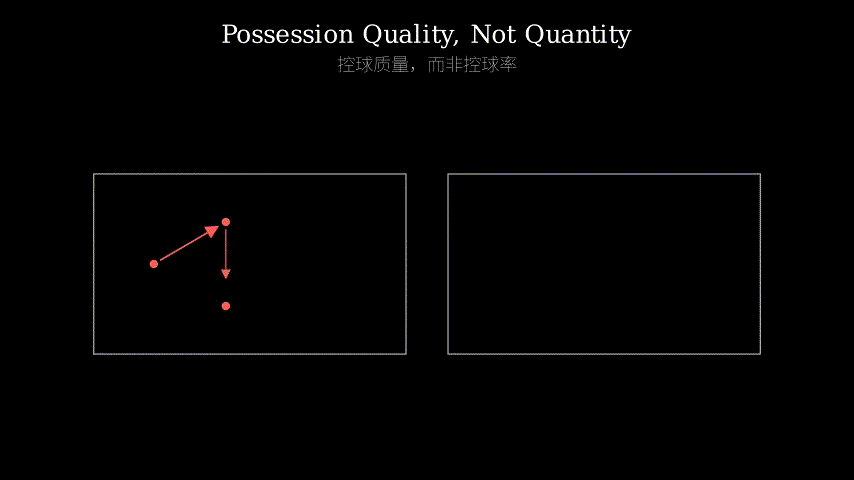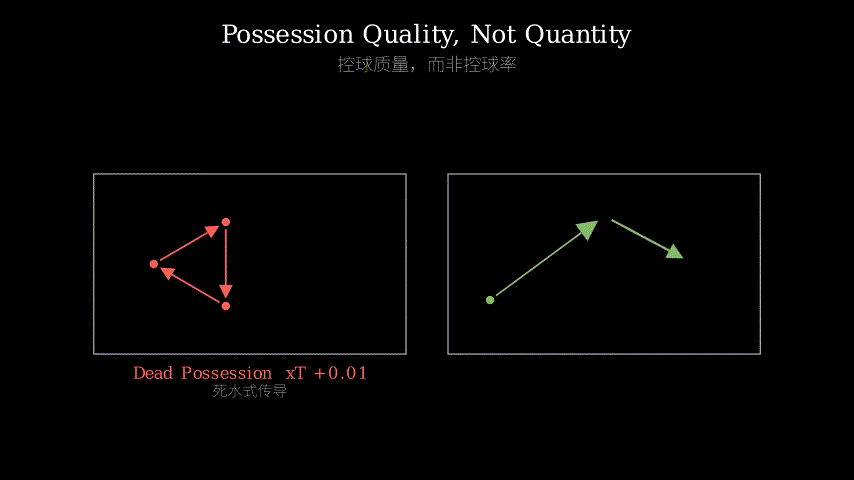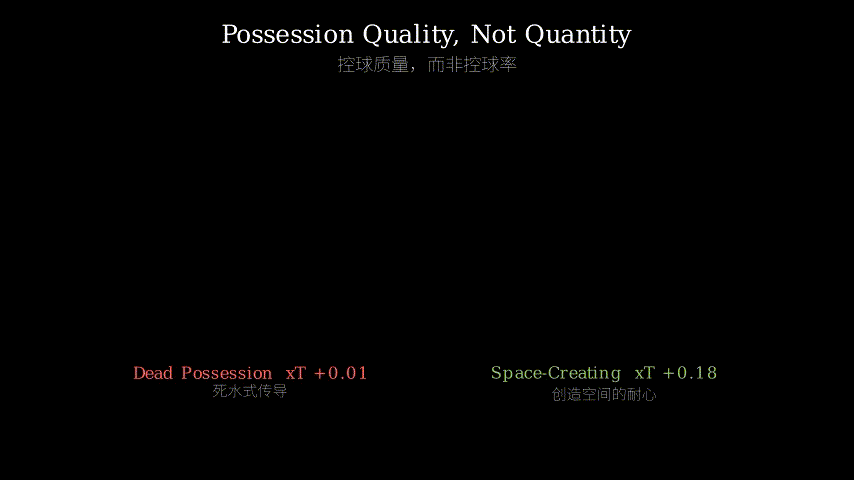
That commitment has a blind spot the broadcast audience notices constantly. A team holds 60% possession, passes 700 times, and loses. The event models say: each of those passes had near-zero value, so the possession was near-zero value. But that answer collapses two very different situations. In one, the team recycled the ball across its own back line while the opponent’s block sat comfortably at rest — nothing happened, nothing was even attempted. In the other, the team circulated patiently, pulled the opponent’s block backwards and sideways, opened a genuine channel, and then fluffed the final pass. Both score ~0 in xT/VAEP terms. Only one is a tactical failure.
Two secondary problems compound this. First, scoreline confounding: a team 2-0 up in the 80th minute *should be circulating without threat. Any index that flags low-threat possession without conditioning on game state will punish good game management. Second, data access: the off-ball question needs positional tracking data of all 22 players, which is proprietary and unavailable for most matches — including, for many analysts, World Cup matches.
The paper’s move is to answer at two layers rather than one: cheap event data screens which possessions deserve scrutiny, and expensive video-derived spatial reconstruction is spent only on those.
PROBLEM
  60% possession that loses  ==  60% possession that dominates?
  Event value models (xT / VAEP / OBV) say both are ~0 value
       |
       v
GAP
  on-ball action value  cannot  distinguish
    [spatially dead circulation]  from  [space-created, unconverted]
  plus: low threat while 2-0 up is GOOD, not junk
  plus: 22-player tracking data unavailable for broadcast matches
       |
       v
ASSUMPTION
  (A1) a possession's worth ~ peak threat gain, not sum of small passes
  (A2) game state must gate the judgment (tied-or-losing only)
  (A3) broadcast frames -> pitch coords is accurate enough
       for a NET pitch-control DELTA (not exact player positions)
       |
       v
METHOD  (two layers)
  L1 event side:  xT grid -> peak threat gain per sequence
                  -> reconstruct live scoreline
                  -> flag low-threat sequences in tied/losing states
  L2 video side:  broadcast video -> homography -> pitch coords
                  -> pitch control field -> Space-Creation Index (SCI)
                  -> classify flagged window: dead / weak / space-creating
       |
       v
EVIDENCE
  2026 WC, 103 matches, 206 team-matches
    flag vs points        r = -0.37
    flag vs xG diff       r = -0.51  (partly index-coupled)
    controlling off. VAEP + field tilt: flag p < 0.0001, VAEP n.s.
  31 of 35 flagged windows, 9 matches (purposive)
    74% non-space-creating | 19% weak progression | 6% space-creating
       |
       v
CONCLUSION
  junk-possession flag carries information the on-ball models miss;
  most flagged windows really are dead, but ~1 in 16 is a
  false accusation that only the spatial layer can acquit
The Increment
One sentence: Before, “sterile possession” was a commentator’s adjective and every low-threat possession looked identical to an event model; after, it is a two-stage measurement where event data flags the suspect sequences (net of scoreline) and broadcast video decides whether the possession was spatially dead or space-creating-but-unconverted.
Core Mechanism
Layer 1 — the event-side junk-possession index. Take a possession sequence (a team’s uninterrupted run of the ball). Overlay the standard expected-threat grid on the pitch: each cell carries a value equal to the probability of scoring within the next few actions from there. Instead of summing per-pass xT deltas — which rewards long chains of sideways passing and dilutes the signal — the index takes the peak threat gain of the sequence: how far above its starting threat did this possession ever get? A sequence that never lifts above its baseline has a peak gain near zero. Then the crucial gate: reconstruct the live scoreline at that moment from the match event feed, and only consider sequences where the team is tied or losing. A 2-0 leader passing sideways is doing its job; a 0-1 chaser passing sideways is not. Sequences that are low-peak-gain *and in a tied-or-losing state get the junk flag. Per team-match you get a flag rate: what fraction of your possession time was junk.
Layer 2 — the video-side Space-Creation Index. For a flagged window, pull the broadcast footage. Detect players, estimate the camera’s homography from pitch-line features, and project detections into pitch coordinates. This won’t give you tracking-vendor precision, and the paper doesn’t need it to: it computes a pitch control field (for each point of the pitch, which team would get there first / control it) at the start and end of the window, and takes the *net change. Did the attacking team’s controlled area grow? Did the defensive block get pushed back toward its own goal? The signed aggregate of that change is SCI. Positive and large: the possession seized space, and the event flag was a false accusation. Near zero: dead circulation, the flag was right. Slightly positive: weak progression, ambiguous.
Data flow. Cheap layer over everything (206 team-matches) to establish the flag is statistically meaningful; expensive layer over a purposive subsample (35 flagged windows, 31 usable, 9 matches) to establish the flag’s failure mode and its rate. The validation strategy is deliberately split too: layer 1 is validated statistically (does the flag predict points beyond VAEP and field tilt?), layer 2 is validated as an adjudicator (of the flagged windows, how many were miscategorized?).
                      MATCH EVENT FEED
                             |
        +--------------------+--------------------+
        |                                         |
        v                                         v
  possession sequence                      goal events
   p1 p2 p3 ... pn                              |
        |                                        v
        v                              reconstruct LIVE SCORELINE
  xT grid lookup per touch                       |
   .--------------------.                        |
   | .01 .02 .04 .09    |                        |
   | .01 .03 .06 .15    |   start xT             |
   | .01 .02 .04 .10    |   ... peak xT          |
   '--------------------'                        |
        |                                        |
        v                                        v
  PEAK THREAT GAIN = max(xT_t) - xT_start   state in \{tied, losing\}?
        |                                        |
        +------------------+---------------------+
                           v
                  LAYER 1: junk flag?
              low peak gain AND not protecting a lead
                           |
              +------------+-------------+
              |                          |
             no                         yes
              |                          |
        (ignore, fine)          BROADCAST VIDEO WINDOW
                                         |
                                         v
                            player detection + line features
                                         |
                                         v
                            homography  H : image -> pitch
                                         |
                                         v
                            22-ish points in pitch coords
                                         |
                              +----------+----------+
                              v                     v
                        pitch control          pitch control
                        field at t_start       field at t_end
                              |                     |
                              +----------+----------+
                                         v
                          SCI = net control change
                          (area seized) + (block pushed back)
                                         |
                     +-------------------+------------------+
                     v                   v                  v
              SCI ~ 0             SCI slightly +        SCI large +
           SPATIALLY DEAD       WEAK PROGRESSION     SPACE-CREATING
            (flag correct)         (ambiguous)      (flag was WRONG:
              74%                     19%          unconverted, not
                                                      sterile)  6%
Structural metaphor: a hospital triage plus imaging. Layer 1 is the triage nurse with a thermometer and a blood-pressure cuff — cheap, fast, applied to every single patient walking through the door. The thermometer here is peak threat gain; the reading “low threat” is a fever. But a fever alone doesn’t mean illness, so the nurse also asks *why you’re here: the live scoreline is the patient history. Low threat while 2-0 up is a marathon runner with a high heart rate — expected, not pathological. Low threat while chasing a deficit is a fever with no explanation, and that patient gets flagged for imaging.
Layer 2 is the MRI. It’s expensive, so you only scan flagged patients, and you accept that it’s a lower-resolution MRI than the hospital next door has (broadcast homography instead of vendor tracking) — because you’re not measuring a tumor’s exact millimeters, you’re asking a binary-ish question: is there anything there or not? Pitch control is the contrast agent that makes the invisible visible: without it, the two teams are just dots; with it, you see territory, and you can see whether the territory moved between the beginning and end of the scan. The diagnosis has three outcomes: nothing there (dead possession, the triage flag was right), something faint (weak progression), and a real finding that the thermometer alone would have misread (space-creating but unconverted — the patient was actually doing fine, the fever was a red herring).
The metaphor also explains the paper’s validation split, which is otherwise odd-looking. You validate a triage protocol by asking whether flagged patients have worse outcomes on average (flag vs points, r = -0.37, and it survives controlling for the incumbent test). You validate imaging by asking what fraction of flagged patients turn out to have been misdiagnosed (6%). Those are different questions and they need different sample sizes — hence 206 team-matches for one and 31 windows for the other.
Key Concepts
-
Expected threat (xT), and why “peak” beats “sum”: Imagine a heat map of the pitch where each square says “if your team has the ball here, what’s the chance you score in the next few touches?” Near your own corner flag: about 1%. Edge of the opponent’s box: maybe 15%. A pass’s xT value is just the difference between the two squares. Now, the natural way to price a possession is to add up all those differences — but that’s a trap. Twenty sideways passes each worth +0.001 and -0.001 sum to noise, and a possession that surged to the edge of the box and then lost the ball can end up summing to roughly the same as one that never left the halfway line. Taking the peak instead asks a sharper question: at its best moment, how dangerous did this possession ever become? A possession that never got dangerous *at any instant is a different animal from one that got dangerous and then broke down. That single design choice is what makes the junk flag meaningful.
-
Pitch control: Take a photo of all 22 players. For every point on the grass, ask: if a loose ball appeared right here, which team would get to it first? Factor in where each player is, which way they’re moving, and how fast. Colour the point by whichever team wins. Now the pitch is painted in two colours, and each team’s painted area is its *controlled space. This is the key trick, because it converts positions (a list of coordinates that tells you nothing on its own) into territory (an area you can measure and compare). Crucially, it doesn’t need perfect coordinates — if a player is off by two metres, the boundary of their painted region shifts slightly, but the overall territorial picture survives. That robustness is exactly why the authors can get away with broadcast video instead of vendor tracking.
-
Space-Creation Index (SCI) as a delta, not a level: The insight is measuring *change, not state. A team’s controlled area at one instant tells you little — it depends on the formation, the phase of play, whether it’s a set piece. But if you paint the pitch at the start of a possession window and again at the end, the difference answers the tactical question directly: did this circulation take territory, or shove the opponent’s block backwards toward its own goal? Taking a delta also cancels a lot of measurement bias — systematic errors in the homography that inflate one team’s area at t_start tend to inflate it at t_end too, so they subtract out. This is the same logic as difference-in-differences in econometrics, or A/B testing against a pre-period baseline: you don’t need an accurate absolute meter, you need a consistent one.
Framework Shift
Before (mainstream approach):            After (this paper):

  event stream                            event stream
       |                                       |
       v                                       v
  price each ON-BALL action              price each SEQUENCE by
  (xT delta, VAEP, OBV)                  PEAK threat gain
       |                                       |
       v                                  gate by LIVE SCORELINE
  sum over possession                     (tied or losing only)
       |                                       |
       v                                       v
  ONE number                             junk flag  (cheap, all matches)
       |                                       |
       v                                  +----+ flagged? ----+
  low value                               |                   |
       |                                 no                  yes
       v                                  |                   |
  "sterile possession"                 done            BROADCAST VIDEO
  (a single bucket,                                          |
   no way to look inside)                                    v
                                                    project to pitch coords
   +-----------------------------+                           |
   | dead circulation            |                           v
   | space-created-unconverted   |   <-- collapsed     pitch control DELTA
   | good game management        |       together             |
   +-----------------------------+                            v
                                                    +---------+---------+
   value lives on THE BALL                          v         v         v
                                                  dead      weak     space-
                                                 (74%)     (19%)   creating
                                                                     (6%)

                                                    value lives in
                                                    THE SPACE, and
                                                    cheap screen gates
                                                    expensive measurement
One sentence: From “price the actions the ball took” to “screen possessions cheaply by scoreline-adjusted peak threat, then spend expensive spatial measurement only on the suspects,” the core shift is treating possession quality as a *two-stage diagnosis of space rather than a one-stage sum of on-ball value.
Expert Assessment
Problem choice: Real gap, and a well-chosen one. The off-ball blind spot in xT/VAEP is genuinely acknowledged in the field, and the usual answer — “get tracking data” — is unavailable to most of the world, including anyone analyzing a World Cup from television. Framing it as *triage plus imaging rather than “let’s build a better tracking pipeline” is the smart part; it makes the problem tractable without pretending broadcast video is as good as vendor data. The scoreline gate is not a flashy contribution but it is the difference between a usable index and one that punishes teams for competently seeing out a win, and I suspect it’s the most immediately reusable piece here. Where it sits in the trajectory: this is a bridging paper between the mature event-value literature and the still-immature broadcast-vision literature, and bridging papers tend to be undervalued at review time and overcited later.
Method maturity: Clever assembly of existing parts rather than new machinery. xT grids, pitch control, and homography-based pitch projection are all off the shelf; the contributions are the peak-gain-instead-of-sum choice, the scoreline gate, the delta formulation of SCI, and the triage architecture. That’s a respectable set of design decisions, not a new model. The delta framing is the single best idea in the paper because it buys robustness to exactly the measurement error broadcast video introduces. What’s under-explored: simpler baselines that might get most of the way there. Field tilt (share of final-third touches) is used as a control but not really pushed as a competitor, and things like a “possession that never entered the final third” counter, defensive-line height, or opponent block depth from a single frame are cheap and might capture much of SCI. If a one-frame heuristic recovers 80% of the three-way classification, the pitch-control machinery is decoration, and the paper doesn’t rule this out. Also unaddressed: broadcast footage systematically fails to show off-camera players, and pitch control over the visible subset is a biased estimate of pitch control — the delta cancels *some of that, but not the part that correlates with the camera panning toward wherever the action is going, which is precisely the space-creation signal.
Experimental integrity: Mixed, and honestly labelled, which counts for something. The strong part is the regression: holding offensive VAEP and field tilt fixed, the junk flag stays significant at p < 0.0001 with match-clustered errors while VAEP doesn’t. That’s the load-bearing evidence for “not a repackaging of on-ball value,” and clustering by match is the right call. Three caveats. (1) The author flags r = -0.51 with xG difference as “partly index-coupled,” and that’s the right disclosure, but it means the headline correlations are softer than they look; the r = -0.37 with points is the honest number and it is modest. (2) The regression is explicitly same-match and descriptive — the paper says so — which means we’re looking at within-match association, not a claim that reducing your junk rate next week earns points. Anyone quoting this as causal is misreading it. (3) Layer 2’s sample is 31 windows from 9 matches, purposively chosen. The 74/19/6 split is therefore an illustration of the failure mode, not an estimate of its rate; the 6% figure especially rests on roughly two windows. With n that small, the honest statement is “the false-accusation category exists and is uncommon,” which is a real finding, just a much weaker one than a percentage implies. There’s also no inter-rater or ground-truth check on the SCI classification against actual tracking data for even a handful of windows, and that comparison — even on ten windows from a league where tracking exists — would have been the cheapest large upgrade in credibility available.
Writing quality: The abstract is dense but genuinely informative, and the author’s willingness to pre-emptively label the coupling and the purposive sampling is better epistemic hygiene than most papers in this space. The corners cut are in layer 2. Homography estimation quality, occlusion handling, what happens when players are off-frame, the SCI thresholds separating “dead” from “weak” from “space-creating” — these are described at a level that would not survive a replication attempt, and the three-way classification thresholds are doing enormous work in producing the 74/19/6 headline. Rewriting the layer-2 methods section with explicit error characterization and threshold sensitivity would lift this from an interesting demo to something people can build on. The World Cup penalty-exit anecdote (73% possession, two non-creating windows) is a good rhetorical hook but it’s an anecdote, and it’s placed where a reader might mistake it for evidence.
Verdict: weak accept — the two-layer triage architecture and the scoreline gate are genuinely useful contributions that get past a real limitation in event-value models, but layer 2’s evaluation is too thin (31 purposive windows, no tracking-data ground truth, undocumented thresholds) to support the classification percentages it reports.
Takeaways
Things worth stealing, in rough order of transferability:
The triage architecture is domain-general. When you have a cheap signal available everywhere and an expensive signal available rarely, don’t choose between them — use the cheap one as a *screen and spend the expensive one only on flagged cases. Then validate them differently: the screen on whether flags predict bad outcomes at scale, the expensive measurement on what fraction of flags it overturns. This is exactly how you’d combine a cheap heuristic with an LLM judge, or logs with tracing, or static analysis with fuzzing. Most papers pick one layer and defend it; the two-layer split with two validation strategies is the reusable move.
Peak instead of sum, when you’re pricing an episode. Summing per-step values over a long episode dilutes signal and lets many neutral steps swamp one decisive one. If the question is “did this episode ever reach a good state?”, take the max, not the total. Directly applicable to summarizing agent trajectories, session quality metrics, and any place you currently average over a variable-length sequence.
Gate your metric by context before you interpret it. Low threat while leading 2-0 is correct behaviour; the raw metric can’t tell. Reconstructing the live game state and conditioning on it is the whole reason the index isn’t garbage. The general form: before flagging a low value as bad, reconstruct what the agent was *trying to do at that moment and exclude the cases where low is optimal. Latency metrics, cost metrics, and engagement metrics all have this problem and rarely get this treatment.
Measure deltas to survive bad instruments. SCI works on broadcast video not because the projection is accurate but because systematic error largely cancels between t_start and t_end. If your measurement instrument is biased but *consistently biased, a before/after difference is trustworthy where an absolute level is not. This is the single most portable technical idea in the paper.
A caution worth internalizing too: the paper’s own structure shows how a three-way percentage split (74/19/6) can be computed from ~31 purposively chosen samples and then read by everyone downstream as a population rate. If you steal the architecture, don’t steal that presentation.
论文: 2608.09887 作者: Seongjin Choi 分类: cs.CV, cs.CY, cs.LG
缺口
足球数据分析花了十年时间在给「持球动作」定价。
xT(预期威胁)给球场每个格子一个价值——从这里持球,接下来几脚内进球的概率是多少——一次传球的价值就是两个格子的差值。 VAEP 则给每个动作打分,同时考虑它对进球概率和失球概率的影响。 on-ball value 是同一思路的推广。
它们共享一个设计承诺:价值挂在持球球员的动作上。
这个承诺有一个连电视观众都能天天察觉的盲区。 一支球队控球 60%,传了 700 次,输了球。 事件模型说:这些传球每一脚价值都接近零,所以这段控球价值接近零。 但这个回答把两种完全不同的情况压成了一坨。
第一种:球队在自家后场倒脚,对手的防守阵型舒舒服服地站着不动,什么都没发生,甚至什么都没尝试。 第二种:球队耐心传导,把对手的防线拽向后方和侧向,真的撕开了一条通道,然后最后一传打飞了。
在 xT / VAEP 眼里两者都约等于 0。 但只有一种是战术失败。
还有两个次级问题让事情更麻烦。
第一是比分混淆:一支 80 分钟 2-0 领先的球队,本来就**应该*没有威胁地倒脚。 任何不区分比赛状态就标记「低威胁控球」的指标,都会惩罚正确的比赛管理。
第二是数据可得性:回答无球问题需要 22 名球员的位置追踪数据,而这类数据是商业专有的,绝大多数比赛拿不到——包括对很多分析者而言的世界杯比赛。
论文的解法是分两层回答而不是一层:廉价的事件数据负责筛出哪些控球值得细看,昂贵的视频空间重建只花在这些嫌疑对象上。
PROBLEM
  输球的 60% 控球  ==  压制对手的 60% 控球?
  事件价值模型 (xT / VAEP / OBV) 说:两者价值都约为 0
       |
       v
GAP
  持球动作价值  无法区分
    [空间上的死水传导]  vs  [创造了空间但没转化]
  另外: 2-0 领先时低威胁是 GOOD,不是垃圾
  另外: 转播比赛拿不到 22 人追踪数据
       |
       v
ASSUMPTION
  (A1) 一段控球的价值 ~ 峰值威胁增益,而非小额传球之和
  (A2) 判断必须由比赛状态把关(只看平局或落后)
  (A3) 转播画面 -> 球场坐标 的精度,
       足够支撑一个「净控制区变化量」(不需要精确球员位置)
       |
       v
METHOD  (两层)
  L1 事件层: xT 网格 -> 每段序列的峰值威胁增益
             -> 重建实时比分
             -> 标记平局/落后状态下的低威胁序列
  L2 视频层: 转播视频 -> 单应变换 -> 球场坐标
             -> 控制区场 -> 空间创造指数 (SCI)
             -> 给被标记窗口分类: 死水 / 弱推进 / 创造空间
       |
       v
EVIDENCE
  2026 世界杯, 103 场, 206 个队-场次
    标记率 vs 积分        r = -0.37
    标记率 vs xG 差       r = -0.51 (部分与指标耦合)
    控制进攻 VAEP + 场地倾斜后: 标记 p < 0.0001, VAEP 不显著
  35 个被标记窗口中的 31 个, 9 场比赛 (目的性抽样)
    74% 非创造空间 | 19% 弱推进 | 6% 创造空间
       |
       v
CONCLUSION
  垃圾控球标记携带了持球模型漏掉的信息;
  大多数被标记窗口确实是死水,但约十六分之一是
  冤案——只有空间层能替它翻案
增量
一句话:以前「无效控球」只是解说词,任何低威胁控球在事件模型眼里长得一模一样;现在它变成了一套两级测量——事件数据(扣除比分因素后)筛出嫌疑序列,转播视频判定这段控球到底是空间上的死水,还是创造了空间只是没转化。
核心机制
第一层——事件侧的垃圾控球指标。 取一段控球序列(球队不间断持球的一段)。 在球场上铺开标准的 xT 网格:每个格子的值等于从这里出发在接下来几脚内进球的概率。
关键在于,它不去累加每脚传球的 xT 增量——那样会奖励一长串横向传球,把信号稀释掉——而是取这段序列的峰值威胁增益:这段控球最危险的那一刻,比起点高出了多少? 一段从头到尾没有超过基线的序列,峰值增益接近零。
然后是那道关键的闸门:从比赛事件流中重建那一刻的实时比分,只考虑球队处于平局或落后的序列。 2-0 领先横向倒脚是在做正确的事;0-1 落后横向倒脚不是。 同时满足「低峰值增益」和「平局或落后」的序列拿到垃圾标记。 每个队-场次得到一个标记率:你的控球时间里有多少比例是垃圾。
第二层——视频侧的空间创造指数。 对一个被标记的窗口,调出转播画面。 检测球员,从球场线条特征估计摄像机的单应矩阵,把检测结果投影到球场坐标。
这达不到商业追踪供应商的精度,而论文并不需要那种精度:它计算窗口开始和结束时刻的控制区场(球场每个点上,哪支球队会先到达/控制它),然后取**净变化量*。 进攻方控制的面积变大了吗?防守阵型被推回自家球门方向了吗? 这个变化量的带符号总和就是 SCI。
数值大而正:这段控球夺取了空间,事件层的标记是冤案。 接近零:死水传导,标记是对的。 略微为正:弱推进,含糊地带。
数据流。 廉价层跑全量(206 个队-场次),用来确立标记在统计上有意义;昂贵层跑一个目的性子样本(35 个被标记窗口,31 个可用,9 场比赛),用来确立标记的失效模式及其发生率。
验证策略也是刻意分开的:第一层用统计验证(标记率能否在控制 VAEP 和场地倾斜后仍预测积分?),第二层当作裁判来验证(被标记的窗口里,有多少被误判了?)。
                      比赛事件流
                             |
        +--------------------+--------------------+
        |                                         |
        v                                         v
     控球序列                                  进球事件
   p1 p2 p3 ... pn                                |
        |                                         v
        v                                   重建实时比分
   每次触球查 xT 网格                             |
   .--------------------.                         |
   | .01 .02 .04 .09    |                         |
   | .01 .03 .06 .15    |   起点 xT               |
   | .01 .02 .04 .10    |   ... 峰值 xT           |
   '--------------------'                         |
        |                                         |
        v                                         v
  峰值增益 = max(xT_t) - xT_start        状态 in \{平局, 落后\}?
        |                                         |
        +------------------+----------------------+
                           v
                   LAYER 1: 是否标记?
              低峰值增益 AND 不是在保护领先
                           |
              +------------+-------------+
              |                          |
             no                         yes
              |                          |
        (忽略, 正常)              转播视频窗口
                                         |
                                         v
                             球员检测 + 球场线条特征
                                         |
                                         v
                             单应变换  H : 图像 -> 球场
                                         |
                                         v
                             约 22 个点的球场坐标
                                         |
                              +----------+----------+
                              v                     v
                        t_start 时刻            t_end 时刻
                        的控制区场              的控制区场
                              |                     |
                              +----------+----------+
                                         v
                           SCI = 净控制区变化
                        (夺取的面积) + (阵型被推回的量)
                                         |
                     +-------------------+------------------+
                     v                   v                  v
              SCI ~ 0             SCI 略正             SCI 明显正
            空间上的死水            弱推进            创造了空间
            (标记正确)             (含糊)          (标记错了: 是
              74%                    19%           没转化, 不是无效)
                                                          6%
核喻:医院的分诊台 + 影像科。
第一层是拿着体温计和血压计的分诊护士——便宜、快,对每一个走进门的病人都做。 这里的体温计是峰值威胁增益,读数「低威胁」就是发烧。
但光有发烧不等于有病,所以护士还要问你为什么来:实时比分就是病史。 2-0 领先时的低威胁,等于马拉松选手心率高——正常,不是病理。 落后追分时的低威胁,是没有解释的发烧,这个病人被开单去做影像。
第二层是 MRI。 它很贵,所以只扫被标记的病人;而且要接受它是一台分辨率更低的 MRI(转播单应变换而非供应商追踪数据)——因为你不是在量肿瘤的精确毫米数,你问的是一个近乎二元的问题:里面到底有没有东西。
控制区场是让不可见变可见的显影剂:没有它,两队只是一堆点;有了它,你看到的是领土,而且能看出这片领土在扫描的头尾之间有没有移动。
诊断有三种结果:什么都没有(死水控球,分诊标记是对的)、有一点微弱迹象(弱推进)、以及一个体温计本来会误读的真实发现(创造了空间但没转化——病人其实状态不错,发烧是个误导)。
这个核喻还顺带解释了论文那个乍看有点怪的验证结构。 你验证一套分诊流程,是问被标记的病人平均结局是否更差(标记率 vs 积分,r = -0.37,且在控制现有检验后仍成立)。 你验证影像科,是问被标记的病人里有多大比例最终被证明误诊(6%)。
这是两个不同的问题,需要不同的样本量——所以一边是 206 个队-场次,一边是 31 个窗口。
关键概念
- 预期威胁 (xT),以及为什么「峰值」优于「求和」: 想象球场的一张热力图,每个方格写着「如果你的球队在这里持球,接下来几脚内进球的概率是多少」。 自家角旗附近:大约 1%。 对手大禁区边缘:可能 15%。 一次传球的 xT 价值就是两个方格的差。
那么给一段控球定价最自然的方式是把这些差值全加起来——但这是个陷阱。 二十次横传,各值 +0.001 和 -0.001,加起来就是噪声;而一段冲到大禁区边缘然后丢球的控球,总和可能和一段从没过中线的控球差不多。
改取峰值问的是一个更锋利的问题:这段控球在它最好的那一瞬间,究竟变得多危险? 一段在任何时刻都没有变危险的控球,和一段变危险了然后崩掉的控球,是两种不同的动物。 这一个设计选择,就是垃圾标记之所以有意义的原因。
- 控制区 (pitch control): 给 22 名球员拍一张照。 对草皮上每一个点问:如果此刻这里冒出一颗无主球,哪支球队会先碰到? 把每名球员的位置、移动方向、速度都算进去。 谁赢就把这个点涂成谁的颜色。
现在球场被涂成两种颜色,每队涂到的面积就是它的控制空间。
这是关键的一招,因为它把位置(一串坐标,本身什么都说明不了)转换成了领土(一个可以测量和比较的面积)。 更重要的是,它不需要完美的坐标——某个球员偏了两米,他那块涂色区的边界会稍微挪一点,但整体的领土格局仍然成立。
正是这种鲁棒性,让作者可以用转播视频而不是供应商追踪数据蒙混过关。
- SCI 是差分量而不是水平量: 洞见在于测量变化,而不是状态。 一支球队在某个瞬间的控制面积告诉你的很少——它取决于阵型、比赛阶段、是不是定位球。
但如果你在一段控球窗口的开头涂一次球场、结尾再涂一次,那个差就直接回答了战术问题:这段传导有没有夺取领土,有没有把对手的阵型推回它自家球门方向?
取差分还抵消了大量测量偏差——单应变换里那些在 t_start 高估某队面积的系统性误差,在 t_end 大概也在高估,于是相减时抵消掉了。
这和计量经济学里的双重差分、或者拿前期基线做 A/B 测试是同一个逻辑:你不需要一把绝对准确的尺,你需要的是一把一致的尺。
框架转变
之前(主流方法):                     之后(本文方法):

  事件流                                  事件流
       |                                       |
       v                                       v
  给每个持球动作定价                   按序列的「峰值威胁增益」定价
  (xT 增量, VAEP, OBV)                        |
       |                                  由实时比分把关
       v                                  (只看平局或落后)
  在控球段上求和                               |
       |                                       v
       v                             垃圾标记 (便宜, 全量比赛)
   一个数字                                    |
       |                                  +----+ 被标记? ----+
       v                                  |                  |
   价值低                                 no                 yes
       |                                  |                  |
       v                                完事            转播视频
  「无效控球」                                              |
  (一个桶,                                                  v
   没法往里看)                                       投影到球场坐标
                                                            |
   +-----------------------------+                          v
   | 死水传导                    |                   控制区「差分」
   | 创造空间但没转化            |  <-- 全被压         |
   | 优秀的比赛管理              |      在一起          v
   +-----------------------------+              +---------+---------+
                                                v         v         v
   价值住在「球」上                            死水      弱推进   创造空间
                                               (74%)     (19%)     (6%)

                                                价值住在「空间」里,
                                                廉价筛查为昂贵测量
                                                把关
一句话:从「给球走过的动作定价」到「用比分校正后的峰值威胁做廉价筛查,再把昂贵的空间测量只花在嫌疑对象上」,核心转变是把控球质量当成一次**关于空间的两级诊断*,而不是一次持球价值的求和。
专家评审
选题眼光:真缺口,而且选得好。
xT / VAEP 的无球盲区在这个领域是被公认的,而通常的答案——「去搞追踪数据」——对世界上大多数人不可得,包括任何从电视上分析世界杯的人。 把问题框成分诊 + 影像而不是「我们来做一条更好的转播视觉流水线」,是聪明的地方;它让问题变得可解,同时没有假装转播视频和供应商数据一样好。
比分闸门不是什么华丽的贡献,但它是「可用的指标」和「惩罚球队称职地守住胜利」之间的分界线,我怀疑它是这篇论文里最容易被直接复用的一块。
位置上,这是一篇桥接论文,连接成熟的事件价值文献和仍不成熟的转播视觉文献——而桥接论文往往在评审时被低估、在日后被高估地引用。
方法成熟度:是对现有零件的巧妙组装,不是新机器。
xT 网格、控制区、基于单应变换的球场投影都是现成的;贡献在于「取峰值而非求和」的选择、比分闸门、SCI 的差分化表述,以及分诊式架构。 这是一组值得尊重的设计决策,不是一个新模型。
差分表述是全文最好的一个想法,因为它恰好买来了对转播视频引入的那种测量误差的鲁棒性。
被探索不足的地方:可能已经走完大半路程的更简单基线。 场地倾斜(final-third 触球占比)被当作控制变量用了,但没有被真正推上来当竞争者;类似「这段控球从未进入前场三区」的计数器、防线高度、从单帧读出的对手阵型深度,都很便宜,可能捕捉了 SCI 的大部分信息。 如果一个单帧启发式能复原三分类的 80%,那控制区那套机器就是装饰——而论文没有排除这一点。
另一个未处理的问题:转播画面系统性地拍不到镜头外的球员,而在可见子集上算控制区,是控制区的一个有偏估计。 差分能抵消一部分,但抵消不了那部分与「镜头正在朝着进攻要去的方向摇」相关的偏差——而那恰恰就是空间创造的信号本身。
实验诚意:好坏参半,但作者标注得诚实,这一点值得加分。
强的部分是回归:在控制进攻 VAEP 和场地倾斜后,垃圾标记在 match-clustered 标准误下仍然 p < 0.0001 显著,而 VAEP 不显著。 这是「不是持球价值的重新包装」这一论断的承重证据,而按比赛聚类是正确的做法。
三个保留意见。
(1) 作者主动标注了 r = -0.51 与 xG 差的相关「部分与指标耦合」,这个披露是对的,但它也意味着头条相关系数比看起来要软;r = -0.37 与积分的相关才是诚实的那个数,而它只是中等。
(2) 回归被明确说明是同场次、描述性的——论文自己讲了——这意味着我们看到的是场内关联,不是「下周降低你的垃圾率就能多拿分」的因果主张。 任何把这个当因果引用的人都读错了。
(3) 第二层的样本是 9 场比赛里的 31 个窗口,目的性挑选。 所以 74/19/6 这个划分是失效模式的一次示例,不是其发生率的估计;尤其 6% 这个数字大概建立在两个窗口上。 在这么小的 n 下,诚实的说法是「冤案这一类别存在,且不常见」——这仍是个真实发现,只是比一个百分比暗示的要弱得多。
另外,全文没有把 SCI 分类与真实追踪数据做过任何对照检验,哪怕只对几个窗口做——而这个对照(即便只是在有追踪数据的联赛里取十个窗口)本来是可得的、性价比最高的一次可信度升级。
写作功力:摘要密度高但信息量真实,而且作者愿意主动标注耦合和目的性抽样,这份认识论卫生比这个领域大多数论文要好。
偷懒的地方在第二层。 单应变换的估计质量、遮挡处理、球员出画怎么办、区分「死水 / 弱推进 / 创造空间」的 SCI 阈值——这些描述的详细程度撑不起一次复现尝试,而那三分类阈值在生产 74/19/6 这个头条数字时承担了巨大的工作量。
把第二层的方法节重写一遍,加上明确的误差刻画和阈值敏感性分析,能把这篇从一个有意思的 demo 提升到别人可以在上面搭建的东西。
那个世界杯点球淘汰的轶事(73% 控球,两个非创造窗口)是个好的修辞钩子,但它就是个轶事,而且被放在了读者可能误认为它是证据的位置。
判决:弱接收 —— 两层分诊架构和比分闸门是真正有用的贡献,绕过了事件价值模型的一个真实局限;但第二层的评估太薄(31 个目的性窗口、没有追踪数据作为 ground truth、阈值未记录),撑不起它报告的那些分类百分比。
要点总结
值得「偷」的东西,大致按可迁移性排序。
分诊架构是跨领域通用的。 当你有一个到处都有的廉价信号和一个很少能拿到的昂贵信号时,不要在两者之间选择——用廉价的做筛查,把昂贵的只花在被标记的案例上。 然后用不同方式验证它们:筛查层验证「标记是否在规模上预测坏结局」,昂贵层验证「它推翻了多大比例的标记」。
这正是你该怎么把廉价启发式和 LLM judge 结合、怎么把日志和 tracing 结合、怎么把静态分析和 fuzzing 结合。 大多数论文选一层然后为它辩护;两层拆分加两套验证策略才是可复用的那一招。
给一段「情节」定价时,取峰值而不是求和。 在长情节上累加每步价值会稀释信号,让许多中性步骤压过一个决定性步骤。 如果问题是「这段情节有没有曾经到达过一个好状态」,取 max,不要取 total。
这直接适用于总结 agent 轨迹、会话质量指标,以及任何你现在在对变长序列做平均的地方。
解读指标之前,先按上下文给它把关。 2-0 领先时的低威胁是正确行为,原始指标区分不出来。 重建实时比赛状态并以它为条件,是这个指标不至于变成垃圾的全部原因。
通用形式:在把一个低值判为坏之前,先重建 agent 在那一刻想做什么,把「低就是最优」的情况排除掉。 延迟指标、成本指标、参与度指标都有这个毛病,而且很少得到这种处理。
测差分,从而在烂仪器上活下来。 SCI 能在转播视频上工作,不是因为投影准,而是因为系统性误差在 t_start 和 t_end 之间大体抵消了。 如果你的测量工具有偏但一致地有偏,那么前后差是可信的,而绝对水平不可信。
这是全文最可携带的一个技术想法。
还有一个值得内化的警示:这篇论文自己的结构就展示了,一个三分类百分比(74/19/6)可以从约 31 个目的性挑选的样本算出来,然后被下游所有人读成一个总体发生率。 如果你要偷这个架构,不要连这种呈现方式一起偷。