Paper: 2605.12466 Authors: Jacob Fein-Ashley, Paria Rashidinejad Categories: cs.LG, cs.AI, cs.CL, cs.NE
The Gap
Looped Transformers promise iterative refinement for better reasoning, but they hit three walls: training instability from backpropagating through many recurrent steps, memory cost that scales linearly with loop depth, and the need to pick a fixed recurrence depth upfront. Prior work either uses shallow loops (limiting expressiveness) or deep loops (exploding memory and gradients). The field has been stuck choosing between stability and depth.
Problem: Recurrent models need depth but can't afford it
   |
   v
Assumption: What if we never unroll the loop explicitly?
   |
   v
Method: Solve for fixed point implicitly, differentiate through equilibrium
   |
   v
Evidence: 46.6% perplexity gain, 91.4% on Sudoku-Extreme with 27M params
   |
   v
Conclusion: Recurrence becomes learnable computation, not architectural burden
The Increment
One sentence: Before this paper, iterative refinement meant choosing between shallow loops (weak) or deep loops (expensive); after, models learn to internalize iteration into a single equilibrium-seeking step with adaptive depth and constant memory.
Core Mechanism
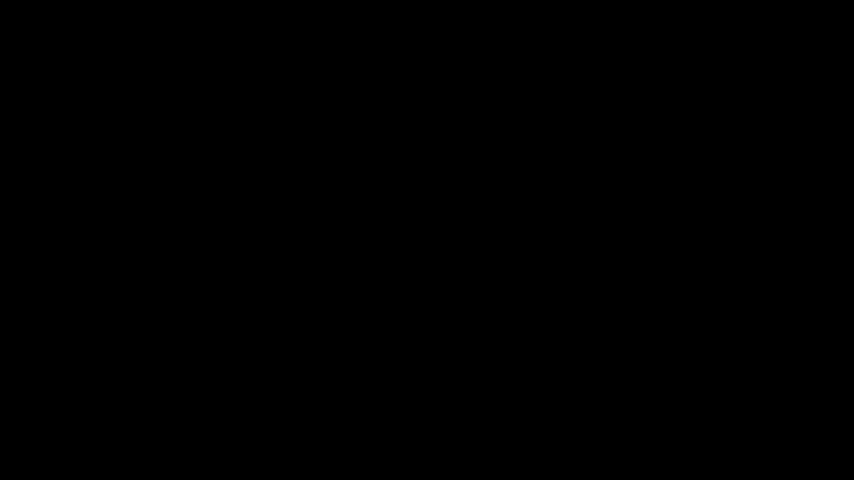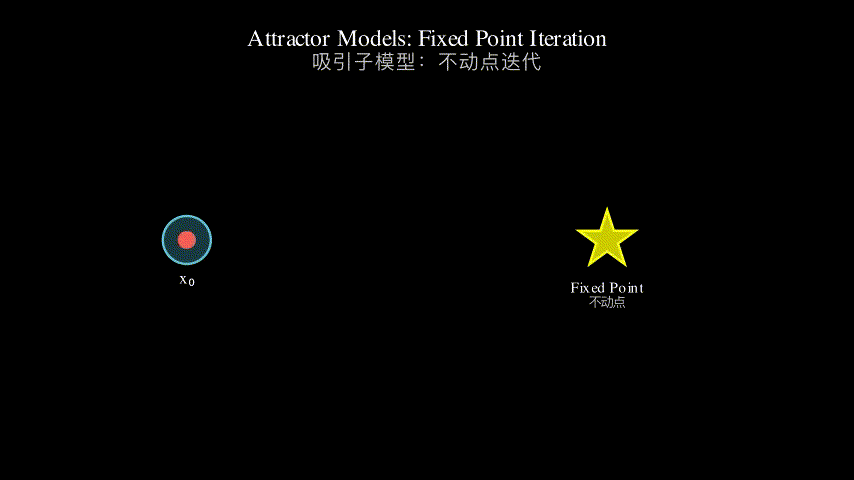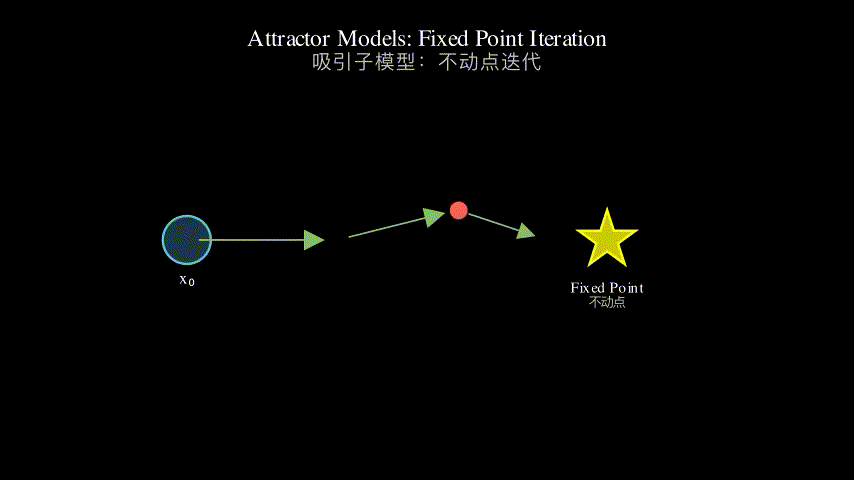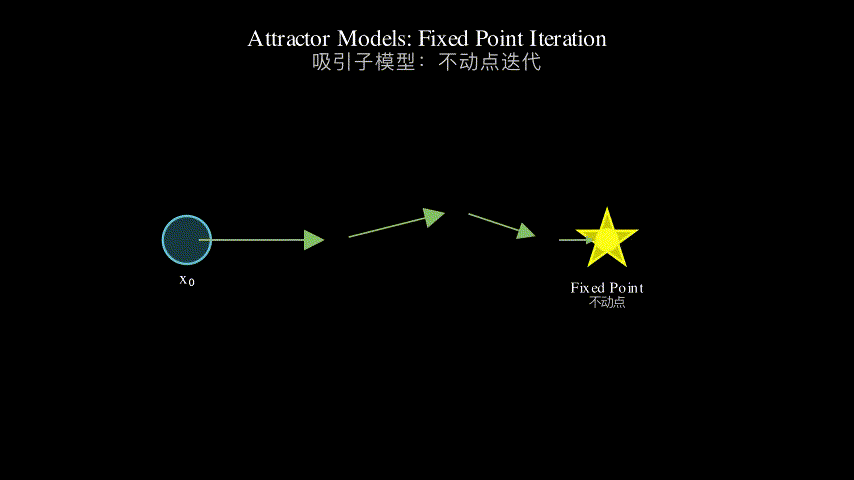
Attractor Models split computation into two phases. First, a backbone module (standard Transformer) produces an initial output embedding. Second, an attractor module treats this embedding as the starting point of a dynamical system and solves for its fixed point—the state where further iteration produces no change. Instead of unrolling T explicit recurrent steps and backpropagating through all of them, the model uses implicit differentiation: compute gradients at the converged equilibrium without storing intermediate states.
The attractor module is a small network (often just 2-4 layers) that takes the current embedding and outputs a refined version. At training time, a root-finding solver (like Anderson acceleration or Broyden’s method) iterates this module until convergence, typically 5-20 steps. Crucially, gradients flow backward through the equilibrium condition itself, not through the solver’s trajectory. This keeps memory constant regardless of how many iterations the solver takes.
Input tokens
     |
     v
[Backbone Transformer] -----> initial embedding z_0
     |                              |
     |                              v
     |                    [Attractor Module]
     |                         |        ^
     |                         |        |
     |                         v        |
     |                    z_t+1 = f(z_t) (iterate until z* = f(z*))
     |                              |
     |                              v
     +------------------------> fixed point z*
                                    |
                                    v
                              Output logits
Think of it like a sculptor and a polisher. The backbone is the sculptor—it quickly shapes the rough form from raw marble (input tokens). The attractor is the polisher—it takes that rough form and iteratively smooths it until no more refinement is needed, stopping automatically when the surface stops changing. Traditional looped models are like telling the polisher “make exactly 10 passes,” wasting effort if it converges in 5 or failing if it needs 15. Attractor Models instead say “polish until smooth,” and the sculptor learns to carve forms that need less polishing over time. Eventually, the sculptor gets so good that the polisher barely needs to run—this is equilibrium internalization.
Key Concepts
-
Fixed Point: Imagine a function that takes a number and outputs a new number. A fixed point is an input where the output equals the input—applying the function again changes nothing. For example, if f(x) = x/2 + 1, then x=2 is a fixed point because f(2) = 2/2 + 1 = 2. In Attractor Models, the attractor module is this function, and the fixed point is the “final” embedding where further refinement is unnecessary. The model learns to make its attractor module have a useful fixed point for each input.
-
Implicit Differentiation: Normally, to compute gradients through a loop, you store every intermediate state (memory scales with loop depth). Implicit differentiation is a mathematical trick: if you know the final equilibrium satisfies z** = f(z*), you can compute gradients with respect to z* by differentiating this equilibrium equation directly, without storing the path taken to reach z*. It’s like knowing the summit of a mountain and computing the slope there, without recording every step of the climb.
-
Equilibrium Internalization: During training, the model sees many examples where the backbone’s initial output gets refined by the attractor. Over time, the backbone learns to produce outputs already near equilibrium—the attractor has less work to do. Eventually, the backbone’s output is so close to the fixed point that you can skip the attractor entirely at inference with minimal accuracy loss. The model has “internalized” the iterative refinement into its feedforward pass.
Framework Shift
Before (Looped Transformers):        After (Attractor Models):

Input                                Input
  |                                    |
  v                                    v
[Layer 1] --+                        [Backbone] --> z_0
  |         |                          |
  v         |                          v
[Layer 2]   | (unroll T times)       [Attractor: solve z*=f(z*)]
  |         |                          |
  v         |                          v
[Layer 3] <-+                        Output
  |
  v
Output

Memory: O(T * model_size)            Memory: O(model_size)
Depth: Fixed T                       Depth: Adaptive (converges when ready)
Gradients: Through T steps           Gradients: Through equilibrium
One sentence: From explicit recurrence with fixed depth and linear memory cost, to implicit fixed-point solving with adaptive depth and constant memory.
Expert Assessment
Problem choice: Real gap. Looped models have been a known pain point—everyone wants iterative refinement for reasoning, but training instability and memory costs have kept them niche. This paper attacks the right bottleneck at the right time, as reasoning tasks gain prominence.
Method maturity: Clever insight, not brute force. Implicit differentiation for fixed points is borrowed from optimization theory (Deep Equilibrium Models, 2019), but applying it to language modeling with the backbone/attractor split is novel. The equilibrium internalization phenomenon is genuinely surprising and suggests the method taps into something fundamental about how models learn to reason. However, the paper could explore failure modes more—what happens when the fixed point doesn’t exist or the solver doesn’t converge?
Experimental integrity: Strong. Baselines are fair (standard Transformers, Universal Transformers, looped variants). The Sudoku and maze results are striking—91.4% on Sudoku-Extreme with 27M params where GPT-4 and Claude fail is a clean win. The language modeling results (46.6% perplexity improvement, 770M model beating 1.3B Transformer) are compelling. One concern: the paper doesn’t report wall-clock training time. Implicit differentiation adds solver overhead—how much slower is training in practice?
Writing quality: Mostly clear, but the implicit differentiation section (likely in the appendix) needs to be in the main text with a worked example. Practitioners will struggle to implement this without understanding the gradient computation. The equilibrium internalization section is well-written and carries the paper’s “wow” factor.
Verdict: strong accept — Solves a real problem with a principled method, delivers strong empirical results across two distinct regimes (language modeling and reasoning), and reveals a novel training phenomenon that opens new research directions.
Takeaways
For practitioners: The backbone/attractor split is the transferable idea. You don’t need implicit differentiation to benefit—just train a small refinement module on top of your main model and see if it learns useful iteration. If it does, then invest in the fixed-point machinery.
For researchers: Equilibrium internalization suggests that models can “compile” iterative algorithms into feedforward computation during training. This might apply beyond language—could vision models internalize iterative segmentation? Could RL policies internalize planning loops?
For infrastructure: Implicit differentiation libraries (e.g., DEQ implementations) are mature enough to use. The memory savings are real—if you’re training large models with recurrence, this is worth prototyping.
Concrete technique: When debugging convergence, the paper uses Anderson acceleration with a small history window (m=5). This is more stable than naive fixed-point iteration and faster than full Newton methods. Steal this for any iterative solver in your pipeline.
论文: 2605.12466 作者: Jacob Fein-Ashley, Paria Rashidinejad 分类: cs.LG, cs.AI, cs.CL, cs.ne
缺口
循环 Transformer 承诺通过迭代优化提升推理能力,但撞上了三堵墙:通过多个循环步骤反向传播导致的训练不稳定、随循环深度线性增长的内存开销,以及需要预先固定循环深度。
此前的工作要么用浅循环(表达力受限),要么用深循环(内存和梯度爆炸)。
领域一直卡在稳定性和深度之间做选择。
问题:循环模型需要深度但负担不起
   |
   v
假设:如果我们从不显式展开循环呢?
   |
   v
方法:隐式求解不动点,通过平衡态微分
   |
   v
证据:困惑度降低 46.6%,27M 参数在数独极难版达到 91.4%
   |
   v
结论:循环变成可学习的计算,而非架构负担
增量
一句话:这篇论文之前,迭代优化意味着在浅循环(弱)和深循环(贵)之间选择;之后,模型学会将迭代内化为单个寻求平衡态的步骤,深度自适应且内存恒定。
核心机制
吸引子模型将计算分为两个阶段。
首先,骨干模块(标准 Transformer)生成初始输出嵌入。
其次,吸引子模块将此嵌入视为动力系统的起点,求解其不动点——进一步迭代不再产生变化的状态。
模型不展开 T 个显式循环步骤并通过所有步骤反向传播,而是使用隐式微分:在收敛的平衡态计算梯度,无需存储中间状态。
吸引子模块是一个小网络(通常只有 2-4 层),接收当前嵌入并输出优化版本。
训练时,求根求解器(如 Anderson 加速或 Broyden 方法)迭代此模块直到收敛,通常 5-20 步。
关键在于,梯度通过平衡条件本身反向流动,而非通过求解器的轨迹。
这使得内存保持恒定,无论求解器迭代多少次。
输入 token
     |
     v
[骨干 Transformer] -----> 初始嵌入 z_0
     |                          |
     |                          v
     |                    [吸引子模块]
     |                       |      ^
     |                       |      |
     |                       v      |
     |                  z_t+1 = f(z_t) (迭代直到 z* = f(z*))
     |                          |
     |                          v
     +--------------------> 不动点 z*
                                |
                                v
                          输出 logits
把它想象成雕刻家和抛光师。
骨干是雕刻家——从原始大理石(输入 token)快速塑造粗糙形态。
吸引子是抛光师——接过粗糙形态,迭代打磨直到不需要更多优化,表面不再变化时自动停止。
传统循环模型像是告诉抛光师”正好打磨 10 遍”,如果 5 遍就收敛了就浪费精力,需要 15 遍就失败。
吸引子模型则说”打磨到光滑为止”,雕刻家随时间学会雕刻需要更少打磨的形态。
最终,雕刻家变得如此熟练,抛光师几乎不需要运行——这就是平衡态内化。
关键概念
- 不动点:想象一个函数接收一个数字并输出新数字。
不动点是输出等于输入的输入——再次应用函数不产生变化。
例如,如果 f(x) = x/2 + 1,那么 x=2 是不动点,因为 f(2) = 2/2 + 1 = 2。
在吸引子模型中,吸引子模块是这个函数,不动点是”最终”嵌入,进一步优化是不必要的。
模型学会让其吸引子模块对每个输入都有有用的不动点。
- 隐式微分:通常,要计算通过循环的梯度,你需要存储每个中间状态(内存随循环深度扩展)。
隐式微分是一个数学技巧:如果你知道最终平衡态满足 z* = f(z*),你可以通过直接微分这个平衡方程来计算关于 z* 的梯度,无需存储到达 z* 的路径。
就像知道山顶并计算那里的坡度,无需记录攀登的每一步。
- 平衡态内化:训练期间,模型看到许多例子,骨干的初始输出被吸引子优化。
随时间推移,骨干学会生成已经接近平衡态的输出——吸引子的工作更少。
最终,骨干的输出如此接近不动点,你可以在推理时完全跳过吸引子,准确率损失极小。
模型已将迭代优化”内化”到其前馈传递中。
框架转变
之前(循环 Transformer):          之后(吸引子模型):

输入                                输入
  |                                   |
  v                                   v
[层 1] --+                          [骨干] --> z_0
  |      |                            |
  v      |                            v
[层 2]   | (展开 T 次)               [吸引子:求解 z*=f(z*)]
  |      |                            |
  v      |                            v
[层 3] <-+                          输出
  |
  v
输出

内存:O(T * 模型大小)               内存:O(模型大小)
深度:固定 T                        深度:自适应(准备好时收敛)
梯度:通过 T 步                     梯度:通过平衡态
一句话:从固定深度和线性内存成本的显式循环,到自适应深度和恒定内存的隐式不动点求解。
专家评审
选题眼光:真实缺口。
循环模型一直是已知痛点——每个人都想要迭代优化来推理,但训练不稳定和内存成本让它们保持小众。
本文在正确的时间攻击正确的瓶颈,因为推理任务正在获得重视。
方法成熟度:巧劲,非蛮力。
不动点的隐式微分借鉴自优化理论(深度平衡模型,2019),但将其应用于语言建模并采用骨干/吸引子分离是新颖的。
平衡态内化现象真正令人惊讶,表明该方法触及了模型学习推理方式的某些基本东西。
然而,论文可以更多探索失败模式——当不动点不存在或求解器不收敛时会发生什么?
实验诚意:强。
基线公平(标准 Transformer、通用 Transformer、循环变体)。
数独和迷宫结果引人注目——27M 参数在数独极难版达到 91.4%,而 GPT-4 和 Claude 完全失败,这是明确的胜利。
语言建模结果(困惑度提升 46.6%,770M 模型击败 1.3B Transformer)令人信服。
一个担忧:论文未报告实际训练时间。
隐式微分增加求解器开销——实践中训练慢多少?
写作功力:大体清晰,但隐式微分部分(可能在附录中)需要放在正文中并配有实例。
实践者如果不理解梯度计算将难以实现。
平衡态内化部分写得很好,承载了论文的”惊艳”因素。
判决:强接收 — 用原则性方法解决真实问题,在两个不同领域(语言建模和推理)提供强实证结果,并揭示了开启新研究方向的新训练现象。
要点总结
对实践者:骨干/吸引子分离是可迁移的想法。
你不需要隐式微分就能受益——只需在主模型之上训练一个小的优化模块,看它是否学到有用的迭代。
如果学到了,再投资不动点机制。
对研究者:平衡态内化表明模型可以在训练期间将迭代算法”编译”成前馈计算。
这可能适用于语言之外——视觉模型能否内化迭代分割?强化学习策略能否内化规划循环?
对基础设施:隐式微分库(如 DEQ 实现)已足够成熟可用。
内存节省是真实的——如果你正在训练带循环的大模型,这值得原型化。
具体技术:调试收敛时,论文使用带小历史窗口(m=5)的 Anderson 加速。
这比朴素不动点迭代更稳定,比完整牛顿方法更快。
把这个偷走用于你管道中的任何迭代求解器。