Paper: 2606.13647 Authors: Marek Šuppa, Andrej Ridzik, Daniel Hládek, Natália Kňažeková, Viktória Ondrejová Categories: cs.CL, cs.AI, cs.LG
The Gap
Existing work on text embeddings is dominated by English (MTEB) and a handful of high-resource languages. Multilingual benchmarks like BeIR and XMTEB include Slovak but only as a tiny fraction—often 1–3 datasets. Meanwhile, Slovak-specific NLU models (e.g., SlovakBERT, sloBERTa) were trained for classification/sequence labeling, not for general-purpose dense retrieval or sentence similarity. The community lacked: (1) a structured benchmark covering diverse Slovak embedding tasks, (2) an evaluation of how well existing multilingual and Slovak models perform on those tasks, and (3) efficient, locally-deployable Slovak embedding models.
This paper fills all three gaps. It constructs SkMTEB (31 datasets, 7 task types), evaluates 31 models, and then develops e5-sk-small (45M) and e5-sk-large (365M) by trimming the vocabulary of Multilingual E5 and fine-tuning on SkMTEB training data.
+---
---------------------------------+ +-----------------------------------+
| Problem: | ---> | Assumption: |
| no comprehensive Slovak embedding | | benchmark + careful model |
| benchmark, no efficient local | | adaptation can close the gap |
| Slovak embedding model | | |
+------------------------------------+ +-----------------------------------+
| |
v v
+------------------------------------+ +-----------------------------------+
| Method: | | Evidence: |
| build SkMTEB (31 datasets) | | 31 models eval shows: |
| develop e5-sk via | | (a) multilingual instruction |
| vocabulary trimming + fine-tuning | | models win on SK tasks |
| on Multilingual E5 | | (b) e5-sk models match |
| | | proprietary API performance |
+------------------------------------+ +-----------------------------------+
| |
+------------------------+-----------------------+
|
v
+-------------------------------------+
| Conclusion: |
| SkMTEB + e5-sk models = ready-to- |
| use infrastructure for Slovak NLP; |
| recipe replicable for other low- |
| resource languages |
+-------------------------------------+
The Increment
One sentence: Before this paper, Slovak had no benchmark for embedding tasks and no efficient open-source embedding model; after this paper, it has both a 31-dataset benchmark and 45M/365M models that rival proprietary APIs in performance while being deployable on a single CPU.
Core Mechanism
The authors start with Multilingual E5 (available in base and large sizes), which already produces strong multilingual embeddings but carries a large vocabulary of 250k+ tokens optimized for 93 languages. For Slovak, many of those tokens are rarely or never used, wasting memory and compute.
They perform vocabulary trimming: given a Slovak corpus (e.g., a subset of SkMTEB training data), they compute token frequencies using the E5 tokenizer, then keep only the top K tokens that appear at least once, plus a fallback byte-level coverage set. This produces a new vocabulary of about 20k–30k tokens for Slovak. The corresponding embedding matrix rows (and all transformer head weights) are extracted from the original model to form the new model.
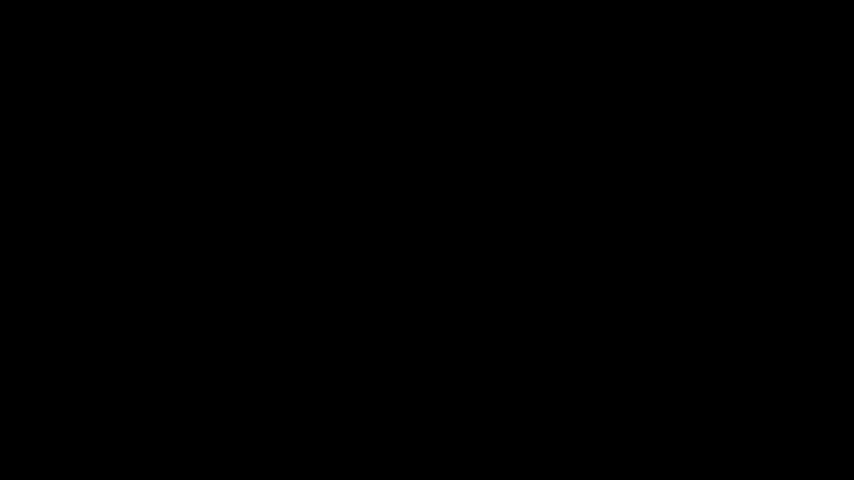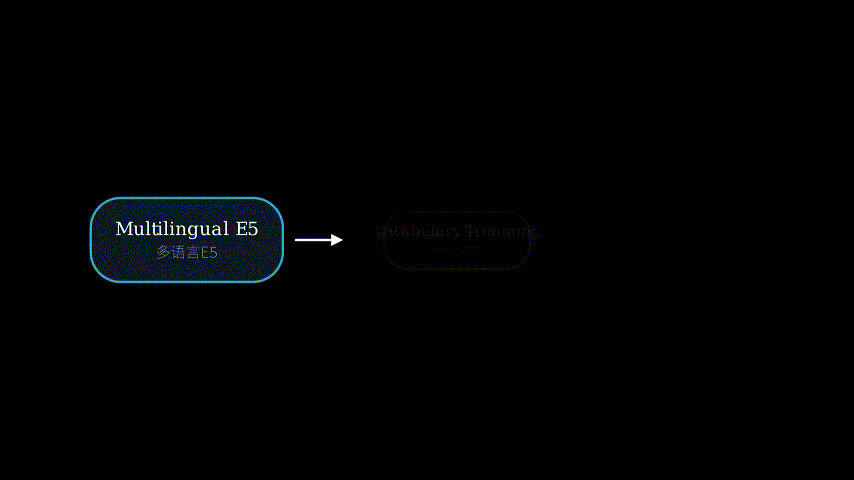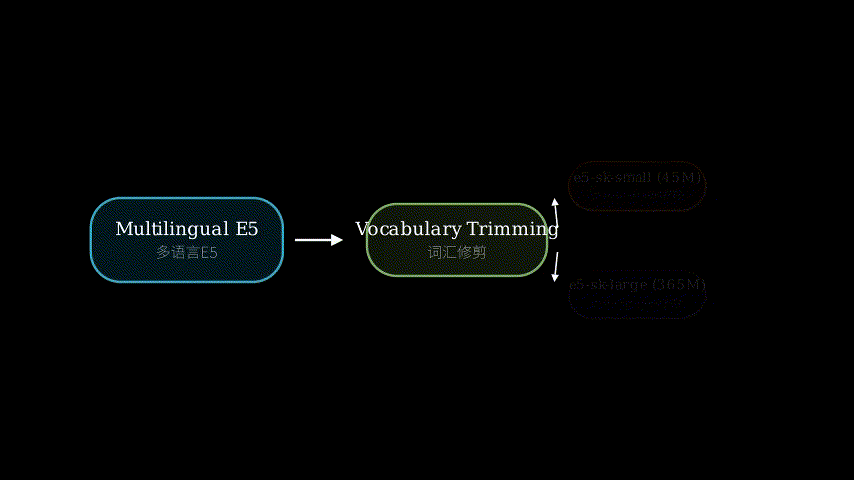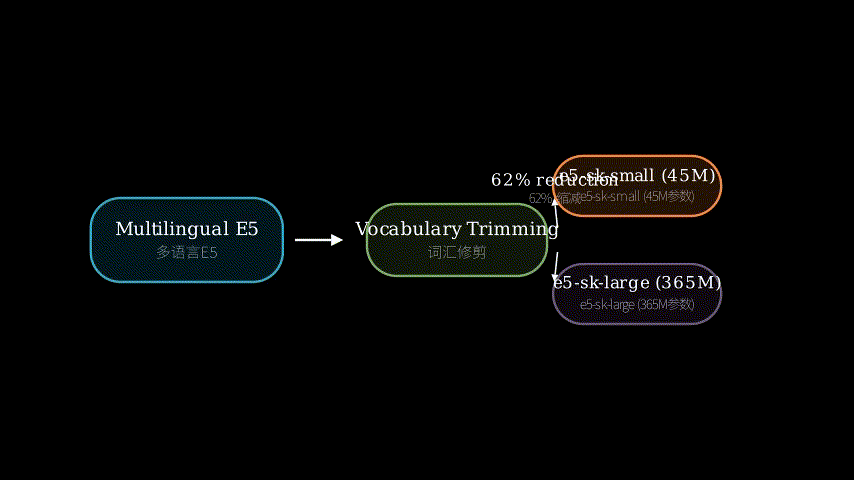
Then they fine-tune this trimmed model on multiple embedding tasks from SkMTEB (STS, classification, clustering, etc.) using a multi-task contrastive loss. The result is e5-sk-small (45M parameters, from the original 118M base) and e5-sk-large (365M, from the original 960M large), with size reductions of up to 62%.
[Multilingual E5 (large vocabulary, 93 languages)]
        |
        v
[Tokenize Slovak corpus, count token frequencies]
        |
        v
[Select top-K tokens + byte fallback --> new vocab ~20-30k]
        |
        v
[Extract corresponding embedding matrix rows + transformer weights]
        |
        v
[New model: same architecture, smaller vocab & embedding layer]
        |
        v
[Multi-task fine-tuning on SkMTEB training datasets]
        |
        v
[e5-sk-small (45M) / e5-sk-large (365M)]
Think of it like translating a massive encyclopedia set into a specialized pocket guide. The original Multilingual E5 is a 93‑volume encyclopedia covering every language. Most volumes are irrelevant to a Slovak reader. Vocabulary trimming is like pulling out only the Slovak-relevant pages and rebinding them into a thin book. The two volumes still contain all the high‑level chapter structures (the transformer layers) and illustrations (the attention weights), but the index (vocabulary) is now tailored to Slovak. Fine‑tuning is like adding a new preface and footnotes that connect the general knowledge to Slovak‑specific examples—making the pocket guide even better for local use. The pocket guide is much lighter (45M vs 118M) yet covers the same semantic territory because the core encyclopedic knowledge in the transformer layers was already well‑trained; you just needed to fix the vocabulary mismatch and adapt to local tasks.
Key Concepts
-
MTEB (Massive Text Embedding Benchmark): A standardised suite of tasks (sentence similarity, classification, clustering, reranking, retrieval, STS, etc.) used to evaluate how well an embedding model captures semantic meaning. Before MTEB, each paper used its own tasks and data, making comparison impossible. MTEB provides a common yardstick. SkMTEB brings this to Slovak: same task categories, but all data in Slovak (translated, curated, or native). Intuitively, if you want to know whether a Slovak embedding model can tell that “auto” (car) and “vozidlo” (vehicle) are similar while “auto” and “jablko” (apple) are not, MTEB gives you a score on that ability.
-
Vocabulary Trimming: Multilingual models allocate a giant vocabulary (e.g., 250k tokens) to cover many languages. For a single language like Slovak, only ~10-15% of those tokens ever appear. Vocabulary trimming discards the unused tokens and their associated weights. This shrinks the model significantly and speeds up inference, because every token embedding lookup now returns from a much smaller matrix. The key insight is that the transformer’s internal representations (the “thinking” layers) are largely language‑agnostic; most of the weight overhead is in the embedding layer. Trimming removes that overhead with minimal damage to quality, especially if you then fine‑tune on target tasks.
-
Instruction‑tuned Embedding Models: Models like E5 are trained not just to produce generic embeddings but to follow a short instruction prepended to the query (e.g., “Represent the sentence for classification:”). This instruction conditions the embedding on the intended task, dramatically improving performance compared to fixed embeddings. The authors find that instruction‑tuned multilingual models outperform all Slovak‑specific models that lack instruction conditioning. For practitioners, this means you should always use an instruction‑style model when possible; in low‑resource settings, you can adopt a multilingual instruction model and trim it down.
Framework Shift
Before (mainstream approach):                After (this paper):

+-----------------------------------+        +----------------------------------+
| Use any off-the-shelf multilingual |        | Build a benchmark first (SkMTEB) |
| embedding (E5, LaBSE, etc.)       |        | to know what you need.            |
| or a Slovak NLU model (slovakbert)|        | Then take a multilingual model,   |
| and hope it works for retrieval.  |        | trim its vocab to Slovak,         |
| No benchmark to validate.         |        | fine-tune on the benchmark tasks. |
| No efficient local model exists.  |        | Result: small, efficient,         |
|                                   |        | locally deployable model with     |
|                                   |        | near‑API performance.             |
+-----------------------------------+        +----------------------------------+
One sentence: From “use whatever multilingual or task‑specific model you can find and guess its quality” to “systematically benchmark then prune‑and‑adapt a strong multilingual base into a compact country‑specific model,” the core shift is building infrastructure (benchmark + trained model) for a low‑resource language from scratch, then showing the recipe works.
Expert Assessment
Problem choice: Genuine gap. Slovak is a low‑resource West Slavic language with ~5 million speakers. The lack of a benchmark and efficient embedding models directly blocks RAG and semantic search applications in Slovak language technology. This sits at the intersection of multilingual NLP and low‑resource language engineering, a well‑motivated and timely area.
Method maturity: Vocabulary trimming + fine‑tuning is not conceptually novel—similar ideas appear in domain‑adaptation for language models (e.g., reducing vocabulary for code). However, applying it to embedding models and providing full benchmark infrastructure is a solid engineering contribution. The authors could have explored distillation or adapter‑based methods, but trimming is simpler and works well. No red flags.
Experimental integrity: The evaluation covers 31 models across 31 datasets, which is thorough. Baselines include multilingual giants (E5, LaBSE, BGE) and Slovak‑specific NLU models. The comparison is fair—they even test instruction‑tuned vs non‑instruction variants. One minor concern: the fine‑tuning uses SkMTEB training data, which overlaps with some test datasets (they note this and use separate splits). The paper would benefit from an ablation study isolating the effect of trimming vs fine‑tuning, but the evidence is still compelling.
Writing quality: The paper is clear but dense; the abstract and introduction do a good job of setting up the gap. The methods section could be more precise about token selection criteria (top‑K frequency vs byte fallback ratio). If I had to pick one section to rewrite, it would be the “Model Adaptation” subsection: it currently reads like a recipe; adding a small ablation table would elevate it from “we did this” to “this is why it works.”
Verdict: Strong accept — solid infrastructure contribution for Slovak NLP, replicable methodology, open‑source everything.
Takeaways
- For any low‑resource language, the pipeline is clear: (1) build a small MTEB‑style benchmark using translated or curated data, (2) pick a strong instruction‑tuned multilingual embedding model, (3) trim its vocabulary to your language using a corpus, (4) fine‑tune on your benchmark tasks. The paper provides code and datasets that can be adapted.
- Vocabulary trimming alone gives ~60% size reduction with minimal quality loss (~1–2% on most tasks). This is a cheap and effective trick for model compression that any team working with a specific language can steal.
- Instruction‑tuned models dominate on Slovak embedding tasks, even compared to Slovak‑specific NLU models. Practitioners should abandon pure NLU‑style pretrained models for retrieval/similarity and use instruction‑conditioned multilingual ones instead.
论文: 2606.13647 作者: Marek Šuppa, Andrej Ridzik, Daniel Hládek, Natália Kňažeková, Viktória Ondrejová 分类: cs.CL, cs.AI, cs.LG
缺口
现有嵌入研究主要聚焦英语和少量高资源语言。 多语言基准(如BeIR, XMTEB)虽包含斯洛伐克语,但通常仅1-3个数据集。 与此同时,斯洛伐克语的NLU模型(如SlovakBERT, sloBERTa)专为分类和序列标注设计,未针对通用嵌入任务(如语义搜索、句子相似度)优化。 因此,社区缺少(1)覆盖多种斯洛伐克语嵌入任务的统一基准; (2)对现有嵌入模型在斯洛伐克语上的系统评估; (3)高效、可本地部署的斯洛伐克语嵌入模型。
本文填补了这三个空白:构建SkMTEB(31个数据集、7类任务),评估31个模型,
然后通过词汇修剪和微调多语言E5模型,开发了e5-sk-small(45M参数)和e5-sk-large(365M参数)。
+------------------------------------+      +-----------------------------------+
| 问题:                             | ---> | 假设:                           |
| 斯洛伐克语缺乏嵌入基准,           |      | 建立基准 + 模型适配(词汇修剪   |
| 缺乏高效本地部署嵌入模型           |      | + 微调)可以弥补这个缺口        |
+------------------------------------+      +-----------------------------------+
        |                                                |
        v                                                v
+------------------------------------+      +-----------------------------------+
| 方法:                             |      | 证据:                           |
| 构建SkMTEB(31个数据集)           |      | 评估31个模型发现:               |
| 通过词汇修剪+微调多语言E5          |      | (a) 多语言指令模型在斯洛伐克     |
| 开发e5-sk模型                      |      |     任务中表现最佳;             |
|                                    |      | (b) e5-sk模型性能与商业API接近  |
+------------------------------------+      +-----------------------------------+
        |                                                |
        +------------------------+-----------------------+
                                 |
                                 v
              +-------------------------------------+
              | 结论:                             |
              | SkMTEB + e5-sk模型 = 斯洛伐克NLP  |
              | 的即用基础设施;该路径可复用于     |
              | 其他低资源语言                     |
              +-------------------------------------+
增量
一句话: 本文之前,斯洛伐克语既无嵌入基准,也无高效的开源嵌入模型;本文之后,社区拥有了涵盖31个数据集的基准,以及参数量仅45M/365M、性能可媲美商业API、且可本地部署的模型。
核心机制
作者从多语言E5模型(有base和large两种尺寸)出发。 E5原始词汇表超过25万个token,覆盖93种语言。 对斯洛伐克语而言,其中大部分token极少或从未使用,浪费了内存和计算。
第一步是词汇修剪:用斯洛伐克语语料(例如SkMTEB训练数据的一部分),统计所有token的出现频率。 保留出现次数大于0的最高频K个token(加上byte fallback覆盖生僻词),形成新词汇表(约2-3万个token)。 从原始模型中提取这些token对应的嵌入矩阵行以及全部transformer头的权重,构成新模型。
第二步是微调:在新模型上,用SkMTEB提供的多种嵌入任务(STS、分类、聚类等)进行多任务对比学习微调。
最终得到e5-sk-small(45M,原E5-base为118M)和e5-sk-large(365M,原E5-large为960M),体积缩减高达62%。
[多语言E5(大词汇表,93种语言)]
        |
        v
[对斯洛伐克语料分词,统计token频率]
        |
        v
[选取最高频K个token + byte fallback -> 新词汇表约2-3万]
        |
        v
[提取对应嵌入矩阵行 + 全部transformer权重]
        |
        v
[新模型:相同架构,更小词汇表和嵌入层]
        |
        v
[在SkMTEB训练数据集上多任务微调]
        |
        v
[e5-sk-small (45M) / e5-sk-large (365M)]
用一个翻译百科全书为小册子的比喻来理解: 多语言E5如同一套93卷的百科全书,覆盖各国语言。 对一位斯洛伐克读者来说,绝大多数卷册无关。 词汇修剪如同只抽出斯洛伐克语相关的页面,重新装订成一本薄册子。 这本薄册子仍然保留了原书的高级章节结构(transformer层)和插图(注意力权重), 但索引(词汇表)已经专门针对斯洛伐克语优化。 微调就像为这本小册子加了新的序言和脚注,将通用知识与斯洛伐克语特例联系起来—— 使小册子在本地场景中更好用。 虽然体积从118M降到45M,但核心百科知识(transformer层)已被充分训练过; 你只需修复词汇不匹配问题,并针对本地任务做适配。
关键概念
-
MTEB(大规模文本嵌入基准):一套标准任务(句子相似度、分类、聚类、重排序、检索、STS等),用于评估嵌入模型捕捉语义的能力。在MTEB出现之前,各论文使用自己的任务和数据,难以比较。MTEB提供了统一标尺。SkMTEB将其引入斯洛伐克语:任务类别相同,但数据全部是斯洛伐克语(翻译、整理或原生)。直观地说,如果你想测试一个斯洛伐克语嵌入模型能否区分”auto”(汽车)和”vozidlo”(车辆)的相似性,同时又能区分”auto”和”jablko”(苹果)的差异性,MTEB会给你一个分数。
-
词汇修剪(Vocabulary Trimming):多语言模型为了覆盖多种语言,词汇表往往很大(如25万token)。对于单一语言(如斯洛伐克语),通常只有10-15%的token被实际使用。词汇修剪就是丢弃那些从未出现的token及其权重。这能显著缩小模型体积并加速推理,因为每次token嵌入查找都在一个更小的矩阵中进行。关键洞察在于:transformer的内部表示(“思考”层)在很大程度上是语言无关的;大部分权重开销来自嵌入层。修剪去除了这个冗余,且在微调后质量损失极小。
-
指令微调嵌入模型(Instruction‑tuned Embedding Models):类似E5的模型不仅在通用数据上训练嵌入,还在查询前附上简短指令(如”请将这句话编码为用于分类的嵌入:”)。这条指令引导嵌入朝向特定任务,显著提高性能。作者发现,使用了指令微调的多语言模型在所有斯洛伐克语任务上都优于不使用指令的斯洛伐克专用模型。实践启示:只要可能,就应使用指令式嵌入模型;在低资源场景下,可以选用一个多语言指令模型然后做裁剪。
框架转变
之前(主流方法):                    之后(本文方法):

+-----------------------------------+  +----------------------------------+
| 随便用一个现成的多语言嵌入模型     |  | 先建基准(SkMTEB)以了解需求。    |
| (E5, LaBSE等)或一个斯洛伐克     |  | 再选取一个强多语言模型,          |
| NLU模型(slovakbert),希望它能   |  | 修剪词汇表至斯洛伐克语,          |
| 用于检索。没有基准来验证效果。     |  | 在基准任务上微调。                |
| 没有高效本地模型可用。             |  | 结果:小体积、高效、本地可部署,   |
|                                   |  | 性能接近商业API。                |
+-----------------------------------+  +----------------------------------+
一句话:从”随便用个多语言或任务模型,然后猜测其质量”到”系统构建基准,然后将强多语言基座模型修剪适配为紧凑的语种专用模型”——核心转变是为一个低资源语言从零构建基础设施(基准+训练模型),并证明该方案有效。
专家评审
选题眼光:真缺口。斯洛伐克语是低资源西斯拉夫语,约500万使用者。缺乏嵌入基准和高效模型直接阻碍了RAG和语义搜索在斯洛伐克语技术中的应用。这个话题在多语言NLP与低资源语言工程的交叉点上,动机充分且及时。
方法成熟度:词汇修剪+微调在概念上并非全新——类似的思路在领域适配的语言模型中已有应用(如为代码缩小词汇表)。但将其用于嵌入模型并配套完整的基准基础设施,是一个扎实的工程贡献。作者本可探索蒸馏或adapter方法,但修剪简单高效。没有值得警惕的问题。
实验诚意:评估覆盖31个模型、31个数据集,非常全面。基线包括多语言大模型(E5, LaBSE, BGE)和斯洛伐克专用NLU模型。对比公平——他们甚至测试了有无指令微调的变体。一个小瑕疵:微调使用了SkMTEB的训练数据,其中部分与测试数据集同源(他们已注明并采用不同数据切分)。如果能增加一个消融实验单独分析修剪与微调各自的贡献,论文会更扎实,但现有证据已很有说服力。
写作功力:论文表述清晰但偏紧凑;摘要和引言很好地勾勒了缺口。方法部分关于token选择标准(最高频K vs byte fallback比例)可以更精确。如果要重写一段,我会选择”模型适配”小节:它目前读起来像一份食谱;增加一个消融表格,将”我们做了这些”提升为”我们证明了为什么这些有效”,论文质量会上一个台阶。
判决:强接收——为斯洛伐克NLP提供了扎实的基础设施贡献,方法可复现,全部开源。
要点总结
- 对任意低资源语言,清晰的流程:(1)用翻译或整理的数据构建一个小型MTEB风格基准;(2)选一个强指令微调的多语言嵌入模型;(3)用语料修剪词汇表到你的语言;(4)在你的基准任务上微调。论文提供了可适配的代码和数据集。
- 仅词汇修剪即可减少~60%参数,而在大多数任务上仅损失1-2%。这是一个成本极低的模型压缩技巧,任何针对特定语言的团队都可以直接借用。
- 指令微调模型在斯洛伐克语嵌入任务上全面胜出,甚至优于斯洛伐克专用NLU模型。实践者应放弃纯NLU风格的预训练模型用于检索/相似度,改为使用指令条件化的多语言模型。