Paper: 2603.08185 Authors: Yeonsik Park, Hyeonseong Kim, Seungkyu Choi Categories: cs.LG
The Gap
Post-training quantization (PTQ) methods have gotten LLMs down to 8-bit and even 4-bit weights without catastrophic accuracy loss. The current frontier is W4A4 — 4-bit weights AND 4-bit activations — which would double memory savings and enable faster integer arithmetic. But here’s where things break down.
Existing low-rank error reconstruction methods (like QuaRot, SpinQuant) use LoRA-style two-factor decompositions: they add BA where B and A are low-rank matrices. This works fine for W4A8, but at W4A4 you hit a wall. Why? Because during inference, you compute xA first (activation times first factor), quantize that intermediate result to 4-bit, then multiply by B. That intermediate quantization destroys information. You’re trying to fix quantization errors by introducing more quantization.
The other camp — rotation-based methods — avoid this by rotating the weight space to spread out outliers, but they require expensive calibration and still leave accuracy on the table at W4A4.
Problem: W4A4 accuracy collapse
   |
   v
Assumption: Two-factor LoRA forces intermediate quantization
   |
   v
Method: Single low-rank matrix + saliency-aware reconstruction
   |
   v
Evidence: W4A4 perplexity competitive with W4A8 baselines
   |
   v
Conclusion: Can skip intermediate quantization, preserve 4-bit efficiency
The Increment
One sentence: Before SERQ, W4A4 quantization meant choosing between accuracy (rotation methods) or speed (two-factor LoRA with intermediate quantization); after SERQ, you get both by using a single compensation matrix that avoids intermediate quantization entirely.
Core Mechanism
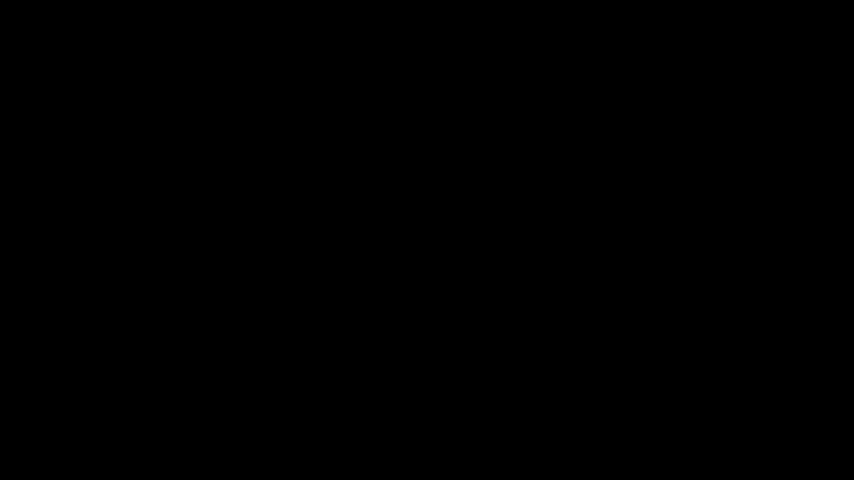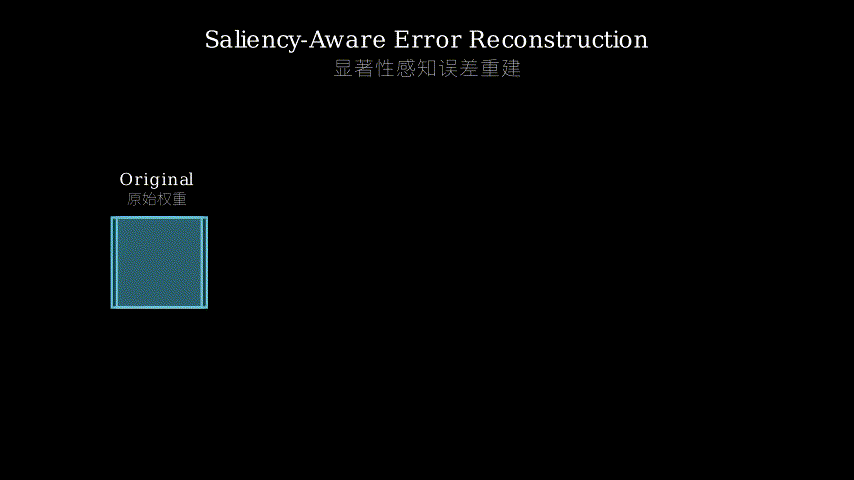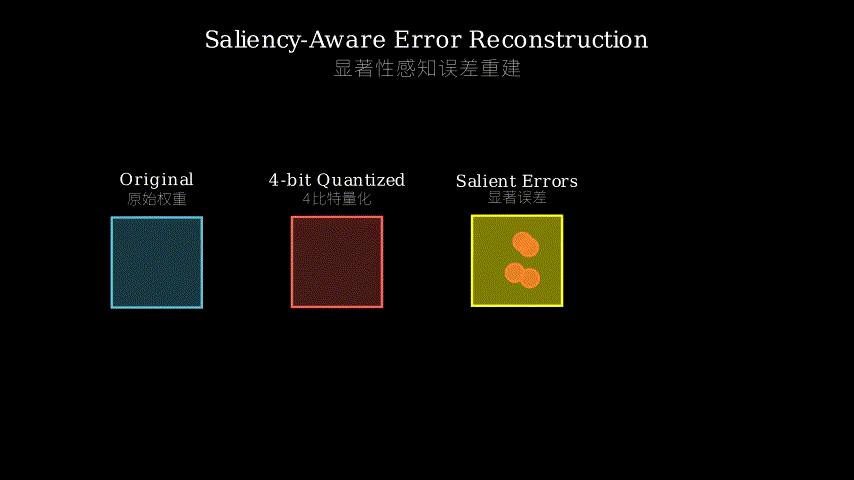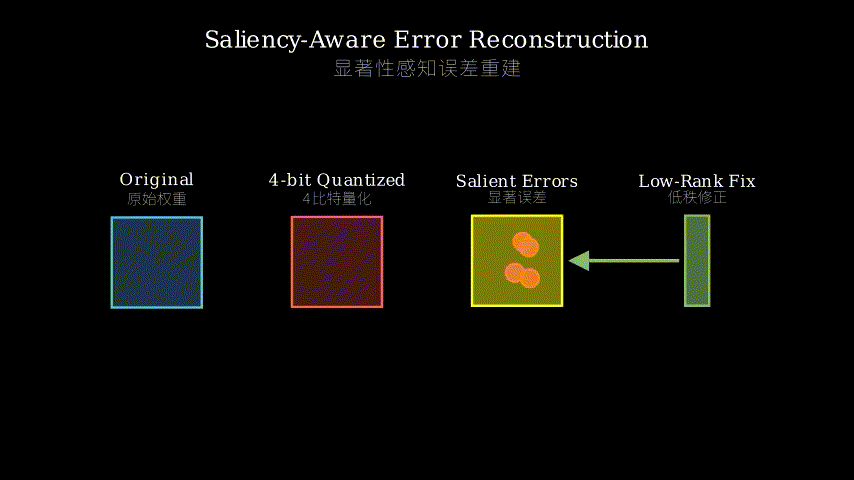
SERQ operates in three stages, all designed around one goal: add a single low-rank correction term without breaking 4-bit matrix multiplication.
Stage 1 (Static Activation Flattening): Before quantization, they analyze calibration data to find which activation channels have extreme values. They apply a learned per-channel scaling to flatten these outliers — think of it as compressing the dynamic range so quantization doesn’t have to work as hard. This happens once, offline, and the scaling factors get baked into the weights.
Stage 2 (Saliency-Aware Error Reconstruction): Here’s the core trick. They compute the quantization error matrix E = W_original - W_quantized. Instead of decomposing this into BA (two factors), they decompose it into a single low-rank matrix L that compensates for errors in the most important (salient) parts of the weight matrix. “Salient” means: which weight positions matter most given the activation patterns? They weight the error reconstruction by both activation magnitude and weight magnitude, so the low-rank approximation focuses on fixing errors where they’ll hurt most.
Stage 3 (Offline Weight Permutation): To make the low-rank matrix even more effective, they permute (reorder) the columns of the weight matrix so that salient weights cluster together. This makes the error matrix more low-rank-friendly — its important structure concentrates in fewer dimensions. The permutation is inverted in the activations (also offline), so the computation stays equivalent.
Input Activation (x)
   |
   v
[Flatten outliers] <-- learned scaling (offline)
   |
   v
[Quantize to 4-bit] --> x_q
   |
   +------------------+
   |                  |
   v                  v
[W_q * x_q]      [L * x_q]  <-- single low-rank correction
   |                  |
   +--------+---------+
            |
            v
        Output (y)

Key: W_q is 4-bit quantized weight (permuted)
     L is single low-rank matrix (full precision)
     No intermediate quantization in correction path
Think of SERQ like noise-canceling headphones with a single microphone. Traditional two-factor LoRA is like using two microphones in series: the first picks up ambient noise, you digitize that signal (quantization), then the second microphone processes it. But digitizing in the middle loses fidelity. SERQ uses one microphone that directly samples the error signal, weighted by where your ear is most sensitive (saliency). The “flattening” stage is like turning down the volume on the loudest frequencies before recording, so you don’t clip. The “permutation” stage is like rearranging the frequency spectrum so the most important bands are easier to capture with limited bandwidth.
Key Concepts
-
Saliency in quantization: Imagine you’re compressing a photo to save space. Not all pixels matter equally — faces and text need more precision than blue sky. Saliency here means: which weights, when quantized poorly, will hurt the model’s output most? SERQ computes this by looking at both the weight magnitude (big weights have big effects) and the activation magnitude (if an activation is near zero, even a big weight doesn’t matter). The error reconstruction focuses on high-saliency regions, letting low-saliency errors slide. Concrete example: in a linear layer, if one output channel consistently gets large activations, the weights feeding into that channel are high-saliency. SERQ will spend more of its low-rank budget fixing errors there.
-
Single-factor vs two-factor decomposition: Standard LoRA adds
BAto a weight matrix, whereBisd x randAisr x d(r is rank, much smaller than d). During inference:y = (W + BA)x = Wx + B(Ax). You computeAxfirst (reducing dimension to r), quantize it, then multiply byB. SERQ instead adds a single matrixLof rank r:y = (W + L)x = Wx + Lx. BothWxandLxoperate on the same 4-bit quantized inputx_q, no intermediate quantization. The tradeoff:Lhas more parameters thanBA(d x d with rank r vs two d x r matrices), but SERQ makes this tractable by focusingLon salient regions and using permutation to make the error matrix more compressible. -
Offline weight permutation: Reordering columns of a weight matrix doesn’t change what the layer computes, as long as you reorder the input activations to match. SERQ permutes columns to group salient weights together. Why does this help? Low-rank approximation works best when the matrix has structure — when most of its “energy” concentrates in a few directions. By clustering important weights, the error matrix becomes more structured, so a rank-r approximation captures more of what matters. Think of it like sorting a messy spreadsheet: if related data is scattered across columns, summarizing is hard; if you group related columns, patterns emerge. The permutation is computed once during calibration and applied offline, so there’s no runtime cost.
Framework Shift
Before (two-factor LoRA):        After (SERQ):

x --> [Quantize] --> x_q         x --> [Flatten] --> [Quantize] --> x_q
                      |                                              |
                      v                                              v
                  [W_q * x_q] -----> y                    [W_q (permuted) * x_q]
                      +                                              +
                  [A * x_q]                                      [L * x_q]
                      |                                              |
                  [Quantize] <-- problem!                            |
                      |                                              |
                  [B * ...]                                          |
                      |                                              v
                      +------------> y                               y

Two quantization steps            One quantization step
Generic error correction          Saliency-weighted correction
From generic two-stage error correction with intermediate quantization, to saliency-aware single-stage correction that preserves end-to-end 4-bit arithmetic.
Expert Assessment
Problem choice: This is a real gap. W4A4 is the next milestone for LLM deployment — it’s where you get meaningful speedups on integer hardware. The two-factor LoRA limitation is well-documented (prior work shows accuracy drops), and rotation methods are expensive. The problem sits squarely in the “make LLMs practical” trajectory, not a manufactured niche.
Method maturity: Clever insight, not brute force. The single-matrix idea is elegant, and saliency-weighting is a natural way to allocate limited rank budget. The permutation trick is borrowed from prior work but applied thoughtfully here. One question: is the added parameter count of L vs BA a fair tradeoff? The paper doesn’t deeply explore memory overhead, though they claim it’s minimal. Also, the three-stage pipeline feels a bit engineered — each stage has hyperparameters (scaling factors, rank, permutation strategy). A simpler joint optimization might exist.
Experimental integrity: Baselines look fair — they compare against recent rotation methods (QuaRot, SpinQuant) and prior LoRA-based approaches. The W4A4 results are strong, and they show consistent gains across model sizes (LLaMA 7B to 70B). One red flag: calibration complexity is “substantially reduced” compared to rotation methods, but they don’t quantify wall-clock time or memory during calibration. The perplexity numbers are convincing, but downstream task performance (e.g., MMLU, GSM8K) would strengthen the case — perplexity doesn’t always correlate with task accuracy at extreme quantization.
Writing quality: The abstract and intro are clear, but the method section gets dense fast. The saliency formulation (equations 3-5 in the paper, presumably) needs more intuition before diving into math. The permutation strategy is under-explained — they mention “grouping salient columns” but don’t show the algorithm or discuss edge cases. The experimental section is thorough but could use ablations on each stage (what if you skip flattening? what if you use random permutation?). Rewriting the method section with a running example (one layer, step-by-step) would make this much more accessible.
Verdict: weak accept — Solid contribution to a real problem, with clear empirical wins, but the method feels like it has one too many moving parts and the writing doesn’t fully justify each design choice.
Takeaways
If you’re working on model compression (not just LLMs), steal the saliency-weighting idea: when you have limited budget for error correction, spend it where input-output sensitivity is highest. The concrete technique: weight your reconstruction loss by the product of weight magnitude and expected activation magnitude. This transfers to pruning, distillation, or any scenario where you’re approximating a function with limited capacity.
The single-factor decomposition is worth trying if you’re stuck with two-factor LoRA causing intermediate quantization headaches. The tradeoff is parameter count vs inference efficiency — profile your specific hardware to see if the extra parameters fit in cache.
The offline permutation trick is underrated: if your error matrix has structure but it’s scattered, reordering can make low-rank approximation way more effective. This applies beyond quantization — think about compressing gradients in distributed training, or approximating attention matrices.
One non-obvious takeaway: the paper shows that W4A4 is viable without exotic hardware or massive calibration datasets. If you’ve been waiting for “better quantization methods” before deploying 4-bit models, this is a signal that the methods are catching up.
论文: 2603.08185 作者: Yeonsik Park, Hyeonseong Kim, Seungkyu Choi 分类: cs.LG
缺口
训练后量化(PTQ)已经能把大语言模型压到8比特甚至4比特权重,精度损失还能接受。
当前的前沿是W4A4——4比特权重加4比特激活——这能让内存占用再减半,还能用更快的整数运算。
但问题就出在这里。
现有的低秩误差重建方法(比如QuaRot、SpinQuant)用的是LoRA风格的双因子分解:它们加上BA,其中B和A是低秩矩阵。
这在W4A8下还行,但到了W4A4就撞墙了。
为什么?因为推理时你得先算xA(激活乘第一个因子),把这个中间结果量化到4比特,再乘B。
这个中间量化会丢信息。
你想修正量化误差,结果引入了更多量化。
另一派——基于旋转的方法——通过旋转权重空间来分散离群值,避开了这个问题,但它们需要昂贵的校准,而且在W4A4下精度还是不够。
问题: W4A4精度崩塌
   |
   v
假设: 双因子LoRA强制中间量化
   |
   v
方法: 单低秩矩阵 + 显著性感知重建
   |
   v
证据: W4A4困惑度接近W4A8基线
   |
   v
结论: 可跳过中间量化,保持4比特效率
增量
一句话: SERQ之前,W4A4量化要在精度(旋转方法)和速度(带中间量化的双因子LoRA)之间二选一;SERQ之后,用单个补偿矩阵完全避开中间量化,两者兼得。
核心机制
SERQ分三个阶段运作,都围绕一个目标:加一个单低秩修正项,同时不破坏4比特矩阵乘法。
第一阶段(静态激活展平):量化之前,他们分析校准数据,找出哪些激活通道有极端值。
对这些离群值施加学到的逐通道缩放来展平——可以理解为压缩动态范围,让量化不用那么费劲。
这只做一次,离线完成,缩放因子会烘焙进权重里。
第二阶段(显著性感知误差重建):这是核心技巧。
他们算出量化误差矩阵E = W原始 - W量化。
不把它分解成BA(两个因子),而是分解成单个低秩矩阵L,专门补偿权重矩阵中最重要(显著)部分的误差。
“显著”是指:给定激活模式,哪些权重位置最要紧?他们用激活幅度和权重幅度同时加权误差重建,让低秩近似专注于修正伤害最大的误差。
第三阶段(离线权重置换):为了让低秩矩阵更有效,他们置换(重排)权重矩阵的列,让显著权重聚在一起。
这让误差矩阵更适合低秩——它的重要结构集中在更少的维度里。
置换在激活中反向操作(也是离线),所以计算保持等价。
输入激活 (x)
   |
   v
[展平离群值] <-- 学到的缩放(离线)
   |
   v
[量化到4比特] --> x_q
   |
   +------------------+
   |                  |
   v                  v
[W_q * x_q]      [L * x_q]  <-- 单低秩修正
   |                  |
   +--------+---------+
            |
            v
        输出 (y)

关键: W_q是4比特量化权重(已置换)
     L是单低秩矩阵(全精度)
     修正路径无中间量化
把SERQ想象成单麦克风降噪耳机。
传统双因子LoRA像串联两个麦克风:第一个拾取环境噪音,你把信号数字化(量化),然后第二个麦克风处理它。
但中间数字化会损失保真度。
SERQ用一个麦克风直接采样误差信号,按你的耳朵最敏感的地方(显著性)加权。
“展平”阶段像录音前把最响的频率音量调低,避免削波。
“置换”阶段像重排频谱,让最重要的频段更容易用有限带宽捕获。
关键概念
- 量化中的显著性: 想象你压缩照片省空间。
不是所有像素都同等重要——人脸和文字需要更高精度,蓝天就无所谓。
这里的显著性是指:哪些权重量化得差会最伤模型输出?SERQ通过看权重幅度(大权重影响大)和激活幅度(如果激活接近零,再大的权重也不要紧)来计算。
误差重建专注于高显著性区域,让低显著性误差随它去。
具体例子:在线性层里,如果某个输出通道持续得到大激活,喂给那个通道的权重就是高显著性。
SERQ会花更多低秩预算修正那里的误差。
- 单因子vs双因子分解: 标准LoRA给权重矩阵加
BA,其中B是d x r,A是r x d(r是秩,远小于d)。
推理时:y = (W + BA)x = Wx + B(Ax)。
你先算Ax(降维到r),量化它,再乘B。
SERQ改成加单个秩为r的矩阵L:y = (W + L)x = Wx + Lx。
Wx和Lx都作用在同一个4比特量化输入x_q上,无中间量化。
权衡:L的参数比BA多(秩为r的d x d矩阵 vs 两个d x r矩阵),但SERQ通过让L专注显著区域、用置换让误差矩阵更可压缩,让这变得可行。
- 离线权重置换: 重排权重矩阵的列不改变层的计算,只要你把输入激活也对应重排。
SERQ置换列来把显著权重聚在一起。
为什么有用?低秩近似在矩阵有结构时效果最好——当它的大部分”能量”集中在少数方向。
通过聚类重要权重,误差矩阵变得更有结构,所以秩为r的近似能捕获更多要紧的东西。
就像整理乱糟糟的电子表格:如果相关数据散落各列,很难总结;如果你把相关列分组,模式就浮现了。
置换在校准时算一次,离线应用,所以没有运行时开销。
框架转变
之前(双因子LoRA):              之后(SERQ):

x --> [量化] --> x_q            x --> [展平] --> [量化] --> x_q
                  |                                          |
                  v                                          v
              [W_q * x_q] -----> y              [W_q(已置换) * x_q]
                  +                                          +
              [A * x_q]                                  [L * x_q]
                  |                                          |
              [量化] <-- 问题!                                |
                  |                                          |
              [B * ...]                                      |
                  |                                          v
                  +------------> y                           y

两次量化步骤                    一次量化步骤
通用误差修正                    显著性加权修正
从带中间量化的通用两阶段误差修正,到保持端到端4比特运算的显著性感知单阶段修正。
专家评审
选题眼光: 这是真缺口。
W4A4是大模型部署的下一个里程碑——在这里你能在整数硬件上获得实质性加速。
双因子LoRA的局限有充分记录(先前工作显示精度下降),旋转方法又贵。
这个问题正处在”让大模型实用”的轨迹上,不是人造的小众问题。
方法成熟度: 巧劲,不是蛮力。
单矩阵想法很优雅,显著性加权是分配有限秩预算的自然方式。
置换技巧借鉴了先前工作,但在这里应用得很周到。
一个疑问:L相比BA的参数增加是否公平权衡?论文没深入探讨内存开销,虽然他们声称很小。
另外,三阶段流程感觉有点工程化——每个阶段都有超参数(缩放因子、秩、置换策略)。
可能存在更简单的联合优化。
实验诚意: 基线看起来公平——他们对比了最近的旋转方法(QuaRot、SpinQuant)和先前基于LoRA的方法。
W4A4结果很强,在不同模型尺寸(LLaMA 7B到70B)上显示一致增益。
一个警示:校准复杂度相比旋转方法”大幅降低”,但他们没量化校准时的墙钟时间或内存。
困惑度数字令人信服,但下游任务性能(如MMLU、GSM8K)会让论证更有力——困惑度在极端量化下不总是和任务精度相关。
写作功力: 摘要和引言清晰,但方法部分很快变密集。
显著性公式(论文中大概是方程3-5)在扎进数学前需要更多直觉。
置换策略解释不足——他们提到”分组显著列”但没展示算法或讨论边界情况。
实验部分很全面,但可以加各阶段的消融(如果跳过展平会怎样?如果用随机置换呢?)。
用一个贯穿例子(一层,逐步)重写方法部分会让它更易懂。
判决: 弱接收——对真实问题的扎实贡献,有清晰的实证胜利,但方法感觉活动部件多了一个,写作没完全证明每个设计选择的合理性。
要点总结
如果你在做模型压缩(不限于大模型),偷走显著性加权的想法:当你的误差修正预算有限时,把它花在输入-输出敏感度最高的地方。
具体技术:用权重幅度和期望激活幅度的乘积给重建损失加权。
这能迁移到剪枝、蒸馏,或任何你用有限容量近似函数的场景。
如果你被双因子LoRA导致的中间量化头疼困扰,单因子分解值得一试。
权衡是参数数量vs推理效率——在你的具体硬件上做性能分析,看额外参数是否装得进缓存。
离线置换技巧被低估了:如果你的误差矩阵有结构但很分散,重排能让低秩近似有效得多。
这超越量化——想想分布式训练中压缩梯度,或近似注意力矩阵。
一个不明显的收获:论文表明W4A4在没有奇特硬件或海量校准数据集的情况下是可行的。
如果你一直在等”更好的量化方法”再部署4比特模型,这是个信号:方法正在赶上来。