Paper: 2602.24208 Authors: Yasaman Haghighi, Alexandre Alahi Categories: cs.CV, cs.LG
Abstract
Diffusion models have achieved remarkable success in video generation, delivering state-of-the-art quality. However, their inference process remains computationally expensive due to the requirement of numerous sequential denoising steps. This paper introduces SenCache, a sensitivity-aware caching framework that addresses the computational bottleneck through a principled approach. Unlike existing heuristic-based caching methods that require extensive manual tuning, SenCache formalizes caching error by analyzing model output sensitivity to perturbations in denoising inputs (noisy latent and timestep). The framework demonstrates that sensitivity serves as a reliable predictor of caching error and proposes a dynamic policy that adaptively selects caching timesteps on a per-sample basis. Experimental validation on Wan 2.1, CogVideoX, and LTX-Video demonstrates superior visual quality compared to existing caching methods under equivalent computational budgets.
Key Contributions
- Theoretical Framework: Formalization of caching error through sensitivity analysis of model outputs to input perturbations, providing a principled foundation for understanding when caching is safe
- Sensitivity-Based Predictor: Identification of model output sensitivity as a key predictor of caching error, enabling informed decisions about cache/reuse timesteps
- Dynamic Caching Policy: Introduction of SenCache, an adaptive algorithm that selects caching timesteps dynamically on a per-sample basis rather than using fixed heuristics
- Empirical Validation: Demonstration of improved visual quality over existing caching methods across multiple state-of-the-art video generation models (Wan 2.1, CogVideoX, LTX-Video)
- Theoretical Justification: Explanation of why prior empirical heuristics work and how they can be extended to sample-specific approaches
Methodology and Technical Approach
The core innovation of SenCache lies in its sensitivity-aware formulation of the caching problem. Traditional caching methods in diffusion models reuse previously computed outputs at certain timesteps to avoid redundant computation. However, determining which timesteps are safe for caching has relied on empirical heuristics without theoretical justification.
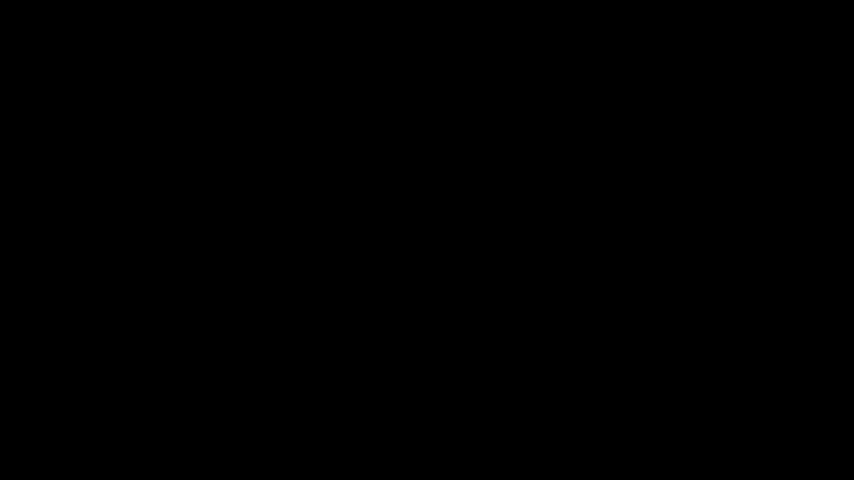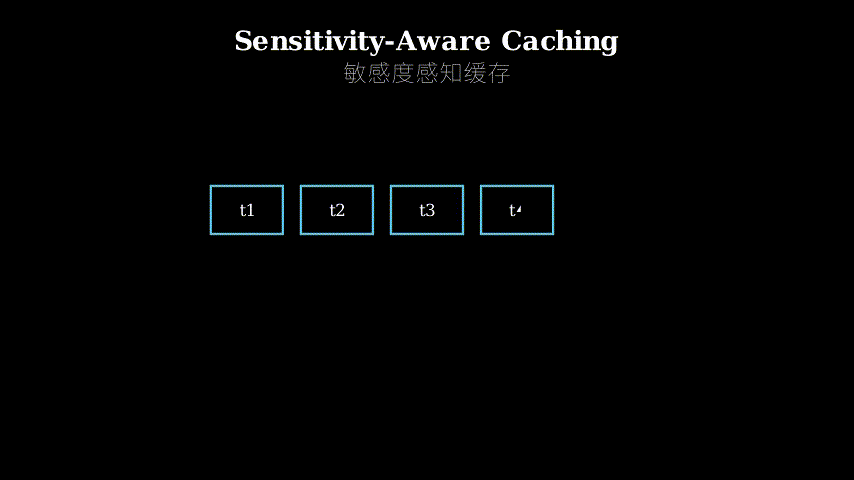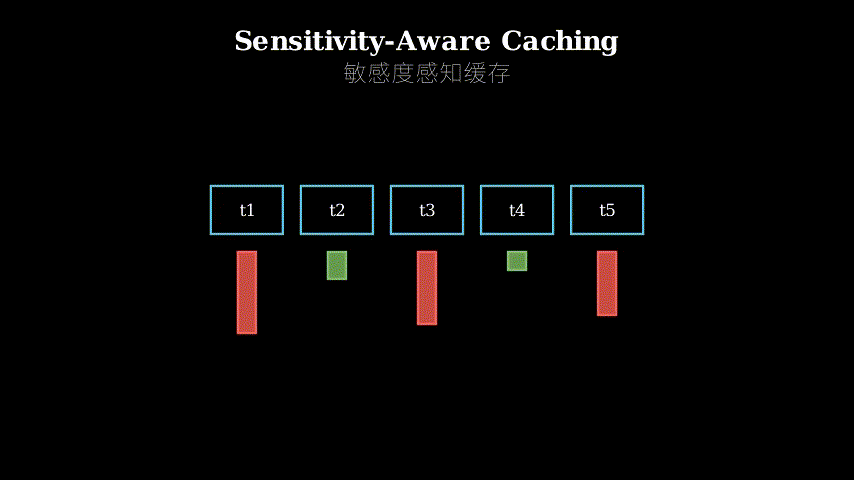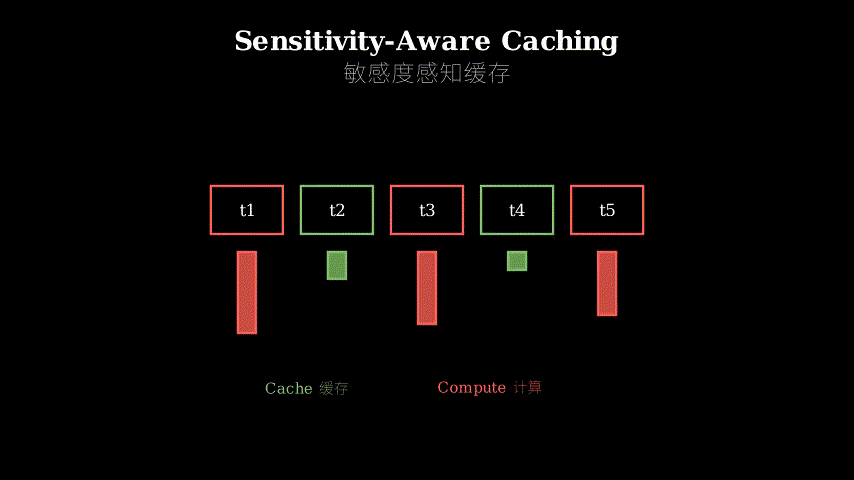
SenCache addresses this by analyzing the sensitivity of model outputs to perturbations in both the noisy latent and the timestep . The framework establishes that when sensitivity is low, the model output changes minimally between consecutive timesteps, making caching safe. Conversely, high sensitivity indicates significant changes that would result in large caching errors if outputs were reused.
The sensitivity metric is computed efficiently during inference without requiring additional forward passes. Based on this metric, SenCache dynamically decides at each timestep whether to compute a fresh output or reuse a cached one. This adaptive approach allows the method to handle varying content complexity across different samples, unlike fixed caching schedules that apply the same pattern to all inputs.
The mathematical formulation considers both first-order and higher-order sensitivity terms, providing a comprehensive understanding of how errors propagate through the denoising process. This theoretical grounding not only improves performance but also offers interpretability—explaining why certain timesteps are more amenable to caching than others.
Experimental Results and Performance
SenCache was evaluated on three prominent video generation models: Wan 2.1, CogVideoX, and LTX-Video. The experiments compared SenCache against existing caching baselines under controlled computational budgets, measured by the number of function evaluations (NFE).
Results demonstrate consistent improvements in visual quality metrics across all tested models. For instance, on Wan 2.1, SenCache achieved higher perceptual quality scores while using the same or fewer denoising steps compared to uniform caching strategies. The adaptive nature of SenCache proved particularly beneficial for complex scenes with high motion or intricate details, where fixed caching schedules often introduced visible artifacts.
Qualitative analysis revealed that SenCache better preserves temporal coherence and fine-grained details in generated videos. The method’s ability to identify critical timesteps—where fresh computation is essential—prevented the accumulation of errors that plague aggressive caching strategies. Meanwhile, it successfully exploited redundancy in smoother regions of the denoising trajectory, achieving computational savings without quality degradation.
Ablation studies confirmed the importance of the sensitivity metric, showing that removing the adaptive component and reverting to fixed schedules resulted in performance drops. The experiments also validated that the sensitivity computation overhead is negligible compared to the savings from reduced denoising steps.
Implications and Future Directions
SenCache represents a significant step toward making diffusion-based video generation more practical for real-world applications. By reducing inference costs without sacrificing quality, the method enables deployment scenarios that were previously computationally prohibitive, such as real-time video editing or high-resolution generation on resource-constrained devices.
The theoretical framework introduced by SenCache opens avenues for future research in adaptive inference strategies. The sensitivity-based approach could potentially be extended to other acceleration techniques, such as distillation or pruning, creating hybrid methods that combine multiple optimization strategies. Additionally, the framework’s interpretability provides insights into the denoising dynamics of diffusion models, which could inform architecture design and training procedures.
One promising direction is the integration of SenCache with learned acceleration methods. While SenCache is training-free, combining it with models specifically trained for fast inference could yield even greater speedups. Another area of exploration is the application of sensitivity-aware principles to other generative models beyond diffusion, such as autoregressive transformers or flow-based models.
The work also raises questions about the fundamental trade-offs between computation and quality in generative models. Understanding these trade-offs through the lens of sensitivity analysis could lead to more efficient model designs that naturally exhibit favorable caching properties.
Takeaways
- Principled caching framework: SenCache provides the first theoretically grounded approach to caching in diffusion models, moving beyond empirical heuristics
- Sensitivity as error predictor: Model output sensitivity to input perturbations reliably predicts caching error, enabling informed cache/reuse decisions
- Adaptive per-sample optimization: Dynamic caching policies that adapt to individual samples outperform fixed schedules across diverse content
- Training-free acceleration: SenCache achieves significant speedups without requiring model retraining or fine-tuning, making it immediately applicable to existing models
- Consistent quality improvements: Experimental validation across multiple state-of-the-art video generation models demonstrates robust performance gains under equivalent computational budgets
论文: 2602.24208 作者: Yasaman Haghighi, Alexandre Alahi 分类: cs.CV, cs.LG
摘要
扩散模型在视频生成领域取得了显著成功,达到了最先进的质量水平。然而,由于需要大量连续的去噪步骤,其推理过程的计算成本仍然很高。本文提出了SenCache,一个基于敏感度感知的缓存框架,通过原则性方法解决计算瓶颈问题。与现有需要大量手动调优的启发式缓存方法不同,SenCache通过分析模型输出对去噪输入(噪声潜变量和时间步)扰动的敏感度来形式化缓存误差。该框架证明敏感度是缓存误差的可靠预测指标,并提出了一种动态策略,能够针对每个样本自适应地选择缓存时间步。在Wan 2.1、CogVideoX和LTX-Video上的实验验证表明,在相同计算预算下,SenCache相比现有缓存方法实现了更优的视觉质量。
主要贡献
- 理论框架: 通过对模型输出对输入扰动的敏感度分析来形式化缓存误差,为理解何时可以安全缓存提供了原则性基础
- 基于敏感度的预测器: 识别出模型输出敏感度是缓存误差的关键预测指标,使得关于缓存/重用时间步的决策更加明智
- 动态缓存策略: 引入SenCache自适应算法,针对每个样本动态选择缓存时间步,而非使用固定启发式规则
- 实证验证: 在多个最先进的视频生成模型(Wan 2.1、CogVideoX、LTX-Video)上展示了相比现有缓存方法的视觉质量提升
- 理论解释: 阐明了先前经验启发式方法有效的原因,以及如何将其扩展到样本特定的方法
方法论与技术路径
SenCache的核心创新在于其对缓存问题的敏感度感知形式化。扩散模型中的传统缓存方法在特定时间步重用先前计算的输出以避免冗余计算。然而,确定哪些时间步适合缓存一直依赖于缺乏理论依据的经验启发式方法。
SenCache通过分析模型输出对噪声潜变量和时间步扰动的敏感度来解决这一问题。该框架确立了当敏感度较低时,模型输出在连续时间步之间变化很小,使得缓存是安全的。相反,高敏感度表明存在显著变化,如果重用输出将导致较大的缓存误差。
敏感度指标在推理过程中高效计算,无需额外的前向传播。基于该指标,SenCache在每个时间步动态决定是计算新输出还是重用缓存输出。这种自适应方法能够处理不同样本间的内容复杂度变化,不同于对所有输入应用相同模式的固定缓存调度。
数学形式化考虑了一阶和高阶敏感度项,提供了对误差如何在去噪过程中传播的全面理解。这种理论基础不仅提升了性能,还提供了可解释性——解释了为什么某些时间步比其他时间步更适合缓存。
实验结果与性能表现
SenCache在三个主流视频生成模型上进行了评估:Wan 2.1、CogVideoX和LTX-Video。实验在受控的计算预算下将SenCache与现有缓存基线进行比较,计算预算通过函数评估次数(NFE)来衡量。
结果显示,在所有测试模型上,视觉质量指标都有一致的提升。例如,在Wan 2.1上,SenCache在使用相同或更少去噪步骤的情况下,相比均匀缓存策略实现了更高的感知质量分数。SenCache的自适应特性在具有高运动或复杂细节的复杂场景中表现尤为突出,而固定缓存调度在这些场景中往往会引入可见的伪影。
定性分析表明,SenCache更好地保持了生成视频的时间连贯性和细粒度细节。该方法识别关键时间步的能力——在这些时间步新计算是必需的——防止了困扰激进缓存策略的误差累积。同时,它成功利用了去噪轨迹平滑区域的冗余性,在不降低质量的情况下实现了计算节省。
消融研究证实了敏感度指标的重要性,显示移除自适应组件并恢复到固定调度会导致性能下降。实验还验证了敏感度计算开销相比减少去噪步骤带来的节省可以忽略不计。
影响与未来方向
SenCache代表了使基于扩散的视频生成在实际应用中更加可行的重要一步。通过在不牺牲质量的情况下降低推理成本,该方法使得以前计算上难以实现的部署场景成为可能,例如实时视频编辑或在资源受限设备上的高分辨率生成。
SenCache引入的理论框架为自适应推理策略的未来研究开辟了道路。基于敏感度的方法可能扩展到其他加速技术,如蒸馏或剪枝,创建结合多种优化策略的混合方法。此外,该框架的可解释性提供了对扩散模型去噪动态的洞察,这可以为架构设计和训练过程提供指导。
一个有前景的方向是将SenCache与学习型加速方法集成。虽然SenCache是免训练的,但将其与专门为快速推理训练的模型结合可能产生更大的加速效果。另一个探索领域是将敏感度感知原则应用于扩散之外的其他生成模型,如自回归Transformer或基于流的模型。
这项工作还提出了关于生成模型中计算与质量之间基本权衡的问题。通过敏感度分析的视角理解这些权衡可能导致更高效的模型设计,这些设计自然表现出有利的缓存特性。
要点总结
- 原则性缓存框架: SenCache提供了扩散模型中首个理论基础的缓存方法,超越了经验启发式规则
- 敏感度作为误差预测器: 模型输出对输入扰动的敏感度可靠地预测缓存误差,使得缓存/重用决策更加明智
- 自适应的样本级优化: 针对单个样本自适应的动态缓存策略在多样化内容上优于固定调度
- 免训练加速: SenCache在不需要模型重训练或微调的情况下实现显著加速,可立即应用于现有模型
- 一致的质量提升: 在多个最先进视频生成模型上的实验验证展示了在相同计算预算下的稳健性能提升