Paper: 2605.28814 Authors: Guowei Xu, Zhenting Qi, Huangyuan Su, Weirui Ye, Himabindu Lakkaraju, Sham M. Kakade, Yilun Du Categories: cs.CL
The Gap
Current self-improvement methods for language models—best-of-N sampling, tree search, reinforcement learning—rely on autoregressive generation guided by sparse verification signals (right/wrong at the end). This creates two bottlenecks: (1) candidates are confined to regions where the model already assigns high probability, making it hard to discover novel solutions, and (2) without intermediate feedback, the model wastes samples exploring dead ends. The result: on hard reasoning tasks, these methods plateau or fail to improve at all.
Problem: LMs stuck in local optima
    |
    v
Assumption: Autoregressive expansion + sparse reward
            traps search in high-probability regions
    |
    v
Method: BES = Forward evolution (recombine trajectories)
              + Backward decomposition (dense subgoals)
    |
    v
Evidence: Theory (escape entropy shell, exponential sample reduction)
          + Experiments (gains where SOTA fails)
    |
    v
Conclusion: Bidirectional search breaks the bottleneck
The Increment
One sentence: Before BES, language model search was a flashlight in a dark room—you could only see where the beam pointed. After BES, you have a map that shows shortcuts and a toolkit to cut through walls.
Core Mechanism
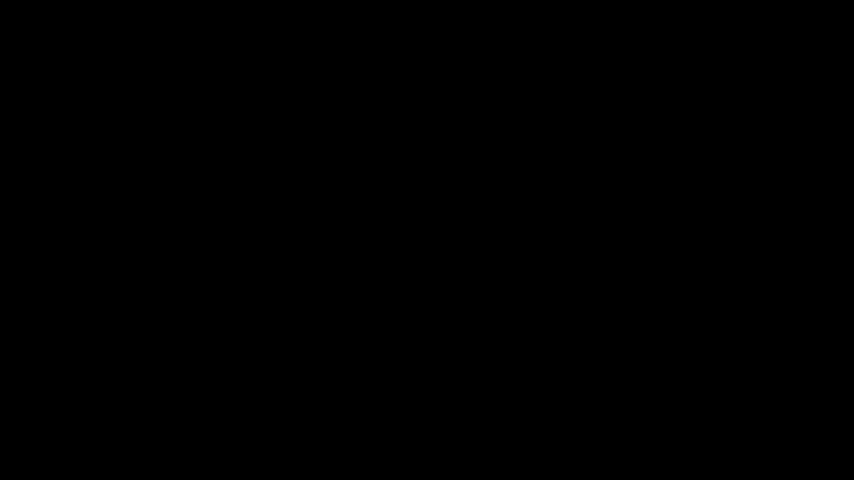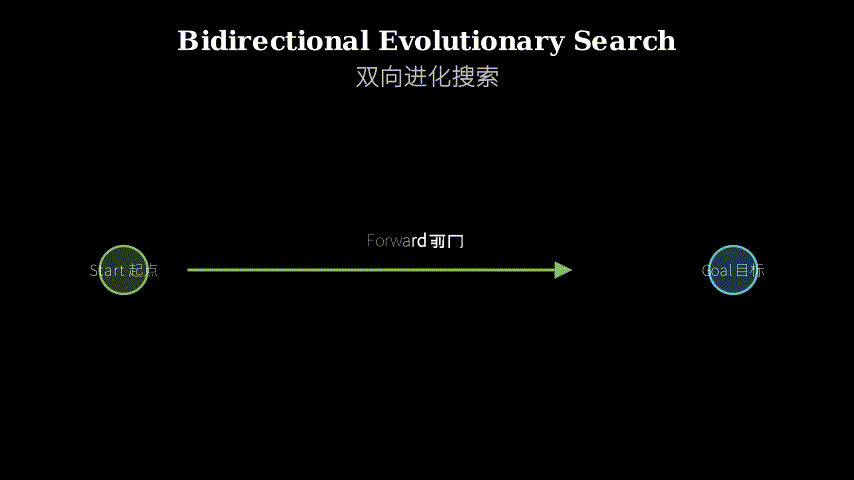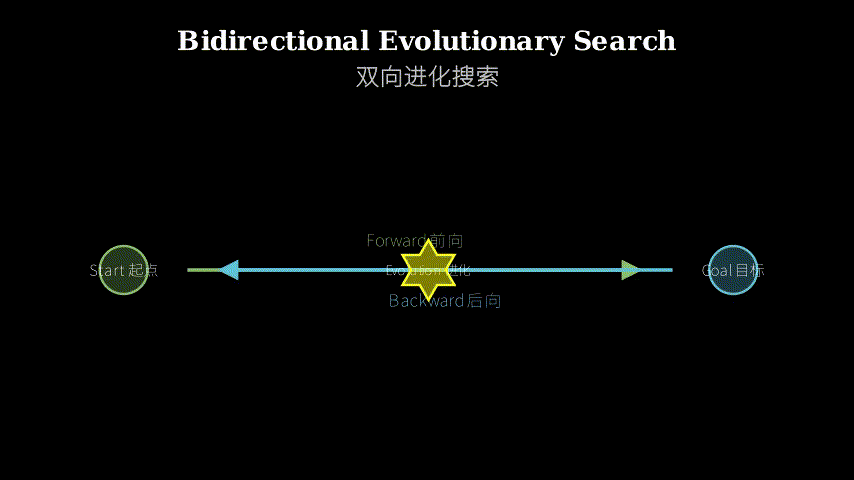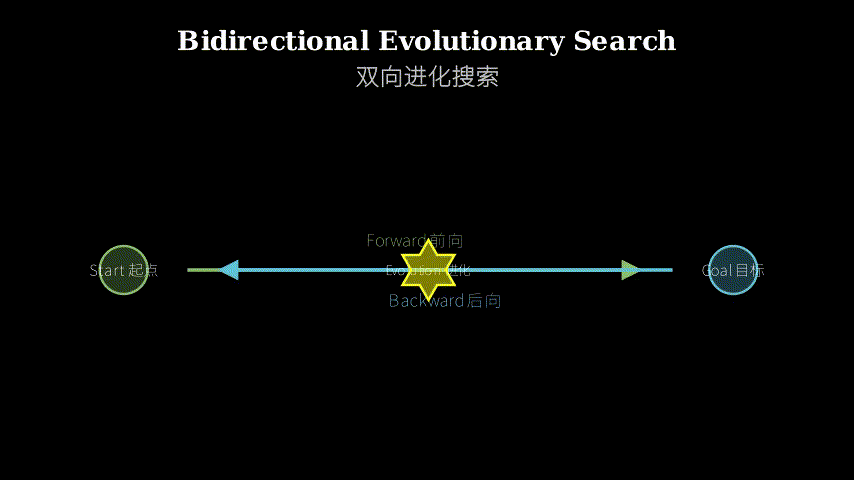
BES operates in two coupled loops. The forward search starts with the original problem and generates candidate solutions, but instead of only extending sequences token-by-token (autoregressive expansion), it also applies evolution operators: crossover (splice two partial solutions at a common checkpoint) and mutation (replace a segment with an alternative). These operators create candidates that lie outside the model’s natural probability distribution—solutions the model wouldn’t generate in a single rollout but can recognize as valid when assembled.
The backward search takes the original task and recursively decomposes it into verifiable subgoals using the model itself. For example, “prove theorem X” becomes “prove lemma A, then use A to prove X.” Each subgoal acts as a checkpoint. The forward search can now verify progress at these intermediate points, not just at the final answer. This dense feedback steers evolution toward productive regions.
The two loops interact: backward search provides the checkpoints where forward crossover can splice trajectories, and forward search validates whether the decomposed subgoals are actually achievable. The system iterates until it finds a solution or exhausts its budget.
Original Task
     |
     v
[Backward Decomposition]
     |
     +---> Subgoal_1 ---> Subgoal_2 ---> ... ---> Final Goal
              |              |                        |
              v              v                        v
         [Checkpoints for forward search]
              ^              ^                        ^
              |              |                        |
     +--------+--------------+------------------------+
     |
[Forward Evolution]
     |
     +---> Expansion: model generates next tokens
     +---> Crossover: splice trajectory_A + trajectory_B at checkpoint
     +---> Mutation: replace segment with alternative
     |
     v
Candidate Pool ---> Verify at checkpoints ---> Keep promising ones
Think of it like navigating a maze with a team. Standard search is one person walking forward, trying every turn until they hit a dead end or the exit. BES is different: one team member (backward search) stands at the exit and works backward, marking intermediate doors that must be passed through. Another team (forward search) explores from the entrance, but instead of just walking, they can teleport between marked doors (crossover) or try alternate routes between doors (mutation). The backward markers prevent wasted exploration, and the forward recombination lets you assemble a path from fragments that individually seemed unpromising.
Key Concepts
-
Entropy shell: Imagine the model’s probability distribution as a landscape where height = probability. Autoregressive sampling walks downhill from the starting point, exploring only valleys the model already knows. The “entropy shell” is the narrow band of trajectories with similar total probability—most samples land here. Evolution operators (crossover, mutation) let you jump between valleys, reaching solutions that are low-probability as complete sequences but high-value when assembled from parts. It’s the difference between walking a trail versus cutting through the forest with a machete.
-
Backward decomposition: Instead of asking “what comes next?” (forward), ask “what must come before?” (backward). The model generates a plan: “To solve X, first solve Y, then Z.” Each subgoal Y, Z becomes a checkpoint. This is recursive—Y might decompose further. The key insight: verifying a subgoal is easier than verifying the final answer, so you get dense feedback. It’s like debugging code by adding print statements at every function, not just checking if the final output is correct.
-
Crossover at checkpoints: Two partial solutions that reach the same intermediate state can be spliced together. If trajectory A solves subgoal Y via path P1, and trajectory B solves the final goal starting from Y via path P2, crossover creates a new candidate: P1 + P2. This candidate might never appear in the model’s top-k samples because P1 and P2 individually have low joint probability, but their combination is valid. It’s like assembling a jigsaw puzzle: two people work on different sections, then snap them together at a shared edge piece.
Framework Shift
Before (expansion-only search):        After (BES):

Start                                  Start
  |                                      |
  v                                      v
[Autoregressive Expansion]          [Backward Decomposition]
  |                                      |
  +---> Token_1                          +---> Subgoal_1 --> Subgoal_2 --> Goal
  +---> Token_2                               ^         ^              ^
  +---> ...                                   |         |              |
  +---> Token_N                          [Forward Evolution]
  |                                           |
  v                                           +---> Expand
Verify: Right/Wrong?                          +---> Crossover (splice at subgoals)
                                              +---> Mutate (replace segments)
(Confined to high-prob regions,               |
 sparse feedback at end only)                 v
                                         Verify at each subgoal
                                         (Dense feedback, escape prob. shell)
One sentence: From walking a single path in the model’s probability landscape to building a map of the terrain and teleporting between waypoints.
Expert Assessment
Problem choice: This is a real gap. The autoregressive bottleneck is well-known in the community—AlphaCode, tree search methods, and RL fine-tuning all struggle when the model’s prior is misaligned with the solution space. The paper doesn’t manufacture the problem; it names something practitioners have been hitting for years. The timing is right: as models plateau on benchmarks, self-improvement is the next frontier.
Method maturity: The core ideas (evolutionary algorithms, backward chaining) are old, but the synthesis is clever. The theoretical motivation (entropy shell, exponential sample reduction) is hand-wavy but directionally correct—it’s more intuition than proof. The real contribution is showing these ideas work together in the LM setting. However, the method is complex: forward evolution + backward decomposition + checkpoint alignment. Simpler ablations (e.g., just crossover without backward search) would clarify what’s load-bearing. The paper hints at this but doesn’t fully isolate components.
Experimental integrity: Baselines are fair (best-of-N, MCTS, mainstream RL algorithms). The post-training experiments show gains where others fail, which is compelling. The inference-time results on AIME, GPQA, and LiveCodeBench are strong, but the paper doesn’t report variance or multiple seeds—hard to know if the gains are robust or lucky runs. The claim that BES “outperforms existing open-source frameworks” is supported, but the comparison is against open-source only; closed-source systems (o1, o3) aren’t included, so we don’t know where this sits in the absolute landscape. No major red flags, but I’d want to see error bars.
Writing quality: The abstract and intro are crisp. The method section is dense—too much notation, not enough intuition. Figure 1 does heavy lifting, but the text doesn’t walk through a concrete example end-to-end. The related work is thorough but reads like a checklist. The biggest missed opportunity: the paper doesn’t explain *when BES helps vs. when simpler methods suffice. If I rewrote one section, it’d be the experiments—add a failure analysis showing where BES still struggles and why.
Verdict: Weak accept — The method is novel and the results are promising, but the complexity and incomplete ablations leave questions about what’s essential. The paper advances the field but needs tighter analysis to be a strong contribution.
Takeaways
For practitioners:
- Checkpoints as search structure: If you’re doing any form of search (RL, MCTS, sampling), decompose the task into verifiable intermediate states. Even without evolution, dense feedback beats sparse rewards.
- Recombination over generation: When the model’s prior is weak, don’t just sample more—recombine partial solutions. This applies beyond LMs: any generative system where you can splice outputs at natural boundaries (code at function calls, proofs at lemmas, plans at subgoals).
- Backward planning as a tool: Use the model to generate subgoals, not just solutions. This is cheap (one backward pass) and gives you a roadmap even if forward search fails.
Transferable technique: The “entropy shell escape” framing is useful for any probabilistic search. If your samples cluster in a narrow region, you need operators that jump between modes, not just refine within a mode. Crossover is one such operator; others include analogy-based transfer or constraint-guided generation.
What doesn’t transfer: The specific implementation (crossover at checkpoints, recursive decomposition) is tailored to sequential reasoning tasks. For tasks without natural decomposition (e.g., image generation, open-ended dialogue), the method needs rethinking.
论文: 2605.28814 作者: Guowei Xu, Zhenting Qi, Huangyuan Su, Weirui Ye, Himabindu Lakkaraju, Sham M. Kakade, Yilun Du 分类: cs.CL
缺口
当前语言模型的自我改进方法——best-of-N 采样、树搜索、强化学习——依赖自回归生成和稀疏验证信号(最后对错)。
这造成两个瓶颈:(1)候选解被限制在模型已经赋予高概率的区域,难以发现新颖解法;(2)缺乏中间反馈,模型浪费样本探索死胡同。
结果:在困难推理任务上,这些方法停滞或完全无法改进。
问题:语言模型困在局部最优
    |
    v
假设:自回归扩展 + 稀疏奖励
      将搜索困在高概率区域
    |
    v
方法:BES = 前向进化(重组轨迹)
            + 后向分解(密集子目标)
    |
    v
证据:理论(逃离熵壳,指数级样本减少)
      + 实验(在 SOTA 失效处获得增益)
    |
    v
结论:双向搜索打破瓶颈
增量
一句话:BES 之前,语言模型搜索是黑屋里的手电筒——只能看到光束照到的地方。
BES 之后,你有了一张显示捷径的地图,还有一套能穿墙的工具。
核心机制
BES 在两个耦合循环中运行。
前向搜索从原始问题出发生成候选解,但不只是逐词扩展序列(自回归扩展),还应用进化算子:交叉(在共同检查点拼接两个部分解)和变异(用替代方案替换片段)。
这些算子创造出位于模型自然概率分布之外的候选解——模型在单次生成中不会产生的解,但组装后能识别为有效。
后向搜索接收原始任务,用模型本身递归分解为可验证的子目标。
例如,“证明定理 X”变成”证明引理 A,然后用 A 证明 X”。
每个子目标充当检查点。
前向搜索现在可以在这些中间点验证进展,而非只在最终答案处。
这种密集反馈引导进化走向有效区域。
两个循环交互:后向搜索提供前向交叉可以拼接轨迹的检查点,前向搜索验证分解的子目标是否真的可达。
系统迭代直到找到解或耗尽预算。
原始任务
     |
     v
[后向分解]
     |
     +---> 子目标_1 ---> 子目标_2 ---> ... ---> 最终目标
              |              |                        |
              v              v                        v
         [前向搜索的检查点]
              ^              ^                        ^
              |              |                        |
     +--------+--------------+------------------------+
     |
[前向进化]
     |
     +---> 扩展:模型生成下一个词元
     +---> 交叉:在检查点拼接 轨迹_A + 轨迹_B
     +---> 变异:用替代方案替换片段
     |
     v
候选池 ---> 在检查点验证 ---> 保留有希望的
把它想象成团队走迷宫。
标准搜索是一个人向前走,尝试每个转弯直到撞上死胡同或出口。
BES 不同:一个队员(后向搜索)站在出口向后推,标记必须经过的中间门。
另一队(前向搜索)从入口探索,但不只是走路,他们能在标记的门之间传送(交叉)或尝试门之间的替代路线(变异)。
后向标记防止浪费探索,前向重组让你从单独看似无望的片段组装出路径。
关键概念
- 熵壳:把模型的概率分布想象成一个景观,高度 = 概率。
自回归采样从起点向下走,只探索模型已知的山谷。
“熵壳”是总概率相似的轨迹的狭窄带——大多数样本落在这里。
进化算子(交叉、变异)让你在山谷间跳跃,到达作为完整序列概率低但从部分组装时价值高的解。
这是沿着小径走与用砍刀穿越森林的区别。
- 后向分解:不问”下一步是什么?“(前向),而问”之前必须是什么?“(后向)。
模型生成计划:“要解决 X,先解决 Y,再解决 Z。“每个子目标 Y、Z 成为检查点。
这是递归的——Y 可能进一步分解。
关键洞察:验证子目标比验证最终答案容易,所以你得到密集反馈。
就像调试代码时在每个函数加打印语句,而非只检查最终输出是否正确。
- 检查点交叉:到达同一中间状态的两个部分解可以拼接。
如果轨迹 A 通过路径 P1 解决子目标 Y,轨迹 B 从 Y 开始通过路径 P2 解决最终目标,交叉创造新候选:P1 + P2。
这个候选可能永远不会出现在模型的 top-k 样本中,因为 P1 和 P2 单独的联合概率低,但它们的组合有效。
就像拼图:两人做不同部分,然后在共享的边缘块处扣在一起。
框架转变
之前(仅扩展搜索):                之后(BES):

起点                                  起点
  |                                      |
  v                                      v
[自回归扩展]                        [后向分解]
  |                                      |
  +---> 词元_1                           +---> 子目标_1 --> 子目标_2 --> 目标
  +---> 词元_2                                ^         ^              ^
  +---> ...                                   |         |              |
  +---> 词元_N                           [前向进化]
  |                                           |
  v                                           +---> 扩展
验证:对/错?                                  +---> 交叉(在子目标拼接)
                                              +---> 变异(替换片段)
(限制在高概率区域,                           |
 仅在末尾稀疏反馈)                            v
                                         在每个子目标验证
                                         (密集反馈,逃离概率壳)
一句话:从在模型概率景观中走单一路径,到绘制地形图并在路标间传送。
专家评审
选题眼光:这是真缺口。
自回归瓶颈在社区中众所周知——AlphaCode、树搜索方法、RL 微调在模型先验与解空间不对齐时都挣扎。
论文没有制造问题;它命名了实践者多年来一直碰到的东西。
时机恰当:随着模型在基准上停滞,自我改进是下一个前沿。
方法成熟度:核心思想(进化算法、后向链接)是旧的,但综合很巧妙。
理论动机(熵壳、指数级样本减少)是手摇的但方向正确——更多是直觉而非证明。
真正的贡献是展示这些想法在语言模型设定中协同工作。
然而,方法复杂:前向进化 + 后向分解 + 检查点对齐。
更简单的消融(例如,只有交叉没有后向搜索)会澄清什么是承重的。
论文暗示了这一点但没有完全隔离组件。
实验诚意:基线公平(best-of-N、MCTS、主流 RL 算法)。
训练后实验在其他方法失效处显示增益,这很有说服力。
在 AIME、GPQA 和 LiveCodeBench 上的推理时结果强劲,但论文没有报告方差或多个种子——难以知道增益是稳健的还是幸运的运行。
声称 BES”优于现有开源框架”得到支持,但比较仅针对开源;未包括闭源系统(o1、o3),所以我们不知道这在绝对景观中处于什么位置。
没有重大危险信号,但我想看到误差条。
写作功力:摘要和引言简洁。
方法部分密集——符号太多,直觉不够。
图 1 承担重任,但文本没有端到端走过具体例子。
相关工作彻底但读起来像清单。
最大的错失机会:论文没有解释何时 BES 有帮助 vs. 何时更简单的方法足够。
如果我重写一节,会是实验——添加失败分析,展示 BES 仍然挣扎的地方及原因。
判决:弱接收 — 方法新颖,结果有希望,但复杂性和不完整的消融留下关于什么是必要的问题。
论文推进了领域但需要更严格的分析才能成为强贡献。
要点总结
对实践者:
- 检查点作为搜索结构:如果你在做任何形式的搜索(RL、MCTS、采样),将任务分解为可验证的中间状态。
即使没有进化,密集反馈也胜过稀疏奖励。
- 重组胜过生成:当模型先验弱时,不要只是采样更多——重组部分解。
这适用于语言模型之外:任何可以在自然边界拼接输出的生成系统(代码在函数调用处,证明在引理处,计划在子目标处)。
- 后向规划作为工具:用模型生成子目标,而非只生成解。
这很便宜(一次后向传递)并给你路线图,即使前向搜索失败。
可迁移技术:“熵壳逃逸”框架对任何概率搜索有用。
如果你的样本聚集在狭窄区域,你需要在模态间跳跃的算子,而非只在模态内精炼。
交叉是这样的算子之一;其他包括基于类比的迁移或约束引导生成。
不可迁移的:具体实现(检查点交叉、递归分解)是为顺序推理任务定制的。
对于没有自然分解的任务(例如,图像生成、开放式对话),方法需要重新思考。