Paper: 2606.30639 Authors: Xuan Zhang, Wenxuan Zhang, See-Kiong Ng, Yang Deng Categories: cs.AI, cs.CL
The Gap
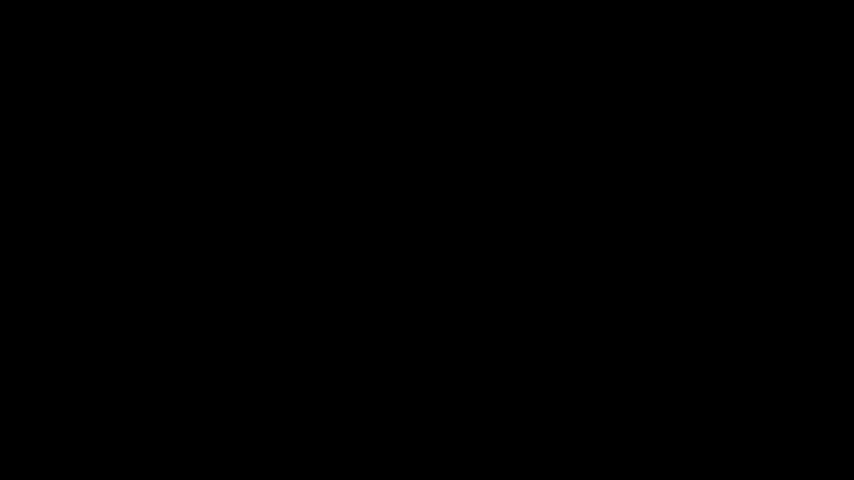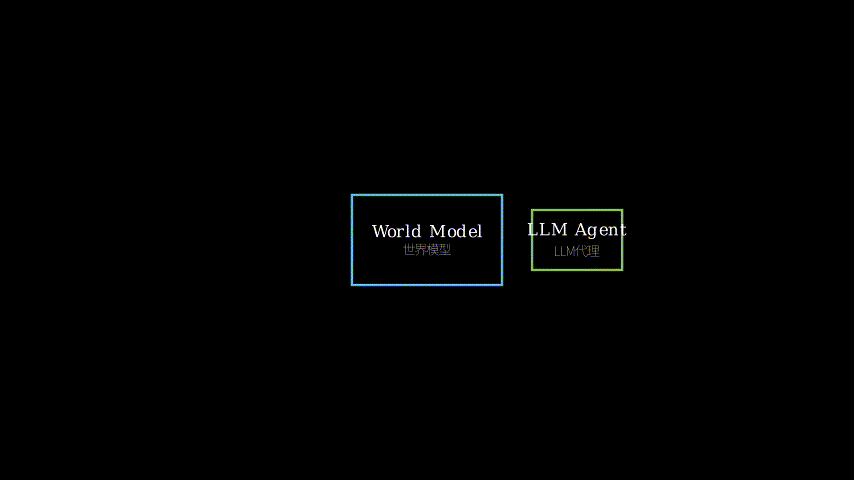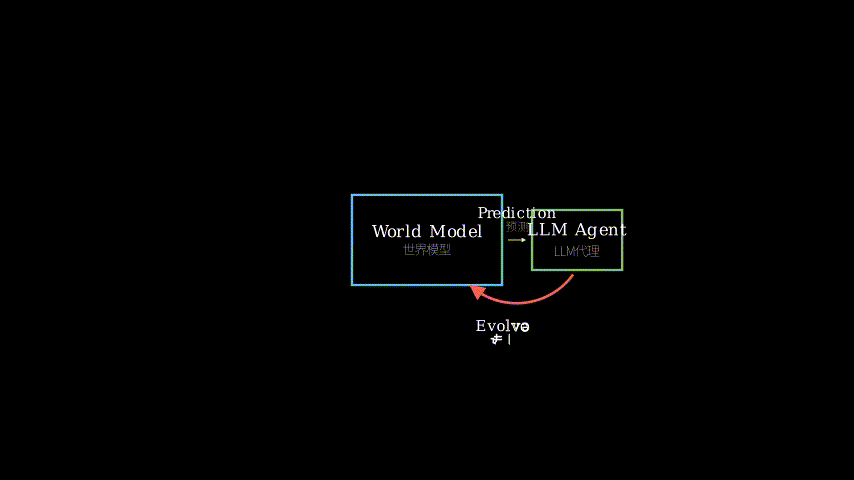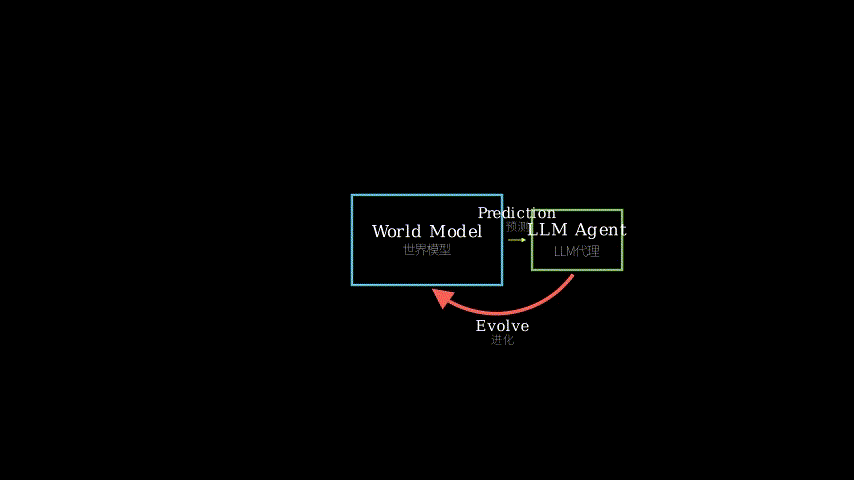
Existing research has built world models to give LLM agents foresight, but their predictions are often unreliable. If the model’s forecast is wrong, the agent might ignore it, misuse it, or even perform worse than without it. Prior approaches either used static, frozen world models that can’t learn from deployment experience, or required expensive fine-tuning to adapt. The core problem is a deployment-time adaptation gap: how to make a world model’s foresight more trustworthy and useful for planning *after it’s been deployed, without retraining the core models.
The logical path from gap to this paper’s contribution looks like this:
Problem: Unreliable world model foresight
    |
    v
Assumption: Deployment-time experience contains correct signals
    |
    v
Method: Build a memory-augmented context reviser (WorldEvolver)
    |
    v
Evidence: Higher prediction accuracy & agent success in testbeds
    |
    v
Conclusion: Test-time memory revision enhances both foresight & planning
The Increment
One sentence: Before this paper, world models were static advisors after training; after this paper, they become self-correcting systems that revise their own reasoning context in real-time based on what actually happens.
Core Mechanism
WorldEvolver doesn’t change the parameters of the LLM agent or the base world model. Instead, it sits between them as a dynamic memory manager that revises the context provided to the world model for future predictions. It works through three interconnected modules:
- Episodic Memory acts like a short-term, event-specific log. When the agent takes an action and observes the real outcome, this memory retrieves the most relevant past *real transitions. Instead of the world model generating a prediction from scratch, it now “simulates” by starting from a verified, real state from history.
- Semantic Memory operates on mismatches. When a world model prediction is significantly different from the observed reality, this module doesn’t just log the event; it distills a heuristic rule (e.g., “If you want to turn on a device, check if it’s plugged in first”). These rules accumulate and are injected as constraints or hints for future predictions.
- Selective Foresight is the quality control gate. Not every prediction the world model makes is confident or useful. This module evaluates the world model’s own confidence (or other signals) and filters out low-confidence predictions before they are given to the agent for reasoning. This prevents the agent from being misled by “hallucinated” foresight.
Data flows as follows: The agent acts -> The environment responds -> WorldEvolver updates both episodic and semantic memories with the new data -> When the agent needs to plan its next move, WorldEvolver retrieves memories to build a revised context -> Selective Foresight filters this context -> The frozen world model makes a prediction on this curated context -> The agent uses this improved prediction for planning.
Agent Action -> Environment Response
        |                     |
        v                     v
[ Update Memories ] (Episodic & Semantic)
        |
        v
[ Build Revised Context for World Model ]
        |
        v
[ Selective Foresight Gate ] (Filter low-confidence)
        |
        v
[ Frozen World Model ] (Predicts on refined context)
        |
        v
[ Agent Planning ]
Structural Metaphor
Think of WorldEvolver as a driving coach sitting in the passenger seat, and the LLM agent as the driver. The world model is the driver’s innate sense of “if I turn the wheel left, the car will go left.”
- Episodic Memory is the coach’s notebook of past drives. If the driver is about to turn left at a tricky intersection, the coach doesn’t rely on abstract rules. He flips open the notebook to the *exact time last week they made that same turn, showing what actually happened (the car skidded a little on gravel). This grounds the prediction in reality.
- Semantic Memory is the coach’s general wisdom, derived from reviewing those notes. After noticing skids happen repeatedly on gravelly turns, he extracts a rule: “On loose surfaces, reduce steering input.” He now whispers this rule to the driver *before the next turn, actively shaping the driver’s expectation.
- Selective Foresight is the coach’s judgment of when to offer advice. If the driver is on a straight, empty highway, the coach stays quiet. But if the driver approaches a complex merge, the coach actively provides guidance, knowing the driver’s own foresight might be shaky here. He filters out irrelevant or unreliable “what-ifs.”
Without the coach (WorldEvolver), the driver (agent) has a fixed, textbook understanding of driving (world model) that can fail on real, messy roads. The coach makes the driver’s practical understanding dynamic and grounded, all without teaching the driver a new way to physically operate the car.
Key Concepts
- Deployment-Time Context Revision: The central, clever idea. Most AI systems have two phases: training (learning) and inference (using). This paper argues for a powerful middle ground: learning how to set up the problem for a frozen model at inference time. It’s like a student who, before taking a math test, isn’t allowed to learn new formulas, but *is allowed to organize their notes, highlight key concepts, and decide which problems to attempt first based on past homework. The core knowledge is fixed, but the strategy for deploying it is optimized on the fly.
- Selective Foresight: A crucial filter for reliability. LLMs are known to generate plausible but incorrect text (hallucinations). World models inherit this risk. This concept is an admission that not all model outputs are equal. By actively gating predictions based on confidence or consistency, the system prevents the agent from reasoning on unstable foundations. It’s the difference between a weather forecast that says “70% chance of rain” versus “We’re not sure, maybe check outside,” and deciding whether to bring an umbrella based on that.
Framework Shift
Before (mainstream approach):        After (this paper):

[ Agent ]                            [ Agent ]
    |                                    |
    v                                    v
[ Static Context ]                 [ WorldEvolver ]
    |                                /    |    \
    v                              /     |     \
[ Frozen World Model ]       [Episodic] [Semantic] [Selective]
    |                           Mem.       Mem.      Gate
    v                              \     |     /
[ Prediction ]                      \    |    /
    |                                \   |   /
    v                                 v  v  v
[ Planning ]                    [ Revised Context ]
                                      |
                                      v
                                [ Frozen World Model ]
                                      |
                                      v
                                [ Gated Prediction ]
                                      |
                                      v
                                  [ Planning ]
From static advice to self-correcting counsel, the core shift is treating the world model’s input context as a learnable, mutable asset at test time, rather than a fixed artifact of the training process.
Expert Assessment
Problem choice: Excellent. The reliability of world models for long-horizon planning is a genuine and pressing bottleneck. Framing it as a deployment-time adaptation problem is insightful and practical. It sits at the intersection of memory-augmented agents and test-time optimization, a fruitful and active area.
Method maturity: Clever and modular. The decomposition into episodic, semantic, and selective memory is clean and motivated by cognitive science. It’s more nuanced than a brute-force “retrieve top-k similar memories” approach. A simpler approach (like just retrieving all past transitions) would likely be noisier and slower. This three-part system shows thoughtful design.
Experimental integrity: The baselines seem fair, testing against other memory and world model approaches. The use of multiple backbones (Llama, Mistral) is good practice. However, the testbeds (ALFWorld, ScienceWorld), while standard, are still relatively constrained, text-based environments. The paper’s claims about real-world applicability are extrapolated. I’d like to see more analysis on the Selective Foresight module—when does it filter, and does filtering ever become too conservative?
Writing quality: The paper is clear and well-structured. The Experimental Analysis section could be stronger. It shows *that it works, but deeper ablations into why—e.g., case studies of how a semantic rule corrected a persistent error, or a visualization of memory retrieval patterns—would elevate it from a solid system paper to a more insightful one.
Verdict: weak accept — It presents a well-motivated, novel, and effective mechanism for a real problem. While the environments are not massively complex, the core idea of self-evolving context through structured memory is compelling and likely to inspire follow-up work in more challenging domains.
Takeaways
- Separate the “Predictor” from the “Strategist”: You can often get big gains by keeping a powerful but frozen model (the Predictor) and building a lighter, adaptive system around it (the Strategist) that manages *how and when you query it. This is cheaper and more stable than fine-tuning the large model.
- Build Multi-Scale Memory Systems: Don’t just store raw data. Think about building at least two memory banks: one for specific, verbatim events (episodic) and one for distilled, general principles (semantic). Use mismatches between prediction and observation as the trigger to populate the semantic memory.
- Implement a Confidence Gate: When using any generative model for planning or reasoning, don’t treat all its outputs as gospel. Implement a simple filter based on the model’s own confidence scores, or consistency with retrieved knowledge, before passing its output to a critical decision-making step.
论文: 2606.30639 作者: Xuan Zhang, Wenxuan Zhang, See-Kiong Ng, Yang Deng 分类: cs.AI, cs.CL
缺口
现有研究已经为LLM代理构建了世界模型来提供预见性,但这些预测往往不可靠。 如果模型的预测错了,代理可能会忽略它、误用它,甚至比不用时表现更差。 此前的方法要么是使用静态、冻结的世界模型,无法从部署经验中学习; 要么需要昂贵的微调来适应。 核心问题是一个部署时适应缺口:如何在模型部署后、且不重新训练核心模型的情况下,让世界模型的预见对规划更可信、更有用。
从缺口到本文贡献的逻辑路径如下:
问题:世界模型预见不可靠
    |
    v
假设:部署时经验包含正确信号
    |
    v
方法:构建基于记忆的上下文修正器(WorldEvolver)
    |
    v
证据:在测试床中实现更高的预测准确率和代理成功率
    |
    v
结论:测试时的记忆修正能同时增强预见性和规划性能
增量
一句话: 本文之前,世界模型在训练后是静态的顾问;本文之后,它们变成了能够基于实际发生的事实时自我修正的系统。
核心机制
WorldEvolver 不改变LLM代理或基础世界模型的参数。 相反,它作为动态的记忆管理器位于两者之间,负责修正为世界模型未来预测提供的上下文。 它通过三个相互连接的模块工作:
- 情景记忆 像一个短期的、针对特定事件的日志。 当代理采取行动并观察到真实结果时,该记忆会检索最相关的过去真实转换。 世界模型不再从头生成预测,而是通过从历史中一个已验证的真实状态开始进行“模拟”。
- 语义记忆 处理预测与观察的不匹配。 当世界模型的预测与观测到的现实有显著差异时,该模块不只是记录事件,而是提炼出一条启发式规则(例如,“如果你想打开一个设备,先检查它是否插电”)。 这些规则会累积,并作为约束或提示注入到未来的预测中。
- 选择性预见 是质量控制关卡。 世界模型做出的每一个预测并非都可信或有用。 该模块评估世界模型自身的置信度(或其他信号),并在将低置信度预测交给代理进行推理之前将其过滤掉。 这防止了代理被“幻觉”预见所误导。
数据流如下:代理行动 -> 环境响应 -> WorldEvolver用新数据更新情景和语义记忆 -> 当代理需要规划下一步时,WorldEvolver检索记忆以构建修正后的上下文 -> 选择性预见过滤该上下文 -> 冻结的世界模型基于这个精心策划的上下文做出预测 -> 代理使用这个改进后的预测进行规划。
代理行动 -> 环境响应
        |                     |
        v                     v
[ 更新记忆 ](情景与语义)
        |
        v
[ 为世界模型构建修正后上下文 ]
        |
        v
[ 选择性预见门控 ](过滤低置信度)
        |
        v
[ 冻结的世界模型 ](基于精炼上下文预测)
        |
        v
[ 代理规划 ]
结构性比喻
把WorldEvolver想象成坐在副驾驶座的驾驶教练,LLM代理是司机。 世界模型是司机固有的“如果我把方向盘向左转,车就会向左开”的直觉。
- 情景记忆 是教练过去驾驶经历的笔记本。 如果司机准备在一个棘手的路口左转,教练不依赖抽象规则。 他翻到笔记本中上周在同一个地方转弯的确切记录,展示实际发生了什么(车在砂石地上稍微打滑了)。 这让预测基于现实。
- 语义记忆 是教练通过回顾那些笔记得出的通用智慧。 在注意到砂石路转弯时反复打滑后,他提炼出一条规则:“在松散路面上,减少转向幅度。” 他现在会在下次转弯前把这条规则低声告诉司机,主动塑造司机的预期。
- 选择性预见 是教练判断何时提供建议的智慧。 如果司机在笔直空旷的高速公路上,教练就保持沉默。 但如果司机要驶入复杂的并道区,教练会主动提供指导,因为他知道司机自己的预见在这里可能不稳。 他会过滤掉无关或不可靠的“假设情况”。
没有教练(WorldEvolver),司机(代理)拥有的是对驾驶(世界模型)固定的、教科书式的理解,在真实、混乱的道路上可能会失败。 教练让司机的实践理解变得动态且基于现实,而完全不需要教司机一种新的物理操作汽车的方式。
关键概念
- 部署时上下文修正:核心的巧妙思想。 大多数AI系统有两个阶段:训练(学习)和推理(使用)。 本文提出了一个强大的中间地带:在推理时学习如何为冻结的模型设置问题。 这就像一个学生,在参加数学考试前,不允许学习新公式,但被允许根据过去的作业来整理笔记、高亮关键概念,并决定先尝试哪些题目。 核心知识是固定的,但部署它的策略是在运行中优化的。
- 选择性预见:确保可靠性的关键过滤器。 LLMs以生成看似合理但不正确的文本(幻觉)而闻名。 世界模型继承了这一风险。 这一概念承认并非所有模型输出都同等重要。 通过基于置信度或一致性主动过滤预测,系统防止代理在不稳固的基础上进行推理。 这就像天气预报说“70%概率下雨”和“我们不确定,也许你该看看外面”的区别,并据此决定是否带伞。
框架转变
之前(主流方法):                之后(本文方法):

[ 代理 ]                        [ 代理 ]
    |                                |
    v                                v
[ 静态上下文 ]                 [ WorldEvolver ]
    |                              /    |    \
    v                            /     |     \
[ 冻结的世界模型 ]        [情景] [语义] [选择性]
    |                           记忆   记忆   门控
    v                            \     |     /
[ 预测 ]                         \    |    /
    |                             \   |   /
    v                              v  v  v
[ 规划 ]                    [ 修正后的上下文 ]
                                  |
                                  v
                            [ 冻结的世界模型 ]
                                  |
                                  v
                            [ 被门控的预测 ]
                                  |
                                  v
                                [ 规划 ]
从静态建议到自我修正的辅导,核心转变是将世界模型的输入上下文视为测试时一个可学习、可修改的资产,而非训练过程的固定产物。
专家评审
选题眼光: 非常好。 世界模型对长期规划的可靠性是一个真实且紧迫的瓶颈。 将其定义为部署时适应问题是深刻且实用的。 它位于记忆增强代理和测试时优化的交叉点,这是一个富有成效且活跃的领域。
方法成熟度: 巧妙且模块化。 分解为情景、语义和选择性记忆很清晰,并受认知科学启发。 它比“检索最相似的top-k记忆”的蛮力方法更细致。 更简单的方法(比如只检索所有过往转换)可能会更嘈杂、更慢。 这个三部分系统展现了深思熟虑的设计。
实验诚意: 基线看起来是公平的,与其他记忆和世界模型方法进行了测试。 使用多种骨干网络(Llama, Mistral)是很好的实践。 然而,测试床(ALFWorld, ScienceWorld)虽然标准,但仍然是相对受限的、基于文本的环境。 论文关于现实世界适用性的说法是外推的。 我希望看到更多关于选择性预见模块的分析——它何时过滤,过滤会不会变得过于保守?
写作功力: 论文清晰且结构良好。 实验分析部分可以更强。 它展示了为什么有效,但更深入的消融研究——例如,展示语义规则如何修正了持续性错误的案例研究,或记忆检索模式的可视化——将把它从一篇扎实的系统论文提升为更具洞见的作品。
判决: 弱接收 — 它针对一个真实问题提出了一个动机充分、新颖且有效的机制。 尽管环境并不特别复杂,但通过结构化记忆实现上下文自我进化的思想引人注目,并可能启发在更挑战性领域中的后续工作。
要点总结
- 分离“预测器”与“策略师”:你通常可以通过保持一个强大但冻结的模型(预测器),并在其周围构建一个更轻量、自适应的系统(策略师)来管理**如何以及何时*查询它,从而获得巨大收益。 这比微调大模型更便宜、更稳定。
- 构建多尺度记忆系统:不要只存储原始数据。 考虑至少建立两个记忆库:一个用于具体、逐字事件(情景),一个用于提炼的、通用原则(语义)。 利用预测与观察之间的不匹配作为填充语义记忆的触发器。
- 实现置信度门控:当使用任何生成模型进行规划或推理时,不要将它的所有输出都当作真理。 在将输出传递给关键决策步骤之前,根据模型自身的置信度分数,或与检索到的知识的一致性,实现一个简单的过滤器。