Paper: 2606.05122 Authors: XiuYu Zhang, Yi Shan, Junfeng Fang, Zhenkai Liang Categories: cs.CL
The Gap
Current approaches treat LLM self-evaluation as a training problem: teach the model to predict judge scores through extensive reinforcement learning. The RewardBench baseline requires ~5000 examples. This assumes the ability must be acquired from scratch.
But what if the ability is already there, just hidden? The authors find that base models, with only few-shot prompting, already predict external judge scores well above chance. The gap: no one tried to elicit this latent capability efficiently instead of training it from zero.
Problem: LLM needs to predict judge scores
         |
         v
Assumption: Base models lack this ability
         |
         v
Old method: Train with 5000+ RL examples
         |
         v
This paper's insight: Ability already exists latently
         |
         v
New method: Elicit with 160 examples (SEE)
         |
         v
Evidence: Matches RL baseline calibration, 31x fewer examples
         |
         v
Conclusion: Self-evaluation is elicitation, not acquisition
The Increment
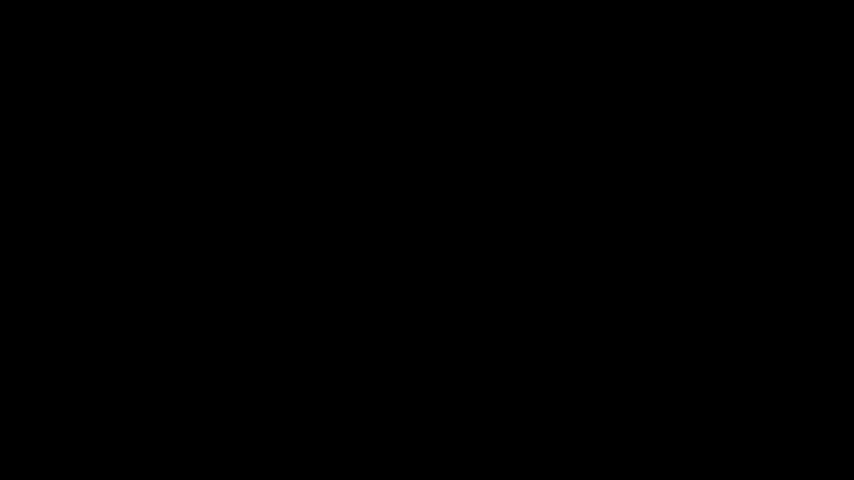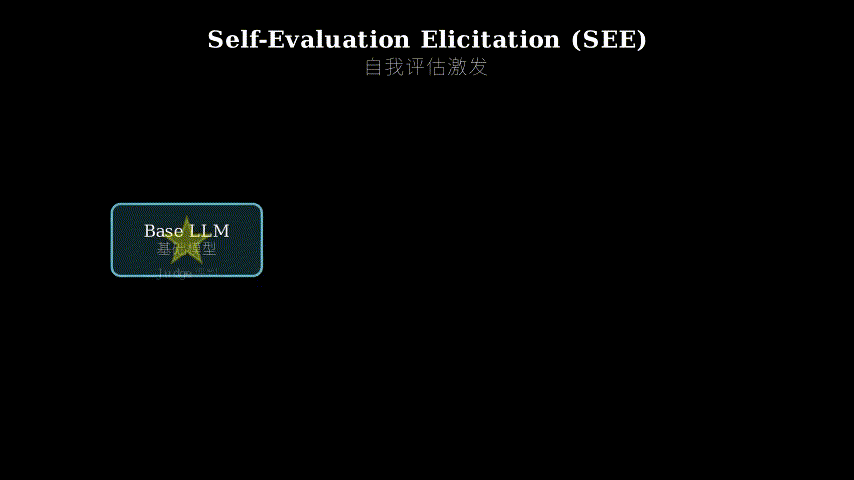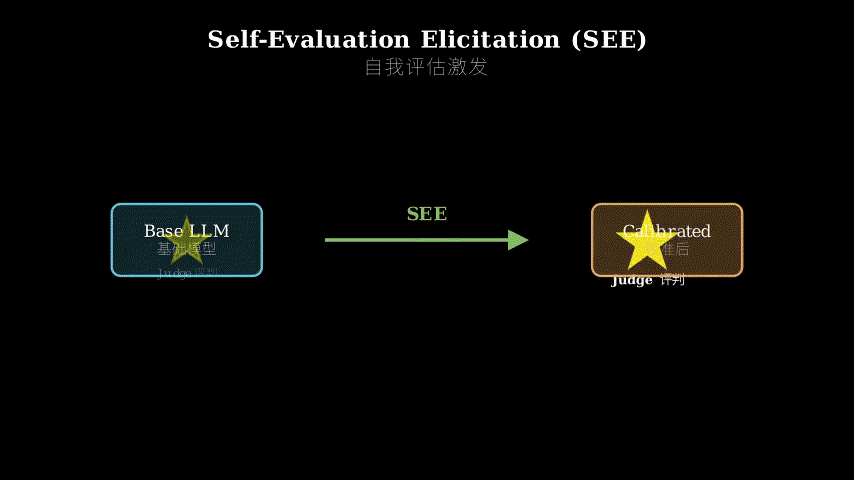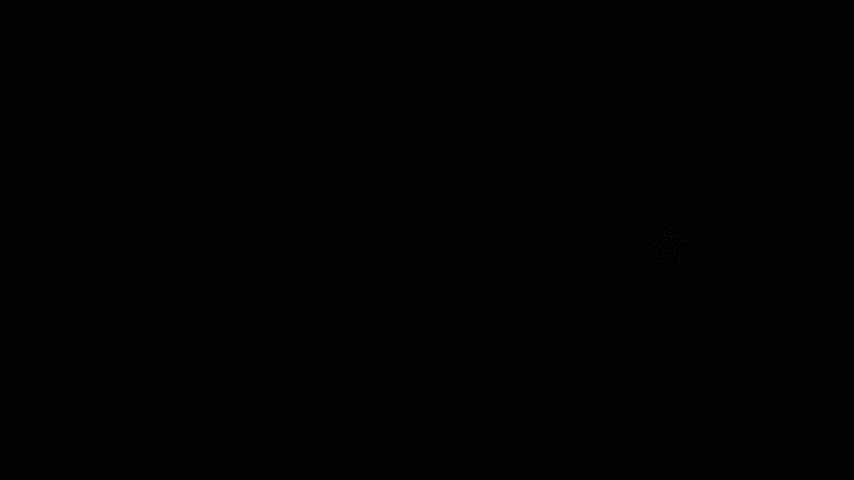
One sentence: Before, we trained models to evaluate themselves with thousands of examples; now, we elicit a pre-existing latent ability with 160 examples by coupling answer improvement with judge prediction.
Core Mechanism
SEE (Self-Evaluation Elicitation) has two phases. First, calibration-coupled RL: the model learns to both improve its answer AND predict how a judge will score it. The prediction happens before seeing the actual judge score, forcing the model to internalize quality signals. Second, masked distillation: the model’s answer tokens are frozen, and only the prediction head is updated. This sharpens the self-evaluation without degrading answer quality.
The cycle runs on just 160 unique examples. During calibration-coupled RL, the model generates an answer, predicts the judge’s multi-attribute scores (e.g., helpfulness, harmlessness), then sees the actual scores. It gets reward for both better answers and more accurate predictions. During masked distillation, the model sees the same examples again, but this time only the prediction mechanism is updated using the RL-generated trajectory as teaching signal.
Input prompt
     |
     v
[Generate answer] --> frozen in phase 2
     |
     v
[Predict judge scores] <-- updated in both phases
     |
     v
[See actual judge scores]
     |
     v
RL reward = answer quality + prediction accuracy
     |
     v
Phase 1: update both answer + prediction
Phase 2: update only prediction (answer frozen)
Think of it like learning to cook while learning to taste. Phase 1 is cooking practice: you make a dish, guess how a food critic would rate it, then see their actual rating. You improve both your cooking and your ability to predict the critic. Phase 2 is pure tasting practice: you taste dishes you already made, refine your prediction of the critic’s rating, but don’t change the dishes themselves. The coupling in phase 1 is key—you can’t learn to predict the critic in isolation; you need to feel how changes in your cooking change the scores.
Key Concepts
-
Latent judge calibration: The base model already contains implicit knowledge of what makes a good answer. When you ask it to predict how a judge will score its own output, it can do so above chance even without targeted training. This isn’t oracle knowledge—it’s pattern recognition from pretraining. The model saw enough judge-like feedback (ratings, critiques, preferences) during pretraining that it internalized a quality model. SEE surfaces this latent model instead of building a new one from scratch.
-
Calibration-coupled RL: Traditional RL optimizes answer quality. Traditional supervised learning optimizes prediction accuracy. Coupling means optimizing both simultaneously with a shared reward signal. The magic: when the model tries to predict the judge while improving the answer, it can’t just memorize judge behavior—it must learn the underlying quality notion that drives the judge’s decisions. It’s like learning physics by predicting experiment outcomes while designing experiments. The coupling forces you to learn principles, not just correlations.
-
Masked distillation: After RL, you have a model that’s decent at both answering and predicting. But the answer quality might have drifted, and the prediction could be sharper. Masked distillation freezes the answer generation (masks those tokens) and distills only the prediction capability from the RL trajectory. You’re extracting the “tasting” skill while leaving the “cooking” skill untouched. The RL trajectory becomes the teacher: “here’s how you predicted when you were coupled with answer improvement—now do that consistently.”
Framework Shift
Before (RL baseline):                  After (SEE):

Train from scratch                     Elicit pre-existing ability
    |                                      |
    v                                      v
[5000 examples]                        [160 examples]
    |                                      |
    v                                      v
[RL: optimize answer]                  [Phase 1: couple answer + predict]
    |                                      |
    v                                      v
[Separate: train predictor]            [Phase 2: distill predict, freeze answer]
    |                                      |
    v                                      v
Judge-aligned model                    Judge-aligned model
(acquisition paradigm)                 (elicitation paradigm)
From “train a new skill with lots of data” to “surface a hidden skill with minimal data,” the core shift is recognizing that pretraining already embedded judge calibration.
Expert Assessment
Problem choice: Real gap. The field assumed self-evaluation requires extensive training, but the authors checked the null hypothesis first: does the base model already know something? The few-shot baseline (Table 1) is a simple sanity check no one did. This paper sits at the boundary between scaling (more data solves everything) and efficiency (maybe data isn’t the bottleneck). Important framing shift.
Method maturity: Clever. Coupling answer improvement with prediction is the key insight—it prevents the model from learning superficial judge patterns. The masked distillation phase is a neat trick to preserve answer quality while sharpening prediction. However, the method still uses RL, just less of it. The ablation (Table 2) shows removing coupling or distillation hurts, but doesn’t explore simpler alternatives like direct few-shot calibration with better prompting or retrieval-augmented few-shot. The 31x data reduction is impressive, but we don’t know if 160 is near the minimum or just “good enough.”
Experimental integrity: Solid. Three benchmarks (RewardBench, MT-Bench, AlpacaEval 2), multiple judges (GPT-4, Claude, Llama-3-70B), held-out judge transfer tested. Baselines are fair: they compare to a strong RL method and show few-shot base model performance. The calibration metrics (Table 1, 3) are appropriate. One concern: all experiments use Llama-3.1-8B. No evidence this transfers to other model families or sizes. The “localized in token distribution” claim (Figure 3) needs more investigation—what happens with out-of-distribution judges?
Writing quality: Abstract is dense but precise. Introduction sets up the problem clearly. Methods section is straightforward. The weakness: Section 4 (results) buries the key insight. Table 1’s few-shot baseline is the paper’s most important result—it shows latent ability exists—but it’s presented as a side note. The paper would hit harder if it led with “base models already do this above chance” and then motivated SEE as the efficient path to full performance. The related work section is thin; more engagement with RLHF alternatives (DPO, rejection sampling) would strengthen positioning.
Verdict: weak accept — The reframing from acquisition to elicitation is valuable, the method is efficient, and the experiments are decent, but the scope is narrow (one model family, one setting) and the writing doesn’t foreground the core insight early enough.
Takeaways
Concrete ideas you can steal:
-
Check latent capabilities before training: Before scaling up training data, run a few-shot baseline to see if the model already has a weak version of the target skill. If it does, elicitation methods (prompting, lightweight fine-tuning) might work better than training from scratch.
-
Couple related tasks during training: If you’re training a model to do X and you also want it to predict Y (where Y is related to X’s quality), train both together. The coupling forces the model to learn shared structure rather than task-specific heuristics. Example: training a code generator? Couple it with predicting test pass rate.
-
Masked distillation for selective updates: After training, if one capability drifted but another improved, freeze the drifted part and distill only the improved part from the training trajectory. Useful when you want to sharpen one skill without risking others.
-
Calibration as a diagnostic: Use a model’s ability to predict external judges as a probe for whether it learned generalizable quality notions vs. memorized judge quirks. If predictions transfer across judges, the model learned something real.
论文: 2606.05122 作者: XiuYu Zhang, Yi Shan, Junfeng Fang, Zhenkai Liang 分类: cs.CL
缺口
现有方法将大模型的自我评估视为训练问题:通过大量强化学习教会模型预测评判者的打分。
RewardBench 基线需要约 5000 个样本。
这假设了能力必须从零开始习得。
但如果能力已经存在,只是被隐藏了呢?
作者发现,基础模型仅通过少样本提示,就已经能远高于随机水平地预测外部评判者的打分。
缺口在于:没人尝试高效地唤醒这种潜在能力,而非从零训练。
问题:大模型需要预测评判者打分
         |
         v
假设:基础模型缺乏这种能力
         |
         v
旧方法:用 5000+ 强化学习样本训练
         |
         v
本文洞察:能力已潜在存在
         |
         v
新方法:用 160 个样本唤醒(SEE)
         |
         v
证据:校准效果匹配强化学习基线,样本数减少 31 倍
         |
         v
结论:自我评估是唤醒问题,而非习得问题
增量
一句话: 以前,我们用数千样本训练模型自我评估;现在,我们通过将答案改进与评判预测耦合,用 160 个样本唤醒一个预存在的潜在能力。
核心机制
SEE(自我评估唤醒)有两个阶段。
第一阶段是校准耦合强化学习:模型学习同时改进答案并预测评判者会如何打分。
预测发生在看到实际评判分数之前,迫使模型内化质量信号。
第二阶段是掩码蒸馏:模型的答案 token 被冻结,只更新预测头。
这样在不降低答案质量的情况下锐化自我评估。
整个循环只在 160 个独特样本上运行。
在校准耦合强化学习期间,模型生成答案,预测评判者的多属性分数(如有用性、无害性),然后看到实际分数。
它因更好的答案和更准确的预测获得奖励。
在掩码蒸馏期间,模型再次看到相同样本,但这次只更新预测机制,使用强化学习生成的轨迹作为教学信号。
输入提示
     |
     v
[生成答案] --> 在阶段2中冻结
     |
     v
[预测评判者分数] <-- 在两个阶段都更新
     |
     v
[看到实际评判者分数]
     |
     v
强化学习奖励 = 答案质量 + 预测准确性
     |
     v
阶段1:更新答案和预测
阶段2:只更新预测(答案冻结)
想象一边学做菜一边学品尝。
阶段1是烹饪练习:你做一道菜,猜测美食评论家会如何评分,然后看到他们的实际评分。
你同时提升烹饪和预测评论家的能力。
阶段2是纯品尝练习:你品尝已经做好的菜,精炼对评论家评分的预测,但不改变菜本身。
阶段1的耦合是关键——你不能孤立地学习预测评论家;你需要感受烹饪的变化如何改变分数。
关键概念
- 潜在评判校准: 基础模型已经包含了什么是好答案的隐性知识。
当你要求它预测评判者会如何给自己的输出打分时,即使没有针对性训练,它也能做到高于随机水平。
这不是先知般的知识——而是预训练中的模式识别。
模型在预训练期间见过足够多的类评判反馈(评分、批评、偏好),因此内化了一个质量模型。
SEE 将这个潜在模型浮现出来,而不是从头构建新模型。
- 校准耦合强化学习: 传统强化学习优化答案质量。
传统监督学习优化预测准确性。
耦合意味着用共享奖励信号同时优化两者。
神奇之处:当模型在改进答案的同时尝试预测评判者时,它不能只是记忆评判者行为——它必须学习驱动评判者决策的底层质量概念。
就像通过预测实验结果同时设计实验来学习物理学。
耦合迫使你学习原理,而非仅仅相关性。
- 掩码蒸馏: 强化学习后,你有一个在回答和预测方面都不错的模型。
但答案质量可能漂移了,预测也可以更锐利。
掩码蒸馏冻结答案生成(掩盖那些 token),只从强化学习轨迹中蒸馏预测能力。
你提取”品尝”技能,同时保持”烹饪”技能不变。
强化学习轨迹成为教师:“这是你在与答案改进耦合时的预测方式——现在稳定地这样做。
“
框架转变
之前(强化学习基线):              之后(SEE):

从零开始训练                        唤醒预存在能力
    |                                  |
    v                                  v
[5000 个样本]                        [160 个样本]
    |                                  |
    v                                  v
[强化学习:优化答案]                  [阶段1:耦合答案和预测]
    |                                  |
    v                                  v
[分开:训练预测器]                    [阶段2:蒸馏预测,冻结答案]
    |                                  |
    v                                  v
评判对齐模型                          评判对齐模型
(习得范式)                          (唤醒范式)
从”用大量数据训练新技能”到”用最少数据浮现隐藏技能”,核心转变是认识到预训练已经嵌入了评判校准。
专家评审
选题眼光: 真缺口。
该领域假设自我评估需要大量训练,但作者先检验了零假设:基础模型已经知道些什么吗?
少样本基线(表1)是一个没人做过的简单完整性检查。
本文处于扩展(更多数据解决一切)和效率(也许数据不是瓶颈)的边界。
重要的思维框架转变。
方法成熟度: 巧妙。
将答案改进与预测耦合是关键洞察——它防止模型学习肤浅的评判者模式。
掩码蒸馏阶段是保持答案质量同时锐化预测的巧妙技巧。
然而,该方法仍使用强化学习,只是用得更少。
消融实验(表2)显示移除耦合或蒸馏会造成损害,但没有探索更简单的替代方案,如通过更好的提示或检索增强少样本进行直接少样本校准。
31 倍的数据减少令人印象深刻,但我们不知道 160 是否接近最小值还是只是”足够好”。
实验诚意: 扎实。
三个基准(RewardBench、MT-Bench、AlpacaEval 2),多个评判者(GPT-4、Claude、Llama-3-70B),测试了留出评判者的迁移。
基线公平:他们与强大的强化学习方法比较,并展示了少样本基础模型性能。
校准指标(表1、3)合适。
一个担忧:所有实验使用 Llama-3.1-8B。
没有证据表明这能迁移到其他模型家族或尺寸。
“定位在 token 分布中”的声称(图3)需要更多调查——在分布外评判者上会发生什么?
写作功力: 摘要密集但精准。
引言清晰地设定了问题。
方法部分直接了当。
弱点:第4节(结果)埋没了关键洞察。
表1的少样本基线是论文最重要的结果——它显示潜在能力存在——但它作为旁注呈现。
如果论文以”基础模型已经高于随机水平地做到这一点”开头,然后将 SEE 定位为达到完整性能的高效路径,论文会更有力。
相关工作部分单薄;与 RLHF 替代方案(DPO、拒绝采样)的更多互动会加强定位。
判决: 弱接收 — 从习得到唤醒的重构有价值,方法高效,实验不错,但范围狭窄(一个模型家族,一个设置),写作没有足够早地突出核心洞察。
要点总结
你能偷走的具体想法:
- 训练前检查潜在能力: 在扩大训练数据之前,运行少样本基线,看看模型是否已经有目标技能的弱版本。
如果有,唤醒方法(提示、轻量微调)可能比从头训练效果更好。
- 训练期间耦合相关任务: 如果你正在训练模型做 X,并且你也希望它预测 Y(其中 Y 与 X 的质量相关),一起训练两者。
耦合迫使模型学习共享结构而不是任务特定的启发式。
示例:训练代码生成器?
将它与预测测试通过率耦合。
- 用于选择性更新的掩码蒸馏: 训练后,如果一种能力漂移但另一种提升了,冻结漂移的部分,只从训练轨迹蒸馏提升的部分。
当你想锐化一种技能而不冒险损害其他技能时很有用。
- 校准作为诊断: 使用模型预测外部评判者的能力作为探针,判断它是学习了可泛化的质量概念还是记忆了评判者怪癖。
如果预测在评判者间迁移,模型学到了真实的东西。