Paper: 2604.26940 Authors: Wenxuan Ye, Yangyang Zhang, Xueli An, Georg Carle, Yunpu Ma Categories: cs.CL
The Gap
Small language models (SLMs) are fast and cheap to deploy, but they reason poorly compared to large models (LLMs). Current fixes fall into two camps: (1) call an LLM at divergence points to generate better tokens, which adds latency and cost, or (2) distill the LLM’s full generative distribution into the SLM, which fails because small models lack the capacity to mimic complex distributions accurately.
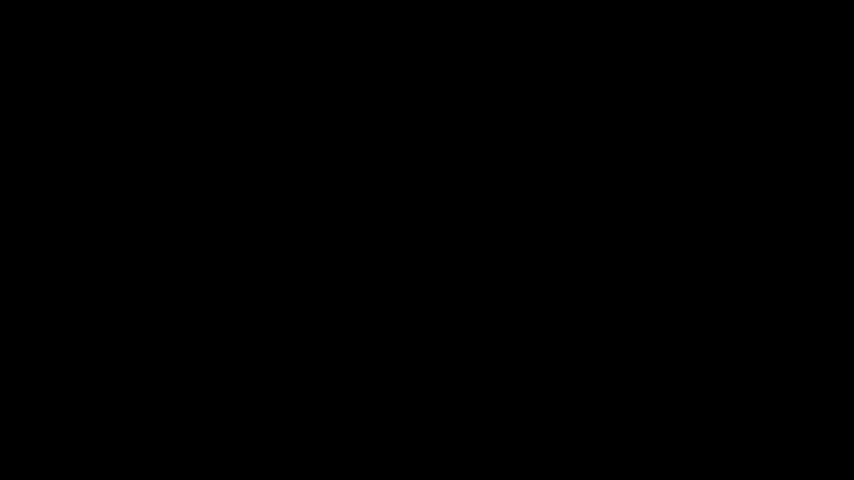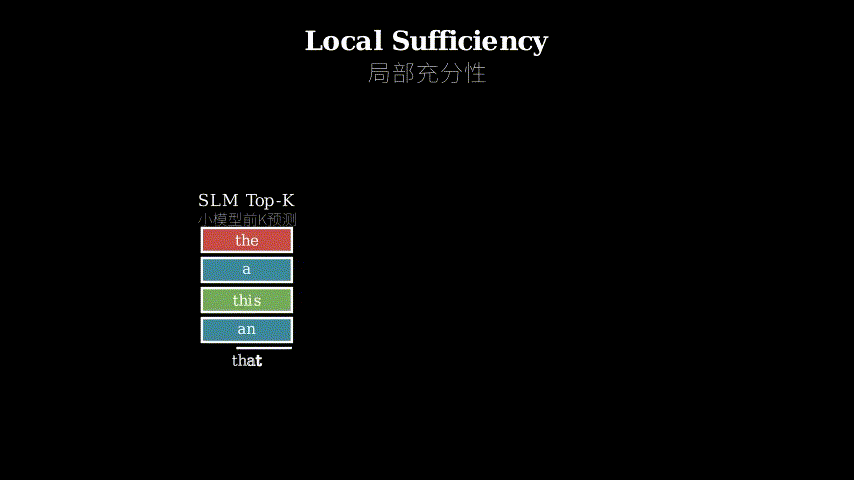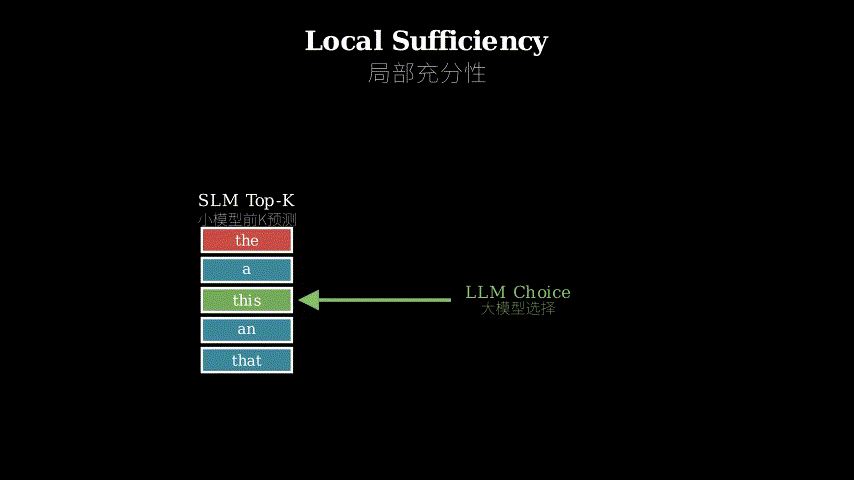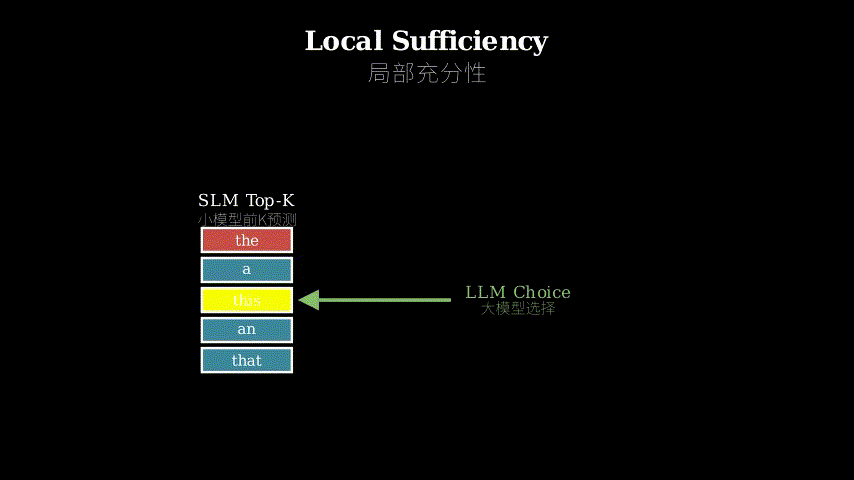
The paper identifies a middle ground: at reasoning divergence points, the LLM’s preferred token is almost always hiding in the SLM’s top-K predictions (95% hit rate in top-8), just not ranked first. This observation—called “local sufficiency”—suggests the SLM already knows the right answer; it just needs help picking it.
Problem: SLMs reason poorly
   |
   v
Observation: LLM's choice is in SLM's top-K (95% hit rate)
   |
   +---> Method: Train SLM to re-rank its own top-K
   |
   v
Evidence: 24.1% improvement, matches 8-path self-consistency
   |
   v
Conclusion: Selection > generation for distillation
The Increment
One sentence: Before this paper, small models either called large models at runtime (slow) or tried to mimic their full output distribution (failed); after, small models learn to re-rank their own top-K candidates using distilled selection logic (fast + effective).
Core Mechanism
S2T has two phases. First, S2T-ORACLE uses the LLM as a selector during inference: when the SLM’s top-1 token diverges from what the LLM would pick, the LLM chooses among the SLM’s top-K candidates instead of generating freely. This reframes the LLM’s role from open-ended generation (hard supervision signal) to discrete ranking (simple supervision signal).
Second, S2T-LOCAL distills this selection behavior into the SLM itself. The SLM learns a re-ranking head that scores its own top-K candidates, trained on examples where the LLM’s choice differed from the SLM’s greedy pick. At inference, the SLM generates top-K, re-ranks them, and picks the highest-scoring token—no LLM needed.
Training:
  SLM generates top-K --> LLM selects best --> record (context, top-K, LLM choice)
                                                         |
                                                         v
                                              Train re-ranking head on SLM

Inference:
  SLM generates top-K --> SLM re-ranks --> pick top-1 --> continue
       ^                                                      |
       |______________________________________________________| (loop)
Think of it like a chess student who generates candidate moves but doesn’t know which is best. The master (LLM) doesn’t demonstrate new moves; instead, they point to the best move among the student’s candidates and explain why. After enough examples, the student internalizes the selection criteria and can self-correct without the master present. The key insight: the student already generates good moves (local sufficiency), they just need to learn which one to trust.
Key Concepts
-
Local sufficiency: At reasoning divergence points, the token the LLM would pick is almost always present in the SLM’s top-K predictions, even when it’s not the SLM’s top-1 choice. This means the SLM’s probability distribution already assigns non-trivial mass to the correct token—it’s a ranking problem, not a generation problem. Empirically, 95% of the time, the LLM’s choice appears in the SLM’s top-8. This is surprising because it suggests capacity limitations manifest as ranking errors, not missing knowledge.
-
Selection vs generation distillation: Traditional distillation trains the SLM to match the LLM’s full output distribution over the entire vocabulary (tens of thousands of tokens). This is hard because the LLM’s distribution is complex and the SLM lacks capacity. Selection distillation simplifies the task: given K candidates (typically 8), pick the best one. The supervision signal shrinks from a 50k-dimensional probability vector to a discrete choice among 8 options. This is easier to learn and more robust to capacity mismatch.
-
Divergence-triggered re-ranking: The SLM doesn’t re-rank at every token. It only activates the re-ranking head when its top-1 prediction differs from what the LLM would pick (detected during training via oracle access, or approximated during inference via a learned divergence detector). This keeps overhead low—most tokens are generated greedily, and re-ranking only fires at critical reasoning junctions (typically 10-20% of tokens).
Framework Shift
Before (mainstream approach):          After (this paper):

LLM (32B)                              SLM (1.5B)
   |                                      |
   | generate token                       | generate top-K
   v                                      v
[full vocab distribution]              [K=8 candidates]
   |                                      |
   | distill                              | re-rank (learned)
   v                                      v
SLM (1.5B)                             [pick best]
   |                                      |
   | mimic distribution (fails)           | continue
   v
[poor reasoning]                       [improved reasoning]

OR:                                    No runtime LLM call
                                       No distribution matching
SLM generates                          Just: propose + select
   |
   | divergence detected
   v
LLM called at runtime
   |
   | generate token (slow)
   v
continue
From “teach the small model to think like the large model” to “teach the small model to pick the right answer from its own proposals,” the core shift is supervision simplification.
Expert Assessment
Problem choice: Real gap. The SLM deployment dilemma (speed vs quality) is acute in production. The observation of local sufficiency is non-obvious and well-motivated—if true, it changes how we think about capacity limitations. The paper positions itself against both runtime LLM calls (FrugalGPT, Hybrid LLM) and standard distillation, which is the right framing.
Method maturity: The core insight (local sufficiency) is clever and empirically validated. The method is straightforward—no architectural tricks, just reframing the supervision signal. However, the divergence detection mechanism (how to know when to re-rank without oracle LLM access) is underspecified. The paper mentions a “learned divergence detector” but doesn’t detail its architecture or failure modes. This is a load-bearing component that deserves more scrutiny.
Experimental integrity: Baselines are fair (greedy decoding, self-consistency, speculative decoding, standard distillation). The 95% hit rate claim is strong and well-documented. The 24.1% improvement is averaged across multiple benchmarks (GSM8K, MATH, etc.), which is good practice. However, the paper doesn’t report variance or confidence intervals, and the ablation on K (why 8?) is thin. The comparison to 8-path self-consistency is compelling but slightly apples-to-oranges (single-trajectory vs ensemble).
Writing quality: The abstract and intro are crisp. The method section is clear but rushes through divergence detection. The related work section is thorough. The results section could use error bars and per-benchmark breakdowns. The paper would benefit from a failure analysis—when does re-ranking fail? What types of reasoning errors persist?
Verdict: weak accept — Solid empirical contribution with a useful insight (local sufficiency), but the divergence detection mechanism needs more detail and the experimental analysis could be deeper.
Takeaways
For practitioners: If you’re deploying small models and can’t afford runtime LLM calls, this paper offers a concrete recipe: (1) collect divergence points where your SLM’s top-1 differs from an LLM’s choice, (2) train a lightweight re-ranking head on the SLM’s top-K at those points, (3) use the re-ranking head at inference to self-correct. The key is that you only need the LLM during training, not deployment.
For researchers: The local sufficiency observation is the real contribution. It suggests that capacity limitations in small models manifest as ranking errors rather than missing knowledge. This reframes the distillation problem: instead of compressing the LLM’s full distribution (hard), compress its ranking preferences over a small candidate set (easier). This principle could extend beyond language models—anywhere a small model generates a candidate set, a larger model’s selection logic might be easier to distill than its generative distribution.
Transferable technique: The “propose then select” pattern. If your small model struggles with a task, check if the correct answer is in its top-K. If yes, train a selector. If no, you have a generation problem, not a ranking problem, and you need a different approach.
论文: 2604.26940 作者: Wenxuan Ye, Yangyang Zhang, Xueli An, Georg Carle, Yunpu Ma 分类: cs.CL
缺口
小语言模型(SLM)部署快、成本低,但推理能力远不如大模型(LLM)。
现有的解决方案分两类:(1)在推理分歧点调用 LLM 生成更好的 token,但这会增加延迟和成本;(2)将 LLM 的完整生成分布蒸馏到 SLM,但因为小模型容量不足,无法准确模仿复杂分布,所以失败。
本文发现了一个中间地带:在推理分歧点,LLM 偏好的 token 几乎总是藏在 SLM 的 top-K 预测中(top-8 命中率 95%),只是没排到第一位。
这个观察——称为”局部充分性”——说明 SLM 其实已经知道正确答案,只是需要帮助来选出它。
问题:SLM 推理能力差
   |
   v
观察:LLM 的选择在 SLM 的 top-K 中(95% 命中率)
   |
   +---> 方法:训练 SLM 重排自己的 top-K
   |
   v
证据:提升 24.1%,匹配 8 路自洽性
   |
   v
结论:选择 > 生成(对蒸馏而言)
增量
一句话: 这篇论文之前,小模型要么运行时调用大模型(慢),要么试图模仿大模型的完整输出分布(失败);之后,小模型学会用蒸馏的选择逻辑重排自己的 top-K 候选(快且有效)。
核心机制
S2T 分两个阶段。
第一阶段,S2T-ORACLE 在推理时把 LLM 当作选择器:当 SLM 的 top-1 token 与 LLM 的选择分歧时,LLM 从 SLM 的 top-K 候选中选一个,而不是自由生成。
这把 LLM 的角色从开放式生成(监督信号复杂)重构为离散排序(监督信号简单)。
第二阶段,S2T-LOCAL 把这个选择行为蒸馏到 SLM 自身。
SLM 学习一个重排头,给自己的 top-K 候选打分,训练数据来自 LLM 的选择与 SLM 贪心选择不同的例子。
推理时,SLM 生成 top-K,重排它们,选得分最高的 token——不需要 LLM。
训练:
  SLM 生成 top-K --> LLM 选最佳 --> 记录(上下文, top-K, LLM 选择)
                                                         |
                                                         v
                                              在 SLM 上训练重排头

推理:
  SLM 生成 top-K --> SLM 重排 --> 选 top-1 --> 继续
       ^                                            |
       |____________________________________________| (循环)
把它想象成一个象棋学生,能生成候选走法但不知道哪个最好。
师傅(LLM)不演示新走法,而是指出学生候选中的最佳走法并解释原因。
经过足够多的例子,学生内化了选择标准,可以在师傅不在场时自我纠正。
关键洞察:学生已经能生成好走法(局部充分性),只需要学会信任哪一个。
关键概念
- 局部充分性: 在推理分歧点,LLM 会选的 token 几乎总在 SLM 的 top-K 预测中,即使它不是 SLM 的 top-1 选择。
这意味着 SLM 的概率分布已经给正确 token 分配了非平凡的质量——这是排序问题,不是生成问题。
实证上,95% 的情况下,LLM 的选择出现在 SLM 的 top-8 中。
这很惊人,因为它表明容量限制表现为排序错误,而非缺失知识。
- 选择式蒸馏 vs 生成式蒸馏: 传统蒸馏训练 SLM 匹配 LLM 在整个词表上的完整输出分布(数万个 token)。
这很难,因为 LLM 的分布复杂,SLM 容量不足。
选择式蒸馏简化了任务:给定 K 个候选(通常 8 个),选最好的。
监督信号从 5 万维概率向量缩减为 8 个选项中的离散选择。
这更容易学习,对容量不匹配更鲁棒。
- 分歧触发的重排: SLM 不在每个 token 都重排。
只有当它的 top-1 预测与 LLM 的选择不同时,才激活重排头(训练时通过 oracle 访问检测,推理时通过学习的分歧检测器近似)。
这保持了低开销——大多数 token 贪心生成,重排只在关键推理节点触发(通常 10-20% 的 token)。
框架转变
之前(主流方法):                  之后(本文方法):

LLM (32B)                          SLM (1.5B)
   |                                  |
   | 生成 token                        | 生成 top-K
   v                                  v
[完整词表分布]                       [K=8 个候选]
   |                                  |
   | 蒸馏                              | 重排(学习的)
   v                                  v
SLM (1.5B)                         [选最佳]
   |                                  |
   | 模仿分布(失败)                   | 继续
   v
[推理差]                            [推理改善]

或者:                              无运行时 LLM 调用
                                   无分布匹配
SLM 生成                           只有:提议 + 选择
   |
   | 检测到分歧
   v
运行时调用 LLM
   |
   | 生成 token(慢)
   v
继续
从”教小模型像大模型一样思考”到”教小模型从自己的提议中选对答案”,核心转变是监督简化。
专家评审
选题眼光: 真缺口。
SLM 部署困境(速度 vs 质量)在生产中很尖锐。
局部充分性的观察非显而易见且动机充分——如果为真,它改变了我们对容量限制的理解。
论文针对运行时 LLM 调用(FrugalGPT、Hybrid LLM)和标准蒸馏两方面定位,框架正确。
方法成熟度: 核心洞察(局部充分性)巧妙且有实证验证。
方法直接——没有架构花招,只是重构监督信号。
但分歧检测机制(如何在没有 oracle LLM 访问时知道何时重排)描述不足。
论文提到”学习的分歧检测器”但没详述其架构或失败模式。
这是承重组件,值得更多审视。
实验诚意: 基线公平(贪心解码、自洽性、推测解码、标准蒸馏)。
95% 命中率的声明强且有充分记录。
24.1% 的提升在多个基准(GSM8K、MATH 等)上平均,这是好做法。
但论文没报告方差或置信区间,对 K 的消融(为什么是 8?)很薄。
与 8 路自洽性的比较有说服力,但略有苹果橙子之嫌(单轨迹 vs 集成)。
写作功力: 摘要和引言简洁。
方法部分清晰但在分歧检测上匆忙带过。
相关工作部分详尽。
结果部分需要误差条和逐基准分解。
论文会受益于失败分析——重排何时失败?哪些类型的推理错误持续存在?
判决: 弱接收 — 扎实的实证贡献,有用的洞察(局部充分性),但分歧检测机制需要更多细节,实验分析可以更深入。
要点总结
对实践者: 如果你在部署小模型且负担不起运行时 LLM 调用,本文提供了具体配方:(1)收集 SLM 的 top-1 与 LLM 选择不同的分歧点,(2)在这些点上用 SLM 的 top-K 训练轻量重排头,(3)推理时用重排头自我纠正。
关键是你只需要 LLM 参与训练,不需要部署时调用。
对研究者: 局部充分性观察是真正的贡献。
它表明小模型的容量限制表现为排序错误而非缺失知识。
这重构了蒸馏问题:不是压缩 LLM 的完整分布(难),而是压缩它在小候选集上的排序偏好(易)。
这个原则可能扩展到语言模型之外——任何小模型生成候选集的地方,大模型的选择逻辑可能比其生成分布更易蒸馏。
可迁移技术: “提议然后选择”模式。
如果你的小模型在某任务上挣扎,检查正确答案是否在它的 top-K 中。
如果是,训练一个选择器。
如果不是,你有生成问题而非排序问题,需要不同方法。