Paper: 2603.04392 Authors: Jiezhong Wu, Jack O’Brien, Jennifer Li, M. S. Krafczyk, Ved G. Shah, Amanda R. Wasserman, Daniel W. Apley, Gautham Narayan, Noelle I. Samia Categories: astro-ph.IM, cs.LG
The Gap
Astronomy is about to drown in data. The Vera Rubin Observatory will generate 10 million transient alerts per night — supernovae, asteroids, anything that changes in the sky. Current pipelines use physics-based MCMC codes that take hours per object to fit light curves and extract parameters like peak brightness or decay rate. That’s fine for hundreds of objects, catastrophic for millions.
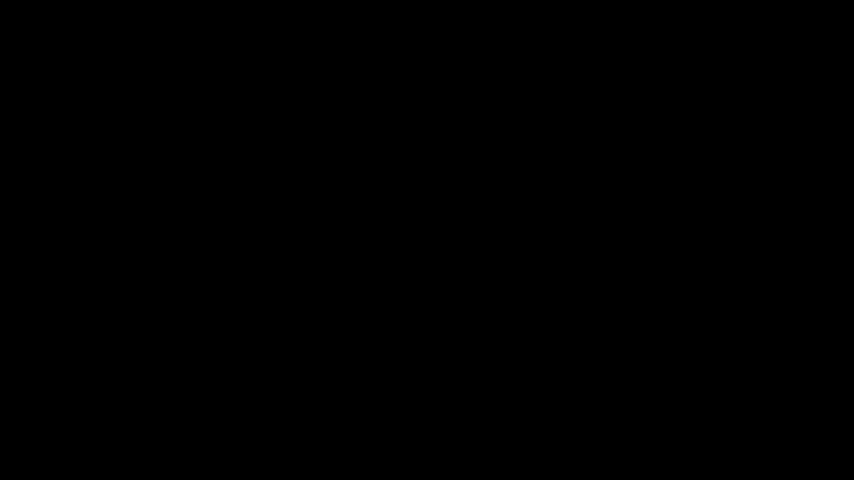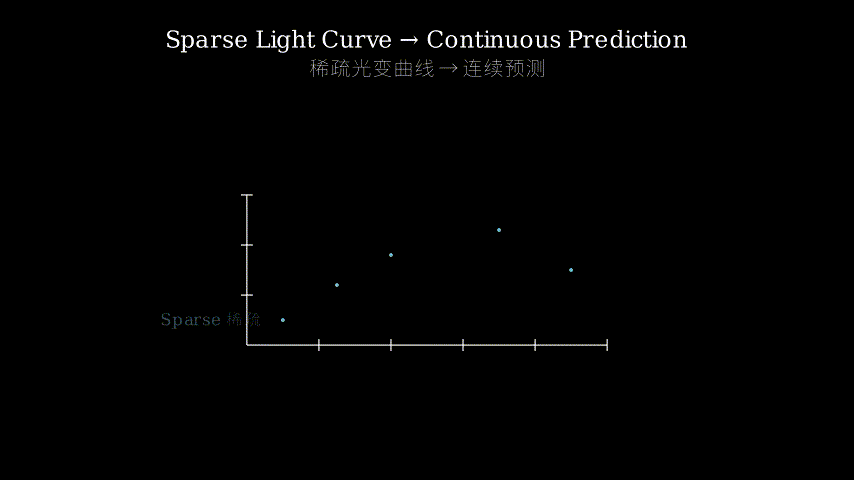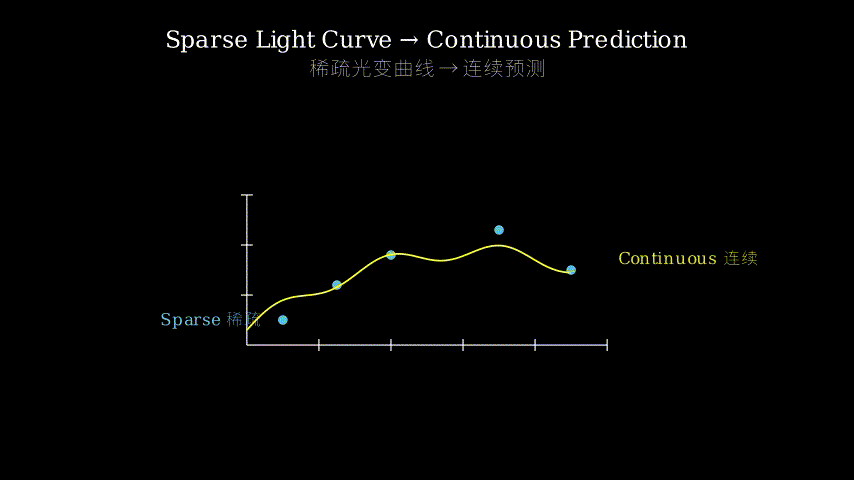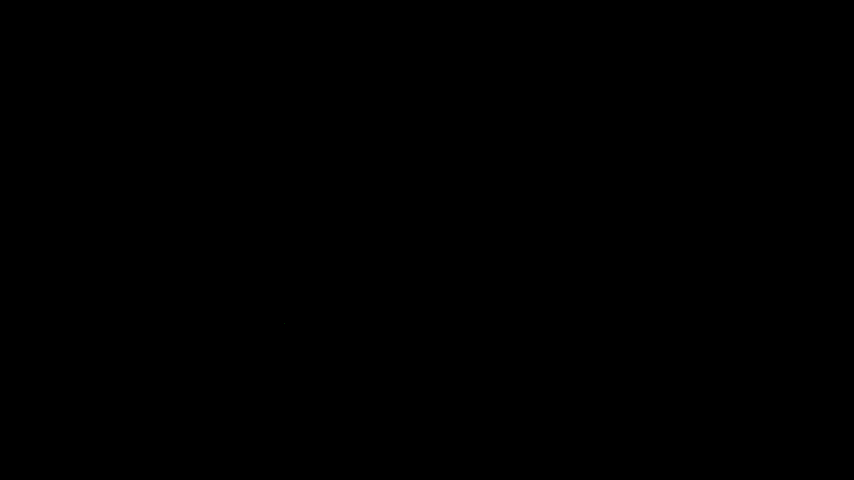
Existing ML approaches (RNNs, Transformers) struggle because astronomical light curves are nasty: sparse (maybe 5-10 observations), irregularly sampled (clouds, moon phases), multi-band (different telescopes, different filters), heteroscedastic (measurement errors vary wildly), and you need to forecast future behavior to decide which objects deserve expensive spectroscopic follow-up. Discrete-time models can’t naturally handle irregular sampling. Gaussian Processes scale poorly. Physics simulators are too slow.
Problem: 10M alerts/night, hours/object with MCMC
   |
   v
Assumption: Continuous-time latent dynamics + interpretable output
   |
   v
Method: Masked GRU-ODE encoder -> Neural ODE propagator -> Gaussian basis decoder
   |
   v
Evidence: Millisecond inference, accurate forecasts on sparse data
   |
   v
Conclusion: Scalable pipeline for real-time transient prioritization
The Increment
One sentence: Before SELDON, you chose between fast-but-opaque ML or slow-but-interpretable physics; after SELDON, you get millisecond inference with physically meaningful parameters.
Core Mechanism
SELDON is a three-stage pipeline. First, a masked GRU-ODE encoder processes panels of multi-band light curves (think: brightness measurements in different colors over time, with gaps). The masking handles missing data — some bands have 2 points, others have 10. The GRU-ODE part means it’s not stepping through fixed time intervals; it’s solving a differential equation that describes how the hidden state evolves continuously. This produces a summary vector capturing “what we know so far.”
Second, a latent neural ODE takes that summary and integrates it forward in continuous time to future epochs you care about (say, 30 days out). This isn’t predicting discrete points; it’s learning the differential equation governing the light curve’s evolution. You can query it at any timestamp.
Third, the forecasted trajectory gets encoded by a deep sets module (permutation-invariant, handles variable-length sequences) into a latent distribution, which a decoder maps to parameters of a weighted sum of Gaussian basis functions. These parameters — rise time, decay rate, peak flux — are what astronomers actually want. They’re interpretable and directly usable for prioritization.
Sparse multi-band     Masked GRU-ODE        Neural ODE          Deep Sets      Gaussian Basis
light curves    -->   Encoder         -->   Propagator    -->   Encoder   -->  Decoder
(irregular times)     (summary vector)      (continuous         (latent z)     (rise, decay,
                                             forecast)                          peak flux)
     [gaps]               [h(t)]              [h(t+dt)]           [z~N]         [params]
Think of SELDON like a weather forecasting system for stars. The encoder is a meteorologist looking at scattered weather station reports (some stations report hourly, others daily, some are offline). They synthesize this into a mental model of the current atmospheric state. The neural ODE is the physics simulation running forward — but instead of Navier-Stokes equations, it’s learned dynamics. The decoder translates the simulation output into actionable forecasts: “expect peak rainfall at 3pm, decay by evening” — except here it’s “expect peak brightness in 5 days, exponential decay with timescale 20 days.” Each component maps: scattered reports → encoder, atmospheric state → hidden vector, physics sim → neural ODE, actionable forecast → Gaussian parameters.
Key Concepts
-
Neural ODE (Ordinary Differential Equation): Instead of predicting the next value in a sequence (like RNNs do), you predict the derivative — the rate of change. Then you use a numerical integrator (like solving physics equations) to get the actual trajectory. Why? Because real processes evolve continuously, not in discrete steps. A supernova doesn’t care that you observed it on Monday and Thursday; its brightness changes smoothly in between. Neural ODEs let you query the model at any timestamp, handle irregular sampling naturally, and bake in the inductive bias that the world is continuous. Concrete example: predicting a ball’s position. RNN: “at t=1 it’s here, at t=2 it’s there.” Neural ODE: “its velocity is v(t) = f(position, t), now integrate to get position at any t.”
-
Variational Autoencoder (VAE) for Time Series: You want to compress a messy, high-dimensional light curve into a low-dimensional latent code that captures the “essence” of the transient. VAEs do this by learning an encoder (data → latent distribution) and decoder (latent → reconstructed data), with a twist: the latent code is probabilistic (a distribution, not a point), which forces the model to learn smooth, generalizable representations. For forecasting, you encode observed data into z, then decode z into future predictions. The “variational” part means you’re doing approximate Bayesian inference — the latent code represents uncertainty about what’s really happening.
-
Gaussian Basis Functions for Interpretability: Instead of outputting raw predicted brightness values, SELDON outputs parameters of a sum of Gaussians: each Gaussian has a center (when it peaks), width (how fast it rises/falls), and amplitude (how bright). This is interpretable because astronomers think in these terms: “Type Ia supernovae peak in ~20 days, decay exponentially.” The decoder learns to map latent codes to these physically meaningful parameters, so you’re not just getting predictions — you’re getting a parameterized model of the light curve that scientists can reason about.
Framework Shift
Before (mainstream approach):        After (this paper):

Physics-based MCMC:                  SELDON:

Observed data                        Observed data
    |                                    |
    v                                    v
Fit parametric model                 Encode to latent h(t)
(e.g., exponential)                      |
    |                                    v
    v                                Propagate with Neural ODE
Sample parameters                        |
with MCMC                                v
    |                                Decode to Gaussian params
    v                                    |
Parameters                               v
(hours per object)                   Parameters
                                     (milliseconds per object)

Discrete-time ML:                    Continuous-time ML:

RNN/Transformer                      GRU-ODE + Neural ODE
    |                                    |
Fixed time steps                     Continuous dynamics
    |                                    |
Interpolate for gaps                 Native irregular sampling
    |                                    |
Opaque predictions                   Interpretable parameters
From discrete-time black boxes to continuous-time interpretable dynamics, the core shift is treating time as a first-class citizen in the model architecture.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The Rubin Observatory is coming online, and the 10M alerts/night figure isn’t hype — it’s infrastructure reality. Current MCMC codes genuinely can’t scale. The problem sits at a critical juncture: astronomy is transitioning from data-starved to data-flooded, and the tooling hasn’t caught up. This is applied ML done right — solving a domain bottleneck with appropriate methods.
Method maturity: Clever synthesis, not brute force. Neural ODEs are trendy but appropriate here — continuous time is the right inductive bias for physical processes. The Gaussian basis decoder is smart: it bridges the gap between ML flexibility and scientific interpretability. However, I’m skeptical about one thing: the paper doesn’t deeply explore whether simpler approaches (e.g., Gaussian Processes with inducing points, or even well-tuned interpolation + standard VAEs) were truly exhausted. The architecture feels like it has many moving parts (masked GRU-ODE, latent ODE, deep sets, Gaussian decoder) — each justified individually, but collectively it’s complex. Could you get 80% of the benefit with 50% of the machinery?
Experimental integrity: The baselines seem fair (they compare against RNNs, Transformers, and physics-based models), and the numbers are compelling (millisecond inference vs hours). However, I’d want to see more ablation studies. What if you dropped the neural ODE propagator and just used the encoder-decoder? What’s the marginal gain of each component? The paper likely has these, but they need to be front and center. Also, the evaluation is on simulated data — real astronomical data is messier. Generalization to real Rubin data is the ultimate test, and that’s still pending.
Writing quality: The abstract and intro are strong — they nail the motivation. The method section is dense but clear. Where they cut corners: the related work is thin (neural ODEs for time series is a crowded space, and they don’t position themselves carefully), and the discussion of failure modes is absent. When does SELDON break? What kinds of transients does it struggle with? A paragraph on limitations would elevate the paper from “cool demo” to “mature contribution.”
Verdict: weak accept — Solid applied work addressing a real problem with appropriate methods, but needs more ablation studies and honest discussion of limitations before it’s a strong accept.
Takeaways
-
Continuous-time models for irregular data: If your time series has variable sampling rates (medical records, sensor networks, financial ticks), neural ODEs are worth trying. The key insight: model the derivative, not the next value.
-
Interpretable decoders: Don’t just output raw predictions. If your domain has meaningful parameterizations (e.g., pharmacokinetics has absorption/elimination rates, epidemiology has R0/recovery time), design your decoder to output those parameters directly. It makes the model debuggable and trustworthy.
-
Masking for heterogeneous panels: When you have multiple correlated time series with different amounts of data (e.g., patients with different test histories), masked encoders that handle variable-length inputs gracefully are essential. The GRU-ODE + masking combo here is a reusable pattern.
-
Speed as a feature: In high-throughput scenarios (fraud detection, real-time bidding, astronomical surveys), inference speed isn’t just nice-to-have — it’s a hard constraint. Designing for millisecond latency from the start (not as an afterthought) changes your architecture choices.
论文: 2603.04392 作者: Jiezhong Wu, Jack O’Brien, Jennifer Li, M. S. Krafczyk, Ved G. Shah, Amanda R. Wasserman, Daniel W. Apley, Gautham Narayan, Noelle I. Samia 分类: astro-ph.IM, cs.LG
缺口
天文学即将被数据淹没。
Vera Rubin天文台每晚会产生一千万条瞬变天体警报——超新星、小行星、任何天空中变化的东西。
现有流程用基于物理的MCMC代码拟合光变曲线并提取参数(如峰值亮度或衰减率),每个天体要花几小时。
处理几百个天体还行,面对数百万个就崩了。
现有机器学习方法(RNN、Transformer)也不行,因为天文光变曲线很难搞:稀疏(可能只有5-10个观测点)、采样不规则(云层、月相影响)、多波段(不同望远镜、不同滤光片)、异方差(测量误差变化很大),而且你需要预测未来行为来决定哪些天体值得昂贵的光谱跟进。
离散时间模型无法自然处理不规则采样。
高斯过程扩展性差。
物理模拟器太慢。
问题: 每晚1000万警报, MCMC每个天体要几小时
   |
   v
假设: 连续时间潜在动力学 + 可解释输出
   |
   v
方法: 掩码GRU-ODE编码器 -> 神经ODE传播器 -> 高斯基解码器
   |
   v
证据: 毫秒级推理, 稀疏数据上准确预测
   |
   v
结论: 可扩展的实时瞬变天体优先级排序流程
增量
一句话: SELDON之前,你要在快速但不透明的机器学习和缓慢但可解释的物理模型之间二选一;SELDON之后,你能用毫秒级推理得到物理上有意义的参数。
核心机制
SELDON是三阶段流程。
第一阶段,掩码GRU-ODE编码器处理多波段光变曲线面板(想象:不同颜色的亮度测量随时间变化,有缺口)。
掩码处理缺失数据——有些波段有2个点,有些有10个。
GRU-ODE部分意味着它不是按固定时间间隔步进;而是求解一个微分方程,描述隐藏状态如何连续演化。
这产生一个摘要向量,捕获”我们目前知道的”。
第二阶段,潜在神经ODE拿着这个摘要,在连续时间中向前积分到你关心的未来时刻(比如30天后)。
这不是预测离散点;而是学习支配光变曲线演化的微分方程。
你可以在任意时间戳查询它。
第三阶段,预测的轨迹被深度集模块编码(排列不变,处理变长序列)成潜在分布,解码器将其映射到高斯基函数加权和的参数。
这些参数——上升时间、衰减率、峰值流量——正是天文学家真正想要的。
它们可解释,直接可用于优先级排序。
稀疏多波段      掩码GRU-ODE       神经ODE         深度集        高斯基
光变曲线   -->   编码器      -->   传播器    -->   编码器   -->  解码器
(不规则时间)     (摘要向量)        (连续          (潜在z)       (上升,衰减,
                                   预测)                        峰值流量)
   [缺口]           [h(t)]          [h(t+dt)]       [z~N]        [参数]
把SELDON想象成恒星的天气预报系统。
编码器是气象学家看着零散的气象站报告(有些站每小时报告,有些每天报告,有些离线)。
他们将这些综合成当前大气状态的心智模型。
神经ODE是向前运行的物理模拟——但不是Navier-Stokes方程,而是学到的动力学。
解码器将模拟输出翻译成可操作的预报:“预计下午3点降雨峰值,傍晚衰减”——只不过这里是”预计5天后亮度峰值,时间尺度20天的指数衰减”。
每个组件映射:零散报告→编码器,大气状态→隐藏向量,物理模拟→神经ODE,可操作预报→高斯参数。
关键概念
- 神经ODE(常微分方程): 不是预测序列中的下一个值(像RNN那样),而是预测导数——变化率。
然后用数值积分器(像求解物理方程)得到实际轨迹。
为什么?因为真实过程是连续演化的,不是离散步进。
超新星不在乎你周一和周四观测它;它的亮度在中间平滑变化。
神经ODE让你在任意时间戳查询模型,自然处理不规则采样,并内置世界是连续的归纳偏置。
具体例子:预测球的位置。
RNN:“t=1时在这,t=2时在那”。
神经ODE:“它的速度是v(t)=f(位置,t),现在积分得到任意t的位置”。
- 时间序列的变分自编码器(VAE): 你想把混乱的高维光变曲线压缩成低维潜在编码,捕获瞬变天体的”本质”。
VAE通过学习编码器(数据→潜在分布)和解码器(潜在→重建数据)做到这点,有个转折:潜在编码是概率性的(一个分布,不是一个点),这迫使模型学习平滑、可泛化的表示。
对于预测,你把观测数据编码成z,然后把z解码成未来预测。
“变分”部分意味着你在做近似贝叶斯推理——潜在编码表示关于真实情况的不确定性。
- 可解释性的高斯基函数: 不是输出原始预测亮度值,SELDON输出高斯和的参数:每个高斯有中心(何时峰值)、宽度(上升/下降多快)和振幅(多亮)。
这是可解释的,因为天文学家就是这么思考的:“Ia型超新星约20天达到峰值,指数衰减”。
解码器学习将潜在编码映射到这些物理上有意义的参数,所以你不只是得到预测——你得到光变曲线的参数化模型,科学家可以推理。
框架转变
之前(主流方法):                  之后(本文方法):

基于物理的MCMC:                  SELDON:

观测数据                          观测数据
    |                                |
    v                                v
拟合参数模型                      编码到潜在h(t)
(如指数)                             |
    |                                v
    v                            用神经ODE传播
用MCMC采样参数                       |
    |                                v
    v                            解码到高斯参数
参数                                 |
(每个天体几小时)                     v
                                 参数
                                 (每个天体几毫秒)

离散时间机器学习:                连续时间机器学习:

RNN/Transformer                  GRU-ODE + 神经ODE
    |                                |
固定时间步                        连续动力学
    |                                |
为缺口插值                        原生不规则采样
    |                                |
不透明预测                        可解释参数
从离散时间黑盒到连续时间可解释动力学,核心转变是把时间作为模型架构中的一等公民。
专家评审
选题眼光: 这是真缺口,不是人造的。
Rubin天文台即将上线,每晚1000万警报不是炒作——是基础设施现实。
现有MCMC代码确实无法扩展。
这个问题处于关键节点:天文学正从数据匮乏转向数据泛滥,工具还没跟上。
这是应用机器学习做对了——用合适的方法解决领域瓶颈。
方法成熟度: 巧妙综合,不是蛮力。
神经ODE很时髦但在这里合适——连续时间是物理过程的正确归纳偏置。
高斯基解码器很聪明:它在机器学习灵活性和科学可解释性之间架起桥梁。
但我对一点持怀疑态度:论文没有深入探索更简单的方法(如带诱导点的高斯过程,或甚至调优的插值+标准VAE)是否真的穷尽了。
架构感觉有很多活动部件(掩码GRU-ODE、潜在ODE、深度集、高斯解码器)——每个单独看都合理,但整体很复杂。
能不能用50%的机制得到80%的收益?
实验诚意: 基线看起来公平(他们与RNN、Transformer和基于物理的模型比较),数字令人信服(毫秒级推理vs几小时)。
但我想看更多消融研究。
如果去掉神经ODE传播器只用编码器-解码器会怎样?每个组件的边际增益是多少?论文可能有这些,但需要放在最前面。
另外,评估是在模拟数据上——真实天文数据更乱。
泛化到真实Rubin数据是终极测试,这还悬而未决。
写作功力: 摘要和引言很强——他们钉住了动机。
方法部分密集但清晰。
他们偷懒的地方:相关工作很薄(时间序列的神经ODE是个拥挤空间,他们没有仔细定位自己),失败模式的讨论缺失。
SELDON什么时候崩?它在哪类瞬变天体上挣扎?一段关于局限性的讨论会把论文从”酷炫演示”提升到”成熟贡献”。
判决: 弱接收——解决真实问题的扎实应用工作,用了合适的方法,但需要更多消融研究和对局限性的诚实讨论才能成为强接收。
要点总结
- 不规则数据的连续时间模型: 如果你的时间序列采样率可变(医疗记录、传感器网络、金融tick),神经ODE值得尝试。
关键洞见:建模导数,不是下一个值。
- 可解释解码器: 不要只输出原始预测。
如果你的领域有有意义的参数化(如药代动力学有吸收/消除率,流行病学有R0/恢复时间),设计你的解码器直接输出那些参数。
这让模型可调试、可信任。
- 异构面板的掩码: 当你有多个相关时间序列,数据量不同(如患者有不同的检测历史),优雅处理变长输入的掩码编码器至关重要。
这里的GRU-ODE+掩码组合是可复用模式。
- 速度作为特性: 在高吞吐场景(欺诈检测、实时竞价、天文巡天),推理速度不只是锦上添花——是硬约束。
从一开始就为毫秒级延迟设计(不是事后想法)会改变你的架构选择。