Paper: 2604.08541 Authors: Haolei Xu, Haiwen Hong, Hongxing Li, Rui Zhou, Yang Zhang, Longtao Huang, Hui Xue, Yongliang Shen, Weiming Lu, Yueting Zhuang Categories: cs.CV
The Gap
Multimodal Mixture-of-Experts models have achieved impressive performance on vision-language tasks, but there is a strange failure mode hiding beneath the surface. Present a grade-school math problem as an image, and the model extracts all the numbers and text perfectly—yet produces the wrong answer due to reasoning errors. Give the exact same problem as pure text, and it solves it correctly with ease.
The authors call this Seeing but Not Thinking: the model perceives visual content accurately but fails to reason correctly, despite possessing the requisite capability on semantically equivalent text inputs.
This is not a niche edge case. On controlled experiments using MATH500 rendered as high-resolution images, 68.2% to 73.1% of failures stem from reasoning errors rather than perception errors. The model sees correctly but thinks incorrectly when visual inputs are involved.
The natural first hypothesis is cross-modal semantic alignment failure: maybe visual information, though correctly perceived, fails to align with the textual semantic space at the representation level. But the authors rule this out through concept intervention experiments, demonstrating that MoE architectures do exhibit cross-modal semantic sharing in middle layers, just like dense models.
If semantic alignment is not the bottleneck, what is? The authors turn their attention to the routing mechanism—the core component distinguishing MoE from dense models. Through systematic analysis, they uncover two critical findings:
-
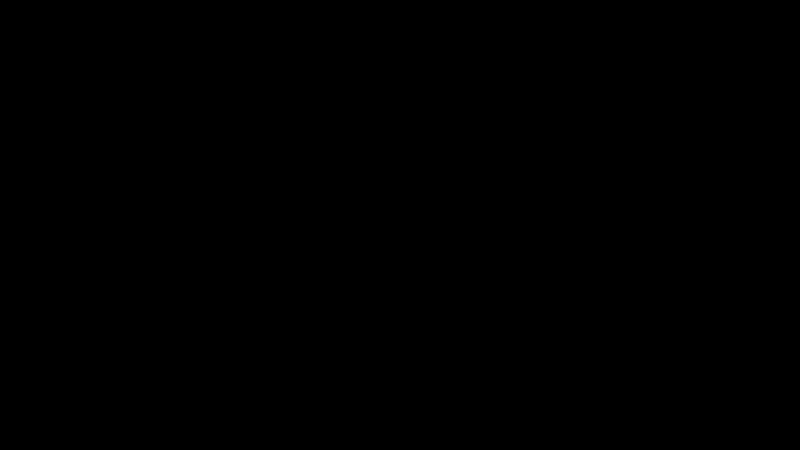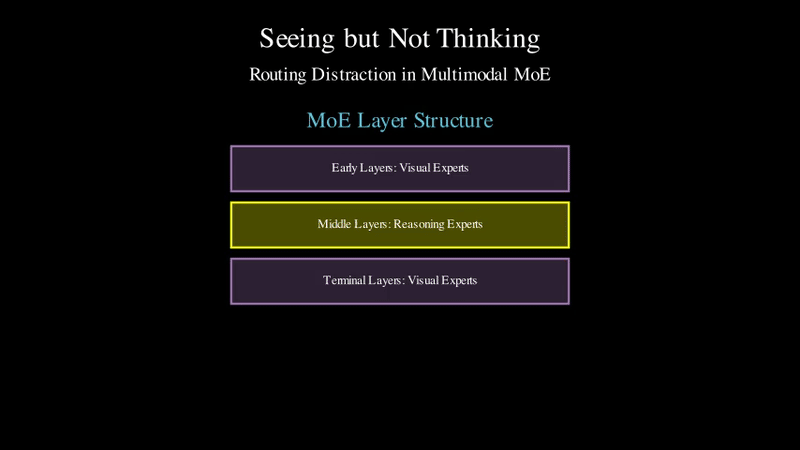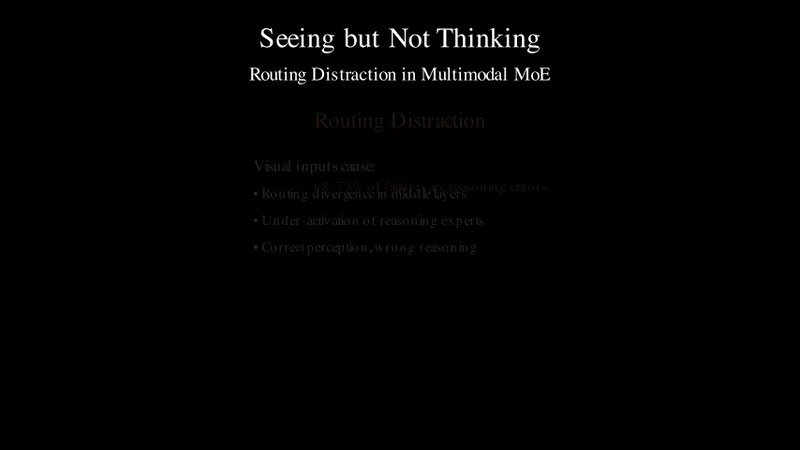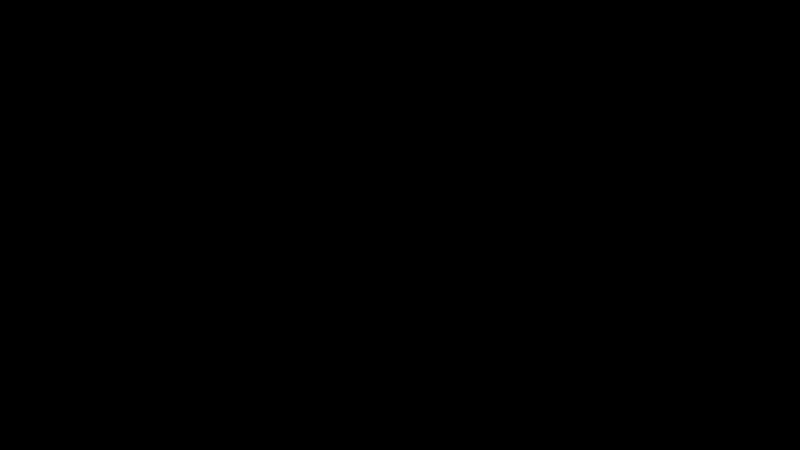
Layer-wise expert separation: Visual experts (handling image encoding) concentrate in early and terminal layers, while domain-specific reasoning experts cluster in middle layers.
-
Routing divergence: Image inputs induce significant routing divergence from text inputs precisely in these middle layers where domain experts concentrate. Crucially, greater routing divergence correlates with lower reasoning accuracy.
This leads to the Routing Distraction hypothesis: when processing visual inputs, the routing mechanism fails to adequately activate task-relevant reasoning experts in middle layers, instead directing computation toward less suitable experts. The visual modality does not impair intrinsic reasoning capabilities; rather, it causes suboptimal expert selection.
[Problem]
   |
   v
[Models perceive correctly
 but reason incorrectly
 on visual inputs]
   |
   v
[Hypothesis 1: Semantic alignment failure?]
   |
   v
[Test: Cross-modal concept intervention]
   |
   v
[Result: Semantic sharing exists in middle layers]
   |
   v
[Hypothesis 2: Routing distraction?]
   |
   v
[Analysis: Visual and domain experts
 are layer-wise separated
 Image inputs cause routing divergence
 in middle layers]
   |
   v
[Validation: Routing-guided intervention
 enhances domain expert activation
 Improves reasoning up to 3.17%]
The Increment
One sentence: Before this paper, the failure of multimodal MoE models on visual reasoning was attributed vaguely to “multimodal integration issues”; after it, we have a mechanistic explanation—routing distraction in middle layers—and a practical intervention method.
Core Mechanism
The paper proceeds in three stages: diagnosis, analysis, and intervention.
Stage 1: Verifying Cross-Modal Semantic Sharing
The authors design a concept intervention experiment. They construct an arithmetic completion task where the input consists of a digit image followed by textual arithmetic (e.g., image of “3” followed by ”+ 2 =”). They extract hidden state vectors for source digit S and target digit T from pure text inputs, then perform this intervention on image token hidden states:
ĥ_img^(l) ← h_img^(l) - α·h_src^(l) + α·h_tgt^(l)
This removes the source concept’s semantic vector from the image representation while adding the target concept’s vector. If the model’s output changes to match the target digit, the intervention succeeds.
Results show a clear inverted U-shaped pattern across layers: low success rates in early layers (visual features not yet aligned), high success rates exceeding 90% in middle layers (8-42), and sharp decline in terminal layers (output distribution already determined). This confirms that MoE architectures exhibit cross-modal semantic sharing, ruling out alignment failure as the sole explanation.
Stage 2: Identifying Layer-Wise Expert Specialization
The authors identify domain experts by comparing activation frequencies between domain-specific data (GSM8K for math) and general data (Alpaca). Experts with significantly higher activation on domain data are classified as domain experts. Similarly, they identify visual experts by comparing activation frequencies between image-rendered and text versions of the same content.
The key finding: visual experts and domain experts exhibit layer-wise separation. Visual experts cluster in early layers (initial visual encoding) and terminal layers (preparing outputs), while math experts concentrate in middle layers (6-42) where cross-modal semantic sharing occurs.
Stage 3: Analyzing Routing Divergence
The authors measure routing divergence between semantically equivalent text and image inputs using Jensen-Shannon Divergence (JSD) on expert activation distributions. They test three image versions with increasing visual complexity.
Results reveal that routing divergence exhibits a U-shaped distribution: larger in early/terminal layers (expected due to visual encoding and output preparation), but critically, the three image versions diverge primarily in middle layers (6-42) where domain experts concentrate. Greater routing divergence in middle layers correlates with lower reasoning accuracy.
The Intervention: Routing-Guided Enhancement
Based on the Routing Distraction hypothesis, the authors propose a simple intervention: explicitly enhance routing weights of identified domain experts during inference. They test two strategies:
-
Soft intervention: Apply moderate additive enhancement to domain expert logits:
r'_k ← r_k + λ·s(r)where s(r) is the standard deviation of expert logits. -
Hard intervention: Force domain expert logits to layer maximum:
r'_k ← max_j(r_j) + δ.
The soft intervention achieves consistent improvements across three MoE models (Kimi-VL-16B, Qwen3-VL-30B, Llama4-Scout-109B) and six benchmarks, with gains up to 3.17% on complex visual reasoning tasks. Hard intervention shows mixed results, sometimes causing severe degradation on models with Top-1 routing.
[Cross-modal concept intervention]
         |
         v
[Semantic sharing verified
 in middle layers]
         |
         v
[Domain expert identification]
[Compare activation frequencies
 on domain vs general data]
         |
         v
[Visual expert identification]
[Compare activation frequencies
 on image vs text data]
         |
         v
[Finding: Layer-wise separation
 Visual experts: early + terminal
 Domain experts: middle layers]
         |
         v
[Routing divergence analysis]
[Image inputs cause divergence
 in middle layers]
         |
         v
[Routing-guided intervention]
[Enhance domain expert activation
 during inference]
         |
         v
[Consistent improvements
 across models and tasks]
Key Concepts
-
Mixture-of-Experts (MoE): An architecture that activates only a sparse subset of experts for each input, enabling efficient scaling. The routing mechanism decides which experts to activate. Unlike dense models where all parameters process every input, MoE models route different inputs to different expert subsets, allowing specialization.
-
Routing distraction: The phenomenon where visual inputs cause the routing mechanism to inadequately activate task-relevant reasoning experts, instead directing computation toward less suitable experts. This is not a failure of reasoning capability itself, but a failure of expert selection.
-
Cross-modal semantic sharing: The property that visual and textual representations of the same concept converge to similar semantic spaces in middle layers of the model. This allows the model to process semantically equivalent information regardless of input modality.
-
Layer-wise expert separation: The spatial distribution pattern where different types of experts concentrate in different layers. Visual experts handle modality-specific processing in early/terminal layers, while domain experts handle abstract reasoning in middle layers where semantic sharing occurs.
Framework Shift
Before (implicit assumption):        After (this paper):

[Multimodal MoE failures]            [Multimodal MoE failures]
          |                                    |
          v                                    v
[Vague attribution to                [Mechanistic diagnosis]
 "integration issues"]                        |
          |                                    v
          v                          [Cross-modal semantic sharing
[No clear mechanism]                  exists in middle layers]
          |                                    |
          v                                    v
[No targeted intervention]           [Visual and domain experts
                                      are layer-wise separated]
                                               |
                                               v
                                     [Routing divergence in
                                      middle layers causes
                                      inadequate domain expert
                                      activation]
                                               |
                                               v
                                     [Routing-guided intervention
                                      recovers reasoning performance]
From vague attribution to mechanistic understanding and targeted intervention, the core shift is treating routing behavior as a first-class object of analysis in multimodal reasoning failures.
Expert Assessment
Problem choice: This is a real and important phenomenon. As multimodal MoE models become the dominant paradigm for scaling vision-language systems, understanding their failure modes is critical. The Seeing but Not Thinking phenomenon is not just academically interesting—it has direct implications for deployment in applications requiring visual reasoning.
Method maturity: The diagnostic methodology is rigorous and well-designed. The cross-modal concept intervention experiment provides clean evidence for semantic sharing. The layer-wise expert analysis reveals structural patterns that were previously hidden. The routing divergence analysis establishes correlation with reasoning performance. The intervention validation demonstrates practical utility.
The main limitation is that the intervention requires task-specific configuration: identifying domain experts, determining optimal intervention layers and strengths. The paper acknowledges this and suggests that developing adaptive methods would improve practical applicability.
Experimental integrity: The experiments are carefully controlled. Using semantically equivalent text and image versions isolates reasoning from perception. Error analysis confirms that 68-73% of failures are reasoning errors, not perception errors. The evaluation spans three models with different scales and routing mechanisms (Top-K vs Top-1), demonstrating generality. The ablations examine intervention layer range, enhancement strength, and domain specificity.
One strength is the analysis of expert identification robustness: the paper shows that domain experts transfer effectively across tasks with different information structures, as long as the reference elicits target domain reasoning patterns. This suggests expert identification locates cognitive functions rather than sample-specific solutions.
Writing quality: The paper is well-structured and clearly written. The progression from diagnosis to analysis to intervention is logical. The figures effectively illustrate key findings. The related work section properly positions the contribution relative to prior work on semantic sharing, expert specialization, and routing intervention.
The limitation section is honest about scope: routing guidance cannot address perceptual errors, requires task-specific configuration, and the cross-modal semantic sharing experiments only verify alignment for simple numerical concepts.
Verdict: accept — This paper makes a solid mechanistic contribution to understanding multimodal MoE failures, provides rigorous experimental validation, and demonstrates practical utility through routing-guided intervention. The Routing Distraction hypothesis is well-supported and the intervention method is simple yet effective.
Takeaways
What practitioners can take from this work:
-
Routing behavior matters for multimodal reasoning. In MoE architectures, it is not enough for the model to have the right experts—the routing mechanism must activate them appropriately. Visual inputs can cause routing distraction even when semantic alignment is preserved.
-
Layer-wise expert analysis reveals hidden structure. Different types of experts concentrate in different layers. Understanding this spatial distribution can guide architecture design and intervention strategies.
-
Inference-time routing intervention is a viable approach. You do not need to retrain the model to mitigate routing distraction. Explicitly enhancing domain expert activation during inference can recover reasoning performance.
-
Domain expert identification is robust to information completeness. As long as the text reference elicits target domain reasoning patterns, identified experts transfer effectively to visual tasks with different information structures. This suggests experts encode cognitive functions rather than sample-specific solutions.
-
Soft intervention outperforms hard intervention. Moderate additive enhancement preserves routing flexibility while systematically increasing domain expert activation probability. Forcing expert logits can disrupt the routing mechanism, especially in Top-1 routing architectures.
-
The gap between perception and reasoning is real. Models can perceive correctly yet reason incorrectly. This is not just a multimodal issue—it reflects a deeper challenge in how neural networks integrate perception with abstract reasoning.
For researchers, this work opens several directions: Can we design routing mechanisms that are less susceptible to modality-induced distraction? Can we develop training objectives that encourage routers to allocate experts based on task requirements rather than input modality? Can we extend this analysis to other types of expert specialization beyond domain-specific reasoning?
论文: 2604.08541 作者: Haolei Xu, Haiwen Hong, Hongxing Li, Rui Zhou, Yang Zhang, Longtao Huang, Hui Xue, Yongliang Shen, Weiming Lu, Yueting Zhuang 分类: cs.CV
缺口
多模态 Mixture-of-Experts 模型在视觉-语言任务上取得了令人印象深刻的表现,但表面之下隐藏着一种奇怪的失败模式。给模型一道小学数学题的图片,它能完美提取所有数字和文本——却因为推理错误给出错误答案。把完全相同的问题以纯文本形式给它,它却能轻松正确解决。
作者将这种现象称为看见但不思考
,却无法正确推理,尽管它在语义等价的文本输入上具备必要的能力。这不是小众边缘案例。在使用 MATH500 渲染为高分辨率图像的受控实验中,68.2% 到 73.1% 的失败源于推理错误而非感知错误。模型看得正确,但在涉及视觉输入时思考错误。
自然的第一个假设是跨模态语义对齐失败
,却未能在表示层面与文本语义空间对齐。但作者通过概念干预实验排除了这一点,证明 MoE 架构确实在中间层表现出跨模态语义共享,就像密集模型一样。如果语义对齐不是瓶颈,那是什么?作者将注意力转向路由机制——区分 MoE 与密集模型的核心组件。通过系统分析,他们发现了两个关键发现:
-
层级专家分离
(处理图像编码)集中在早期和末端层,而领域特定的推理专家聚集在中间层。 -
路由分歧
。关键是,更大的路由分歧与更低的推理准确率相关。
这导致了路由分心假设
,路由机制未能在中间层充分激活任务相关的推理专家,而是将计算导向不太合适的专家。视觉模态不会损害内在推理能力;相反,它导致次优的专家选择。[问题]
|
v
[模型在视觉输入上
感知正确但推理错误]
|
v
[假设1: 语义对齐失败?]
|
v
[测试: 跨模态概念干预]
|
v
[结果: 中间层存在语义共享]
|
v
[假设2: 路由分心?]
|
v
[分析: 视觉和领域专家
层级分离
图像输入在中间层
引起路由分歧]
|
v
[验证: 路由引导干预
增强领域专家激活
推理提升最高3.17%]
增量
一句话: 在这篇论文之前,多模态 MoE 模型在视觉推理上的失败被模糊地归因于”多模态集成问题”;在这之后,我们有了机制性解释——中间层的路由分心——以及实用的干预方法。
核心机制
论文分三个阶段进行
、分析和干预。阶段1: 验证跨模态语义共享
作者设计了一个概念干预实验。他们构建了一个算术补全任务,输入由数字图像后跟文本算术组成(例如,“3”的图像后跟”+ 2 =”)。他们从纯文本输入中提取源数字 S 和目标数字 T 的隐藏状态向量,然后对图像标记的隐藏状态执行此干预:
ĥ_img^(l) ← h_img^(l) - α·h_src^(l) + α·h_tgt^(l)
这从图像表示中移除源概念的语义向量,同时添加目标概念的向量。如果模型的输出改变以匹配目标数字,则干预成功。
结果显示跨层的清晰倒 U 型模式
(视觉特征尚未对齐),中间层(8-42)成功率高超过 90%,末端层急剧下降(输出分布已确定)。这证实 MoE 架构表现出跨模态语义共享,排除对齐失败作为唯一解释。阶段2: 识别层级专家专业化
作者通过比较领域特定数据(数学用 GSM8K)和通用数据(Alpaca)的激活频率来识别领域专家。在领域数据上激活显著更高的专家被分类为领域专家。类似地,他们通过比较相同内容的图像渲染版本和文本版本的激活频率来识别视觉专家。
关键发现:视觉专家和领域专家表现出层级分离。视觉专家集中在早期层(初始视觉编码)和末端层(准备输出),而数学专家集中在发生跨模态语义共享的中间层(6-42)。
阶段3: 分析路由分歧
作者使用 Jensen-Shannon 散度(JSD)测量语义等价的文本和图像输入之间的路由分歧。他们测试了三个视觉复杂度递增的图像版本。
结果显示路由分歧呈现 U 型分布
/末端层较大(由于视觉编码和输出准备,这是预期的),但关键是,三个图像版本主要在领域专家集中的中间层(6-42)分歧。中间层更大的路由分歧与更低的推理准确率相关。干预: 路由引导增强
基于路由分心假设,作者提出了一个简单的干预
。他们测试了两种策略:-
软干预
logits 应用适度的加性增强:r'_k ← r_k + λ·s(r),其中 s(r) 是专家 logits 的标准差。 -
硬干预
logits 达到层最大值:r'_k ← max_j(r_j) + δ。
软干预在三个 MoE 模型(Kimi-VL-16B、Qwen3-VL-30B、Llama4-Scout-109B)和六个基准测试中实现了一致的改进,在复杂视觉推理任务上提升最高达 3.17%。硬干预显示混合结果,有时在具有 Top-1 路由的模型上造成严重退化。
[跨模态概念干预]
         |
         v
[中间层验证语义共享]
         |
         v
[领域专家识别]
[比较领域数据与
 通用数据的激活频率]
         |
         v
[视觉专家识别]
[比较图像数据与
 文本数据的激活频率]
         |
         v
[发现: 层级分离
 视觉专家: 早期+末端
 领域专家: 中间层]
         |
         v
[路由分歧分析]
[图像输入在中间层
 引起分歧]
         |
         v
[路由引导干预]
[推理期间增强
 领域专家激活]
         |
         v
[跨模型和任务
 一致改进]
关键概念
-
Mixture-of-Experts (MoE): 一种仅为每个输入激活稀疏专家子集的架构,实现高效扩展。路由机制决定激活哪些专家。与所有参数处理每个输入的密集模型不同,MoE 模型将不同输入路由到不同的专家子集,允许专业化。
-
路由分心: 视觉输入导致路由机制未能充分激活任务相关的推理专家,而是将计算导向不太合适的专家的现象。这不是推理能力本身的失败,而是专家选择的失败。
-
跨模态语义共享: 相同概念的视觉和文本表示在模型中间层收敛到相似语义空间的特性。这允许模型处理语义等价的信息,无论输入模态如何。
-
层级专家分离: 不同类型的专家集中在不同层的空间分布模式。视觉专家在早期/末端层处理模态特定处理,而领域专家在发生语义共享的中间层处理抽象推理。
框架转变
之前(隐含假设):                  之后(本文):

[多模态MoE失败]                  [多模态MoE失败]
          |                                |
          v                                v
[模糊归因于                      [机制性诊断]
 "集成问题"]                             |
          |                                v
          v                      [中间层存在跨模态
[无清晰机制]                      语义共享]
          |                                |
          v                                v
[无针对性干预]                   [视觉和领域专家
                                  层级分离]
                                           |
                                           v
                                 [中间层路由分歧
                                  导致领域专家
                                  激活不足]
                                           |
                                           v
                                 [路由引导干预
                                  恢复推理性能]
从模糊归因到机制理解和针对性干预,核心转变是将路由行为作为多模态推理失败分析中的一等对象。
专家评审
选题眼光: 这是一个真实且重要的现象。随着多模态 MoE 模型成为扩展视觉-语言系统的主导范式,理解其失败模式至关重要。看见但不思考现象不仅在学术上有趣——它对需要视觉推理的应用部署有直接影响。
方法成熟度: 诊断方法严谨且设计良好。跨模态概念干预实验为语义共享提供了清晰证据。层级专家分析揭示了以前隐藏的结构模式。路由分歧分析建立了与推理性能的相关性。干预验证展示了实用价值。
主要限制是干预需要任务特定配置
、确定最佳干预层和强度。论文承认这一点,并建议开发自适应方法将提高实际适用性。实验诚意: 实验经过仔细控制。使用语义等价的文本和图像版本将推理与感知隔离。错误分析证实 68-73% 的失败是推理错误,而非感知错误。评估涵盖三个具有不同规模和路由机制(Top-K vs Top-1)的模型,展示了通用性。消融研究检查了干预层范围、增强强度和领域特异性。
一个优势是专家识别鲁棒性分析
,只要参考引发目标领域推理模式。这表明专家识别定位认知功能而非样本特定解决方案。写作功力: 论文结构良好,表述清晰。从诊断到分析到干预的进展合乎逻辑。图表有效说明关键发现。相关工作部分恰当地将贡献相对于语义共享、专家专业化和路由干预的先前工作定位。
限制部分诚实地说明范围
,需要任务特定配置,跨模态语义共享实验仅验证简单数值概念的对齐。判决: 接收 — 这篇论文对理解多模态 MoE 失败做出了扎实的机制性贡献,提供了严格的实验验证,并通过路由引导干预展示了实用价值。路由分心假设得到充分支持,干预方法简单而有效。
要点总结
实践者可以从这项工作中获得:
-
路由行为对多模态推理很重要。 在 MoE 架构中,模型拥有正确的专家是不够的——路由机制必须适当地激活它们。即使语义对齐得以保留,视觉输入也可能导致路由分心。
-
层级专家分析揭示隐藏结构。 不同类型的专家集中在不同层。理解这种空间分布可以指导架构设计和干预策略。
-
推理时路由干预是可行方法。 你不需要重新训练模型来缓解路由分心。在推理期间显式增强领域专家激活可以恢复推理性能。
-
领域专家识别对信息完整性具有鲁棒性。 只要文本参考引发目标领域推理模式,识别的专家就能有效迁移到具有不同信息结构的视觉任务。这表明专家编码认知功能而非样本特定解决方案。
-
软干预优于硬干预。 适度的加性增强保留路由灵活性,同时系统地增加领域专家激活概率。强制专家 logits 可能破坏路由机制,尤其是在 Top-1 路由架构中。
-
感知与推理之间的差距是真实的。 模型可以感知正确却推理错误。这不仅仅是多模态问题——它反映了神经网络如何将感知与抽象推理整合的更深层挑战。
对于研究人员,这项工作开启了几个方向
?我们能否开发训练目标,鼓励路由器根据任务需求而非输入模态分配专家?我们能否将这种分析扩展到领域特定推理之外的其他类型的专家专业化?