Paper: 2604.13019 Authors: Himangi Mittal, Gaurav Mittal, Nelson Daniel Troncoso, Yu Hu Categories: cs.CV
The Gap
Computer Use Agents (CUAs) can navigate web pages and simple UIs, but they struggle in dense coding environments where buttons, tabs, and text fields are packed within pixels of each other. Existing approaches like SeeClick, CogAgent, and ShowUI use single-shot coordinate prediction: the model looks at a screenshot, predicts (x, y) coordinates, and clicks. No second chances. When the first click misses by 5 pixels in a crowded IDE toolbar, the task fails. The core problem: these models lack a feedback loop to detect and correct their own errors.
Problem: Dense IDE interfaces require sub-pixel accuracy
    |
    v
Assumption: Single-shot prediction can't self-correct displacement errors
    |
    v
Method: Multi-turn refinement with visual feedback from previous attempts
    |
    v
Evidence: 15-20% improvement in click precision across GPT-5.4, Claude, Qwen
    |
    v
Conclusion: Iterative visual reasoning > one-shot coordinate prediction
The Increment
One sentence: Before this paper, GUI agents clicked once and hoped for the best; after, they click, observe the result, and adjust until they hit the target.
Core Mechanism
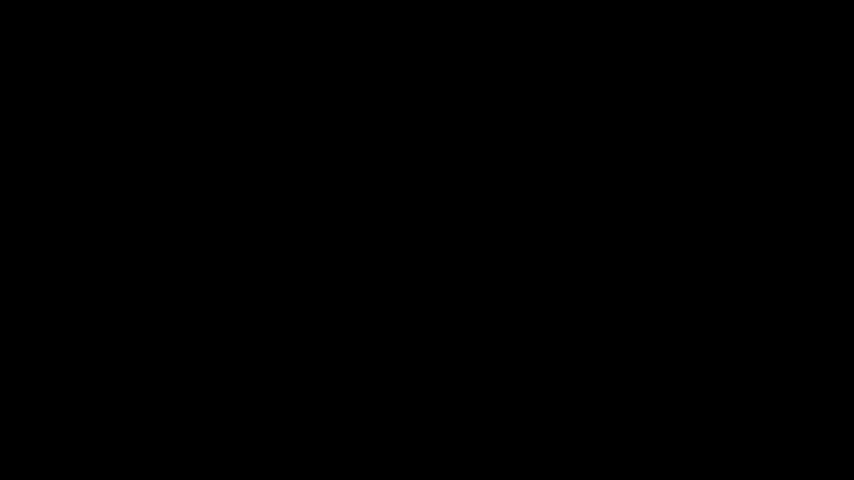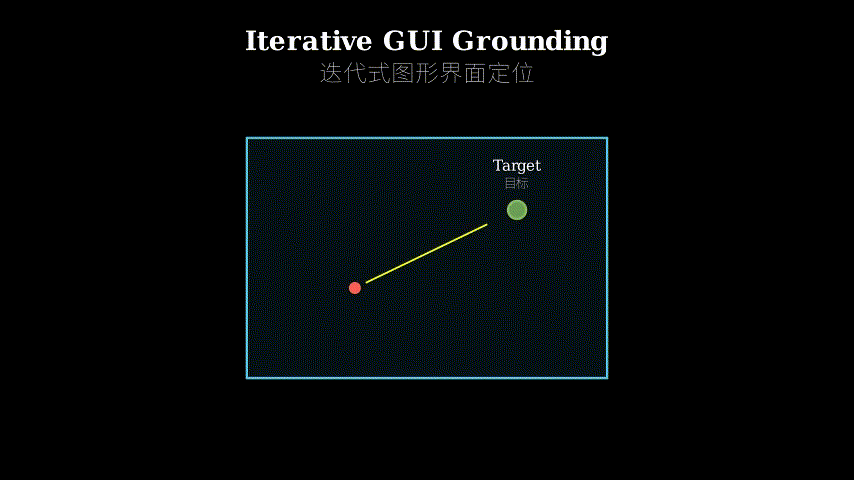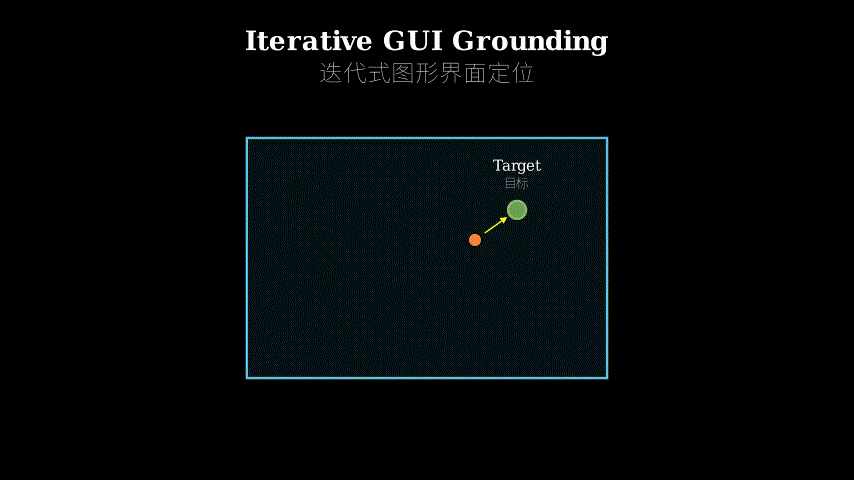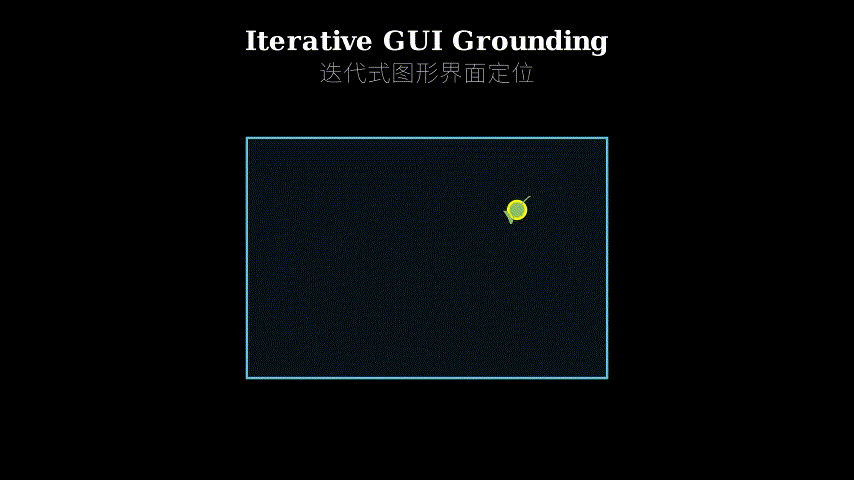
The method replaces single-shot prediction with a three-phase loop. First, the agent receives a task (“click the debug button”) and a screenshot. It predicts initial coordinates and clicks. Second, the system captures a new screenshot showing where the cursor actually landed—maybe it’s 8 pixels too far left. Third, the agent sees both the target description and the visual evidence of its miss, then predicts a correction vector. This loop repeats up to 3-5 turns until the cursor lands within an acceptable error radius (typically 5 pixels).
The architecture uses vision-language models (VLMs) like GPT-5.4 or Claude as the reasoning engine. Each turn, the VLM receives: (1) the original task, (2) the current screenshot with the cursor position marked, (3) a history of previous attempts. The model outputs a coordinate adjustment, not an absolute position. The system applies this delta, clicks, and feeds the result back. The key innovation is treating the cursor’s visible position as a training signal—the model learns to interpret “I’m 10 pixels northwest of the target” from raw pixels.
Turn 1:                Turn 2:                Turn 3:
Screenshot -----> VLM -----> Click (x1,y1)     Screenshot -----> VLM -----> Click (x2,y2)     Screenshot -----> Success
   ^                |                              ^                |                              ^
   |                v                              |                v                              |
   +--- Cursor at (x1,y1) -------------------------+--- Cursor at (x2,y2) -------------------------+
        "Too far left"                                  "Almost there"
Think of it like parallel parking. A single-shot model is someone who eyeballs the space, turns the wheel once, and either nails it or doesn’t. This paper’s approach is the normal human process: you pull in, see you’re too far from the curb, back up and adjust, check again, nudge forward. The steering wheel is the coordinate prediction, the rear-view mirror is the visual feedback, and the parking lines are the target UI element. Each adjustment uses information from the previous attempt—you don’t re-plan from scratch, you correct the error you just observed.
Key Concepts
-
Visual Feedback Loop: Instead of treating GUI grounding as a one-time perception problem, the system makes it a closed-loop control problem. After each action, the agent observes the outcome (cursor position) and uses that observation to compute the next action. This is analogous to how a thermostat works: measure temperature, compare to target, adjust heating. The “temperature” here is cursor displacement; the “heating” is coordinate adjustment. Without this loop, the agent is flying blind—it has no way to know if its internal model of the UI matches reality.
-
Displacement Error Correction: The model doesn’t just predict “click at (450, 320).” It predicts “move 15 pixels right and 8 pixels down from where you are now.” This relative encoding is crucial because VLMs are better at judging spatial relationships (“the cursor is slightly left of the button”) than absolute pixel coordinates. It’s the difference between saying “the coffee shop is at GPS coordinates 37.7749, -122.4194” versus “walk two blocks north from where you’re standing.” The second is easier to execute with noisy perception.
-
Sub-Pixel Accuracy in Dense UIs: IDEs pack dozens of interactive elements into a 1920x1080 screen. A typical VS Code toolbar has buttons that are 24x24 pixels, separated by 2-pixel gaps. If your click lands 10 pixels off-center, you might hit the wrong button entirely. “Sub-pixel accuracy” here means the final cursor position must be within 5 pixels of the target center—roughly the size of a small icon. This isn’t about rendering precision; it’s about the tolerance for error in a high-density interface where every pixel matters.
Framework Shift
Before (single-shot):                After (multi-turn refinement):

  Task + Screenshot                    Task + Screenshot
         |                                     |
         v                                     v
    [VLM Model]                           [VLM Model]
         |                                     |
         v                                     v
   Predict (x,y)                         Predict (x,y)
         |                                     |
         v                                     v
      Click once                            Click
         |                                     |
    Success or fail                           v
    (no recovery)                    Capture new screenshot
                                              |
                                              v
                                         [VLM Model] <--+
                                              |         |
                                              v         |
                                      Predict delta     |
                                              |         |
                                              v         |
                                          Adjust & click|
                                              |         |
                                              +---------+
                                              |
                                              v
                                      Success (or max turns)
[One sentence: From blind one-shot prediction to iterative visual servoing, the core shift is treating GUI grounding as a feedback control problem rather than a perception problem.]
Expert Assessment
Problem choice: Real gap. Dense coding interfaces are where CUAs actually break in practice—anyone who’s tried to automate IDE tasks knows single-shot clicking is a coin flip. The authors didn’t manufacture this; they’re addressing a deployment blocker.
Method maturity: Clever but not novel in robotics—visual servoing has been around for decades. The contribution is showing that VLMs can do this without explicit training on displacement correction. The simplicity is a feature: no new model architecture, just a different prompting strategy. However, they don’t explore why 3-5 turns is the sweet spot, or whether there are diminishing returns.
Experimental integrity: Baselines are fair (SeeClick, CogAgent, ShowUI are the right comparisons). The 15-20% improvement is consistent across models, which suggests it’s not a fluke. But the paper lacks failure analysis—when does multi-turn refinement still fail? Are there UI patterns where it gets stuck in local minima? The benchmarks (precision-cua-bench) are new, so we can’t compare to prior work directly.
Writing quality: The abstract oversells (“fundamentally rely” is too strong). Section 3 (method) is clear, but Section 4 (experiments) buries the key result (Table 2) under too much setup. The related work section name-drops papers without explaining what they tried and why it didn’t work. Rewriting Section 2 to include a concrete failure case from existing methods would make the motivation land harder.
Verdict: weak accept — Solves a real problem with a simple, transferable idea, but the evaluation could be deeper and the writing tighter.
Takeaways
Steal the feedback loop pattern: Any agent that interacts with a UI can benefit from this. Instead of “predict action → execute → done,” do “predict action → execute → observe outcome → adjust.” This applies beyond clicking: form filling (type text, see if it appeared in the right field, correct), scrolling (scroll down, check if target is visible, scroll more), even code editing (insert line, check syntax highlighting, fix indentation).
Relative vs absolute coordinates: When your model struggles with precise positioning, switch from predicting absolute targets to predicting deltas from the current state. This reduces the burden on the model’s spatial reasoning and makes errors more recoverable.
Visual feedback as supervision: You don’t need labeled training data for every possible UI. If you can render the outcome of an action (cursor position, form state, etc.), you can use that as a self-supervised signal. The model learns to interpret its own mistakes by seeing them.
论文: 2604.13019 作者: Himangi Mittal, Gaurav Mittal, Nelson Daniel Troncoso, Yu Hu 分类: cs.CV
缺口
计算机使用智能体(CUA)能浏览网页和简单界面,但在密集的编码环境中表现不佳——按钮、标签页、文本框挤在几个像素之内。
现有方法如 SeeClick、CogAgent、ShowUI 采用单次坐标预测:模型看一眼截图,预测 (x, y) 坐标,然后点击。
没有第二次机会。
当第一次点击在拥挤的 IDE 工具栏中偏差 5 个像素时,任务就失败了。
核心问题:这些模型缺乏反馈回路来检测和纠正自己的错误。
问题:密集 IDE 界面需要亚像素级精度
    |
    v
假设:单次预测无法自我纠正位移误差
    |
    v
方法:利用先前尝试的视觉反馈进行多轮修正
    |
    v
证据:在 GPT-5.4、Claude、Qwen 上点击精度提升 15-20%
    |
    v
结论:迭代视觉推理 > 单次坐标预测
增量
一句话: 这篇论文之前,GUI 智能体点一次就听天由命;之后,它们点击、观察结果、调整,直到命中目标。
核心机制
该方法用三阶段循环取代单次预测。
首先,智能体接收任务(“点击调试按钮”)和截图。
它预测初始坐标并点击。
其次,系统捕获新截图,显示光标实际落点——可能向左偏了 8 个像素。
第三,智能体同时看到目标描述和未命中的视觉证据,然后预测修正向量。
这个循环重复 3-5 轮,直到光标落在可接受的误差半径内(通常是 5 个像素)。
架构使用视觉-语言模型(VLM)如 GPT-5.4 或 Claude 作为推理引擎。
每一轮,VLM 接收:(1) 原始任务,(2) 标记了光标位置的当前截图,(3) 先前尝试的历史。
模型输出坐标调整量,而非绝对位置。
系统应用这个增量,点击,并将结果反馈回去。
关键创新是将光标的可见位置视为训练信号——模型学会从原始像素中解读”我在目标西北方 10 个像素”。
第 1 轮:              第 2 轮:              第 3 轮:
截图 -----> VLM -----> 点击 (x1,y1)     截图 -----> VLM -----> 点击 (x2,y2)     截图 -----> 成功
   ^                |                        ^                |                        ^
   |                v                        |                v                        |
   +--- 光标在 (x1,y1) -----------------------+--- 光标在 (x2,y2) -----------------------+
        "太靠左了"                                "差不多了"
把它想象成平行停车。
单次模型是那种目测车位、打一次方向盘、要么成功要么失败的人。
本文的方法是正常人的流程:你倒进去,发现离路边太远,倒出来调整,再检查,微调前进。
方向盘是坐标预测,后视镜是视觉反馈,停车线是目标 UI 元素。
每次调整都使用上一次尝试的信息——你不会从头重新规划,而是纠正刚才观察到的误差。
关键概念
- 视觉反馈回路: 该系统不把 GUI 定位当作一次性感知问题,而是当作闭环控制问题。
每次动作后,智能体观察结果(光标位置),用这个观察计算下一步动作。
这类似恒温器的工作方式:测量温度,与目标比较,调整加热。
这里的”温度”是光标位移;“加热”是坐标调整。
没有这个回路,智能体就是盲飞——它无法知道自己对 UI 的内部模型是否符合现实。
- 位移误差修正: 模型不只是预测”点击 (450, 320)”。
它预测”从当前位置向右移 15 个像素,向下移 8 个像素”。
这种相对编码至关重要,因为 VLM 更擅长判断空间关系(“光标在按钮稍左边”)而非绝对像素坐标。
这就像说”咖啡店在 GPS 坐标 37.7749, -122.4194”和”从你站的地方向北走两个街区”的区别。
第二种在感知有噪声时更容易执行。
- 密集 UI 中的亚像素精度: IDE 在 1920x1080 屏幕上塞进几十个交互元素。
典型的 VS Code 工具栏有 24x24 像素的按钮,间隔 2 个像素。
如果点击偏离中心 10 个像素,可能完全点到错误的按钮。
这里的”亚像素精度”意味着最终光标位置必须在目标中心 5 个像素内——大约是小图标的大小。
这不是关于渲染精度;而是关于高密度界面中的容错度,每个像素都很重要。
框架转变
之前(单次):                      之后(多轮修正):

  任务 + 截图                         任务 + 截图
       |                                   |
       v                                   v
  [VLM 模型]                          [VLM 模型]
       |                                   |
       v                                   v
  预测 (x,y)                          预测 (x,y)
       |                                   |
       v                                   v
    点击一次                              点击
       |                                   |
  成功或失败                                v
  (无法恢复)                        捕获新截图
                                          |
                                          v
                                     [VLM 模型] <--+
                                          |         |
                                          v         |
                                      预测增量       |
                                          |         |
                                          v         |
                                      调整并点击     |
                                          |         |
                                          +---------+
                                          |
                                          v
                                  成功(或达到最大轮数)
[一句话:从盲目的单次预测到迭代视觉伺服,核心转变是将 GUI 定位视为反馈控制问题而非感知问题。
]
专家评审
选题眼光: 真实缺口。
密集编码界面是 CUA 在实践中真正崩溃的地方——任何尝试过自动化 IDE 任务的人都知道单次点击就像抛硬币。
作者没有制造问题;他们在解决部署障碍。
方法成熟度: 巧妙但在机器人学中并不新颖——视觉伺服已经存在几十年了。
贡献在于展示 VLM 可以在没有位移修正显式训练的情况下做到这一点。
简洁性是优点:没有新模型架构,只是不同的提示策略。
但他们没有探索为什么 3-5 轮是最佳点,或是否存在收益递减。
实验诚意: 基线公平(SeeClick、CogAgent、ShowUI 是正确的对比)。
15-20% 的改进在各模型间一致,表明这不是偶然。
但论文缺乏失败分析——多轮修正何时仍会失败?是否存在陷入局部最小值的 UI 模式?基准(precision-cua-bench)是新的,所以无法直接与先前工作比较。
写作功力: 摘要过度推销(“fundamentally rely”太强)。
第 3 节(方法)清晰,但第 4 节(实验)在过多铺垫下埋没了关键结果(表 2)。
相关工作部分罗列论文但没解释它们尝试了什么以及为何不奏效。
重写第 2 节,加入现有方法的具体失败案例,会让动机更有力。
判决: 弱接收 — 用简单、可迁移的想法解决真实问题,但评估可以更深入,写作可以更紧凑。
要点总结
偷走反馈回路模式: 任何与 UI 交互的智能体都能从中受益。
不要”预测动作 → 执行 → 完成”,而要”预测动作 → 执行 → 观察结果 → 调整”。
这适用于点击之外:表单填写(输入文本,看是否出现在正确字段,修正),滚动(向下滚动,检查目标是否可见,继续滚动),甚至代码编辑(插入行,检查语法高亮,修正缩进)。
相对坐标 vs 绝对坐标: 当模型在精确定位上挣扎时,从预测绝对目标切换到预测相对当前状态的增量。
这减轻了模型空间推理的负担,使错误更可恢复。
视觉反馈作为监督: 你不需要为每个可能的 UI 准备标注训练数据。
如果你能渲染动作的结果(光标位置、表单状态等),就可以将其用作自监督信号。
模型通过看到自己的错误来学习解读它们。