Paper: 2604.26883 Authors: Changhyun Roh, Yonghyun Jeong, Jonghyun Lee, Chanho Eom, Jihyong Oh Categories: cs.CV
The Gap
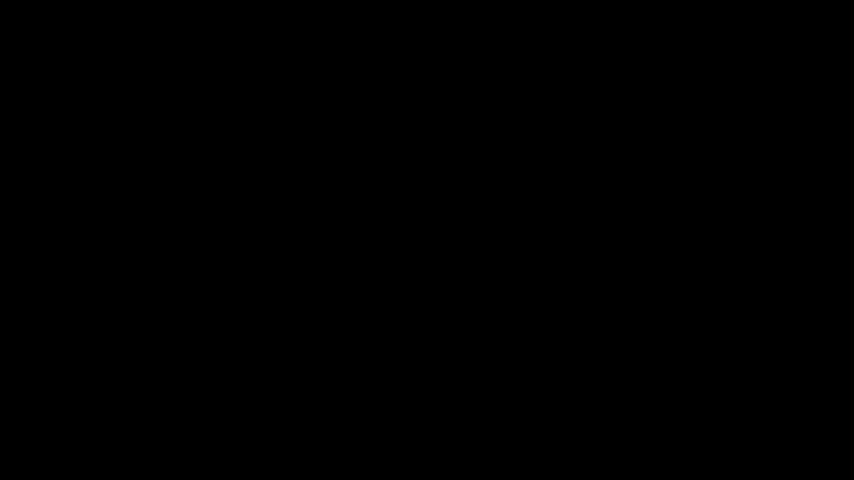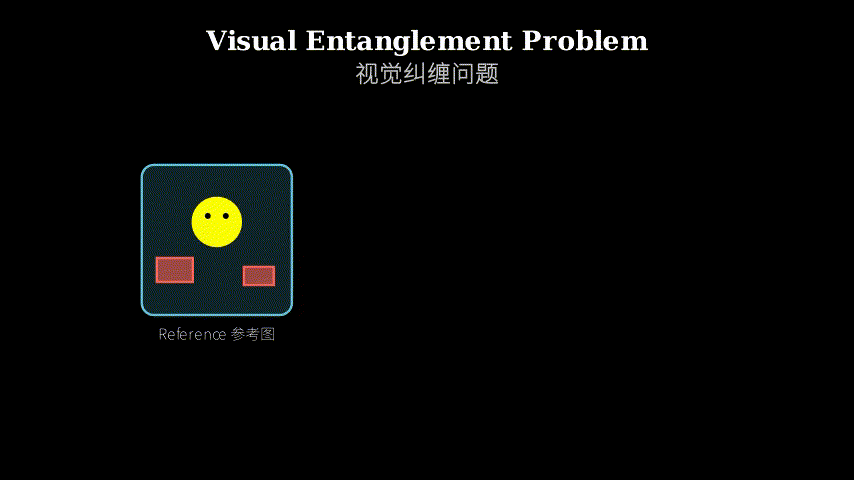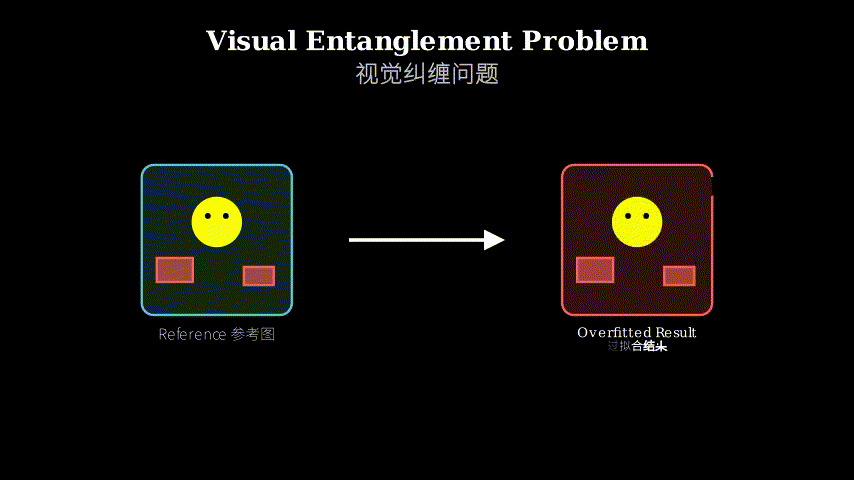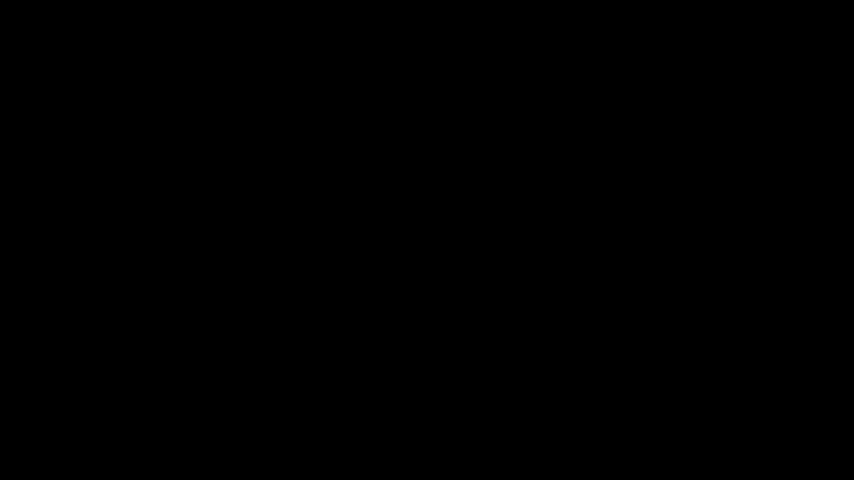
Diffusion-based personalization methods like DreamBooth and Textual Inversion can generate custom concepts from reference images. But when you only have one reference image—common in sticker personalization—test-time fine-tuning (TTF) methods overfit catastrophically. They produce visual entanglement (background artifacts get baked into the learned concept) and structural rigidity (the model memorizes the exact pose/composition and can’t follow new prompts). Existing methods treat the reference image as a monolithic unit, failing to separate “what the thing is” from “where it is” and “what’s around it.”
The sticker domain amplifies this problem because prompts often demand explicit attribute changes (“make it angry,” “put it underwater”) while keeping identity fixed. No existing benchmark systematically evaluates whether a method can disentangle identity from context.
Problem: Single-image overfitting
    |
    v
Assumption: Spatial/structural constraints during adaptation
            can separate identity from context
    |
    v
Method: SEAL (semantic attention loss + token splitting + layer restriction)
    |
    v
Evidence: StickerBench evaluation shows improved identity preservation
          + contextual controllability vs baselines
    |
    v
Conclusion: Explicit spatial guidance during TTF prevents entanglement
The Increment
One sentence: Before SEAL, single-image personalization memorized backgrounds and poses; after SEAL, it learns identity while staying controllable across contexts.
Core Mechanism
SEAL is a plug-and-play adaptation module that wraps around existing personalization pipelines (DreamBooth, Custom Diffusion, etc.) without touching their U-Net backbones. It operates during the test-time fine-tuning phase, applying three constraints:
Semantic-guided Spatial Attention Loss monitors cross-attention maps between text tokens and image regions. It penalizes attention leakage—when the learned concept token attends to background regions instead of the foreground subject. This forces the embedding to encode only the subject, not its surroundings.
Split-merge Token Strategy breaks the concept into two tokens during training: one for coarse identity, one for fine details. At inference, they merge back into a single token. This prevents the single token from becoming a “kitchen sink” that encodes pose, background, and identity all at once.
Structure-aware Layer Restriction freezes deeper U-Net layers during adaptation. Early layers handle high-level semantics (what the thing is), while deep layers encode spatial structure (where things are). By restricting adaptation to early layers, SEAL prevents the model from memorizing reference-specific compositions.
Reference Image
    |
    v
[Foreground Segmentation] --> Attention Mask
    |
    v
Test-time Fine-tuning:
    |
    +---> [Semantic Attention Loss] ---> Penalize background attention
    |
    +---> [Split Token: coarse + fine] ---> Prevent monolithic encoding
    |
    +---> [Layer Restriction: freeze deep] ---> Block structure memorization
    |
    v
Adapted Embedding --> Inference (tokens merge) --> Controllable Generation
Think of SEAL like teaching a portrait artist from a single photo. A bad student memorizes the photo’s background, lighting, and pose—ask them to draw the person in a different setting, and they can’t. SEAL is the instructor standing over their shoulder: “Focus only on the face. Ignore the chair behind them. Don’t memorize how they’re sitting—learn what makes them them.” The attention loss is the instructor tapping the canvas when the student’s eyes wander to the background. The split tokens are like sketching the face in two passes—rough structure first, then details—so the student doesn’t conflate “this person’s nose” with “this person sitting at this angle.” The layer restriction is forbidding the student from practicing perspective drawing during this lesson, because that’s where pose memorization sneaks in.
Key Concepts
-
Visual Entanglement: When a model learns a concept from limited data, it can’t distinguish signal from noise. If your only photo of a dog shows it on a beach, the model might encode “dog” as “dog + sand + waves.” Later, when you prompt “dog in a forest,” you get palm trees in the background. This happens because the embedding vector becomes a compressed representation of the entire image, not just the subject. SEAL fixes this by explicitly supervising where the model is allowed to look during training—attention maps must focus on the foreground mask, or the loss function penalizes the model.
-
Structural Rigidity: Diffusion models generate images by iteratively denoising, guided by cross-attention between text and image features. Deep U-Net layers encode spatial relationships—“the head is above the body,” “the tail curves left.” When fine-tuning on one image, these layers memorize the reference’s exact layout. Prompt “dog jumping” but the model still generates “dog sitting” because the spatial prior is frozen. SEAL restricts adaptation to early layers, which handle semantic identity (“this is a corgi”) without encoding pose. The deep layers stay generic, preserving spatial flexibility.
Framework Shift
Before (standard TTF):              After (SEAL):

Reference Image                     Reference Image
    |                                   |
    v                                   v
Fine-tune entire U-Net          Segment foreground
    |                                   |
    v                                   v
Single concept token            Split tokens (coarse + fine)
    |                                   |
    v                                   v
Embedding = identity            Attention loss: focus on mask
          + background                  |
          + pose                        v
    |                               Freeze deep layers
    v                                   |
Generate: memorized layout              v
                                Embedding = identity only
                                    |
                                    v
                                Generate: flexible layout
From monolithic overfitting to disentangled adaptation, the core shift is explicit spatial supervision during test-time fine-tuning.
Expert Assessment
Problem choice: Real gap. Single-image personalization is a practical constraint (users don’t have 20 photos of their custom sticker character), and the entanglement/rigidity issues are well-documented in prior work. The sticker domain is a smart testbed—attribute edits are explicit and frequent, making failure modes obvious.
Method maturity: Clever but not groundbreaking. The components (attention loss, token splitting, layer freezing) are individually known techniques. The contribution is recognizing that combining them addresses a specific failure mode. The “plug-and-play” framing is honest—it genuinely doesn’t require retraining base models. However, the method introduces hyperparameters (which layers to freeze, attention loss weight) that likely need per-dataset tuning.
Experimental integrity: StickerBench is the paper’s strongest asset—a large-scale dataset with structured six-attribute tags (Appearance, Emotion, Action, Camera, Style, Background) enables systematic evaluation of disentanglement. The baselines (DreamBooth, Custom Diffusion, etc.) are fair. Quantitative metrics (identity preservation, contextual controllability) are appropriate. One concern: no ablation showing whether all three components are necessary, or if two would suffice. The paper claims “consistent improvement” but doesn’t report variance across runs or subjects.
Writing quality: The abstract and introduction are clear. The method section buries the lead—Figure 2 (the architecture diagram) should appear earlier. The “semantic-guided spatial attention loss” is explained in dense math notation before the intuition is given; reversing this order would help. The related work section is thorough but could be trimmed. The experimental section is well-structured, but the qualitative comparisons (Figure 5) cherry-pick favorable examples without showing failure cases.
Verdict: weak accept — Solid incremental contribution with a useful dataset, but the method is a combination of known techniques rather than a conceptual leap. The experimental evaluation is competent but not exhaustive.
Takeaways
Attention supervision as a regularizer: If you’re fine-tuning a model on limited data and want to prevent overfitting to spurious correlations, add a loss term that penalizes attention to irrelevant regions. This generalizes beyond stickers—think few-shot object detection, medical imaging with noisy backgrounds, or any domain where you have segmentation masks.
Layer-wise adaptation: Not all layers should be fine-tuned equally. Early layers encode “what,” deep layers encode “where.” If you want to preserve spatial flexibility, freeze the deep layers. This is a simple heuristic that transfers to other architectures (ViTs, CNNs).
Structured evaluation datasets: StickerBench’s six-attribute schema is a template for building benchmarks in other personalization domains. The key insight: vary one attribute (emotion, action) while holding identity fixed, then measure whether the model can follow the variation. This is more informative than generic “quality” scores.
Token splitting for disentanglement: If a single embedding is encoding too much (identity + context), split it into multiple tokens during training and merge at inference. This is a cheap way to increase representational capacity without architectural changes.
论文: 2604.26883 作者: Changhyun Roh, Yonghyun Jeong, Jonghyun Lee, Chanho Eom, Jihyong Oh 分类: cs.CV
缺口
基于扩散的个性化方法(如 DreamBooth 和 Textual Inversion)可以从参考图像生成自定义概念。
但当你只有一张参考图像时——这在贴纸个性化中很常见——测试时微调(TTF)方法会灾难性地过拟合。
它们产生视觉纠缠(背景伪影被烘焙到学习的概念中)和结构刚性(模型记住确切的姿势/构图,无法遵循新提示)。
现有方法将参考图像视为一个整体单元,无法分离”这东西是什么”与”它在哪里”以及”周围有什么”。
贴纸领域放大了这个问题,因为提示词经常要求明确的属性变化(“让它生气”、“把它放在水下”),同时保持身份固定。
没有现有基准系统地评估方法是否能将身份与上下文解耦。
问题:单图过拟合
    |
    v
假设:适配期间的空间/结构约束
      可以分离身份与上下文
    |
    v
方法:SEAL(语义注意力损失 + token 分割 + 层限制)
    |
    v
证据:StickerBench 评估显示相比基线
      身份保持 + 上下文可控性提升
    |
    v
结论:TTF 期间的显式空间引导防止纠缠
增量
一句话:SEAL 之前,单图个性化会记住背景和姿势;SEAL 之后,它学习身份的同时在不同上下文中保持可控。
核心机制
SEAL 是一个即插即用的适配模块,包裹在现有个性化管道(DreamBooth、Custom Diffusion 等)周围,不触碰它们的 U-Net 主干。
它在测试时微调阶段运行,应用三个约束:
语义引导的空间注意力损失监控文本 token 与图像区域之间的交叉注意力图。
它惩罚注意力泄漏——当学习的概念 token 关注背景区域而非前景主体时。
这迫使嵌入只编码主体,而非其周围环境。
分割-合并 Token 策略在训练期间将概念分解为两个 token:一个用于粗略身份,一个用于精细细节。
在推理时,它们合并回单个 token。
这防止单个 token 成为编码姿势、背景和身份的”大杂烩”。
结构感知层限制在适配期间冻结更深的 U-Net 层。
早期层处理高级语义(这东西是什么),而深层编码空间结构(东西在哪里)。
通过将适配限制在早期层,SEAL 防止模型记住参考特定的构图。
参考图像
    |
    v
[前景分割] --> 注意力掩码
    |
    v
测试时微调:
    |
    +---> [语义注意力损失] ---> 惩罚背景注意力
    |
    +---> [分割 Token:粗略 + 精细] ---> 防止整体编码
    |
    +---> [层限制:冻结深层] ---> 阻止结构记忆
    |
    v
适配嵌入 --> 推理(token 合并)--> 可控生成
把 SEAL 想象成从一张照片教肖像画家。
糟糕的学生会记住照片的背景、光线和姿势——让他们在不同场景中画这个人,他们做不到。
SEAL 是站在他们肩膀上的教练:“只关注脸部。
忽略他们身后的椅子。
不要记住他们怎么坐的——学习是什么让他们成为他们。
“注意力损失是当学生的眼睛游离到背景时教练敲打画布。
分割 token 就像分两遍素描脸部——先粗略结构,再细节——这样学生不会混淆”这个人的鼻子”和”这个人以这个角度坐着”。
层限制是在这节课期间禁止学生练习透视绘画,因为那是姿势记忆潜入的地方。
关键概念
- 视觉纠缠:当模型从有限数据中学习概念时,它无法区分信号和噪声。
如果你唯一一张狗的照片显示它在海滩上,模型可能将”狗”编码为”狗 + 沙子 + 海浪”。
后来,当你提示”森林中的狗”时,你会在背景中得到棕榈树。
这是因为嵌入向量成为整个图像的压缩表示,而不仅仅是主体。
SEAL 通过在训练期间显式监督模型允许看的地方来修复这个问题——注意力图必须聚焦在前景掩码上,否则损失函数会惩罚模型。
- 结构刚性:扩散模型通过迭代去噪生成图像,由文本和图像特征之间的交叉注意力引导。
深层 U-Net 层编码空间关系——“头在身体上方”、“尾巴向左弯曲”。
当在一张图像上微调时,这些层记住参考的确切布局。
提示”狗跳跃”但模型仍然生成”狗坐着”,因为空间先验被冻结了。
SEAL 将适配限制在早期层,这些层处理语义身份(“这是柯基犬”)而不编码姿势。
深层保持通用,保留空间灵活性。
框架转变
之前(标准 TTF):              之后(SEAL):

参考图像                        参考图像
    |                               |
    v                               v
微调整个 U-Net                  分割前景
    |                               |
    v                               v
单个概念 token                  分割 token(粗略 + 精细)
    |                               |
    v                               v
嵌入 = 身份                     注意力损失:聚焦掩码
     + 背景                             |
     + 姿势                             v
    |                           冻结深层
    v                               |
生成:记住的布局                        v
                                嵌入 = 仅身份
                                    |
                                    v
                                生成:灵活布局
从整体过拟合到解耦适配,核心转变是测试时微调期间的显式空间监督。
专家评审
选题眼光:真实缺口。
单图个性化是一个实际约束(用户没有他们自定义贴纸角色的 20 张照片),纠缠/刚性问题在先前工作中有充分记录。
贴纸领域是一个聪明的测试平台——属性编辑是显式且频繁的,使失败模式显而易见。
方法成熟度:巧妙但非突破性。
组件(注意力损失、token 分割、层冻结)是单独已知的技术。
贡献在于认识到组合它们可以解决特定的失败模式。
“即插即用”的框架是诚实的——它确实不需要重新训练基础模型。
然而,该方法引入了超参数(冻结哪些层、注意力损失权重),可能需要针对每个数据集进行调整。
实验诚意:StickerBench 是论文最强的资产——一个具有结构化六属性标签(外观、情绪、动作、相机、风格、背景)的大规模数据集,能够系统评估解耦。
基线(DreamBooth、Custom Diffusion 等)是公平的。
定量指标(身份保持、上下文可控性)是合适的。
一个担忧:没有消融实验显示是否所有三个组件都是必要的,或者两个是否足够。
论文声称”一致改进”但没有报告跨运行或主体的方差。
写作功力:摘要和引言清晰。
方法部分埋没了重点——图 2(架构图)应该更早出现。
“语义引导的空间注意力损失”在给出直觉之前用密集的数学符号解释;颠倒这个顺序会有帮助。
相关工作部分很全面但可以精简。
实验部分结构良好,但定性比较(图 5)挑选了有利的例子,没有显示失败案例。
判决:弱接收 — 扎实的增量贡献和有用的数据集,但方法是已知技术的组合而非概念飞跃。
实验评估称职但不详尽。
要点总结
注意力监督作为正则化器:如果你在有限数据上微调模型并想防止对虚假相关性的过拟合,添加一个惩罚对无关区域注意力的损失项。
这超越了贴纸——想想少样本目标检测、带噪声背景的医学成像,或任何你有分割掩码的领域。
分层适配:并非所有层都应该平等地微调。
早期层编码”是什么”,深层编码”在哪里”。
如果你想保留空间灵活性,冻结深层。
这是一个简单的启发式方法,可以迁移到其他架构(ViT、CNN)。
结构化评估数据集:StickerBench 的六属性模式是在其他个性化领域构建基准的模板。
关键洞察:在保持身份固定的同时改变一个属性(情绪、动作),然后测量模型是否能遵循变化。
这比通用的”质量”分数更有信息量。
用于解耦的 Token 分割:如果单个嵌入编码太多(身份 + 上下文),在训练期间将其分割为多个 token,在推理时合并。
这是一种廉价的方式来增加表示能力,无需架构更改。