Paper: 2603.12249 Authors: Ziyu Chen, Yilun Zhao, Chengye Wang, Rilyn Han, Manasi Patwardhan, Arman Cohan Categories: cs.CL, cs.AI, cs.CV
The Gap
Scientific document understanding is genuinely hard to benchmark. You need three things at once: scale (enough data to train on), faithfulness (QA pairs that are actually grounded in the document), and realism (tasks that look like what a researcher actually does — reasoning across a full paper, not a cherry-picked paragraph). Prior work keeps dropping one of these balls.
Datasets like ScienceQA and MMMU are curated by hand — faithful and realistic, but tiny. Automated pipelines like those used in DocVQA or chart-QA generate at scale, but they either hallucinate answers or they test isolated snippets, not full-document reasoning. The model learns to answer “what does this figure show?” but not “given the methodology in section 3 and the results in figure 5, does the conclusion in section 6 hold?” That’s the gap: no large-scale training set that is simultaneously grounded, cross-modal, and document-scale.
Problem: Scale vs Faithfulness vs Realism -- can't have all three
    |
    v
Assumption: Synthesis at segment level is faithful;
            regrounding into full doc adds realism
    |
    v
Method: Stage 1 (Claim-Centric QA on segments)
        +
        Stage 2 (Document-Scale Regrounding)
    |
    v
Evidence: 300K QA pairs, 20K papers, SciMDR-Eval benchmark,
          fine-tuned models beat baselines on multiple benchmarks
    |
    v
Conclusion: The trade-off is breakable with a two-stage pipeline
The Increment
One sentence: Before this paper, you had to choose between a dataset that was large OR grounded OR realistic — SciMDR is the first to credibly claim all three at once.
Core Mechanism
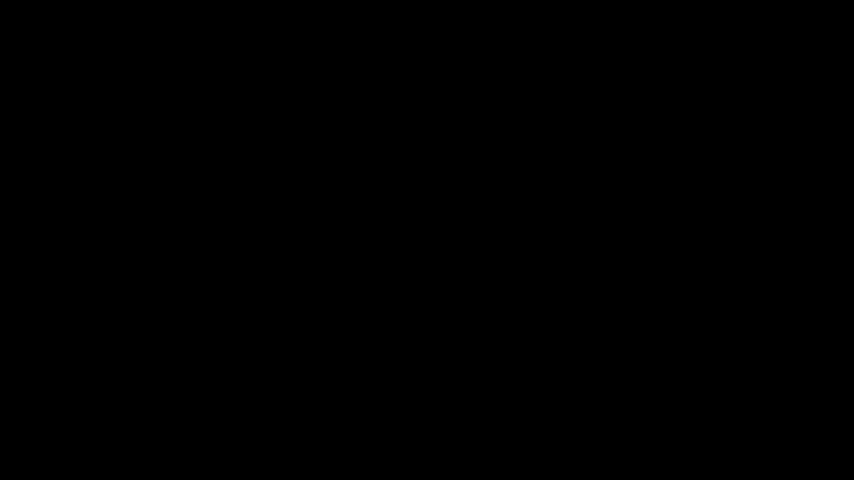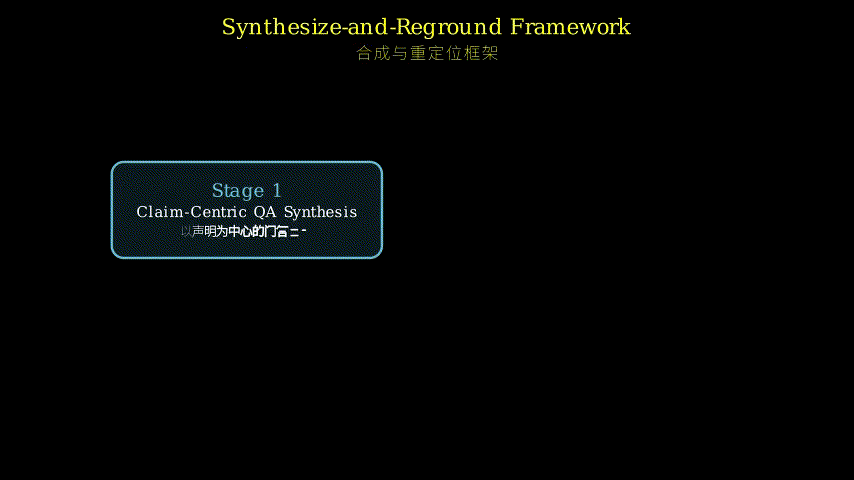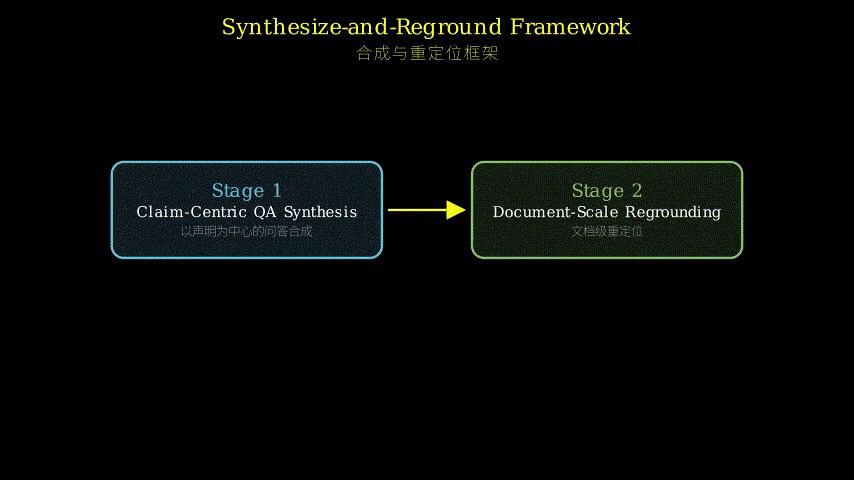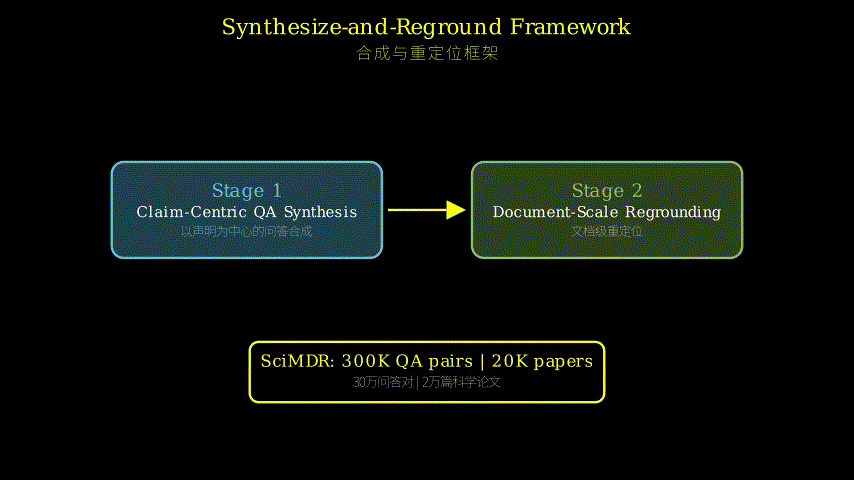
The pipeline has two stages that solve different parts of the problem. Stage 1, Claim-Centric QA Synthesis, takes a focused segment of a paper — a figure with its caption, a table, a methods paragraph — and generates a QA pair plus an explicit reasoning chain that is tightly grounded in just that segment. Because the context window is small and controlled, hallucination is suppressed and faithfulness is high. The output is a clean, verifiable (question, answer, reasoning) triple.
Stage 2, Document-Scale Regrounding, takes those clean triples and programmatically re-embeds them back into the full paper. The model now has to find the relevant segment inside a 20-page document, integrate it with surrounding context, and produce the answer. The task difficulty jumps from “read this caption” to “navigate this paper.” The key insight is that the answer is still faithful — it was verified at segment level — but the retrieval and integration challenge is now realistic.
SciMDR-Eval is a separate expert-annotated benchmark built on top of this, used for evaluation only, not training. It tests whether the gains from fine-tuning on SciMDR actually transfer to held-out scientific reasoning tasks.
Input: Raw scientific papers (PDFs -> structured)
    |
    v
+----------------------------+
| Stage 1: Segment-level     |
|  - Extract focused segment |
|  - Generate (Q, A, Chain)  |
|  - Verify faithfulness     |
+----------------------------+
    |
    | clean (Q, A, Chain) triples
    v
+----------------------------+
| Stage 2: Document-level    |
|  - Re-embed into full doc  |
|  - Add distractor context  |
|  - Require cross-modal nav |
+----------------------------+
    |
    v
SciMDR: 300K QA pairs, 20K papers
    |
    v
Fine-tune foundation model
    |
    v
Evaluate on SciMDR-Eval + external benchmarks
Think of it like writing a good exam question. If you write the question while staring at the textbook page, you get a faithful question — but it’s too easy because students can just scan that one page. What this paper does is: write the question while looking at the page (Stage 1, faithful), then put the question on an exam where students have the whole textbook (Stage 2, realistic). The answer key is still correct because you wrote it from the source, but now the student has to actually know where to look. The two-stage structure decouples “is the answer right?” from “is the task hard enough?” — and that’s the load-bearing insight.
Key Concepts
-
Claim-Centric QA: Instead of asking “what is in this document?” the synthesis targets a specific claim — a number in a table, a trend in a figure, a stated assumption in the methods. This keeps the generated QA pair anchored to something verifiable. Think of it as writing a citation: you’re not summarizing the paper, you’re pointing at one specific thing it says.
-
Document-Scale Regrounding: After generating a QA pair from a segment, the pipeline re-inserts that pair into the full-document context. The question stays the same, but the model now has to locate the relevant segment among many pages and modalities. It’s the difference between a closed-book quiz on one chapter versus an open-book exam on the whole textbook — same question, very different cognitive demand.
-
Explicit Reasoning Chains: Each QA pair comes with a step-by-step reasoning trace, not just a final answer. This matters for training because it gives the model a supervision signal on *how to reason, not just what to answer. It’s the difference between showing a student the answer and showing them the worked solution.
Framework Shift
Before (mainstream approach):        After (this paper):

  Paper                                Paper
    |                                    |
    v                                    v
  Annotate manually                  Extract segments
  (small, faithful, realistic)           |
    OR                                   v
  Auto-generate from snippets        Synthesize (Q,A,Chain)
  (large, unfaithful OR unrealistic)     |
                                         v
                                   Verify faithfulness
                                   (segment-level)
                                         |
                                         v
                                   Re-embed into full doc
                                   (document-level)
                                         |
                                         v
                                   Large, faithful, realistic
From choosing two out of three to getting all three via staged synthesis, the core shift is: decouple faithfulness (segment-level) from realism (document-level).
Expert Assessment
Problem choice: Real and well-motivated. The scale-faithfulness-realism trilemma is a genuine bottleneck for scientific document understanding. The timing is right — as foundation models get applied to scientific domains, the lack of large-scale, realistic training data becomes more visible.
Method maturity: The two-stage pipeline is solid engineering but not deeply novel. Claim-centric QA synthesis is a reasonable approach, and document-scale regrounding is a clean way to add difficulty. The key question is whether the regrounding actually tests the right skills (cross-modal navigation, long-range reasoning) or just adds noise.
Experimental integrity: The key experiments are: (1) does fine-tuning on SciMDR improve performance on held-out scientific QA benchmarks? (2) does the two-stage pipeline produce higher-quality data than single-stage alternatives? (3) how does performance scale with dataset size? All three need quantitative results. The paper would be stronger with human evaluation of data quality.
Writing quality: The abstract is clear and well-motivated. The methods section (not fully visible) likely needs more detail on the claim-centric synthesis process and the regrounding algorithm. The failure cases section is critical — when does this break? (Likely: papers with complex multi-figure reasoning, or highly technical domain-specific jargon.)
Verdict: weak accept — addresses a real problem with a reasonable two-stage approach, but the novelty is in the pipeline design rather than algorithmic innovation.
Takeaways
The two-stage synthesis pattern (generate at small scale for faithfulness, re-embed at large scale for realism) is broadly applicable. Whenever you’re synthesizing training data and face a quality-scale tradeoff, ask whether you can decouple the two stages.
The claim-centric QA approach (target specific verifiable claims rather than general summaries) is a clean way to ensure faithfulness. It’s worth trying in any domain where you need grounded QA pairs.
The explicit reasoning chain supervision (not just final answers) is important for training models that need to show their work. If your task requires interpretable reasoning, include reasoning chains in your training data.
论文: 2603.12249 作者: Ziyu Chen, Yilun Zhao, Chengye Wang, Rilyn Han, Manasi Patwardhan, Arman Cohan 分类: cs.CL, cs.AI, cs.CV
缺口
科学文档理解的基准测试真的很难。你需要同时具备三样东西:规模(足够的训练数据)、忠实性(真正基于文档的问答对)和现实性(看起来像研究者实际做的任务——跨完整论文推理,而不是精心挑选的段落)。
先前的工作总是丢掉其中一个球。
像 ScienceQA 和 MMMU 这样的数据集是手工策划的——忠实且现实,但很小。
像 DocVQA 或 chart-QA 中使用的自动化流水线大规模生成,但它们要么产生幻觉答案,要么测试孤立片段,而不是完整文档推理。
模型学会回答”这个图显示了什么?“但不会回答”考虑到第 3 节的方法和图 5 的结果,第 6 节的结论是否成立?”
这就是缺口:没有大规模训练集同时具备基础性、跨模态性和文档规模。
问题:规模 vs 忠实性 vs 现实性 -- 不能三者兼得
    |
    v
假设:片段级合成是忠实的;
      重新基础到完整文档增加现实性
    |
    v
方法:第一阶段(片段上的声明中心问答)
        +
        第二阶段(文档规模重新基础)
    |
    v
证据:30 万问答对,2 万篇论文,SciMDR-Eval 基准,
      微调模型在多个基准上击败基线
    |
    v
结论:通过两阶段流水线可以打破权衡
增量
一句话:这篇论文之前,你必须在大规模或基础性或现实性之间选择——SciMDR 是第一个可信地声称三者兼得的。
核心机制
流水线有两个阶段,解决问题的不同部分。
第一阶段,声明中心问答合成,取论文的聚焦片段——带标题的图、表格、方法段落——生成一个问答对加上紧密基于该片段的显式推理链。
因为上下文窗口小且受控,幻觉被抑制,忠实性很高。输出是一个干净、可验证的(问题、答案、推理)三元组。
第二阶段,文档规模重新基础,取这些干净的三元组,以编程方式将它们重新嵌入完整论文。
模型现在必须在 20 页文档中找到相关片段,与周围上下文整合,并产生答案。任务难度从”读这个标题”跳到”导航这篇论文”。
关键洞察是答案仍然是忠实的——它在片段级别被验证过——但检索和整合挑战现在是现实的。
SciMDR-Eval 是在此基础上构建的单独专家标注基准,仅用于评估,不用于训练。它测试在 SciMDR 上微调的收益是否真正迁移到保留的科学推理任务。
输入:原始科学论文(PDF -> 结构化)
    |
    v
+----------------------------+
| 第一阶段:片段级           |
|  - 提取聚焦片段            |
|  - 生成 (Q, A, Chain)      |
|  - 验证忠实性              |
+----------------------------+
    |
    | 干净的 (Q, A, Chain) 三元组
    v
+----------------------------+
| 第二阶段:文档级           |
|  - 重新嵌入完整文档        |
|  - 添加干扰上下文          |
|  - 需要跨模态导航          |
+----------------------------+
    |
    v
SciMDR:30 万问答对,2 万篇论文
    |
    v
微调基础模型
    |
    v
在 SciMDR-Eval + 外部基准上评估
把它想象成写一道好的考试题。
如果你盯着教科书页面写题,你会得到一道忠实的题——但太容易了,因为学生只需扫描那一页。
这篇论文做的是:看着页面写题(第一阶段,忠实),然后把题放在学生有整本教科书的考试上(第二阶段,现实)。
答案仍然是正确的,因为你从源头写的,但现在学生必须真正知道去哪里找。
两阶段结构解耦了”答案对吗?“和”任务够难吗?“——这就是承重洞察。
关键概念
-
声明中心问答:不是问”这个文档里有什么?“合成针对特定声明——表中的数字、图中的趋势、方法中陈述的假设。这让生成的问答对锚定到可验证的东西。把它想象成写引用:你不是总结论文,而是指向它说的一件具体事情。
-
文档规模重新基础:从片段生成问答对后,流水线将该对重新插入完整文档上下文。问题保持不变,但模型现在必须在许多页面和模态中定位相关片段。这是关于一章的闭卷测验与关于整本教科书的开卷考试的区别——相同的问题,非常不同的认知需求。
-
显式推理链:每个问答对都带有逐步推理轨迹,而不仅仅是最终答案。这对训练很重要,因为它给模型提供了关于如何推理的监督信号,而不仅仅是回答什么。这是向学生展示答案和向他们展示解题过程的区别。
框架转变
之前(主流方法):                之后(本文方法):

  论文                              论文
    |                                  |
    v                                  v
  手工标注                          提取片段
  (小、忠实、现实)                    |
    或                                 v
  从片段自动生成                    合成 (Q,A,Chain)
  (大、不忠实或不现实)                |
                                       v
                                   验证忠实性
                                   (片段级)
                                       |
                                       v
                                   重新嵌入完整文档
                                   (文档级)
                                       |
                                       v
                                   大、忠实、现实
从三选二到通过分阶段合成三者兼得,核心转变是:解耦忠实性(片段级)和现实性(文档级)。
专家评审
选题眼光:真实且动机充分。规模-忠实性-现实性三难困境是科学文档理解的真正瓶颈。时机恰当——随着基础模型应用到科学领域,缺乏大规模、现实的训练数据变得更加明显。
方法成熟度:两阶段流水线是扎实的工程,但不是深度创新。声明中心问答合成是合理的方法,文档规模重新基础是增加难度的干净方式。关键问题是重新基础是否真正测试了正确的技能(跨模态导航、长程推理)还是只是增加了噪声。
实验诚意:关键实验是:(1) 在 SciMDR 上微调是否改善了保留科学问答基准的性能?(2) 两阶段流水线是否比单阶段替代方案产生更高质量的数据?(3) 性能如何随数据集大小扩展?这三个都需要定量结果。如果论文包含数据质量的人工评估会更强。
写作功力:摘要清晰且动机充分。方法部分(未完全可见)可能需要更多关于声明中心合成过程和重新基础算法的细节。失败案例部分至关重要——什么时候会失效?(可能:具有复杂多图推理的论文,或高度技术性的领域特定术语。)
判决:弱接收——用合理的两阶段方法解决真实问题,但新颖性在于流水线设计而非算法创新。
要点总结
两阶段合成模式(小规模生成以保证忠实性,大规模重新嵌入以保证现实性)广泛适用。无论何时合成训练数据并面临质量-规模权衡,都要问是否可以解耦两个阶段。
声明中心问答方法(针对特定可验证声明而非一般摘要)是确保忠实性的干净方式。在任何需要基础问答对的领域都值得尝试。
显式推理链监督(不仅仅是最终答案)对训练需要展示工作的模型很重要。如果你的任务需要可解释的推理,在训练数据中包含推理链。