Paper: 2608.11152 Authors: Zetao Hong, Song Yuan, Yuanhao Ding, Yibo Zhu, Daxin Jiang, Zhibin Wang, Chen Tian Categories: cs.DC, cs.LG
The Gap
Here’s the setup. Modern RL post-training for LLMs isn’t one workload anymore. You’ve got RLVR (math and code problems with a verifier — long chain-of-thought generations, single turn, moderate prompt), RLHF (reward-model-scored preference data — often shorter generations, multiple samples per prompt), and agentic rollouts (tool calls, environment feedback, many turns with long stalls in between while the sandbox runs your Python or the browser loads). The trainer wants all three mixed in some specified ratio because that’s what makes the resulting policy good. All three hit the same asynchronous inference service.
The state of the art on the serving side is prefix-aware routing. The vLLM Router, SGLang’s cache-aware load balancer, and similar systems all do roughly the same thing: when a request arrives, look at its prefix, figure out which replica already has that prefix in its KV cache, and send it there. Balance load so no replica gets swamped. This works well and it’s the right idea — prefix reuse in RL rollouts is enormous, since you sample multiple completions per prompt and agentic turns share the entire conversation history.
But notice what prefix-aware routing is a policy about: it decides where a request goes. It says nothing about whether a request should be let in right now, or how much of the cache a class of requests deserves to hold. And in mixed rollout serving, that’s where the pain is. An agentic session that’s on turn 7 of 15 is sitting on a fat KV block and will keep sitting on it through the next tool call — maybe 2 seconds, maybe 30. Meanwhile an RLVR request wants to stream 8K tokens of reasoning and needs cache the whole time. RLHF requests come and go fast. Under a pure prefix-locality policy, whichever class happens to arrive in bursts wins the cache, preemptions cascade, and the effective throughput collapses even though the router’s cache-hit-rate dashboard looks great.
Worse, there’s a second-order failure. If you naively fix congestion by throttling whatever class is causing it, you silently change the mixture the trainer asked for. Now you’ve got a systems fix that quietly damages learning. That coupling — serving efficiency versus mixture fidelity — is the actual gap.
   [ PROBLEM ]
   Mixed RLVR + RLHF + agentic rollouts share one
   async inference service. Prefix-aware routers
   (vLLM Router, SGLang cache-aware LB) pick WHERE
   a request goes, not WHETHER it is admitted.
        |
        v
   [ OBSERVATION ]
   Classes differ in three axes, not one:
     (a) sequence structure  (prompt vs gen length)
     (b) interaction pattern (1-turn vs N-turn)
     (c) KV residency time   (how long blocks are held)
   Prefix locality only sees (a). Blindness to (c)
   is what causes preemption cascades.
        |
        v
   [ ASSUMPTION ]
   Congestion is controllable at the ROUTING LAYER,
   before requests reach engine schedulers, IF you
   account for KV footprint x residency, per class.
   And it must be done without distorting the
   trainer-specified workload mixture.
        |
        v
   [ METHOD: MISA-T ]
   +-- adaptive session admission
   +-- workload-aware KV capacity allocation
   +-- residency-time-aware KV accounting
        |
        v
   [ EVIDENCE ]
   rollout-only ablation:
     Step3.7        : +53.3% throughput vs tuned vLLM Router
     Qwen3.6-35B-A3B: +43.6%
   end-to-end, 50 iters, Step3.7:
     +35.6% rollout throughput
     -22.8% mean iteration time
     mixture ~ trainer target ; task scores comparable
        |
        v
   [ CONCLUSION ]
   Rollout scheduling is an admission-control problem,
   not just a placement problem. Prefix locality is
   necessary but insufficient.
The Increment
One sentence: Before this paper, mixed-domain RL rollout serving was tuned by picking a good *placement policy and hoping the engine’s scheduler sorted out the rest; after it, the router itself is a resource-allocation authority that decides which sessions enter and how much KV each workload class may hold — with the trainer’s mixture treated as a hard constraint rather than collateral damage.
Core Mechanism
MISA-T lives entirely at the routing layer, which is the pragmatic design choice here: no engine forks, no vLLM/SGLang internals surgery. It sits between the trainer’s rollout dispatcher and the pool of inference replicas, and it does three things that compose.
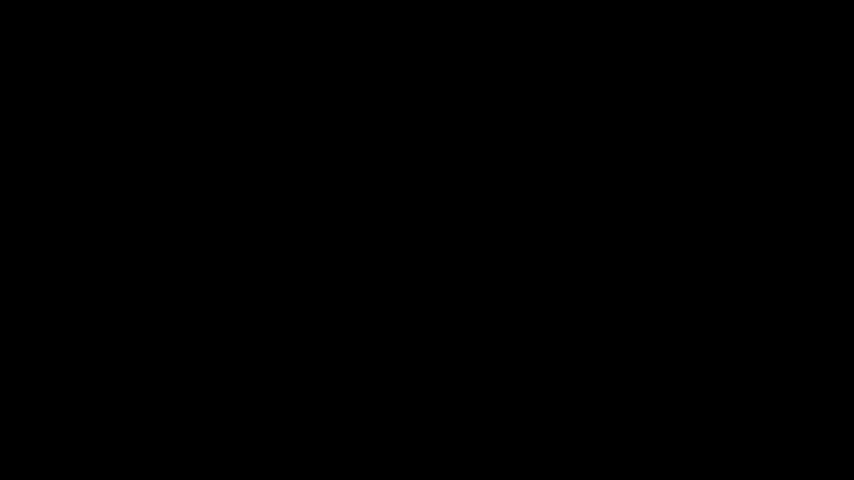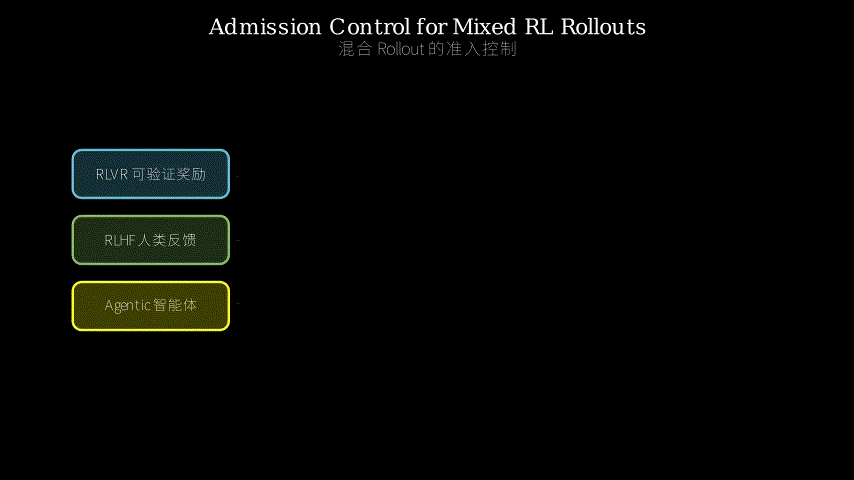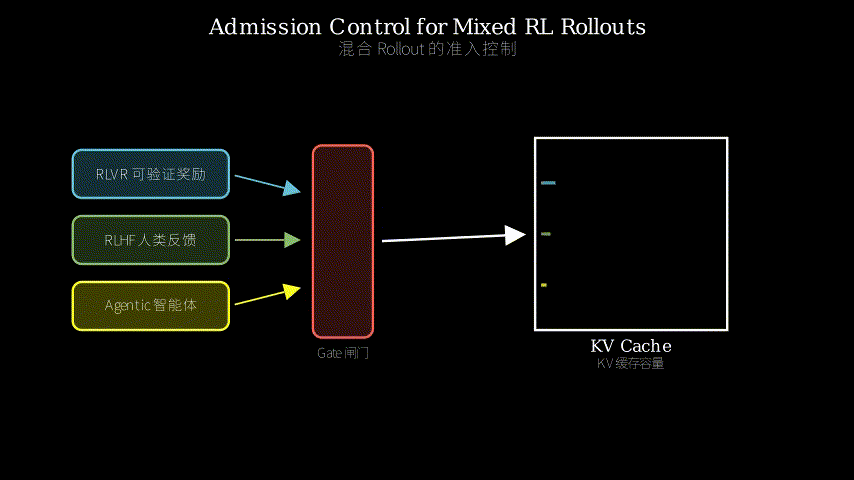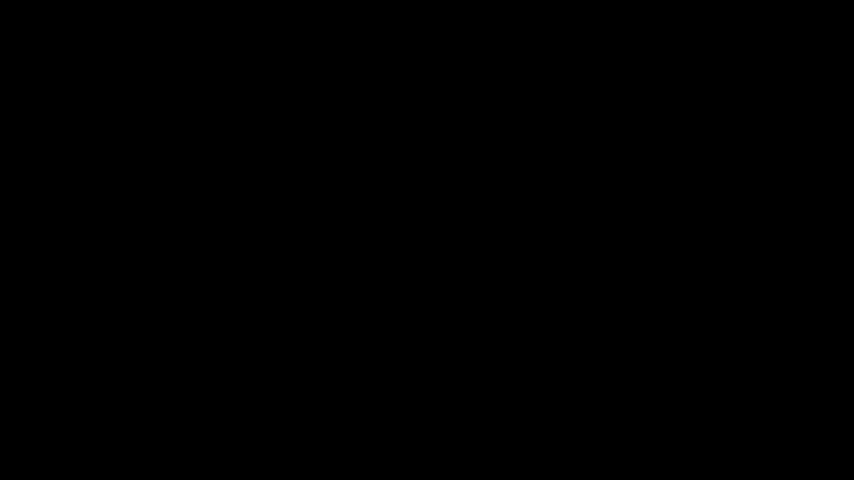
Adaptive session admission. Instead of forwarding every request the moment it arrives, MISA-T maintains a notion of what each replica can actually sustain and gates entry. Note the word *session, not request — an agentic rollout is admitted as a unit with an expected multi-turn lifetime, because admitting turn 1 commits you to holding cache through turns 2..N. Adaptive means the gate moves: it tightens when observed pressure rises (queueing delay, preemption events, cache eviction rate) and loosens when headroom appears. This is the difference between a bouncer with a clicker and a bouncer who watches how full the room actually feels.
Workload-aware KV capacity allocation. The KV budget on each replica is partitioned by workload class rather than served first-come-first-served. RLVR gets a share, RLHF gets a share, agentic gets a share. Crucially the shares are derived from the trainer’s target mixture and each class’s per-session cost, so that the *consumed mixture stays near target. This is the mechanism that decouples “fix congestion” from “distort the data recipe.” If agentic sessions are hogging, you don’t just choke them — you choke them to the level their mixture share entitles them to, which is a defined, defensible number rather than a knob.
Residency-time-aware KV accounting. This is the conceptual core. Existing accounting treats KV cache as a *space resource: this request needs N blocks. MISA-T treats it as a space-time resource: this request needs N blocks for T seconds, so its true cost is roughly N x T. An agentic session with a modest block count but a long stall between turns can be more expensive than an RLVR request with a bigger block count that finishes fast. Under space-only accounting these look reversed, which is precisely why prefix-aware routers get mixed workloads wrong. Once you account in block-seconds, admission and allocation decisions become comparable across classes.
   TRAINER (specifies mixture: e.g. 50% RLVR / 30% RLHF / 20% agentic)
        |
        |  rollout requests, tagged with class
        v
  +==========================================================+
  |                      M I S A - T                         |
  |                   (routing layer)                        |
  |                                                          |
  |  [1] CLASS TAGGER / SESSION TRACKER                      |
  |      request --> which class? new session or turn k?     |
  |      keeps per-session state: turns so far, blocks held   |
  |                     |                                    |
  |                     v                                    |
  |  [2] RESIDENCY-AWARE COST MODEL                          |
  |      cost = blocks x expected_residency                   |
  |         RLVR      : med blocks x med time                |
  |         RLHF      : low blocks x short time              |
  |         agentic   : med blocks x LONG time (stalls)      |
  |                     |                                    |
  |                     v                                    |
  |  [3] KV BUDGET ALLOCATOR (per replica, per class)        |
  |      budget_c derived from trainer mixture + cost_c      |
  |      +-----------+-----------+-----------+               |
  |      |  RLVR pot |  RLHF pot | agentic   |               |
  |      |  ~~~~~~   |  ~~~~     | ~~~~~~~~  |               |
  |      +-----------+-----------+-----------+               |
  |                     |                                    |
  |                     v                                    |
  |  [4] ADMISSION GATE (adaptive)                           |
  |      does class c have block-seconds left in its pot?    |
  |          yes -> admit, then apply prefix-aware placement |
  |          no  -> hold in class queue (do NOT starve;      |
  |                 mixture debt is tracked and repaid)      |
  |                     |                                    |
  |                     v                                    |
  |  [5] PREFIX-AWARE PLACEMENT (retained, not replaced)     |
  |      pick replica with best prefix overlap among those   |
  |      with headroom  ==> keeps cache hit rate high        |
  +==========================================================+
        |                    ^
        |  admitted reqs     |  feedback: queue delay, preemptions,
        v                    |  eviction rate, actual residency
   +---------+  +---------+  +---------+
   | replica |  | replica |  | replica |    (vLLM / SGLang, unmodified)
   |  KV     |  |  KV     |  |  KV     |
   +---------+  +---------+  +---------+
The metaphor: a hotel that had been run as a valet stand.
Think of each inference replica as a hotel and the KV cache as its rooms. Prefix-aware routing is the valet at the door: its whole job is deciding which hotel to send you to, and it’s good at it — it sends you to the hotel where your family is already staying, so you can share their suite (that’s cache reuse). But the valet never asks whether the hotel has rooms, or how long you plan to stay. Everyone who shows up gets sent somewhere, and the front desk deals with the fallout by kicking guests out of rooms mid-stay (that’s preemption and eviction).
MISA-T is the front-desk manager the hotel never had, and its three components are three things a real hotel manager knows:
First, you book a stay, not a night. A business traveler checking in for one night and a family checking in for a two-week trip with day excursions are not the same commitment — the family will keep the room keys while they’re out at the museum. That’s the agentic session holding KV cache through a tool call. Adaptive session admission means the manager commits to the whole stay up front, or not at all, instead of discovering on day four that there’s no room.
Second, the hotel runs room blocks per group. The conference has 50 rooms reserved, the tour group has 30, walk-ins get 20. This is workload-aware KV allocation, and the sizes come from a contract — the trainer’s mixture — not from whoever queued at the desk earliest. When the tour group tries to squeeze in ten extra people, the manager doesn’t evict the conference; he tells the tour group they’re at their block limit. The conference still gets its rooms. The mixture survives.
Third, the manager bills in room-nights, not rooms. One room for fourteen nights costs more than two rooms for one night. This is residency-time-aware accounting, and it’s the piece that makes the other two coherent — without it, the manager would think the family of four in one room is a cheap booking and the four business travelers in four rooms are expensive, which is exactly backwards. Prefix-aware routers count rooms. MISA-T counts room-nights.
And notice: MISA-T doesn’t fire the valet. Placement is still prefix-aware; the front desk just tells the valet which hotels have availability first. That’s why cache hit rates stay high while throughput goes up.
Key Concepts
-
KV cache as a space-time resource (block-seconds): When an LLM generates text, it stores intermediate attention state for every token processed so far — that’s the KV cache, and it’s the real scarce resource in inference, more than compute. Everyone knows it’s measured in blocks (chunks of tokens). What people under-model is *duration. Imagine a parking garage with 100 spaces. If you only count spaces, a car and a truck taking 1 space and 2 spaces look like a 1
problem. But if the car parks for 8 hours and the truck for 10 minutes, the car is consuming 8 space-hours and the truck 0.33 — a 24 problem in the other direction. Agentic rollouts are the all-day parkers: between turn 3 and turn 4 the model isn’t generating anything, but the cache must be held or you pay to recompute the whole conversation. Bill in block-seconds and suddenly the right decisions become obvious. -
Mixture fidelity as a first-class SLO: In normal serving you optimize latency and throughput. In RL rollout serving there’s an extra constraint nobody in the systems literature was tracking: the *composition of what you served has to match what the trainer asked for. If the trainer says “50% math, 30% preference, 20% agentic” and your scheduler quietly delivers 70/25/5 because agentic rollouts kept getting throttled, you’ve built a fast system that trains a worse model — and the failure is invisible in every systems metric. MISA-T’s contribution here is treating this as a constraint to be satisfied, with mixture debt tracked and repaid, rather than as an outcome to be hoped for. This is a genuinely useful framing shift: any time a systems layer sits underneath a learning process, ask what statistical property of the workload your optimization is silently deforming.
-
Admission control vs. placement (the queueing-theory point): These are different levers and confusing them is common. Placement is “which server,” admission is “now or later.” Classic queueing theory tells you that when a system is near saturation and work is heterogeneous, *no placement policy saves you — you have to shed or delay work at the entrance, because past a threshold, letting work in makes total throughput go down (thrashing, preemption, recompute). Anyone who has seen a database die from connection-pool exhaustion knows the shape of this. Prefix-aware routers are pure placement policies operating in a regime where admission is what matters. That’s the paper’s real insight, and stated that plainly it sounds almost obvious — which is usually the sign of a good systems observation.
Framework Shift
  Before (prefix-aware routing):        After (MISA-T):

  trainer                               trainer + mixture contract
    |  all requests, unthrottled          |  requests, class-tagged
    v                                     v
  +--------------------+                +----------------------------+
  |  ROUTER            |                |  ROUTER                   |
  |  question asked:   |                |  questions asked:         |
  |   "WHERE?"         |                |   "SHOULD IT ENTER?"      |
  |                    |                |   "WHOSE BUDGET?"         |
  |  prefix overlap    |                |   "FOR HOW LONG?"         |
  |  + load balance    |                |   then "WHERE?"           |
  +--------------------+                +----------------------------+
    | everything in                      | only what fits, per class
    v                                     v
  +--------------------+                +----------------------------+
  | ENGINE             |                | ENGINE                    |
  | KV = one pot,      |                | KV = per-class pots,      |
  |      FCFS          |                |      billed in block-secs |
  |                    |                |                           |
  | [RLVR][ag][ag][ag] |                | [RLVR ][RLHF][agentic]    |
  |  <- bursty class    |                |  sized by mixture x cost  |
  |     eats the pot    |                |                           |
  |                    |                |                           |
  | preempt! evict!    |                | steady, few preemptions   |
  | recompute!         |                |                           |
  +--------------------+                +----------------------------+
    |                                     |
    v                                     v
  high cache hit rate,                  high cache hit rate AND
  low real throughput,                  high throughput,
  mixture drifts silently               mixture held to target
From placement to admission, the core shift is that the router stops being a traffic sign and becomes a resource governor — one that prices cache in block-seconds and answers to the trainer’s data recipe as a contract.
Expert Assessment
Problem choice: Real gap, and well-timed. The trajectory is clear: 2023-24 was “make rollouts fast” (continuous batching, PagedAttention), 2024-25 was “make rollouts cache-aware” (prefix routing, radix trees), and 2025-26 is “rollouts are now a heterogeneous mixed workload because everyone is training agents *and doing RLVR and still running RLHF in the same pipeline.” Mixed-workload interference at the KV layer is exactly the pain point that shows up when you scale that up, and the mixture-fidelity coupling is a genuinely under-noticed hazard — I’ve seen teams debug reward curves for weeks when the actual cause was the serving layer starving one data source. Naming that failure mode is worth something independent of the mechanism.
Method maturity: Honestly, this is the sensible engineering answer rather than a deep insight, and the paper is at its best when it doesn’t pretend otherwise. Residency-time accounting is the one idea with teeth — it reframes the resource correctly, and the reframing is portable. The other two components are competent applications of textbook material: token-bucket-flavored admission control and weighted fair queueing over a partitioned resource. That’s not a criticism of the result, but it does mean the intellectual delta is thinner than the throughput numbers suggest. Two things I’d want probed harder: first, expected residency has to be *predicted, and agentic turn counts and tool latencies are famously heavy-tailed — how badly does a mispredicted residency hurt, and is there any online correction beyond the feedback loop? Second, and this is the simpler-approach question: how much of the 53% is recoverable by just running separate replica pools per workload class, or per-class rate limits with no residency modeling? Static partitioning is the dumb baseline that often gets 70% of the win, and if the paper doesn’t include it, that’s the first ablation a reviewer should demand.
Experimental integrity: The baseline choice is fair and I want to credit it explicitly — “sweep-tuned cache-aware vLLM Router” means they tuned the baseline rather than shipping it at defaults, which is where most systems papers cheat. Two models, and the end-to-end 50-iteration run with reported task scores and consumed mixture is the right experiment; a lot of rollout-scheduling papers stop at the rollout-only microbenchmark and never show that learning survived. Reporting rollout-only (+53.3%) *and end-to-end (+35.6%) rather than quoting only the bigger number is honest. Now the caveats. The gap between 53% and 35.6% is Amdahl’s law showing up — the training step doesn’t speed up — so the headline should really be the 22.8% iteration-time reduction, and I’d have led with that. “Comparable task scores” over 50 iterations is a weak claim: 50 iterations is short, and scores are noisy at that horizon, so this establishes no catastrophe rather than no cost. The claim I’d most want to see stress-tested is mixture fidelity under adversarial load — “close to the trainer target” needs a number and a distribution, ideally under a burst pattern designed to break it. And single-cluster, two-model results mean I don’t know how this behaves at a different replica-count-to-workload ratio.
Writing quality: The abstract does the thing where three components are named in a list and the reader is left to guess which one carries the weight. It’s residency-time accounting; say so. My concrete suggestion: the paper needs a motivating measurement section that shows the interference and the mixture drift happening in a real trace — footprint versus residency plotted per class, preemption cascades correlated with agentic bursts, and the consumed-versus-target mixture curve diverging under a baseline router. That figure would convert the whole contribution from “we built a scheduler with three features” into “here is a failure mode nobody was measuring, and here is the accounting fix.” Same experiments, twice the impact. Also, “T” in MISA-T is never explained in the abstract, which is a small thing that reads as a rushed submission.
Verdict: weak accept — the residency-time reframing is correct and useful, the end-to-end validation with mixture and task scores is more rigor than this subfield usually shows, but the mechanism is largely known techniques recombined, and the missing static-partitioning baseline plus the thin mixture-fidelity evidence keep it out of strong-accept territory.
Takeaways
Specific things worth stealing:
Price cached state in space-time, not space. Any system holding per-session state under memory pressure — LLM KV cache, connection pools, GPU memory in multi-tenant serving, materialized query state, even CDN edge cache — probably measures footprint and ignores duration. The fix costs almost nothing: multiply by expected residency and let admission decisions compare across heterogeneous tenants on one axis. Block-seconds is the unit. If your eviction policy or admission gate currently reads “needs N units,” ask what it would decide if it read “needs N units for T seconds.”
Admit sessions, not requests. The moment your workload has multi-turn interactions with idle gaps, request-level scheduling is lying to you, because accepting turn 1 is an implicit commitment to hold resources through turn N. Make that commitment explicit at the entrance. This transfers directly to agent serving, long-running RPC sessions, and anything with a sandbox or human in the loop.
When a systems layer sits under a learning process, name the statistical property you might be deforming. This is the framing I’d take furthest beyond this paper. Optimizing throughput while silently shifting the data mixture is a bug that no systems dashboard catches and every ML metric blames on something else. The general move: make the learning-side invariant an explicit, measured constraint in the systems layer — track the debt, repay it — rather than an emergent property. Same logic applies to curriculum ordering, negative-sampling ratios, staleness distributions in async RL, and shard-level data balance. If your scheduler can starve a class, it can change your model.
Ceiling check before you build. Rollout-only +53% became end-to-end +35.6%. Before optimizing a stage, measure its share of wall-clock and compute your Amdahl ceiling. And the corollary for evaluating others’ work: when a paper reports both microbenchmark and end-to-end numbers, the ratio between them tells you how much of the pipeline they actually touched.
The dumb baseline you should always try first: static per-class resource pools. If a paper proposes adaptive, cost-modeled, feedback-driven allocation and doesn’t compare against fixed partitioning, run that comparison yourself before adopting the complexity. Sometimes the answer is separate replica pools and a cron job.
论文: 2608.11152 作者: Zetao Hong, Song Yuan, Yuanhao Ding, Yibo Zhu, Daxin Jiang, Zhibin Wang, Chen Tian 分类: cs.DC, cs.LG
缺口
先说清楚场景。
现在 LLM 的 RL 后训练已经不是单一负载了。
RLVR(数学、代码,有 verifier 打分,特征是超长 CoT 生成、单轮、prompt 中等长度)、RLHF(reward model 打分的偏好数据,生成通常较短,一个 prompt 采多个样本)、agentic rollout(工具调用、环境反馈,多轮,而且轮次之间有长时间的空档——沙箱在跑你的 Python,浏览器在加载页面)。
训练器要求三者按某个指定比例混合,因为这个配比直接决定策略模型的质量。
三类负载打到同一个异步推理服务上。
服务侧的现有最优解是前缀感知路由。
vLLM Router、SGLang 的 cache-aware 负载均衡器,做的事情大同小异:请求进来,看它的前缀,找出哪个副本的 KV cache 里已经有这段前缀,就发到那里去,同时做负载均衡不让某个副本过载。
这套做法是对的,效果也好——RL rollout 里前缀复用量极大,一个 prompt 采多条、agentic 的每一轮共享全部历史对话。
但注意前缀感知路由这个策略管的是什么:它决定请求去哪儿。
它完全没说这个请求现在该不该放进来,也没说某一类请求应该占多少 cache。
而混合 rollout 服务的痛点恰恰就在这儿。
一个走到第 7 轮(总共 15 轮)的 agentic session,正压着一大块 KV,而且接下来的工具调用期间还要继续压着——可能 2 秒,可能 30 秒。
同时一个 RLVR 请求要吐 8K token 的推理链,全程需要 cache。
RLHF 请求来得快走得也快。
在纯前缀局部性策略下,哪一类恰好突发式到达,哪一类就抢到 cache,抢占级联发生,有效吞吐塌掉——而路由器的缓存命中率面板看起来一片大好。
更麻烦的是二阶失效。
如果你为了缓解拥塞,随手掐掉制造拥塞的那一类,你就悄悄改掉了训练器要的配比。
于是你做了一个系统优化,却暗中损伤了学习过程。
服务效率与配比保真度这两者的耦合,才是真正的缺口。
   [ 问题 ]
   RLVR + RLHF + agentic 混合 rollout 共用一个异步
   推理服务。前缀感知路由(vLLM Router、SGLang
   cache-aware LB)决定请求"去哪儿",不决定
   "要不要放进来"。
        |
        v
   [ 观察 ]
   各类负载的差异是三个维度,不是一个:
     (a) 序列结构     (prompt 与生成长度)
     (b) 交互模式     (单轮 vs N 轮)
     (c) KV 驻留时间  (块被占住多久)
   前缀局部性只看得到 (a)。对 (c) 的失明
   才是抢占级联的根因。
        |
        v
   [ 假设 ]
   拥塞可以在**路由层**控制,在请求到达引擎
   调度器之前——前提是按类别把 KV 占用量 x
   驻留时间算清楚。并且不能扭曲训练器
   指定的数据配比。
        |
        v
   [ 方法:MISA-T ]
   +-- 自适应 session 准入
   +-- 负载感知的 KV 容量分配
   +-- 驻留时间感知的 KV 计费
        |
        v
   [ 证据 ]
   纯 rollout 消融:
     Step3.7        : 相比调优后 vLLM Router +53.3%
     Qwen3.6-35B-A3B: +43.6%
   端到端 50 轮迭代,Step3.7:
     rollout 吞吐 +35.6%
     平均迭代时间 -22.8%
     消耗配比 ~ 训练器目标;任务分数持平
        |
        v
   [ 结论 ]
   Rollout 调度是准入控制问题,不只是放置问题。
   前缀局部性必要,但不充分。
增量
一句话:这篇之前,混合域 RL rollout 服务的调优方式是挑一个好的放置策略然后指望引擎调度器兜住剩下的;这篇之后,路由器本身成了资源分配的权力机关,它决定哪些 session 能进、每类负载能占多少 KV——并且把训练器的配比当成硬约束,而不是可以牺牲的副作用。
核心机制
MISA-T 完全活在路由层,这是个务实的设计选择:不用 fork 引擎,不动 vLLM/SGLang 内部。
它坐在训练器的 rollout 分发器和推理副本池之间,做三件可组合的事。
自适应 session 准入。
不是请求一到就转发,MISA-T 维护一个”每个副本实际能承受多少”的判断,在入口设闸。
注意用词是 session 而不是 request——一个 agentic rollout 作为一个整体被准入,带着它预期的多轮生命周期,因为准入第 1 轮就等于承诺了要把 cache 撑到第 N 轮。
自适应意味着闸门会动:观测到压力上升(排队延迟、抢占事件、缓存驱逐率)就收紧,有余量了就放松。
这是”拿着计数器的门卫”和”会看场内实际拥挤程度的门卫”之间的区别。
负载感知的 KV 容量分配。
每个副本上的 KV 预算按负载类别切分,而不是先来先服务。
RLVR 一份,RLHF 一份,agentic 一份。
关键在于这些份额是从训练器的目标配比和每类的单 session 成本推导出来的,从而让实际消耗的配比贴近目标。
这正是把”缓解拥塞”和”扭曲数据配方”解耦开的机制。
如果 agentic session 在抢占资源,你不是简单地掐死它——你是把它掐到它的配比份额所对应的水平,那是一个有定义、能辩护的数字,而不是一个凭感觉调的旋钮。
驻留时间感知的 KV 计费。
这是概念上的核心。
现有计费把 KV cache 当成空间资源:这个请求需要 N 个块。
MISA-T 把它当成时空资源:这个请求需要 N 个块占 T 秒,真实成本大约是 N x T。
一个块数不多但轮次之间空档很长的 agentic session,可能比一个块数更多但很快跑完的 RLVR 请求更贵。
在纯空间计费下这两者的贵贱是颠倒的——这恰恰解释了为什么前缀感知路由器在混合负载上会做错决策。
一旦以”块·秒”为单位计费,准入和分配决策在不同类别之间就可比了。
   训练器 (指定配比: 例如 50% RLVR / 30% RLHF / 20% agentic)
        |
        |  rollout 请求,带类别标签
        v
  +==========================================================+
  |                      M I S A - T                         |
  |                      (路由层)                            |
  |                                                          |
  |  [1] 类别标注 / SESSION 追踪                             |
  |      请求 --> 属于哪类?新 session 还是第 k 轮?         |
  |      维护 per-session 状态: 已进行轮数、占用块数         |
  |                     |                                    |
  |                     v                                    |
  |  [2] 驻留感知成本模型                                    |
  |      cost = 块数 x 预期驻留时间                          |
  |         RLVR    : 中等块数 x 中等时长                    |
  |         RLHF    : 少量块数 x 短时长                      |
  |         agentic : 中等块数 x **长**时长 (空档)           |
  |                     |                                    |
  |                     v                                    |
  |  [3] KV 预算分配器 (按副本、按类别)                      |
  |      budget_c 由训练器配比 + cost_c 推导                 |
  |      +-----------+-----------+-----------+               |
  |      | RLVR 池   | RLHF 池   | agentic 池 |               |
  |      |  ~~~~~~   |  ~~~~     | ~~~~~~~~  |               |
  |      +-----------+-----------+-----------+               |
  |                     |                                    |
  |                     v                                    |
  |  [4] 准入闸门 (自适应)                                   |
  |      类别 c 的池子里还有"块·秒"额度吗?                  |
  |          有 -> 准入,再交给前缀感知放置                  |
  |          无 -> 压在该类队列 (不饿死;配比欠账            |
  |                会被记录并偿还)                           |
  |                     |                                    |
  |                     v                                    |
  |  [5] 前缀感知放置 (保留,未被替换)                        |
  |      在有余量的副本中挑前缀重叠最好的                    |
  |      ==> 缓存命中率保持高位                              |
  +==========================================================+
        |                    ^
        |  已准入请求        |  反馈: 排队延迟、抢占次数、
        v                    |  驱逐率、实际驻留时间
   +---------+  +---------+  +---------+
   |  副本   |  |  副本   |  |  副本   |   (vLLM / SGLang, 未改动)
   |   KV    |  |   KV    |  |   KV    |
   +---------+  +---------+  +---------+
核喻:一家一直只有代客泊车、没有前台经理的酒店。
把每个推理副本想成一家酒店,KV cache 就是房间。
前缀感知路由是门口的泊车小弟:它的全部职责是决定把你送到哪家酒店,而且它干得不错——它会把你送到你家人已经入住的那家,好让你们共用套房(这就是缓存复用)。
但泊车小弟从不问酒店还有没有房,也不问你打算住多久。
来的人一律送走,后果由前台承担——把住到一半的客人从房间里赶出去(这就是抢占和驱逐)。
MISA-T 就是这家酒店一直缺的前台经理,它的三个组件对应真正的经理懂的三件事:
第一,客人订的是一段住宿,不是一晚。
住一晚的商务客和带着白天出游行程住两周的一家人,承诺量完全不同——一家人去博物馆的时候房卡还在他们手里。
这就是 agentic session 在工具调用期间继续占着 KV cache。
自适应 session 准入的意思是,经理要么一开始就为整段住宿留房,要么直接不接,而不是等到第四天才发现没房了。
第二,酒店按团体划房间块。
会议团预留 50 间,旅游团 30 间,散客 20 间。
这就是负载感知的 KV 分配,而房间数来自一份合约——训练器的配比——不是来自谁先排到前台。
旅游团想硬塞十个人进来,经理不会去赶会议团;他会告诉旅游团你们已经到额了。
会议团的房还在,配比保住了。
第三,经理按房·晚计费,不是按房间数。
一间房住十四晚,比两间房住一晚贵。
这就是驻留时间感知计费,也是让前两件事逻辑自洽的那块拼图——没有它,经理会觉得一家四口挤一间房是便宜订单、四个商务客开四间房是贵订单,而这恰好是反的。
前缀感知路由器数房间,MISA-T 数房·晚。
还要注意:MISA-T 没有把泊车小弟辞掉。
放置依然是前缀感知的,前台只是先告诉他哪些酒店还有房。
这就是为什么缓存命中率保持高位、吞吐还能上去。
关键概念
-
KV cache 是时空资源(块·秒):LLM 生成文本时,会为已处理的每个 token 存中间注意力状态,这就是 KV cache,它才是推理里真正稀缺的资源,比算力更稀缺。大家都知道它以”块”(若干 token 的单位)计量。被普遍低估的是时长。想象一个 100 个车位的停车场。如果只数车位,一辆轿车占 1 位、一辆卡车占 2 位,看起来是 1:2 的问题。但如果轿车停 8 小时、卡车停 10 分钟,轿车消耗 8 个”车位·小时”,卡车 0.33——变成反方向的 24:1。Agentic rollout 就是那种停一整天的车:第 3 轮到第 4 轮之间模型什么都没在生成,但 cache 必须占着,否则你要付出重算整段对话的代价。改成按块·秒计费,正确的决策一下就浮出来了。
-
配比保真度是一等公民 SLO:常规服务优化延迟和吞吐。RL rollout 服务多了一个系统文献里没人跟踪的约束:你服务出去的东西的成分必须匹配训练器的要求。如果训练器说”50% 数学、30% 偏好、20% agentic”,而你的调度器因为一直在掐 agentic 而悄悄交付了 70/25/5,那你造了一个又快又能训出更差模型的系统——而这个失效在所有系统指标上都是隐形的。MISA-T 在这里的贡献是把它当成一个需要被满足的约束,欠账要记、要还,而不是一个”希望它成立”的结果。这个框架转换是真有用的:任何时候一个系统层压在学习流程底下,都该问一句——我的优化正在暗中变形哪个统计性质?
-
准入控制 vs 放置(排队论视角):这是两个不同的杠杆,混为一谈的人很多。放置是”发到哪台机器”,准入是”现在还是稍后”。经典排队论告诉你,当系统接近饱和且负载异质时,任何放置策略都救不了你——你必须在入口丢弃或延迟工作,因为超过某个阈值后,多放工作进来会让总吞吐下降(抖动、抢占、重算)。见过数据库被连接池耗尽拖死的人都熟悉这个形状。前缀感知路由器是纯放置策略,却运行在”准入才是关键”的工况区。这就是本文真正的洞见——而这么直白说出来几乎显得理所当然,这通常正是好的系统观察的标志。
框架转变
  之前(前缀感知路由):                之后(MISA-T):

  训练器                                训练器 + 配比合约
    |  全部请求,不限流                    |  请求,带类别标签
    v                                     v
  +--------------------+                +----------------------------+
  |  路由器            |                |  路由器                   |
  |  它只问:          |                |  它依次问:               |
  |   "去哪儿?"       |                |   "该不该进来?"          |
  |                    |                |   "算在谁的预算上?"      |
  |  前缀重叠          |                |   "要占多久?"            |
  |  + 负载均衡        |                |   最后才问 "去哪儿?"     |
  +--------------------+                +----------------------------+
    | 全都放进去                         | 只放装得下的,按类别
    v                                     v
  +--------------------+                +----------------------------+
  | 引擎               |                | 引擎                      |
  | KV = 一个大池,     |                | KV = 按类别切池,          |
  |      先来先服务    |                |      以"块·秒"计费        |
  |                    |                |                           |
  | [RLVR][ag][ag][ag] |                | [RLVR ][RLHF][agentic]    |
  |  <- 突发的那一类    |                |  池子大小 = 配比 x 成本   |
  |     吃掉整个池      |                |                           |
  |                    |                |                           |
  | 抢占!驱逐!重算! |                | 平稳,抢占很少            |
  +--------------------+                +----------------------------+
    |                                     |
    v                                     v
  缓存命中率高,                        缓存命中率高,
  实际吞吐低,                          吞吐也高,
  配比在无声无息中漂移                  配比守住目标
一句话:从放置到准入,核心转变是路由器不再是一块交通指示牌,而变成资源管理者——它用”块·秒”给缓存定价,并且对训练器的数据配方负合约责任。
专家评审
选题眼光:真缺口,而且时间点抓得准。
轨迹很清楚:2023-24 年是”把 rollout 做快”(continuous batching、PagedAttention),2024-25 年是”让 rollout 感知缓存”(前缀路由、radix tree),2025-26 年则是”rollout 已经变成异质混合负载了,因为所有人都在同一条流水线里同时训 agent、跑 RLVR、还留着 RLHF”。
KV 层的混合负载干扰正是规模化之后必然浮现的痛点,而配比保真度的耦合是一个被严重低估的隐患——我见过团队花几周调 reward 曲线,真正的病根在服务层饿死了某一路数据。
把这个失效模式命名出来,这件事本身的价值独立于机制。
方法成熟度:说实话,这是靠谱的工程解,不是深刻的洞见,而论文不装深刻的时候状态最好。
驻留时间计费是唯一有牙齿的想法——它把资源重新定义对了,而且这个重定义是可迁移的。
另外两个组件是教科书材料的称职应用:token bucket 风味的准入控制 + 分区资源上的加权公平队列。
这不是在批评结果,但它意味着智力增量比吞吐数字看起来要薄。
两点我希望被追问得更狠:一,预期驻留时间必须被预测,而 agentic 的轮数和工具延迟是出名的重尾分布——驻留预测错了伤害有多大?除了反馈环之外有没有在线修正?
二,也是”更简单方法”的那个问题:这 53% 里有多少能靠”按负载类别开独立副本池”或”按类别限速、完全不做驻留建模”拿到?
静态分区是那个笨基线,而它经常能拿到 70% 的收益。如果论文没有这个对比,这就是审稿人该要的第一个消融。
实验诚意:基线选择公平,这点我要明确表扬——“sweep-tuned cache-aware vLLM Router”意味着他们调过基线,而不是拿默认配置上场,而后者是多数系统论文作弊的地方。
两个模型;端到端 50 轮迭代、报告任务分数和实际消耗配比,这是对的实验——很多 rollout 调度论文停在纯 rollout 微基准,从不证明学习过程还活着。
同时报纯 rollout(+53.3%)和端到端(+35.6%)而不是只引用大的那个数字,这是诚实的。
现在说保留意见。53% 到 35.6% 之间的落差就是 Amdahl 定律在现身——训练步不会变快——所以真正的标题数字应该是 22.8% 的迭代时间下降,我会把它放在最前面。
“任务分数持平”在 50 轮迭代上是弱主张:50 轮太短,分数在这个尺度上噪声很大,所以这只证明了”没出灾难”,没有证明”没有代价”。
我最想看到被压力测试的是对抗性负载下的配比保真度——“贴近训练器目标”需要一个数字和一个分布,最好是在专门设计来打破它的突发模式下测。
以及,单集群、两个模型意味着我不知道在不同的”副本数:负载量”比例下它会如何表现。
写作功力:摘要犯了那个经典毛病——列出三个组件,让读者自己猜哪个承重。
是驻留时间计费,直接说出来。
具体建议:这篇论文需要一个动机测量章节,用真实 trace 展示干扰和配比漂移正在发生——按类别画出占用量 vs 驻留时间、把抢占级联和 agentic 突发做相关、在基线路由器下画出实际配比与目标配比分道扬镳的曲线。
那张图能把整个贡献从”我们做了个带三个功能的调度器”变成”这里有一个没人在测量的失效模式,这里是对应的计费修正”。
同样的实验,两倍的影响力。
另外 MISA-T 里的 “T” 在摘要里从未解释,小事,但读起来像赶投稿。
判决:弱接收 — 驻留时间的重新定价是正确且有用的,端到端验证带配比和任务分数比这个子领域通常的严谨度要高,但机制主要是已知技术的重组,缺失的静态分区基线加上偏薄的配比保真度证据,让它够不上强接收。
要点总结
值得”偷”走的具体东西:
给缓存状态按时空定价,不是按空间。
任何在内存压力下持有 per-session 状态的系统——LLM KV cache、连接池、多租户服务里的显存、物化查询状态,甚至 CDN 边缘缓存——大概都在量占用量而忽略时长。
修正几乎不要成本:乘上预期驻留时间,让准入决策在异质租户之间落到同一个可比轴上。
单位就是”块·秒”。
如果你的驱逐策略或准入闸门现在读到的是”需要 N 单位”,问问它读到”需要 N 单位持续 T 秒”时会做出什么不同的决定。
准入 session,不是准入 request。
一旦你的负载出现带空闲间隙的多轮交互,请求级调度就在骗你,因为接受第 1 轮就是隐式承诺把资源撑到第 N 轮。
把这个承诺在入口显式化。
这一条直接迁移到 agent 服务、长连接 RPC 会话,以及任何有沙箱或人在环路里的场景。
当系统层压在学习流程底下时,说清楚你可能正在变形哪个统计性质。
这是我最愿意带出这篇论文去用的框架。
为吞吐优化的同时悄悄改变数据配比,是一个系统面板抓不到、而所有 ML 指标都会怪到别处去的 bug。
通用做法:把学习侧的不变量做成系统层里显式、可测的约束——记欠账、还欠账——而不是当成自然涌现的性质。
同样的逻辑适用于 curriculum 顺序、负采样比例、异步 RL 的 staleness 分布、以及 shard 级的数据均衡。
如果你的调度器能饿死某一类,它就能改变你的模型。
动手前先算天花板。
纯 rollout +53% 变成端到端 +35.6%。
优化某个阶段之前,先量它占 wall-clock 的比例,算出你的 Amdahl 上限。
评价别人工作时的推论也在这里:当一篇论文同时报微基准和端到端数字,两者之比会告诉你他们实际动了流水线的多少。
永远该先试的笨基线:静态的按类别资源池。
如果一篇论文提出自适应、带成本模型、反馈驱动的分配,却不跟固定分区比,在你采纳这份复杂度之前,自己跑一遍这个对比。
有时候答案就是”分开的副本池 + 一个 cron job”。