Paper: 2606.26079
Authors: Akshay Paruchuri, Sanmi Koyejo, Ehsan Adeli
Categories: cs.CL, cs.CV, cs.LG
The Gap
Existing MLLM benchmarks (e.g., MMBench, LLaVA-Bench) score each test item on exactly one canonical ordering. They treat the model’s answer as a static property of the content — if a question has four options, only one permutation is ever shown. But emerging evaluation guidelines (e.g., HELM, BIG-bench) demand “order invariance” as a baseline reliability property. The gap? No prior work systematically measures whether shuffling order-irrelevant dimensions (option order, evidence chunk order, document rank, image set order, mixed modality order) changes the answer. This paper fills that gap by building a dedicated audit framework.
[ASCII logic topology: Problem -> Assumption -> Method -> Evidence -> Conclusion]

Problem: "Does order irrelevant to content change MLLM answers?"
   |
   v
Assumption in prior work: "Order does not matter (so single ordering suffices)"
   |
   v
Method: Facet-Probe -- audit 5 order facets across 18 models
   |
   v
Evidence: Bayesian IRT separates ordering noise from per-facet bias; same-ordering control estimates decoder floor. Flip rates 24-50%.
   |
   v
Conclusion: None of 18 models is order-invariant. Prompt mitigation is modality-conditional and insufficient. Propose cross-ordering flip rate as standard metric.
The Increment
One sentence: Before this paper, the field assumed order invariance was safe to ignore; after this paper, we know that every MLLM audited fails it badly, and simple prompt fixes don’t transfer across modalities.
Core Mechanism
Facet-Probe operates in three layers: (1) Facet generation — for each test item, it creates multiple orderings across five facets: option order (permute answer choices), evidence-chunk order (reorder paragraphs in the context), document-rank order (reorder retrieved documents in RAG settings), image-set order (reorder images in a multi-image input), and mixed-modality order (e.g., text-image alternation). (2) Bayesian item-response model — fitted per model per facet, it estimates two latent parameters per item: a “true” correctness score, and a per-facet sensitivity score that captures how much the answer flips when that facet is perturbed. The model accounts for random noise and item difficulty. (3) Same-ordering control — running a Gemini model at temperature 0 on identical inputs multiple times isolates the decoder’s intrinsic stochasticity floor. Any flip rate above that floor is attributed to order sensitivity.
[ASCII diagram of method internal: components, data flow, operations]

  Base Item (canonical order)
         |
         v
   +-----------+     +-----------+
   | Facet Gen |<----| 5 Facets  |
   +-----------+     +-----------+
         |  (e.g., option shuffle, chunk reorder...)
         v
   +-------------------+
   | Multiple orderings |
   +-------------------+
         |
         +---------+---------+---------+---------+---------+
         |  Opt    |  Chunk  |  Doc    |  Img    |  Mixed  |
         +---------+---------+---------+---------+---------+
              |         |         |         |         |
              v         v         v         v         v
   +---------------------------------------------------------+
   |     Bayesian Item-Response Model                        |
   |     (per model per facet)                               |
   |     Input: answer correctness across orderings          |
   |     Output: true score + per-facet sensitivity          |
   +---------------------------------------------------------+
              |
              v
   +---------------------------------------------------------+
   |  Same-ordering control (Gemini temp=0, repeat 10x)     |
   |  = decoder noise floor                                 |
   +---------------------------------------------------------+
              |
              v
   Compare: observed flip rate vs floor -> ordering excess
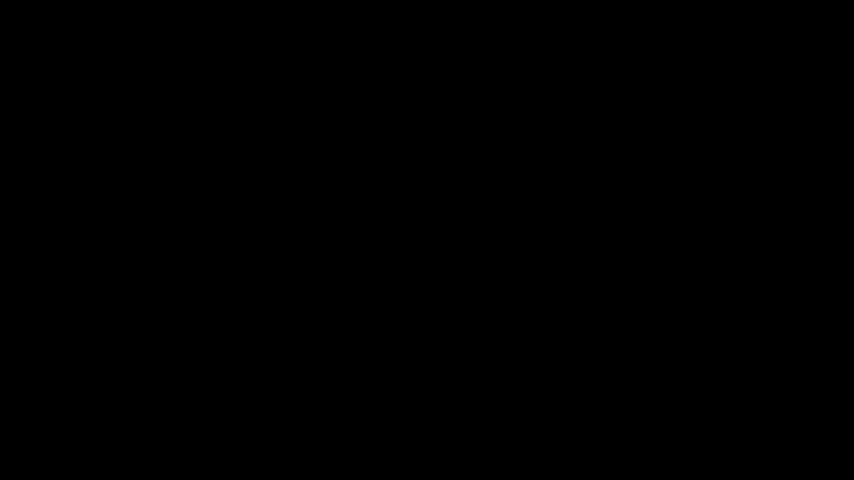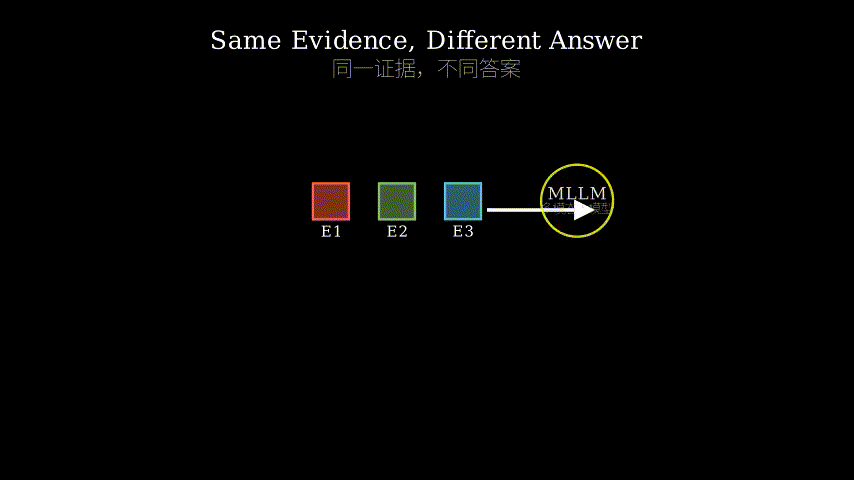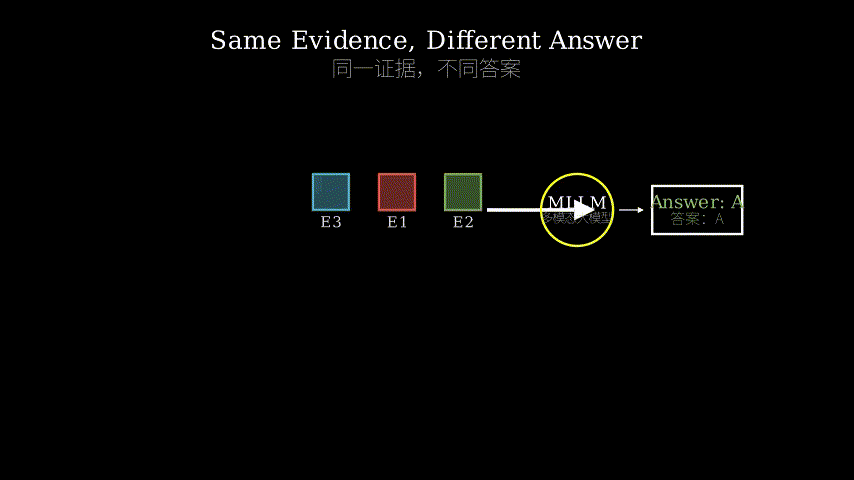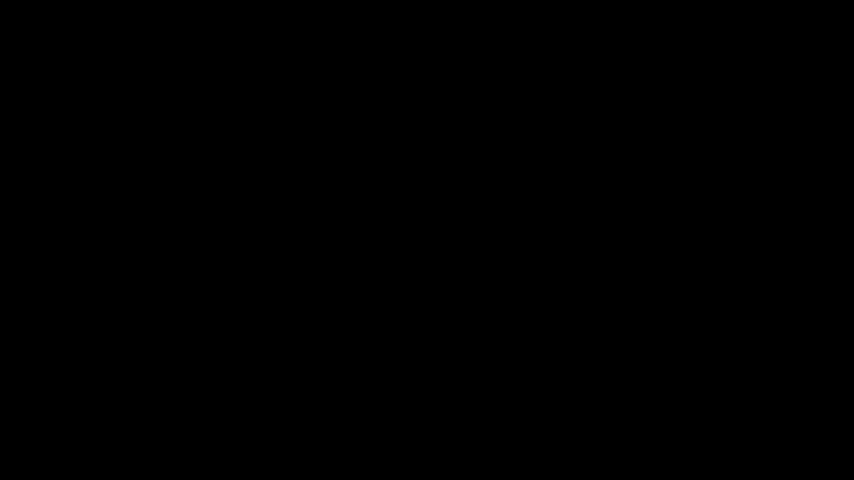
Now let me explain using a load-bearing structural metaphor: Think of each MLLM as a judge in a courtroom. The evidence presented to the judge is a fixed set of documents, images, and options. But the clerk (the model’s input pipeline) has the discretion to rearrange the order of things: the order of witness statements (evidence chunks), the order of exhibits (documents), the placement of photos (image set), the arrangement of the multiple-choice options, and even whether testimony is given in text-then-image or image-then-text (mixed modality). A good, order-invariant judge should deliver the same verdict regardless of which clerk arranged the papers. Facet-Probe is like a contracted audit firm that hires the same judge multiple times, each time giving the same evidence but with the clerk using a different rearranging rule for one facet at a time. The audit then uses a statistical model (like a judge’s “predisposition thermometer”) to separate how much of the verdict flips are due to the judge’s inherent inconsistency (noise) versus how much they are systematically swayed by the ordering (facet bias). Finally, the auditor runs a calibration test — they ask the judge the exact same case twice in the exact same arrangement to see how often the judge contradicts themselves purely from internal randomness (the decoder floor). If the flip rates from the rearrangement tests are much higher than that baseline, then the judge truly cannot be trusted to be order-invariant.
Key Concepts
-
Order sensitivity (flip rate): For a given model and facet, the proportion of test items where changing only the ordering (while keeping all content identical) leads to a different answer. Example: A question has four answer options. You show the model the options in order A,B,C,D and it answers “A”. You then permute the options to D,C,B,A and the model now answers “C”. That’s a flip. The flip rate is the percentage of items where such a change occurs. This measures how much the model’s decision depends on superficial arrangement rather than content.
-
Bayesian Item-Response Theory (IRT): A statistical framework originally from educational testing, used here to separate two sources of variation: the item’s intrinsic difficulty (does the model get it right regardless of ordering?) and the facet’s bias (does a particular ordering of that facet systematically increase or decrease correctness?). The model learns a latent “true correctness” for each item, plus a per-facet shift parameter. This is crucial because raw flip rate conflates random noise with systematic biases; IRT teases them apart.
-
Cross-ordering flip rate: The metric proposed as a standard reporting axis. It is the fraction of test items where the model’s answer changes across two random orderings of a specified facet (or across all facets jointly). Unlike a single-score accuracy, this captures reliability. The authors argue that every MLLM leaderboard should include this number alongside accuracy.
Framework Shift
Before (mainstream approach):        After (this paper):
+===================================+  +===================================+
| Single canonical ordering per     |  | Multiple orderings per facet      |
| test item.                        |  | (5 facets: opt, chunk, doc, img,  |
|                                   |  |  mixed).                          |
| Accuracy = correct / total        |  | Accuracy + cross-ordering flip    |
|                                   |  | rate.                             |
| Order sensitivity is ignored.     |  | Order sensitivity is a first-    |
|                                   |  | class property.                   |
| Conclusion: Model A 85% accurate  |  | Conclusion: Model A 85% accurate  |
| is good.                          |  | but flips on 40% of items under   |
|                                   |  | option shuffling — not good.      |
| If prompted with "think step by   |  | Prompt mitigation is modality-    |
| step", maybe order robustness     |  | conditional: fixes for text don't |
| improves.                         |  | transfer to image ordering.       |
+===================================+  +===================================+
One sentence: From treating order as irrelevant background noise to elevating it as a mandatory, measurable reliability dimension, the core shift is recognizing that shuffling what shouldn’t matter reveals hidden fragility.
Expert Assessment
Problem choice: Real gap. The field has been chasing top-of-the-leaderboard accuracy while ignoring elementary robustness. This paper identifies a blind spot that has been there since the first multimodal benchmark, and it matters because real-world deployment cannot guarantee a canonical ordering. The problem is at the right maturity level — now that we have capable MLLMs, it’s time to stress-test them.
Method maturity: Clever insight deployed with appropriate machinery. The Bayesian IRT is a good fit — it’s not overkill, and the same-ordering control is a simple but crucial sanity check. Simpler alternatives (e.g., just reporting raw flip rate) exist but would conflate noise with bias; the IRT separation adds genuine value. No red flags in design.
Experimental integrity: Solid. 18 models — frontier (GPT-4V, Gemini, Claude) and open-weight — provide comprehensive coverage. The same-ordering control with temperature 0 is a nice baseline. One concern: the mitigation experiments are limited to Gemini and a few prompt strategies; the conclusion that “prompt-level mitigation alone is unlikely to succeed” might be stronger if tested across more models and more prompt variants. But as a first audit, this is thorough. No obvious cherry-picking.
Writing quality: Clear and well-structured. The five-facet breakdown is logical, and the Bayesian modeling section is explained sufficiently for an ML audience. Where it cuts corners: the abstract claims “none of the 18 MLLMs we audit are order-invariant” but the reader must search for the exact flip rate breakdown by model in the appendix. The main paper could show a single summary table more prominently. If the authors rewrite to put the flip rates per model and per facet front and center (maybe Figure 1), the paper’s impact would increase dramatically.
Verdict: Strong accept — The problem is real, the methodology is sound, the results are alarming, and the proposed metric is actionable. Every MLLM practitioner should read this and add “cross-ordering flip rate” to their evaluation checklist.
Takeaways
Three concrete things to steal:
-
The five facet taxonomy — when auditing any system’s input order robustness, use this taxonomy (option, evidence chunk, document rank, image set, mixed modality) as a checklist. It generalizes beyond MLLMs to any model that consumes multiple input elements.
-
The same-ordering control trick — run the same input multiple times (temperature 0) to measure the decoder noise floor. Then any flip rate above that floor must come from ordering changes. This is a cheap, universally applicable sanity check.
-
The Bayesian IRT separation — if you have repeated measurements per item (different orderings), treat item difficulty and ordering sensitivity as latent variables. The IRT framework (or a simpler logistic regression with random effects) lets you attribute source of variation cleanly. Steal this for any reliability diagnostic.
论文: 2606.26079
作者: Akshay Paruchuri, Sanmi Koyejo, Ehsan Adeli
分类: cs.CL, cs.CV, cs.LG
缺口
现有MLLM评测(如MMBench、LLaVA-Bench)对每个测试项只用一种标准顺序打分。 它们把模型的回答当作文本内容的静态属性——比如一道题有四个选项,只展示一种排列顺序。 但新兴的AI评估指南(如HELM、BIG-bench)要求“顺序不变性”作为基线可靠性属性。 缺口在哪?没有任何系统性的工作衡量过,改变与内容无关的顺序(选项顺序、证据块顺序、文档排序、图像集顺序、混合模态顺序)是否会导致答案变化。 本文通过构建专门的审计框架来填补这一缺口。
[ASCII 逻辑拓扑图:问题 -> 假设 -> 方法 -> 证据 -> 结论]

问题:"与内容无关的顺序是否会改变MLLM的答案?"
   |
   v
现有工作的假设:"顺序无关紧要(所以单一顺序就够了)"
   |
   v
方法:Facet-Probe —— 审计5种顺序面,覆盖18个模型
   |
   v
证据:贝叶斯IRT分离顺序噪声与每面偏差;同顺序控制估计解码器下限。
         翻转率24-50%。
   |
   v
结论:18个模型没有一个具有顺序不变性。提示级缓解手段具有模态条件性且不足。
         提出将跨顺序翻转率作为标准指标。
增量
一句话: 这篇论文之前,业界默认可以忽略顺序不变性;这篇论文之后,我们知道每一个被审计的MLLM都严重失败,而且简单的提示调整无法跨模态迁移。
核心机制
Facet-Probe 分三层运作: (1) 面生成——对每个测试项,在五个面上分别创建多种顺序:选项顺序(打乱答案选项)、证据块顺序(重新排列上下文的段落)、文档排名顺序(在RAG场景中重排检索到的文档)、图像集顺序(重排多图像输入中的图片顺序)、混合模态顺序(例如文本-图像交替顺序)。 (2) 贝叶斯项目反应模型——每个模型每面各拟合一个模型,为每个项目估计两个潜在参数:“真”正确率,和一个每面敏感度参数(该面的扰动导致答案翻转的程度)。模型会分离随机噪声和项目难度。 (3) 同顺序控制——让Gemini模型在温度0下对完全相同的输入重复多次,隔离解码器固有的随机性下限。任何高于此下限的翻转率都归因于顺序敏感性。
[方法内部的 ASCII 图:组件、数据流、操作]

基准项目(标准顺序)
         |
         v
   +-----------+
   | 面生成器   |<--- 5个面(选项、块、文档、图像、混合)
   +-----------+
         |
         v
   +-------------------+
   | 多种顺序版本      |
   +-------------------+
         |
         +---------+---------+---------+---------+---------+
         | 选项     | 块      | 文档     | 图像     | 混合     |
         +---------+---------+---------+---------+---------+
              |         |         |         |         |
              v         v         v         v         v
   +----------------------------------------------------------+
   | 贝叶斯项目反应模型(每模型每面)                          |
   | 输入:各顺序下的答案正确性                                |
   | 输出:真正确率 + 每面敏感度                                |
   +----------------------------------------------------------+
              |
              v
   +----------------------------------------------------------+
   | 同顺序控制(Gemini temp=0,重复10次)                     |
   | = 解码器噪声下限                                          |
   +----------------------------------------------------------+
              |
              v
   比较:观察到的翻转率 vs 下限 -> 顺序超额量
现在用一个承重结构性比喻:把每个MLLM想象成法庭上的法官。呈给法官的证据是一套固定的文件、图像和选项。但是书记员(模型的输入管道)可以自主调整顺序:证言顺序(证据块)、物证顺序(文档)、照片摆放(图像集)、多选题选项的排列、甚至陈述是“先文本后图像”还是“先图像后文本”(混合模态)。一个优秀、顺序不变的法官,无论书记员怎么整理案卷,都应该给出同样的判决。Facet-Probe就像一家外聘审计公司:它多次雇佣同一名法官,每次都给出同样的证据,但让书记员每次只改变一个维度的排序规则。然后审计师用统计模型(好比法官的“倾向温度计”)来分离:有多少判决翻转来自法官自身的不一致性(噪声),有多少是真正被顺序系统性地影响了(面偏误)。最后,审计师做校准测试——让法官以完全相同的安排审理同一个案子两次,看看法官光凭内部随机性会犯多少次自我矛盾(解码器下限)。如果打乱顺序测试中的翻转率远高于这个基准,那这位法官就真的不可信了。
关键概念
-
顺序敏感性(翻转率):对于给定的模型和面,改变一个面的顺序(保持内容完全不变)导致答案不同的项目比例。例:一个题目有四个选项,按A,B,C,D顺序展示时模型回答A,打乱为D,C,B,A后模型回答C,这就是一次翻转。翻转率就是出现这种变化的项目百分比。这个指标衡量模型决策在多大程度上依赖于表面排列而非内容。
-
贝叶斯项目反应理论(IRT):一个源自教育测试的统计框架,本文用它分离两种变异来源:项目本身的内在难度(模型不管顺序能否答对?)和面的偏误(特定顺序是否会系统性地提高或降低正确率?)。模型为每个项目学出一个隐式的“真正确率”,再加上每面一个偏移参数。这很关键,因为原始翻转率混淆了随机噪声和系统性偏误;IRT能将它们分离。
-
跨顺序翻转率:本文提议作为标准报告维度的指标。它指的是,在某个面(或所有面共同)的两随机顺序之间,模型答案发生改变的项目比例。与单一分数准确率不同,它捕捉了可靠性。作者认为每个MLLM排行榜都应该把这个数字与准确率并列展示。
框架转变
之前(主流方法):                之后(本文方法):
+============================+  +============================+
| 每个测试项只用单一标准顺序   |  | 每个面生成多种顺序          |
|                             |  | (选项、块、文档、图像、混合) |
| 准确率 = 正确/总数          |  | 准确率 + 跨顺序翻转率        |
|                             |  |                             |
| 顺序敏感性被忽略            |  | 顺序敏感性是优先属性        |
|                             |  |                             |
| 结论:模型A 85%准确,不错   |  | 结论:模型A 85%准确,        |
|                             |  | 但打乱选项后40%项目翻转—— |
|                             |  | 这不好。                    |
| 如果提示说"逐步思考",      |  | 提示缓解具有模态条件性:     |
| 也许顺序鲁棒性会提升。      |  | 对文本有效的策略对图像顺序无效。|
+============================+  +============================+
一句话: 从把顺序当作无关背景噪音,到将其提升为必须测量、有明确定义的可靠性维度,核心转变是认识到“打乱不该有影响的东西”能揭示隐藏的脆弱性。
专家评审
选题眼光: 真缺口。整个领域一直在追逐排行榜顶部准确率,忽视了最基本的鲁棒性。本文发现了一个从第一个多模态基准就存在的盲点,而且它很重要,因为真实部署无法保证规范的顺序。问题处于正确的成熟度——既然我们现在有了强大的MLLM,就应该开始压力测试它们。
方法成熟度: 巧劲配了合适的工具。贝叶斯IRT恰到好处——不是过度复杂,同顺序控制是个简单但关键的校准线。更简单的方法(比如直接报原始翻转率)确实存在,但会混淆噪声和偏误;IRT的分离带来了真正的价值。设计上没有问题。
实验诚意: 扎实。18个模型——前沿的(GPT-4V、Gemini、Claude)和开源权重——覆盖全面。温度0的同顺序控制是个好基线。一个值得注意的点:缓解实验仅限于Gemini和少数提示策略;结论“仅提示级缓解不太可能成功”如果能在更多模型和更多提示变体上验证会更有力。但作为第一次审计,已经相当全面。没有明显的选择性展示。
写作功力: 清晰、结构合理。五个面的分解很有逻辑,贝叶斯建模部分对ML读者来说解释充分。偷懒的地方:摘要说“我们审计的18个MLLM没有一个是顺序不变的”,但读者必须到附录里查找每个模型具体的翻转率分布。主文如果能更突出地放一个汇总表(比如多面×多模型的翻转率热力图),论文的影响力会大幅提升。
判决: 强接收 — 问题真实、方法健全、结果令人震惊、提议的指标可操作。每个MLLM从业者都应该读这篇论文,并把“跨顺序翻转率”加入自己的评估清单。
要点总结
三个可以“偷走”的具体东西:
-
五面分类法——当审计任何系统的输入顺序鲁棒性时,把这张分类表(选项、证据块、文档、图像集、混合模态)作为检查清单。它超越MLLM,适用于任何消费多个输入元素的模型。
-
同顺序控制技巧——对相同输入重复多次(温度0)来测量解码器噪声下限。任何高于下限的翻转率必然来自顺序变化。这是一个廉价、普适的校准线。
-
贝叶斯IRT分离——如果你对每个项目有重复观测(不同顺序),把项目难度和顺序敏感性作为隐变量。IRT框架(或更简单的带随机效应的逻辑回归)能干净地归因变异来源。把这个技巧偷走用到任何可靠性诊断中。