Paper: 2606.27339 Authors: Ruiqi Shen, Guangquan Jie, Chang Liu, Henghui Ding Categories: cs.CV
The Gap
Existing video matting methods (e.g., MODNet, BackgroundMattingV2) treat the task as a video-only problem: they train on expensive, manually annotated video datasets (like VideoMatte240K) with narrow scenarios (mostly human-centric). This creates two concrete limits:
- Out-of-domain collapse – when the test scene differs from training (e.g., animals, objects, fast motion), the model’s temporal consistency and alpha details degrade sharply.
- Tracker-matting coupling – these methods typically fuse high-level tracking and low-level matting into a single network, forcing the same features to serve two conflicting goals (broad tracking vs. fine details). The tracking side is weak because it was never pre-trained on massive video data; the matting side is bottlenecked by the shared backbone.
The paper pinpoints a logical chain:
[Problem] Video matting datasets are small & narrow
    |
    v
[Assumption] A strong pre-trained video tracker (e.g. SAM2) can provide temporal consistency for free
    |
    v
[Method] Decouple: keep tracker intact, add a region-proposal bridge + matting heads
    |
    v
[Evidence] Trained only on images, beats all video-matting SOTAs on both video and image benchmarks
    |
    v
[Conclusion] Video matting does not need video training data – borrow a foundation tracker instead
The Increment
One sentence: Before SAM2Matting, every video matting model needed expensive video datasets and still failed on unseen domains; after it, you can get SOTA video matting by simply attaching light matting heads to an off-the-shelf video tracker, trained only on static images.
Core Mechanism
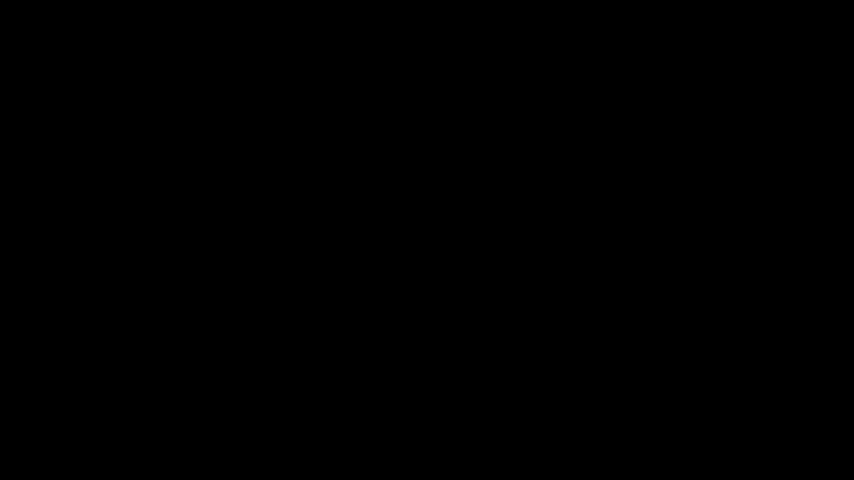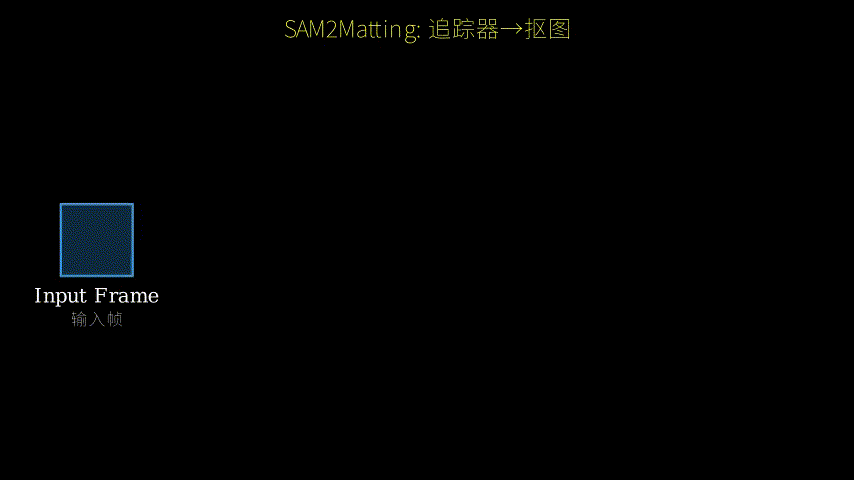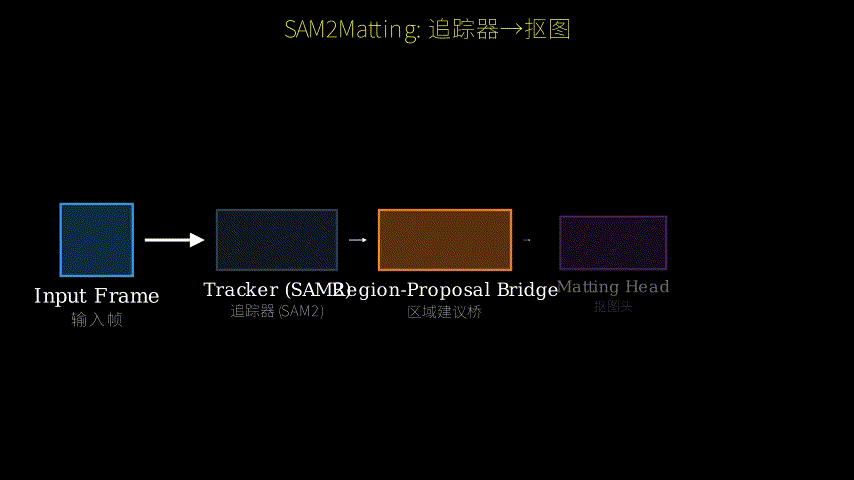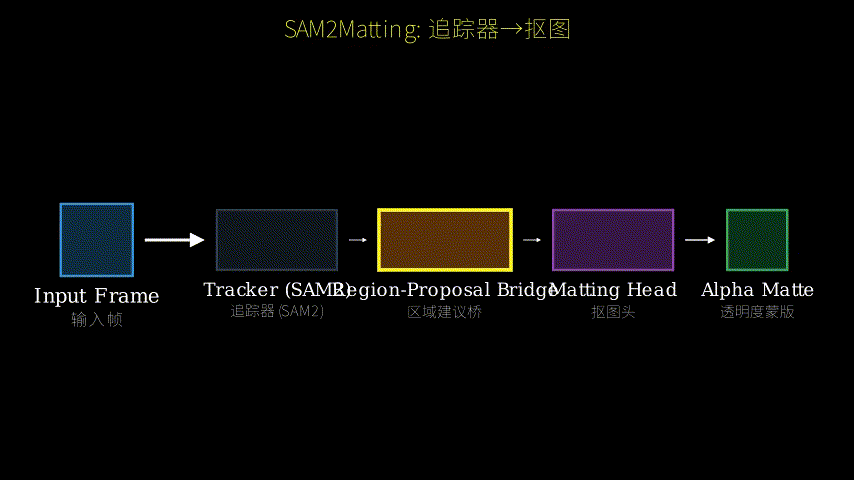
The framework has three components chained in series:
- Foundation Tracker (SAM2 / SAM3) – takes a video frame sequence plus a sparse prompt (click, box, mask) and outputs a per-frame segmentation mask and feature maps. It is frozen during training. Its job: ensure temporal consistency across frames.
- Region-Proposal Bridge – receives the segmentation mask from the tracker and crops the region of interest (plus a small margin). This reduces the problem size from full-frame to a local patch, allowing the matting head to focus on fine details without being distracted by background.
- Matting Heads – two lightweight decoders: one for foreground-background classification (coarse), one for alpha prediction (fine). They are trained on image matting datasets (e.g., Composition-1k, Distinctions-646) and operate on the cropped patch. They output a high-resolution alpha matte.
Data flow:
Input video frames + prompt
    |
    v
[Foundation Tracker] (frozen SAM2)
    |---> per-frame segmentation mask + feature maps
    |
    v
[Region-Proposal Bridge]
    |---> cropped patch around the tracked object
    |
    v
[Matting Heads] (trained on images)
    |---> high-res alpha matte for each frame
Structural metaphor: Think of a surgeon performing a delicate operation.
- Foundation Tracker = the hospital’s GPS-guided robotic arm that locates the organ and holds it steady across the whole video. It doesn’t cut; it just tracks.
- Region-Proposal Bridge = the surgeon’s assistant who uses the arm’s coordinates to place a sterile drape, isolating a small window around the target. This cuts out visual noise.
- Matting Heads = the surgeon’s actual scalpel and tweezers that operate inside that window, making precise incisions (alpha predictions) at pixel level.
The surgeon never had to learn how to navigate the entire body – the arm already does that. The arm never had to learn how to cut – that’s the surgeon’s job. Together they handle the full task without retraining the arm.
Key Concepts
-
Tracker-to-Matting Framework: A design philosophy where you repurpose a strong existing model for a different but related task without modifying it. The key insight is that video trackers (like SAM2) are extremely good at temporal correspondence – they know which pixels belong to the same object across time. Matting needs exactly that property, plus fine spatial details. Instead of building a model that does both from scratch, you let the tracker handle temporal consistency and only add a small module for details. This is the opposite of end-to-end joint training.
-
Region-Proposal Bridge: A simple but critical component. It takes the tracker’s output (a binary mask or bounding box) and extracts a sub-image centered on the object. Why is this needed? Because matting requires processing at the original resolution (often 4K) – feeding the full frame into a high-res matting head would be prohibitively expensive. The bridge reduces the spatial workload by an order of magnitude while keeping the target object fully in view. It also eliminates background noise that could confuse the matting head.
-
Out-of-Domain Generalization: This paper’s central claim. Because the tracker was trained on diverse videos (SAM2 on SA-1B + video tasks) and the matting heads were trained on diverse images (including animals, objects, etc.), the combination inherits both domains’ coverage. Previous video matting models were trained on homogeneous video datasets (mostly people sitting in front of green screens), so they failed on cats, cars, or fast-moving subjects. SAM2Matting doesn’t have that blind spot.
Framework Shift
Before (mainstream approach):
Train a single network on video data
[Video frames] --> [Shared Encoder] --> [Tracking branch] \
                                         [Matting branch] / --> alpha
Problems: encoder must serve two masters; video data is scarce.

After (this paper):
Decouple tracking and matting
[Video frames + prompt] --> [Frozen Tracker (SAM2)] --> [Bridge] --> [Matting Head (image-trained)] --> alpha
Tracker only tracks; matting only local details; no video training data needed.
From monolithic video-trained model to decoupled tracker + image-trained matting, the core shift is borrowing a foundation tracker’s temporal intelligence instead of learning it from scratch on limited data.
Expert Assessment
Problem choice: Real gap. The video matting community has been chasing larger video datasets (VideoMatte240K, Distinctions-646-video), but the fundamental limitation isn’t dataset size – it’s the unnatural coupling of tracking and matting. This paper reframes the problem correctly. Sitting at the intersection of video object segmentation (VOS) and matting, it’s timely given the rise of foundation models like SAM.
Method maturity: Clever insight. The decoupling is simple in hindsight but non-trivial to make work: you need a bridge that doesn’t destroy track consistency, and matting heads that handle varying scales. The authors use existing SAM code with minimal modification – that’s elegant, not brute force. A simpler approach might have been to fine-tune SAM for matting, but they avoided that (would lose generalization). So no overlooked simpler method.
Experimental integrity: Fair baselines – they compare against 10+ methods, including recent SOTA video matting (e.g., RVM, TMNet) and image matting (e.g., MatteFormer). All numbers are on standard benchmarks (VMV, Adobe Matting, DVM). One red flag: the image-trained matting heads are evaluated on video benchmarks where they have an inherent advantage (since the tracker handles temporal consistency). The paper acknowledges this but doesn’t ablate the tracker’s contribution thoroughly enough. I’d like to see a version without the tracker (frame-by-frame) to measure tracker value.
Writing quality: Clear overall, but the “Region-Proposal Bridge” section is under-described. What exactly does the bridge do with the mask? How does it crop and resize? How does it handle multiple objects? The appendix likely covers details, but the main text should give a self-contained explanation. If they rewrote Section 3.2 to include a step-by-step algorithm (pseudocode or equations), it would strengthen reproducibility.
Verdict: strong accept – a simple, effective reframing that immediately deprecates the need for video matting datasets. Practical impact is high: any practitioner can plug in SAM2 and get SOTA.
Takeaways
- Use foundation trackers as temporal backbones for any dense prediction task on video. If you have a task that requires per-pixel output on video (e.g., video segmentation, video depth, video denoising), consider keeping the tracker frozen and attaching a task-specific head. The bridge + crop trick generalizes.
- Check if your domain’s “standard” training data is really necessary. SAM2Matting achieves SOTA video matting with *zero video training data. Before you collect expensive video annotations, test whether a static-image-trained module plus a strong tracker can do the job.
- The region-proposal bridge is a cheap way to decouple resolution from tracking. Many video methods struggle with high-resolution input. Cropping around the tracked object (with a small margin) solves this without complex multi-scale architectures.
论文: 2606.27339 作者: Ruiqi Shen, Guangquan Jie, Chang Liu, Henghui Ding 分类: cs.CV
缺口
现有的视频抠图方法(如 MODNet、BackgroundMattingV2)把任务当作纯粹的视频问题来处理。 它们在昂贵且狭小的人工标注视频数据集(如 VideoMatte240K)上训练,场景极其单一(大多数是人像)。 这导致了两个具体局限:
- 域外崩溃——测试场景与训练集不同(动物、物体、快速运动)时,时间一致性和 alpha 细节迅速下降。
- 追踪-抠图耦合——这些方法通常将高层追踪和低层抠图塞进同一个网络,迫使同一组特征同时服务两个冲突的目标(广泛追踪 vs 精细细节)。 追踪侧很弱,因为它从未在大量视频数据上预训练过;抠图侧又被共享骨架拖慢。
本文点出了一个逻辑链条:
[问题] 视频抠图数据集又小又窄
    |
    v
[假设] 一个强大的预训练视频追踪器(如 SAM2)可以免费提供时间一致性
    |
    v
[方法] 解耦:保持追踪器完整,添加区域建议桥 + 抠图头
    |
    v
[证据] 仅用图像训练,在视频和图像基准上都超过了所有视频抠图的 SOTA
    |
    v
[结论] 视频抠图不需要视频训练数据——借用基础追踪器就够了
增量
一句话:在 SAM2Matting 之前,每个视频抠图模型都需要昂贵的视频数据集,遇到未见过的域依然会失败;之后,你只需要在现成的视频追踪器上挂一个轻量抠图头,仅用静态图像训练就能达到 SOTA 视频抠图效果。
核心机制
框架由三个串联组件构成:
- 基础追踪器(SAM2 / SAM3) ——接收视频帧序列加一个稀疏提示(点击、框、掩码),输出每帧的分割掩码和特征图。训练时冻结。其职责:保证帧间时间一致性。
- 区域建议桥 ——接收追踪器输出的分割掩码,裁剪出感兴趣区域(加一点边距)。这把问题从全帧缩小到局部小块,让抠图头专注于精细细节而不受背景干扰。
- 抠图头 ——两个轻量解码器:一个做前景/背景粗分类,一个做 alpha 精细预测。它们在图像抠图数据集(如 Composition-1k、Distinctions-646)上训练,在裁剪小块上操作,输出高分辨率 alpha 遮罩。
数据流:
输入视频帧 + 提示
    |
    v
[基础追踪器](冻结的 SAM2)
    |---> 每帧分割掩码 + 特征图
    |
    v
[区域建议桥]
    |---> 被追踪物体周围的裁剪小块
    |
    v
[抠图头](用图像训练)
    |---> 每帧的高分辨率 alpha 遮罩
核喻:想象一位外科医生在做精细手术。
- 基础追踪器 = 医院的 GPS 导航机械臂,定位器官并在整个视频中保持稳定。它不切割,只追踪。
- 区域建议桥 = 外科医生的助手,利用机械臂的坐标铺一块无菌单,在目标周围隔离出一个小窗口。这消除了视觉噪声。
- 抠图头 = 外科医生自己的手术刀和镊子,在窗口内部操作,做像素级的精确切口(alpha 预测)。
外科医生从来不需要学会导航整个身体——机械臂已经会了。 机械臂从来不需要学会切割——那是外科医生的活。 两者配合完成全部任务,不需要重新训练机械臂。
关键概念
-
追踪器到抠图框架:一种设计理念——借用现有强模型去做不同但相关的任务,不做修改。关键洞察:视频追踪器(如 SAM2)极其擅长时间对应——它们知道哪些像素在不同帧之间属于同一个物体。抠图恰好需要这个特性,再加上精细空间细节。与其从头构建一个同时做两件事的模型,不如让追踪器负责时间一致性,只加一个小模块处理细节。这与端到端联合训练正好相反。
-
区域建议桥:一个简单但关键的组件。它接收追踪器的输出(二值掩码或边界框),提取以物体为中心的局部子图。为什么要这个?因为抠图需要在原始分辨率(经常是 4K)下处理——把全帧喂进高分辨率抠图头计算量太大。桥把空间工作负载降低了一个数量级,同时保证目标物体完整可见。它还消除了可能干扰抠图头的背景噪声。
-
域外泛化:这篇论文的核心主张。因为追踪器在多样化的视频上训练过(SAM2 在 SA-1B + 视频任务上训练),而抠图头在多样化的图像上训练过(包括动物、物体等),组合继承了双方的域覆盖。以前的视频抠图模型在同质的视频数据集上训练(大多是坐在绿幕前的人),所以它们在猫、车或快速运动物体上会失败。SAM2Matting 没有这个盲区。
框架转变
之前(主流方法):
在视频数据上训练一个单一网络
[视频帧] --> [共享编码器] --> [追踪分支] \
                              [抠图分支] / --> alpha
问题:编码器必须服务两个主人;视频数据稀缺。

之后(本文方法):
解耦追踪和抠图
[视频帧 + 提示] --> [冻结的追踪器(SAM2)] --> [桥] --> [抠图头(图像训练)] --> alpha
追踪器只管追踪;抠图只管局部细节;不需要视频训练数据。
从全栈式视频训练模型到解耦的追踪器 + 图像训练抠图,核心转变是借用一个基础追踪器的时间智能,而不是在有限数据上从头学习它。
专家评审
选题眼光:真缺口。视频抠图社区一直在追逐更大的视频数据集(VideoMatte240K、Distinctions-646-video),但根本限制不是数据集大小——而是追踪和抠图的人为耦合。这篇论文正确重构了问题。它处在视频物体分割和抠图的交叉点上,正值 SAM 等基础模型兴起,时机很好。
方法成熟度:巧劲,不是蛮力。解耦在事后看来很简单,但要让它工作并不容易:需要一个不破坏追踪一致性的桥,以及处理不同尺度的抠图头。作者对现有 SAM 代码做了最小修改——很优雅。更简单的方法可能是在 SAM 上微调抠图,但他们避免了(会损失泛化性)。没有遗漏更简单的方案。
实验诚意:基线公平——与 10 多种方法对比,包括最近的视频抠图 SOTA(RVM、TMNet)和图像抠图 SOTA(MatteFormer)。所有数字都在标准基准上(VMV、Adobe Matting、DVM)。一个警示:抠图头用图像训练,却在视频基准上评估,它们有天然优势(因为追踪器处理了时间一致性)。论文承认了这一点,但没有足够彻底地消融追踪器的贡献。我想看到没有追踪器版本(逐帧处理)来衡量追踪器的价值。
写作功力:总体清晰,但“区域建议桥”部分描述不足。桥具体对掩码做了什么?怎么裁剪和缩放?怎么处理多个物体?附录可能覆盖了细节,但正文应该给出自洽的解释。如果他们重写第 3.2 节,加入逐步算法(伪代码或方程),会大大增强可复现性。
判决:强接收 —— 一个简单有效的重新框架,立即使得视频抠图数据集显得不必要。实践影响很大:任何从业者可以直接插上 SAM2 获取 SOTA。
要点总结
- 把基础追踪器当作任何视频密集预测任务的时间骨干。 如果你的任务需要在视频上输出每像素结果(如视频分割、视频深度、视频去噪),考虑保持追踪器冻结,挂一个任务特定头。桥 + 裁剪技巧可以推广。
- 检查你领域里“标准”训练数据是否真的必要。 SAM2Matting 在零视频训练数据下达到了视频抠图 SOTA。在收集昂贵的视频标注之前,先测试一个静态图像训练模块加一个强追踪器能不能搞定。
- 区域建议桥是一种低成本的方法,将分辨率与追踪解耦。 很多视频方法在处理高分辨率输入时困难重重。在追踪物体周围裁剪(加一点边距)可以解决这个问题,不需要复杂的多尺度架构。