Paper: 2603.02170 Authors: Jintao Zhang, Marco Chen, Haoxu Wang, Kai Jiang, Ion Stoica, Joseph E. Gonzalez, Jianfei Chen, Jun Zhu Categories: cs.LG, cs.AI
The Gap
Low-bit quantization (INT8, INT4) has been a win for inference — SageAttention and similar methods cut memory and speed up attention without hurting accuracy. But training is a different beast. The prior SageBwd work showed you could quantize six of seven matrix multiplications in attention and still fine-tune models successfully. Great for adapting pre-trained models. But try to pre-train from scratch? Performance tanks.
Nobody knew why. Was it the forward pass? The backward pass? Which specific operation breaks? The field had fast inference but couldn’t train models efficiently with low-bit attention. That’s a problem because training is where the real compute cost lives.
Problem: Low-bit attention works for inference + fine-tuning, fails at pre-training
   |
   v
Hypothesis: Quantization error accumulates differently during pre-training
   |
   v
Method: Isolate each quantized operation, test with varying batch sizes
   |
   v
Evidence: Backward score gradient dS is the bottleneck; smaller batches help
   |
   v
Conclusion: SageBwd matches full precision when you control tokens/step + use QK-norm
The Increment
One sentence: Before this paper, low-bit attention was inference-only; after, you can pre-train models with INT8 attention at full-precision performance.
Core Mechanism
SageBwd quantizes the attention mechanism’s matrix multiplications to INT8. Standard attention has seven matmuls: three in the forward pass (Q×K^T, scores×V, output projection) and four in the backward pass (gradients flowing back through those operations). SageBwd quantizes six of them, leaving only the backward score gradient (dS) in higher precision initially.
The method uses two key stabilization techniques. First, QK-normalization: normalize the query and key vectors before computing attention scores. This keeps the score distribution bounded, preventing quantization from amplifying outliers. Second, K-smoothing: apply a smoothing operation to the key matrix to reduce variance. Think of it as pre-conditioning the data before quantization hits it.
The breakthrough insight is diagnostic. By systematically testing each quantized operation, the authors found that the backward score gradient dS is uniquely sensitive to quantization during pre-training. When you quantize dS with large batch sizes (many tokens per step), errors compound and training diverges. But reduce the tokens per step, and suddenly SageBwd matches full-precision training.
Forward Pass:                    Backward Pass:

Q, K, V (INT8)                   dO (gradient from output)
   |                                |
   v                                v
Q x K^T (INT8) -> Scores         dV = Scores^T x dO (INT8)
   |                                |
   v                                v
Softmax (FP32)                   dScores = dO x V^T (FP32) <- bottleneck!
   |                                |
   v                                v
Scores x V (INT8) -> Output      dQ, dK via chain rule (INT8)
Think of quantization like compressing images before sending them over a network. Forward pass is like compressing a photo once — you lose some detail, but it’s viewable. Backward pass is like compressing, decompressing, editing, then compressing again. Each round trip amplifies errors. The score gradient dS is the “edit” step where you’re making fine adjustments based on loss. If those adjustments are quantized too aggressively, you’re editing a blurry image and making it blurrier. QK-norm is like adjusting contrast before compression so details don’t blow out. K-smoothing is like applying a slight blur before compression so sharp edges don’t create artifacts. And reducing tokens per step? That’s like processing smaller image patches so errors don’t accumulate across a huge canvas.
Key Concepts
-
QK-normalization: In standard attention, Q and K can have arbitrary magnitudes. Multiply them, and you get scores that might be tiny or huge. Quantization has fixed precision — say, 256 levels for INT8. If your scores span a wide range, most of those 256 levels get wasted on empty space, and the actual signal gets crushed into a few buckets. QK-norm rescales Q and K to unit norm before multiplication. Now scores live in a predictable range, and quantization levels map cleanly to actual data. Concrete example: without QK-norm, scores might range from -100 to +100. Quantize that to INT8 (-128 to 127), and you’re using 2.28 units per score value — coarse. With QK-norm, scores range from -1 to +1. Now each INT8 level represents 0.016 units — 140× finer resolution.
-
Tokens per step: This is batch size × sequence length. If you’re training with batch size 32 and sequence length 2048, that’s 65,536 tokens per step. Each token contributes to the gradient. When you quantize gradients, errors from each token add up. Small errors × 65,536 tokens = big problem. Reduce to 8,192 tokens per step (batch size 4), and suddenly the same quantization error is 8× less impactful. It’s not about the error per token — it’s about how many errors you’re summing before updating weights.
-
K-smoothing vs Q-smoothing: Smoothing reduces variance in the input matrices before quantization. K-smoothing applies to keys, Q-smoothing to queries. Why does K-smoothing help more? Keys are used in two places: computing attention scores (Q×K^T) and computing the gradient dK. Queries are only used once in the forward pass. Smoothing K stabilizes both forward and backward passes. Smoothing Q only helps forward. During pre-training, the backward pass is where instability shows up, so K-smoothing carries more weight. During fine-tuning, the model is already stable, so Q-smoothing’s forward-pass benefit is enough.
Framework Shift
Before (mainstream approach):        After (this paper):

Training:                            Training:
  Full precision (FP32/BF16)           INT8 quantization
  everywhere                           (6 of 7 matmuls)
       |                                    |
       v                                    v
  Slow, memory-heavy                   Fast, memory-light
       |                                    |
       v                                    v
  Pre-training works                   Pre-training works
                                       (with QK-norm + small batches)

Inference:                           Inference:
  Quantize after training              Same quantization as training
  (post-training quantization)         (quantization-aware training)
       |                                    |
       v                                    v
  Fast, but accuracy risk              Fast, no accuracy loss
From “quantize after training” to “quantize during training,” the core shift is making the training process itself aware of and robust to quantization errors.
Expert Assessment
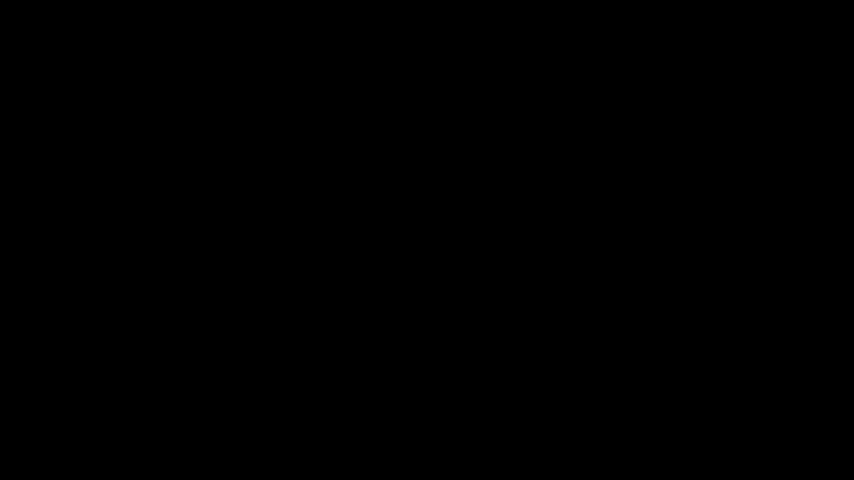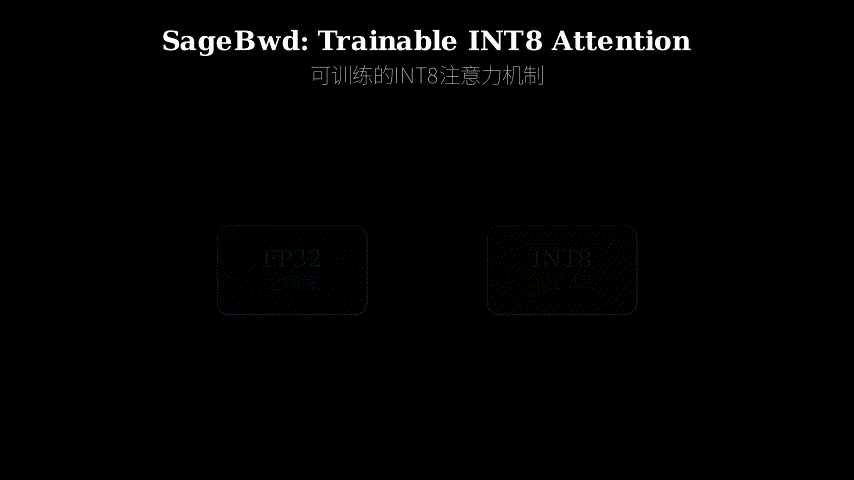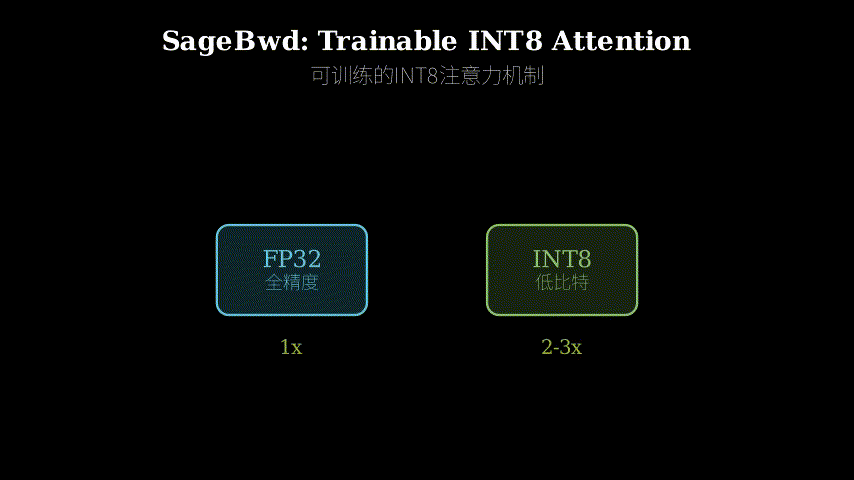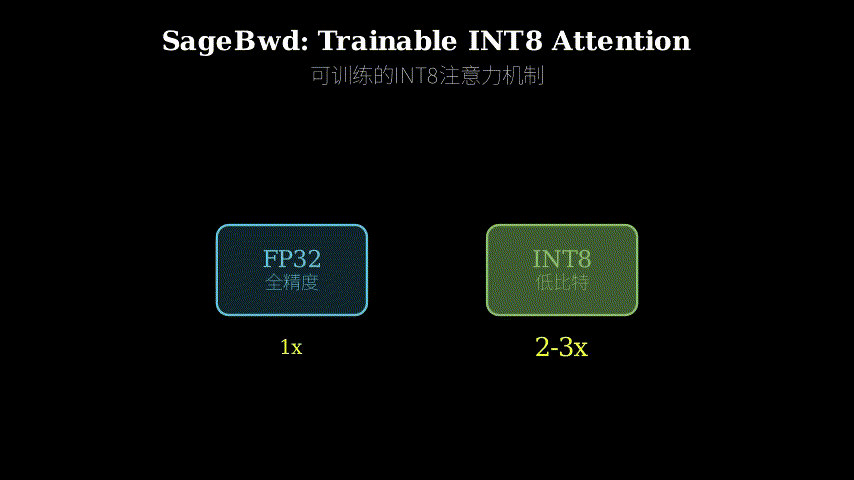
Problem choice: Real gap. Training cost is the elephant in the room for large models. If you can train with INT8 and match FP32 quality, that’s a 4× memory win and potentially 2-3× speed win. The fact that prior work (their own SageBwd v1) failed at pre-training makes this a natural follow-up, not a manufactured problem.
Method maturity: This is diagnostic work done right. They didn’t throw a new architecture at the problem — they isolated variables, tested each quantized operation independently, and found the specific failure mode. The solution (reduce tokens per step, enforce QK-norm) is almost embarrassingly simple, which is a good sign. No exotic tricks, just understanding what breaks and fixing it. That said, “reduce batch size” is a bit unsatisfying as a solution — it trades compute efficiency for numerical stability. I’d want to see if there’s a way to keep large batches and still stabilize dS quantization.
Experimental integrity: Baselines are fair. They compare against full-precision attention and their own prior work. The ablation studies are thorough — they test each component (QK-norm, K-smoothing, Q-smoothing, tokens per step) independently. One minor flag: the experiments are on relatively small models (up to a few billion parameters). Does this scale to 70B+ models? The paper doesn’t say. Also, they don’t report wall-clock training time, only perplexity. I want to know if the speedup is real or if INT8 overhead eats the gains.
Writing quality: The abstract and intro are clear. The method section is dense — they assume you know attention mechanics cold. The ablation section is where the paper shines: each experiment answers a specific question. But the related work section is thin. They cite SageAttention and a few quantization papers but don’t position this work in the broader landscape of efficient training (gradient checkpointing, mixed precision, etc.). Rewriting the related work to show how this fits into the “efficient training” toolkit would elevate the paper.
Verdict: Weak accept — solid diagnostic work with practical impact, but the “reduce batch size” solution feels incomplete, and scaling evidence is missing.
Takeaways
If you’re working on quantization for any iterative optimization process (not just transformers), steal this diagnostic approach: isolate each operation, test with varying data volumes, and find which specific step breaks under quantization. The insight that backward-pass gradients are more sensitive than forward-pass activations is transferable.
For transformer practitioners: QK-normalization is cheap and stabilizes training even without quantization. If you’re seeing training instability with large batch sizes, try it.
The “tokens per step” framing is useful beyond quantization. Any numerical instability that compounds with batch size (gradient clipping, learning rate tuning) can be debugged by varying tokens per step instead of just batch size or sequence length independently.
论文: 2603.02170 作者: Jintao Zhang, Marco Chen, Haoxu Wang, Kai Jiang, Ion Stoica, Joseph E. Gonzalez, Jianfei Chen, Jun Zhu 分类: cs.LG, cs.AI
缺口
低比特量化(INT8、INT4)在推理阶段是个大胜利——SageAttention这类方法能减少内存占用、加速注意力计算,还不损失精度。
但训练是另一回事。
之前的SageBwd工作表明,可以把注意力机制中七个矩阵乘法里的六个量化,微调时仍能保持性能。
这对调整预训练模型很好。
但要从头预训练?性能直接崩盘。
没人知道为什么。
是前向传播的问题?反向传播?具体哪个操作出了问题?业界有了快速推理,却无法用低比特注意力高效训练模型。
这是个大问题,因为训练才是真正的计算成本所在。
问题: 低比特注意力在推理+微调时有效,预训练时失效
   |
   v
假设: 量化误差在预训练时的累积方式不同
   |
   v
方法: 逐个隔离量化操作,用不同批次大小测试
   |
   v
证据: 反向传播的分数梯度dS是瓶颈;小批次有帮助
   |
   v
结论: 控制每步token数+使用QK归一化后,SageBwd达到全精度性能
增量
一句话: 这篇论文之前,低比特注意力只能用于推理;之后,可以用INT8注意力预训练模型并达到全精度性能。
核心机制
SageBwd把注意力机制的矩阵乘法量化到INT8。
标准注意力有七个矩阵乘法:前向传播三个(Q×K^T、分数×V、输出投影),反向传播四个(梯度回流经过这些操作)。
SageBwd量化其中六个,最初只把反向传播的分数梯度(dS)保留在更高精度。
该方法使用两个关键的稳定技术。
第一,QK归一化:在计算注意力分数前归一化查询和键向量。
这让分数分布保持有界,防止量化放大离群值。
第二,K平滑:对键矩阵应用平滑操作以减少方差。
可以理解为在量化击中数据前对数据进行预处理。
突破性洞察是诊断性的。
通过系统测试每个量化操作,作者发现反向传播的分数梯度dS在预训练时对量化特别敏感。
当你用大批次(每步很多token)量化dS时,误差复合,训练发散。
但减少每步的token数,SageBwd突然就能匹配全精度训练了。
前向传播:                        反向传播:

Q, K, V (INT8)                   dO (来自输出的梯度)
   |                                |
   v                                v
Q x K^T (INT8) -> 分数            dV = 分数^T x dO (INT8)
   |                                |
   v                                v
Softmax (FP32)                   d分数 = dO x V^T (FP32) <- 瓶颈!
   |                                |
   v                                v
分数 x V (INT8) -> 输出           dQ, dK 通过链式法则 (INT8)
把量化想象成在网络上发送图片前压缩它们。
前向传播就像压缩一次照片——你损失一些细节,但还能看。
反向传播就像压缩、解压、编辑、再压缩。
每个往返都放大误差。
分数梯度dS是”编辑”步骤,你基于损失做精细调整。
如果这些调整被过度量化,你就是在编辑一张模糊的图片并让它更模糊。
QK归一化就像在压缩前调整对比度,这样细节不会爆掉。
K平滑就像在压缩前应用轻微模糊,这样锐利边缘不会产生伪影。
减少每步token数呢?就像处理更小的图像块,这样误差不会在巨大画布上累积。
关键概念
- QK归一化: 在标准注意力中,Q和K可以有任意大小。
把它们相乘,你得到的分数可能很小或很大。
量化有固定精度——比如INT8有256个级别。
如果你的分数跨越很宽的范围,这256个级别大部分浪费在空白空间上,实际信号被压缩到几个桶里。
QK归一化在乘法前把Q和K重新缩放到单位范数。
现在分数生活在可预测的范围内,量化级别干净地映射到实际数据。
具体例子:没有QK归一化,分数可能从-100到+100。
量化到INT8(-128到127),你每个分数值用2.28个单位——很粗糙。
有了QK归一化,分数范围从-1到+1。
现在每个INT8级别代表0.016个单位——精细140倍。
- 每步token数: 这是批次大小×序列长度。
如果你用批次大小32和序列长度2048训练,那就是每步65,536个token。
每个token都对梯度有贡献。
当你量化梯度时,每个token的误差加起来。
小误差×65,536个token=大问题。
减少到每步8,192个token(批次大小4),突然同样的量化误差影响小了8倍。
这不是关于每个token的误差——而是关于在更新权重前你要累加多少误差。
- K平滑 vs Q平滑: 平滑在量化前减少输入矩阵的方差。
K平滑应用于键,Q平滑应用于查询。
为什么K平滑帮助更大?键在两个地方使用:计算注意力分数(Q×K^T)和计算梯度dK。
查询只在前向传播中使用一次。
平滑K稳定了前向和反向传播。
平滑Q只帮助前向。
在预训练期间,不稳定性出现在反向传播,所以K平滑权重更大。
在微调期间,模型已经稳定,所以Q平滑的前向传播好处就够了。
框架转变
之前(主流方法):                  之后(本文方法):

训练:                            训练:
  全精度(FP32/BF16)                INT8量化
  到处都是                         (7个矩阵乘法中的6个)
       |                                |
       v                                v
  慢,内存占用大                     快,内存占用小
       |                                |
       v                                v
  预训练有效                        预训练有效
                                   (用QK归一化+小批次)

推理:                            推理:
  训练后量化                        训练时就用同样的量化
  (训练后量化)                      (量化感知训练)
       |                                |
       v                                v
  快,但有精度风险                   快,无精度损失
从”训练后量化”到”训练时量化”,核心转变是让训练过程本身意识到量化误差并对其保持鲁棒。
专家评审
选题眼光: 真实缺口。
训练成本是大模型领域的大象。
如果你能用INT8训练并匹配FP32质量,那就是4倍内存优势和潜在的2-3倍速度优势。
之前的工作(他们自己的SageBwd v1)在预训练时失败,这让本文成为自然的后续,而非人造问题。
方法成熟度: 这是做对了的诊断工作。
他们没有向问题扔一个新架构——他们隔离变量,独立测试每个量化操作,找到了具体的失败模式。
解决方案(减少每步token数,强制QK归一化)简单得几乎令人尴尬,这是个好兆头。
没有奇异技巧,只是理解什么坏了并修复它。
话虽如此,“减少批次大小”作为解决方案有点不令人满意——它用计算效率换数值稳定性。
我想看看是否有办法保持大批次同时稳定dS量化。
实验诚意: 基线公平。
他们与全精度注意力和自己之前的工作比较。
消融研究很彻底——他们独立测试每个组件(QK归一化、K平滑、Q平滑、每步token数)。
一个小警示:实验在相对小的模型上(最多几十亿参数)。
这能扩展到70B+模型吗?论文没说。
另外,他们没有报告实际训练时间,只有困惑度。
我想知道加速是否真实,还是INT8开销吃掉了收益。
写作功力: 摘要和引言清晰。
方法部分密集——他们假设你对注意力机制了如指掌。
消融部分是论文的亮点:每个实验回答一个具体问题。
但相关工作部分单薄。
他们引用了SageAttention和几篇量化论文,但没有把这项工作定位在更广泛的高效训练景观中(梯度检查点、混合精度等)。
重写相关工作以展示这如何融入”高效训练”工具包会提升论文。
判决: 弱接收——扎实的诊断工作,有实际影响,但”减少批次大小”解决方案感觉不完整,缺少扩展证据。
要点总结
如果你在做任何迭代优化过程的量化(不只是transformer),偷走这个诊断方法:隔离每个操作,用不同数据量测试,找到哪个具体步骤在量化下崩溃。
反向传播梯度比前向传播激活更敏感这个洞察是可迁移的。
对transformer实践者:QK归一化成本低,即使不量化也能稳定训练。
如果你在大批次时看到训练不稳定,试试它。
“每步token数”框架在量化之外也有用。
任何随批次大小复合的数值不稳定性(梯度裁剪、学习率调优)都可以通过改变每步token数来调试,而不是只独立改变批次大小或序列长度。