Paper: 2608.07435 Authors: Zixuan Lan, Luzhe Sun, Matthew R. Walter, Jiawei Zhou Categories: cs.AI, cs.CL, cs.CV
The Gap
Here’s the structural problem in VLM evaluation right now: models ship every few weeks, benchmarks take a year. The result is a permanent lag where nobody can say precisely what a new model is bad at, only that it scores well on things built for its predecessors.
The prior art splits into two camps, and both hit a wall. The collect-and-annotate camp (VQAv2, GQA, MMBench, MMMU, and the long tail of “MM-something” suites) harvests real images and pays humans to label them. Real images are trustworthy, but you cannot *order a specific failure condition from the world — if you want a photo of a wooden lightbulb, you have to wait for someone to make one. And the moment a suite is public, it saturates and leaks into training data. The synthetic-and-controlled camp (CLEVR-style scene graphs, Winoground, and counterfactual probes like the “Whoops!” style commonsense-violation sets) buys control at the cost of narrowness: hand-authored templates, a fixed rendering domain, and no way to regenerate the test once models catch up.
There’s a third failure mode nobody solves well: a good stress-test sample has to satisfy three constraints simultaneously — it must instantiate the controlled condition, remain unambiguously answerable by a human, and actually be hard for current models. Satisfying all three by hand is expensive, which is exactly why stress tests stay small and stale. SABRE’s bet is that this is a pipeline problem, not a dataset problem.
[Problem]  VLMs ship monthly; hand-built benchmarks take a year
           and saturate on release
                |
                v
[Assumption] "Hard sample" is a *specifiable* object:
             condition + answerability + model-difficulty
             can each be enforced by a separate stage
                |
                v
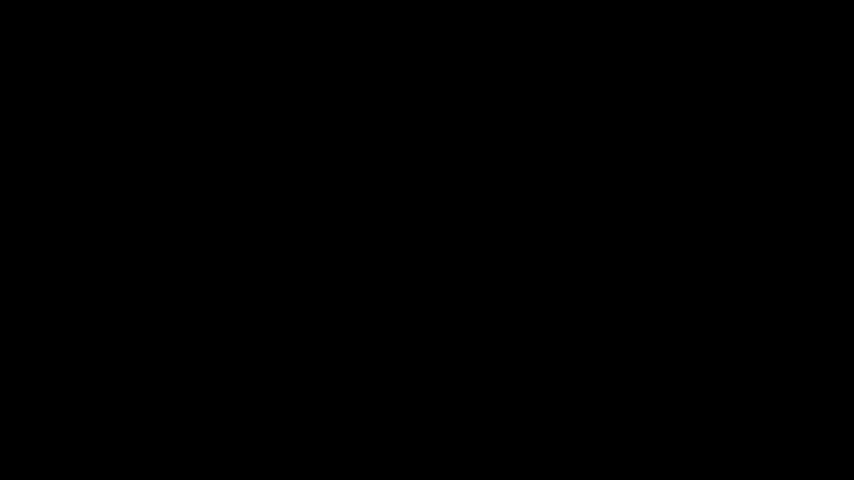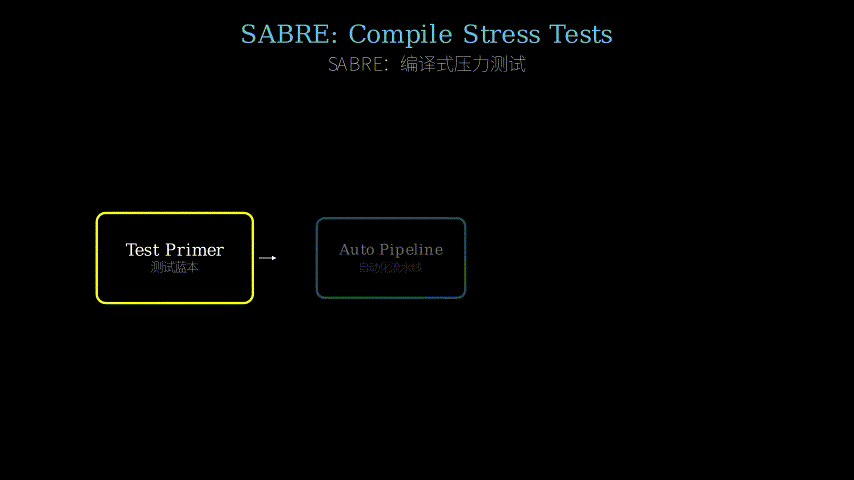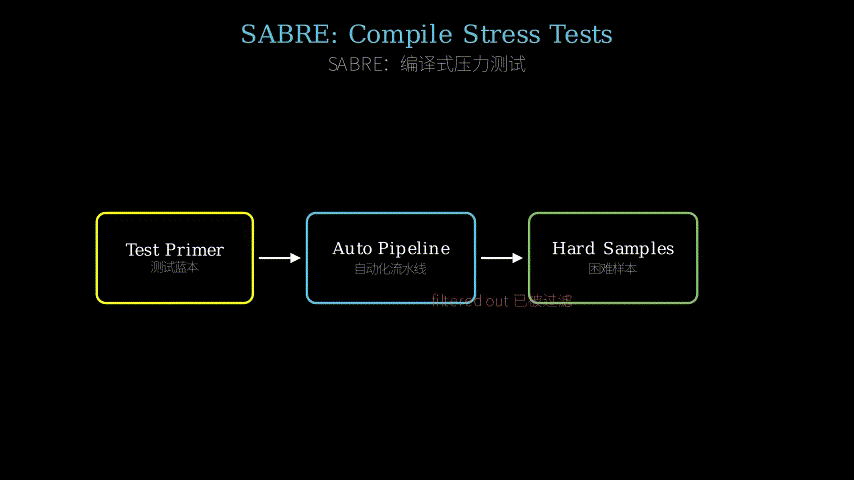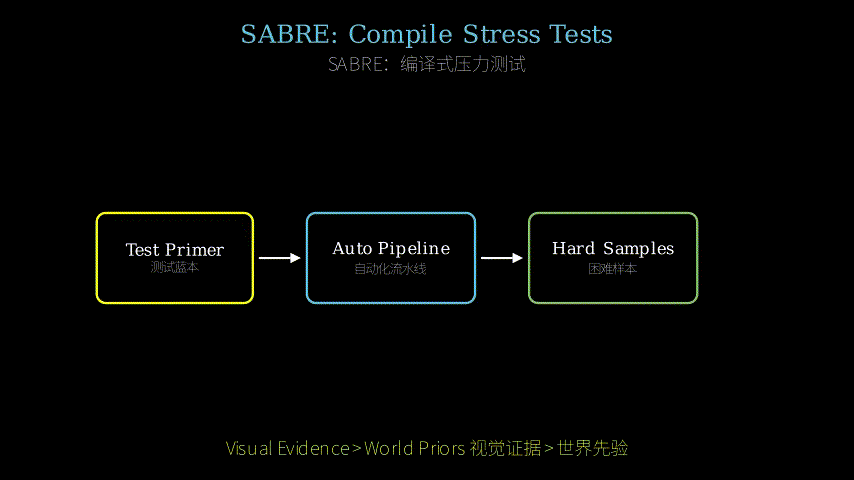
[Method]   Test Primer (Markdown) > structured spec > image
           gen/edit > QA pair > auto-filter against a live
           Filtering VLM > thin human verify + local repair
                |
                v
[Evidence] SABRE-Prior: 600 images / 1,000 questions, 4 axes
           6 VLMs score 17.8% .. 31.3% (mean 22.6)
           real-image Attribute control is comparably hard
           Counting + Spatial pilots reuse the same pipeline
                |
                v
[Conclusion] Ship the *generator*, not the benchmark:
             rewrite the Primer and refresh when models improve
The Increment
One sentence: Before, a VLM stress test was an artifact you built once and watched decay; after, it’s the *output of a program you can re-run against whatever model is current, with the test-design intent living in a human-readable Markdown file.
Core Mechanism
The entry point is the Test Primer: a Markdown document containing a Task Design (prose describing what cognitive failure you’re hunting) and a Data Schema (the slots that define one sample). This is the only artifact a researcher writes by hand. It’s deliberately a document rather than code, because the thing you’re specifying — “a familiar scene containing an entity that doesn’t belong” — is easier to state in English than in a config format.
That Primer gets expanded into structured specifications: concrete slot-fillings like *scene = kitchen counter, anomalous entity = zebra, question axis = context or object = banana, counterfactual material = glass. Each spec then drives image production, either full generation or targeted editing of a real photo, and a paired question-answer whose correct answer is pinned to the violated property. Notice the design choice here: the answer is derived from the spec, not read off the image. That’s what makes automated ground truth possible at all — and also what makes the human verification stage non-optional, since the generator doesn’t always render what the spec asked for.
Then two filters in series. First, automated difficulty filtering: a Filtering VLM answers every candidate, and anything it gets right is discarded. This is the stage that mechanizes “must challenge current models” — the constraint that historically required a human to guess what’s hard. Second, human review, but a deliberately thin one: verify the sample is genuinely answerable, correct the annotation if the render drifted from the spec, or apply *localized image repair to fix a bad region rather than throwing the whole sample away. That repair option is the quiet efficiency win — generation is cheap but not free, and salvaging a 90%-correct image beats resampling.
 Test Primer  (human-written Markdown)
   [ Task Design ]  +  [ Data Schema ]
              |
              v
   +--------------------------------+
   | Spec Synthesis                 |  fill the schema:
   |  scene / entity / attribute /  |  "kitchen + zebra"
   |  expected vs. violated value   |  "banana, material=glass"
   +--------------------------------+  "chair, legs=5"
              |
       +------+------+
       v             v
  [ generate ]   [ edit real image ]
       |             |
       +------+------+
              v
   [ QA writer ]  question + answer keyed to the violation
              |
              v
   +--------------------------------+
   | Filtering VLM                  |
   |   solved?  --- yes ---> discard
   +--------------------------------+
              | no
              v
   +--------------------------------+
   | Human review (thin layer)      |
   |  answerable? -- no --> drop    |
   |  label drifted? --> correct    |
   |  bad region?  --> local repair |
   +--------------------------------+
              |
              v
   SABRE-Prior  |  -Counting  |  -Spatial
        ^                              |
        |                              v
        +---- rewrite Primer, re-run ---+
The metaphor: a vision-science lab that manufactures optical illusions. This one maps part-for-part, and it’s the same subject matter, which helps.
The Test Primer is the design brief a perception researcher writes: “I want stimuli where color constancy overrides the actual pixel values.” Vague to a machine, obvious to a colleague. Spec synthesis is the stimulus parameter sheet — the brief becomes concrete numbers and materials: this hue, this surround, this shape. Image generation and editing is the studio artist or renderer who physically builds each stimulus, and building from a parameter sheet means the “correct answer” is known from the blueprint rather than measured afterward.
The Filtering VLM is the pilot subject you screen against: you show every candidate illusion to one observer, and if they see straight through it, that stimulus is discarded — it isn’t an illusion, it’s just a picture. Only the ones that fool the pilot enter the study. Human review is the lab technician: confirming the stimulus is unambiguous to a careful observer (answerability), fixing the parameter sheet when the artist deviated (annotation correction), and airbrushing a rendering artifact instead of rebuilding the whole stimulus (localized repair). And the point of the whole facility is that when a new population of observers stops being fooled, you don’t commission a new lab — you edit the brief and print a new batch.
The metaphor also exposes the paper’s main vulnerability for free: your illusions are tuned to one pilot subject. Screen against a single observer and you may be collecting that observer’s idiosyncrasies rather than universal perceptual weaknesses. Hold that thought for the assessment.
Key Concepts
-
World priors (and why they’re not a bug): A VLM has seen millions of bananas, all yellow and soft. So “banana” in its representation is welded to “yellow, soft, organic.” That’s not a defect — it’s the compression that lets the model recognize a banana in bad lighting from a weird angle. The prior is doing real work 99% of the time. The failure appears only when the image *contradicts it: show a banana carved from glass and ask what it’s made of. A system that reads pixels says glass; a system that retrieves its expectation says fruit. SABRE-Prior is engineered entirely around forcing that fork, along four axes: Context (a zebra on a kitchen counter — the object is normal, the scene is wrong), Texture (the glass banana — the object is right, the material is wrong), Attribute (a chair with five legs — right object, wrong count of parts), and Language Elicitation (the question’s phrasing implies an answer the image doesn’t support, testing whether the language channel can bully the vision channel).
-
Adversarial filtering, and the selection bias it buys: The pipeline keeps only samples that a chosen VLM fails. This is a well-known trick (it’s how ANLI and Adversarial NLI-style datasets were built), and it’s genuinely the only cheap way to guarantee difficulty. But it changes what the resulting number means. A 22.6% accuracy on a filtered set is *not “VLMs are 22.6% good at trusting visual evidence.” It’s “on the slice of samples that survived one model’s competence filter, VLMs score 22.6%.” The absolute number is manufactured by construction; only the relative comparison across models, and the qualitative pattern of what survives, carries information. The paper is at least aware of this — hence the control.
-
The real-image control: The obvious objection to any synthetic stress test is “you’re not measuring prior-over-evidence, you’re measuring the model’s confusion at diffusion artifacts.” The paper’s answer is an Attribute subset built from *real photographs, reported as comparably difficult for the Filtering VLM. This is the single most important experiment in the paper, because it’s the only thing separating “we found a cognitive failure mode” from “we found an out-of-distribution rendering artifact.”
Framework Shift
Before (mainstream):              After (SABRE):

  crawl / license images            write Test Primer (Markdown)
         |                                    |
         v                                    v
  crowdworkers annotate              synthesize structured specs
         |                                    |
         v                                    v
  filter for quality                 generate / edit images
         |                                    |
         v                                    v
  [ FIXED BENCHMARK ]                auto-filter vs. LIVE model
         |                                    |
         v                                    v
  models saturate it                 thin human verify + repair
         |                                    |
         v                                    v
  paper: "we need a new one"         [ test set instance ]
         |                                    |
         v                                    ^
  restart, 12+ months           edit Primer, re-run <+
                                (days, not months)

  artifact has a shelf life         generator has no shelf life
  difficulty guessed by humans      difficulty enforced by a filter
  ground truth read off image       ground truth inherited from spec
One sentence: From *benchmark-as-dataset to benchmark-as-compiler, the core shift is that the durable deliverable stops being the samples and becomes the specification plus the process that renders it.
Expert Assessment
Problem choice: Real gap, and it’s the *right real gap. The evaluation-lag problem is felt by everyone training VLMs and addressed by almost nobody structurally — the field’s standard response to saturation is to write another static benchmark, which reproduces the problem on a delay. Framing “benchmark construction” as a reusable pipeline with a human-readable entry point is the correct abstraction, and it sits in the same intellectual lineage as adversarial dataset construction and DSPy-style “specify, don’t hand-build.” That said, the paper is arriving into a crowded moment: synthetic-data-for-evaluation is a busy area, and “world priors override visual evidence” has been probed before (Winoground for compositional binding, Whoops!-style sets for commonsense violation, the various counting-failure notes). The contribution isn’t the finding — it’s the machinery.
Method maturity: This is honest engineering rather than a clever insight, and I mean that as a mild compliment. The pipeline is a sensible composition of known parts: LLM slot-filling, image generation and inpainting, adversarial filtering, human-in-the-loop verification. No single stage is novel; the value is that someone actually wired them together and demonstrated cross-domain reuse. Two things bother me. First, the word “automated” is doing more work in the title than in the method — human review verifies validity, corrects annotations, *and performs image repair, which is three distinct human labor categories. Without per-stage human-cost numbers (how many candidates survive filtering? what fraction need repair? minutes per accepted sample?), the scalability claim is asserted rather than demonstrated. Second, a simpler baseline is being skipped: how much of SABRE-Prior could be built with template-based compositing — literally pasting segmented objects into mismatched scenes and recoloring textures? That’s crude, but it’s artifact-controlled and nearly free, and it would establish how much the generative machinery actually buys.
Experimental integrity: The scale is small — 600 images and 1,000 questions is a probe, not a benchmark, and the paper’s own framing (“not a single fixed benchmark”) is partly a hedge against that. Six models evaluated is adequate. The important issues are three. (1) Filter leakage: if the Filtering VLM is among the six evaluated models, its score is structurally depressed and non-comparable, and even if it isn’t, models sharing its family or training lineage will be unfairly penalized. Filtering against a single model is the design’s weakest joint; an ensemble filter or a leave-one-out protocol would have cost little and bought a lot. (2) No human ceiling in the abstract. If humans aren’t at or near 100% on these 1,000 questions, then “answerable” wasn’t enforced tightly enough and part of that 22.6% is ambiguity rather than model failure. This number is load-bearing for the entire paper and I’d want to see it in the first table. (3) The real-image control is the right idea but reported too thinly — “comparably difficult for the Filtering VLM” covers one axis (Attribute), one model, and one comparison. Extend it across all four axes and all six models and the paper’s central claim becomes hard to argue with. Leave it as is and a skeptical reviewer can still say “diffusion artifacts” and not be refuted.
On the headline numbers: 17.8%–31.3% looks alarming and shouldn’t be read as such. Filtered-to-be-hard sets produce low scores by construction, and the interesting content is the 13-point spread between best and worst model, plus whichever of the four axes proves hardest. A per-axis breakdown with error-mode taxonomy would be worth more than the aggregate.
Writing quality: The corner-cutting is visible in the abstract’s structure. Two-thirds of it describes SABRE-Prior — one instantiation — while the framework claim (“reusable framework rather than a single fixed benchmark”) gets one sentence at the end, and the Counting and Spatial pilots that would actually *substantiate generality get half a sentence as “pilots.” That’s backwards relative to the paper’s own thesis. If I could rewrite one section, it’d be whatever covers the pilots: promote them from footnote to evidence, report the diff between the three Primers, and show how much of the pipeline was untouched across domains. Reuse claims are cheap to make and cheap to demonstrate; showing “we changed 40 lines of Markdown and got a working spatial-reasoning stress test” would be the strongest paragraph in the paper. Second priority: a cost table. “Scalable” without dollars-and-minutes per accepted sample is a claim, not a result.
Verdict: weak accept — the framing is right and the pipeline is a genuinely reusable contribution, but single-model adversarial filtering, a thin real-image control, and no reported human ceiling leave the headline numbers interpretable in more than one way.
Takeaways
Things worth stealing, independent of whether you care about VLMs:
-
Ship the generator, not the dataset. If your evaluation target is a moving one, the durable artifact is the specification plus the rendering process. This transfers directly to agent evals, code benchmarks, and safety red-teaming — anywhere saturation is measured in months.
-
Split the three constraints of a hard sample across three stages. “Instantiates the condition” is handled by spec synthesis, “is answerable” by human review, “is hard” by adversarial filtering. Trying to satisfy all three in one authoring step is why hand-built stress tests are expensive. Decomposing them is the actual insight here, and it’s domain-agnostic.
-
Derive ground truth from the spec, not from the artifact. Because the spec says *material = glass before any pixels exist, labeling is free and the failure mode shifts from “wrong label” to “render didn’t match the spec” — which is detectable and repairable. Useful anywhere you generate evaluation data.
-
Localized repair over resampling. When generation is your bottleneck, salvaging near-misses beats rejecting them. Underused pattern in synthetic data pipelines generally.
-
A Markdown document as the API surface. The Test Primer being prose plus a schema, rather than code or YAML, is a real usability choice: the person with the research question can write it without touching the pipeline. Worth copying for any tool where intent is easier to state than to configure.
-
And the caution, which is the most transferable lesson of all: adversarially filtered scores are not absolute capability measurements. If you build an eval this way, report the human ceiling, filter against an ensemble, and treat cross-model *ranking rather than raw accuracy as your signal.
论文: 2608.07435 作者: Zixuan Lan, Luzhe Sun, Matthew R. Walter, Jiawei Zhou 分类: cs.AI, cs.CL, cs.CV
缺口
当下 VLM 评测有一个结构性矛盾:模型几周一迭代,基准要一年才做出来。
结果就是永久性的滞后——没人能精确说出新模型到底差在哪,只知道它在为上一代设计的题目上分数很高。
已有做法分两派,两派都撞墙了。
采集+标注派(VQAv2、GQA、MMBench、MMMU 以及一长串「MM-什么」套件)从真实图像里捞样本,再花钱雇人标注。
真实图像可信,但你没法向世界「下单」定制一个失效条件——想要一张木头做的灯泡的照片,你只能等有人真去做一个。
而且套件一公开就开始饱和、泄漏进训练数据。
合成+可控派(CLEVR 系的场景图、Winoground、以及 Whoops! 式的常识违背集)用控制力换来了狭窄:模板手写、渲染域固定,模型追上来之后没法重新生成。
还有第三个没人解决好的问题:一个合格的压力测试样本必须同时满足三个约束——落实受控条件、对人类仍然无歧义可答、并且对当前模型真的难。
三条靠人工同时满足代价极高,这正是压力测试总是又小又旧的原因。
SABRE 的赌注是:这是流水线问题,不是数据集问题。
[问题]   VLM 月月更新,手工基准做一年,且一发布就饱和
              |
              v
[假设]   "难样本"是可被*规约*的对象:
         受控条件 / 可答性 / 模型难度
         可以分别由三个独立环节强制保证
              |
              v
[方法]   测试底本(Markdown) > 结构化规格 > 图像生成或编辑
         > 问答对 > 用在线 Filtering VLM 自动过滤
         > 轻量人工校验 + 局部修补
              |
              v
[证据]   SABRE-Prior: 600 图 / 1000 问 / 4 个维度
         6 个 VLM 得分 17.8% .. 31.3% (均值 22.6)
         真实图像 Attribute 对照组同样困难
         Counting 与 Spatial 试点复用同一流水线
              |
              v
[结论]   交付*生成器*而非基准:
         改一份底本、重跑一次,就能刷新测试
增量
一句话: 以前 VLM 压力测试是一件做完就开始腐烂的成品;现在它是一段程序的输出,可以对着任何当下最新的模型重跑一遍,而测试设计意图存放在一份人类可读的 Markdown 里。
核心机制
入口是测试底本(Test Primer):一份 Markdown,包含任务设计(用散文描述你想猎捕的认知失效)和数据模式(定义一个样本需要哪些槽位)。
这是研究者唯一需要手写的东西。
它故意做成文档而不是代码,因为你要规约的东西——「一个熟悉场景里出现一个不该出现的实体」——用英文说比用配置格式写容易得多。
底本被展开成结构化规格:具体的槽位填充,比如 *场景=厨房台面,异常实体=斑马,提问维度=context,或者 对象=香蕉,反事实材质=玻璃。
每条规格驱动图像生产,可以是完整生成,也可以是对真实照片做定向编辑;再配一个问答对,正确答案锚定在被违背的那个属性上。
注意这里的设计选择:答案是从规格推导出来的,不是从图像上读出来的。
这才让自动化的 ground truth 成为可能——同时也让人工校验环节变成不可省略的,因为生成器并不总是画出规格要求的东西。
然后是串联的两道筛。
第一道是自动难度过滤:一个 Filtering VLM 回答每个候选样本,答对的直接丢弃。
这一步把「必须能挑战当前模型」这条约束机械化了——过去这条约束需要人去猜什么算难。
第二道是人工审核,但刻意做得很薄:确认样本真的可答;如果渲染偏离了规格就改标注;或者做局部图像修补,只修坏掉的那一块区域,而不是整张废掉。
这个修补选项是安静的效率红利——生成便宜但不免费,抢救一张 90% 正确的图比重新采样划算。
 测试底本 (人工撰写的 Markdown)
   [ 任务设计 ]  +  [ 数据模式 ]
              |
              v
   +--------------------------------+
   | 规格合成                        |  填槽:
   |  场景 / 实体 / 属性 /            |  "厨房 + 斑马"
   |  期望值 vs 违背值                |  "香蕉, 材质=玻璃"
   +--------------------------------+  "椅子, 腿数=5"
              |
       +------+------+
       v             v
   [ 生成图像 ]   [ 编辑真实图像 ]
       |             |
       +------+------+
              v
   [ 问答生成 ]  问题 + 锚定违背属性的答案
              |
              v
   +--------------------------------+
   | Filtering VLM                  |
   |   答对?  --- 是 ---> 丢弃
   +--------------------------------+
              | 否
              v
   +--------------------------------+
   | 人工审核 (薄薄一层)              |
   |  可答?     -- 否 --> 丢弃       |
   |  标注漂移? --------> 修正        |
   |  局部瑕疵? --------> 局部修补    |
   +--------------------------------+
              |
              v
   SABRE-Prior  |  -Counting  |  -Spatial
        ^                              |
        |                              v
        +---- 改底本, 重跑一遍 --------- +
核喻:一间批量制造视错觉的视觉科学实验室。
这个比喻能逐件对应,而且题材本身就是视觉,理解成本更低。
测试底本就是知觉研究者写的设计委托书:「我要一批刺激图,让颜色恒常性压过实际像素值。」——对机器含糊,对同行一目了然。
规格合成是刺激参数表:委托书变成具体的数字和材料,这个色调、这个环境色、这个形状。
图像生成与编辑是工作室的画师或渲染器,把每个刺激物真的做出来;而「按参数表施工」意味着正确答案在像素存在之前就已知,不需要事后测量。
Filtering VLM 是你用来预筛的先导被试:每个候选错觉先给这一位观察者看,如果他一眼看穿,这张就废掉——那不是错觉,那只是一张普通图片。
只有骗过先导被试的才进入正式实验。
人工审核是实验室技师:确认刺激物对认真的观察者无歧义(可答性)、画师跑偏时修正参数表(标注修正)、以及把渲染瑕疵喷修掉而不是整件重做(局部修补)。
整间实验室存在的意义在于:当新一批观察者不再被骗到时,你不需要重建一间实验室——你改改委托书,再印一批就行。
这个比喻还免费暴露了论文最大的软肋:你的错觉是针对一位先导被试调出来的。
只用一个观察者预筛,你可能收集到的是这位观察者的个人癖性,而不是普遍的知觉弱点。
这一点先记住,评审部分会用到。
关键概念
-
世界先验(以及它为什么不是 bug): 一个 VLM 见过几百万根香蕉,全是黄的、软的。所以「香蕉」在它的表示里和「黄色、柔软、有机物」焊在了一起。这不是缺陷,这是压缩——正是这种压缩让它能在糟糕光照下从奇怪角度认出香蕉。先验在 99% 的情况下都在干正经活。失效只在图像反驳先验时出现:给它一根玻璃雕的香蕉,问它是什么材质做的。读像素的系统说玻璃,检索期望的系统说水果。SABRE-Prior 整个就是围绕逼出这个岔口设计的,分四个维度:Context(厨房台面上的斑马——物体正常,场景不对)、Texture(玻璃香蕉——物体对,材质不对)、Attribute(五条腿的椅子——物体对,部件数不对)、Language Elicitation(问题的措辞暗示了一个图像不支持的答案,测试语言通道能不能压倒视觉通道)。
-
对抗式过滤,以及它买来的选择偏差: 流水线只保留某个 VLM 答错的样本。这是个成熟套路(ANLI 那批对抗式 NLI 数据集就这么建的),而且它确实是唯一廉价地保证难度的办法。但它改变了结果数字的含义。过滤后集合上的 22.6% 不是「VLM 在信任视觉证据这件事上只有 22.6% 的水平」,而是「在通过某一个模型能力筛的那个切片上,VLM 得 22.6%」。绝对数值是构造出来的;真正携带信息的只有模型之间的相对比较,以及「什么样本活了下来」这个定性模式。论文至少是意识到这点的——所以才有对照组。
-
真实图像对照组: 对任何合成压力测试最直接的质疑是「你测的不是先验压过证据,你测的是模型对扩散伪影的困惑」。论文的回答是一个用真实照片构建的 Attribute 子集,报告说对 Filtering VLM 同样困难。这是全文最重要的一个实验,因为它是唯一能把「我们发现了一种认知失效模式」和「我们发现了一种分布外渲染伪影」区分开的东西。
框架转变
之前 (主流做法):                  之后 (SABRE):

  爬取 / 授权图像                    撰写测试底本 (Markdown)
         |                                    |
         v                                    v
  众包标注                            合成结构化规格
         |                                    |
         v                                    v
  质量筛选                            生成 / 编辑图像
         |                                    |
         v                                    v
  [ 固定基准 ]                        对*在线*模型自动过滤
         |                                    |
         v                                    v
  模型把它刷饱和                       薄层人工校验 + 修补
         |                                    |
         v                                    v
  论文: "我们需要新基准"                [ 一个测试集实例 ]
         |                                    |
         v                                    ^
  重头再来, 12+ 个月            改底本, 重跑 <-+
                                (以天计, 不是以月计)

  成品有保质期                        生成器没有保质期
  难度靠人猜                          难度由过滤器强制
  ground truth 从图上读                ground truth 从规格继承
一句话: 从基准即数据集到基准即编译器,核心转变是:可长期交付的东西不再是样本,而是规格加上把规格渲染出来的那套流程。
专家评审
选题眼光: 真缺口,而且是对的那个真缺口。
评测滞后这个问题所有训 VLM 的人都在痛,却几乎没人从结构上解决——领域对饱和的标准反应是再写一个静态基准,而这只是把同样的问题延后重演一遍。
把「基准构建」抽象成一条带人类可读入口的可复用流水线,这个抽象层次是对的,和对抗式数据构建、DSPy 式的「写规格而非手搓」属于同一条智识脉络。
但论文进入的是一个拥挤的时刻:合成数据做评测已是热门方向,「世界先验压过视觉证据」也被探过(Winoground 查组合绑定,Whoops! 系查常识违背,各种计数失效的短文)。
贡献不在发现,在机器。
方法成熟度: 这是诚实的工程活,不是精巧的洞见——我这话算温和的褒奖。
流水线是已知零件的合理组合:LLM 填槽、图像生成与 inpainting、对抗式过滤、人在环校验。
没有哪一环是新的;价值在于有人真的把它们接起来,并演示了跨域复用。
有两点让我不舒服。
第一,「自动化」这个词在标题里干的活比在方法里多——人工审核要验证有效性、还要修正标注、还要做图像修补,这是三类不同的人力劳动。
没有分环节的人力成本数字(过滤后存活率多少?多少比例需要修补?每个可用样本平均几分钟?),可扩展性就是断言而非结果。
第二,有个更简单的基线被跳过了:SABRE-Prior 有多少能用模板式合成拼贴做出来——就是把分割出的物体贴进不匹配的场景、再改改颜色?
这很粗糙,但它伪影可控且几乎免费,能说清生成式机器到底额外买到了什么。
实验诚意: 规模偏小——600 图 1000 问是一次探针,不是一个基准;论文自己「不是单一固定基准」的框定,一部分就是对这点的对冲。
评了六个模型算够。
真正的问题有三个。
(1)过滤泄漏:如果 Filtering VLM 就在这六个被评模型里,它的分数被结构性压低、不可比;即使不在,与它同族或同训练血统的模型也会被不公平惩罚。用单一模型做过滤是整个设计最弱的关节;换成集成过滤或留一法协议,成本很低、收益很大。
(2)摘要里没有人类上限。如果人类在这 1000 题上不是接近 100%,那说明「可答性」没有被足够严格地强制,22.6% 里有一部分是歧义而非模型失效。这个数字对全文承重,我希望它出现在第一张表里。
(3)真实图像对照组想法对,但报告太薄——「对 Filtering VLM 同样困难」只覆盖了一个维度(Attribute)、一个模型、一次比较。把它扩展到四个维度、六个模型,论文的核心主张就很难反驳了;就这么放着,怀疑派仍然可以说「扩散伪影」而不被驳倒。
关于头条数字:17.8%–31.3% 看着骇人,但不该那么读。
被筛成难题的集合天然产生低分,真正有信息量的是最好与最差之间那 13 个点的差距,以及四个维度里哪个最难。
一张分维度拆解加错误模式分类表,比这个聚合数字值钱得多。
写作功力: 偷懒痕迹在摘要结构里就看得见。
三分之二的篇幅在描述 SABRE-Prior——一个实例化;而框架主张(「可复用框架而非单一固定基准」)只在最后拿到一句话,真正能支撑通用性的 Counting 和 Spatial 试点只得到半句「pilots」。
相对论文自己的论点,这是倒置的。
如果只能重写一节,我会重写讲试点的那部分:把它们从脚注升格为证据,报告三份底本之间的 diff,展示跨域时流水线有多少部分完全没动。
复用主张说起来便宜,演示起来也便宜;能写出「我们改了 40 行 Markdown,就得到一个能跑的空间推理压力测试」,那会是全文最强的一段。
第二优先级:一张成本表。
没有「每个可用样本几美元几分钟」,「可扩展」就只是主张,不是结果。
判决: 弱接收 — 框定是对的、流水线是真正可复用的贡献,但单模型对抗过滤、过薄的真实图像对照、以及缺失的人类上限,让头条数字留下了不止一种解读方式。
要点总结
不管你做不做 VLM,这些是值得偷的:
-
交付生成器,不交付数据集。 如果你的评测目标在移动,可长期持有的资产是规格加渲染流程。这一条能直接迁移到 agent 评测、代码基准、安全红队——任何饱和周期以月计的地方。
-
把「难样本」的三条约束拆到三个环节。 「落实受控条件」交给规格合成,「可答」交给人工校验,「够难」交给对抗过滤。想在一个撰写动作里同时满足三条,正是手工压力测试昂贵的原因。拆开它们才是这里真正的洞见,而且与领域无关。
-
ground truth 从规格推导,不从成品读取。 因为规格在任何像素存在之前就写着「材质=玻璃」,标注是免费的,失效模式从「标错了」变成「渲染没匹配规格」——后者可检测、可修补。任何生成评测数据的场景都能用。
-
局部修补优于重新采样。 当生成是你的瓶颈时,抢救接近合格的样本比丢弃它划算。这个模式在合成数据流水线里普遍被低估。
-
把 Markdown 文档当作 API 界面。 测试底本是散文加模式,而不是代码或 YAML,这是个实在的可用性选择:有研究问题的那个人不必碰流水线就能写。任何「意图比配置更容易表达」的工具都值得抄这一手。
-
以及最值得迁移的那条警告:对抗过滤后的分数不是绝对能力度量。如果你这样建评测,请报告人类上限、用集成而非单模型做过滤,并把跨模型排序而不是原始准确率当作你的信号。