Paper: 2605.00798 Authors: Arunabh Srivastava, Mohammad A., Khojastepour, Srimat Chakradhar, Sennur Ulukus Categories: cs.LG, cs.CL, cs.MA
The Gap
LLMs can generate impressive text, but they’re notoriously unreliable when you need them to follow a structured workflow. Prior work splits into two camps: end-to-end LLM execution (flexible but chaotic—the model drifts, hallucinates, or skips steps) and rigid symbolic planners (deterministic but brittle—can’t handle natural language ambiguity). Methods like ReAct and PlanGEN try to bridge this by having LLMs generate and execute plans, but they lack enforcement mechanisms. The model might claim it’s following step 3 while actually doing something from step 5, or it might satisfy the surface instruction while violating implicit constraints.
Problem: LLMs unreliable for structured workflows
    |
    v
Assumption: Need both NL flexibility AND execution determinism
    |
    v
Method: Agentic language with control flow + constraint validation
    |
    v
Evidence: Outperforms baselines on Natural-plan & SciBench
    |
    v
Conclusion: Explicit control + dynamic verification = reliable execution
The Increment
One sentence: Before RunAgent, you chose between flexible-but-unreliable LLM execution or rigid-but-brittle symbolic planning; after RunAgent, you get natural language expressiveness with programming-like execution guarantees through explicit control constructs and constraint validation.
Core Mechanism
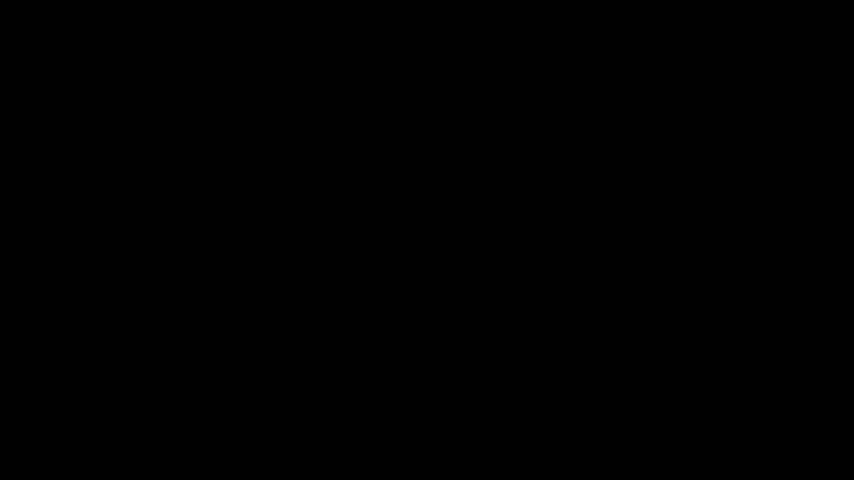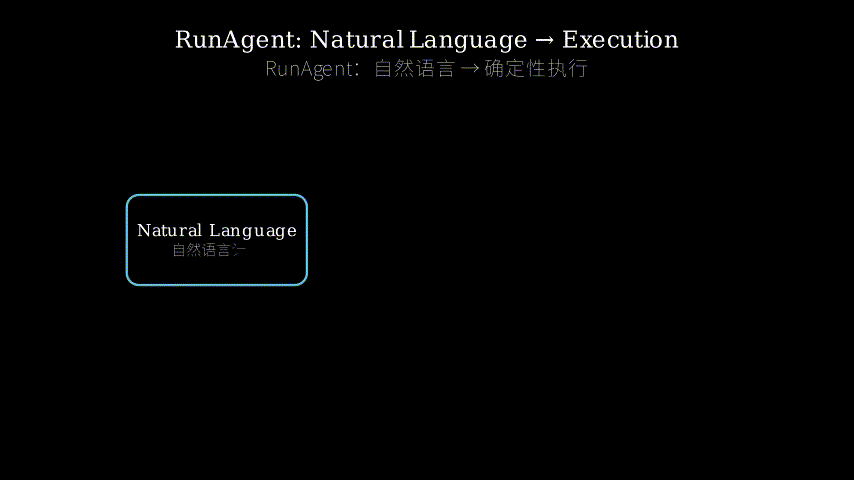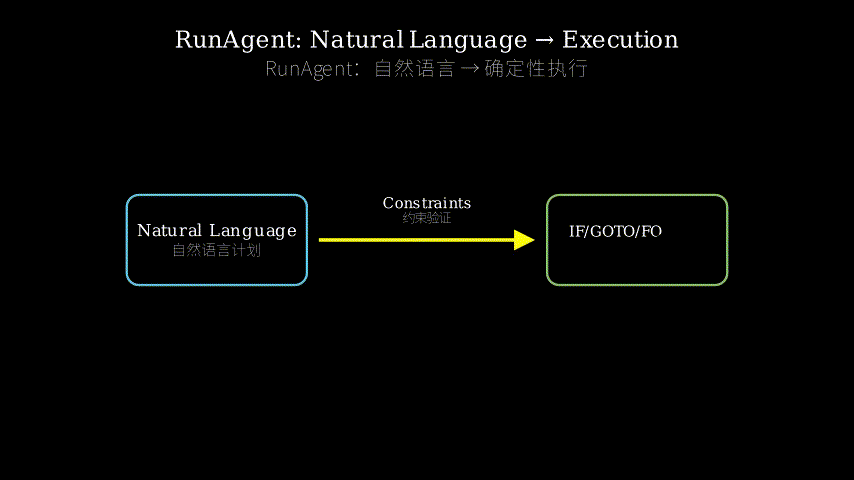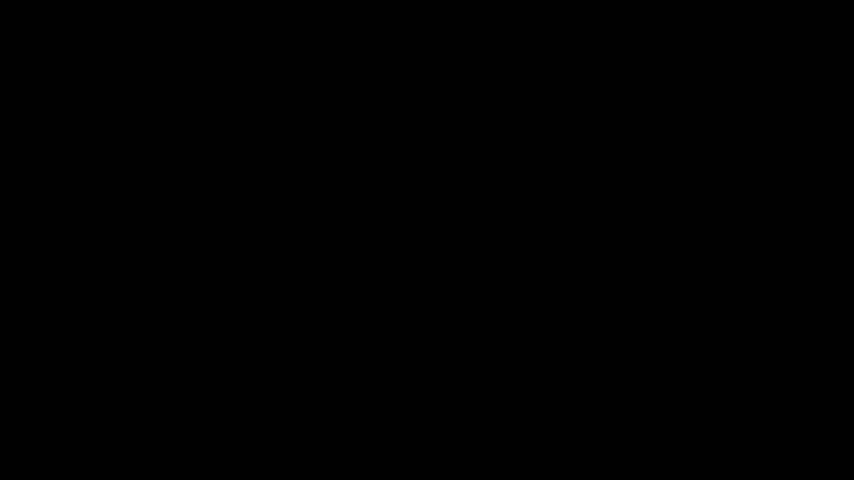
RunAgent introduces an “agentic language” that sits between natural language and code. Each plan step gets annotated with explicit control flow constructs (IF, GOTO, FORALL) that dictate execution order, plus rubrics that define success criteria. The system has three execution modes: LLM-based reasoning for open-ended tasks, tool usage for structured operations, and code generation for computational work. At each step, RunAgent doesn’t just check if the output looks right—it autonomously derives constraints from the task description and validates them.
The execution flow works like this: parse the plan into steps with control annotations, execute the current step using the appropriate mode, validate both the step’s explicit rubric and derived constraints, then use the control construct to determine the next step. If validation fails, error correction kicks in—the system analyzes what went wrong and retries with corrections. Context management runs throughout: only information relevant to the current step gets retained, preventing the context window from becoming a junkyard of irrelevant history.
Think of RunAgent as a stage director for an improv troupe. The script (plan) is written in natural language with stage directions (control constructs). Each actor (execution mode—LLM, tool, code) has different strengths. The director (RunAgent) reads the stage directions to know who performs next, watches the performance (step execution), checks both the explicit cues (rubrics) and implicit blocking rules (derived constraints), and decides if the scene worked. If an actor flubs their line, the director stops, explains what went wrong, and they retry. Meanwhile, the prompter (context manager) only feeds actors the lines relevant to their current scene, not the entire play. The control constructs are load-bearing: without GOTO, you can’t loop back to retry; without IF, you can’t branch based on validation results; without FORALL, you can’t iterate over collections. The metaphor maps directly: stage directions → control flow, performance → execution, blocking rules → constraints, scene transitions → step sequencing.
Key Concepts
-
Agentic Language: Imagine you’re giving instructions to a very literal assistant. “Handle the customer complaints” is too vague—they might ignore urgent ones or spend all day on spam. You need to be more specific: “FOR each complaint in the queue, IF priority is high, THEN respond within 1 hour, ELSE respond within 24 hours.” That’s what agentic language does—it adds programming-like control flow (loops, conditionals, jumps) to natural language instructions. The “agentic” part means each step can still be executed by an intelligent agent (LLM, tool, code), not just dumb string matching. So you get the expressiveness of “handle complaints naturally” with the precision of “follow this exact workflow.”
-
Constraint Derivation: Most systems only check what you explicitly tell them to check. If your rubric says “output should be a valid email,” they verify the format but miss that you sent it to the wrong person. RunAgent reads the task description (“notify the customer about their order”) and the current instance (“order #1234 for [email protected]”) and derives implicit constraints: the email must mention order #1234, must be sent to [email protected], must contain order status. These aren’t in the rubric—the system infers them from context. It’s like a good assistant who doesn’t just follow the checklist but understands what you’re actually trying to accomplish.
-
Dynamic Mode Selection: Different tasks need different tools. Answering “What’s the capital of France?” needs LLM reasoning. Querying a database needs tool usage. Computing a statistical correlation needs code execution. RunAgent doesn’t force everything through one interface—it looks at each step and picks the appropriate mode. If the step says “analyze the sentiment,” it uses the LLM. If it says “fetch user records where age
> 30,” it generates a database query. If it says “calculate the standard deviation,” it writes Python code. The selection happens automatically based on the step’s structure and requirements, not manual annotation.
Framework Shift
Before (mainstream approach):        After (RunAgent):

Plan: NL text blob                   Plan: NL + control constructs
  |                                    |
  v                                    v
LLM executes freeform                Step-by-step executor
  |                                    |
  v                                    +---> Mode selector
Check output format                    |       |
  |                                    |       +-> LLM / Tool / Code
  v                                    |
Done (hope it worked)                  +---> Constraint validator
                                       |       |
                                       |       +-> Rubric check
                                       |       +-> Derived constraints
                                       |
                                       +---> Control flow interpreter
                                       |       |
                                       |       +-> IF / GOTO / FORALL
                                       |
                                       +---> Error correction
                                       |
                                       v
                                     Next step (guaranteed valid)
From implicit execution to explicit control, the core shift is making the workflow structure first-class and enforceable rather than hoping the LLM remembers to follow it.
Expert Assessment
Problem choice: Real gap. The “LLMs are unreliable for structured tasks” problem is well-documented and matters for practical deployment. This isn’t manufactured—anyone who’s tried to build an LLM-based workflow system has hit this wall. The positioning is smart: they’re not trying to replace LLMs or symbolic planners, just bridge them.
Method maturity: Solid engineering with one clever insight (constraint derivation) and a lot of good systems work (mode selection, context filtering, error correction). The agentic language isn’t revolutionary—it’s basically adding control flow annotations to natural language—but it’s the right level of structure. The constraint derivation is genuinely useful: most systems only validate what you explicitly specify, and inferring implicit constraints from task descriptions is a practical win. The dynamic mode selection feels obvious in hindsight but is often overlooked. No major red flags about simpler approaches being ignored.
Experimental integrity: Baselines are reasonable (GPT-4, Claude, PlanGEN). The datasets (Natural-plan, SciBench) are appropriate for testing structured execution. The paper claims “outperforms” but doesn’t show failure case analysis—I’d want to see where RunAgent still fails and why. The constraint derivation mechanism is described conceptually but the paper doesn’t detail how it actually works (is it prompt engineering? a separate model? rule-based?). That’s a significant omission for reproducibility. The context filtering claims efficiency gains but doesn’t show ablations proving it’s necessary.
Writing quality: The abstract and intro are clear. The method section is where it gets hand-wavy—“autonomously derives constraints” needs a concrete algorithm, not just a description. The evaluation section shows results but doesn’t dig into why RunAgent wins or where it struggles. If they rewrote Section 3 (Method) with pseudocode and concrete examples of constraint derivation, the paper would jump from “interesting idea” to “reproducible system.”
Verdict: weak accept — Addresses a real problem with a practical solution, but the constraint derivation mechanism needs more detail for the contribution to be fully evaluated and reproduced.
Takeaways
The constraint derivation idea is immediately useful: when building any LLM-based system, don’t just validate explicit outputs—infer what must be true from the task context and check those too. The mode selection pattern (LLM for reasoning, tools for structured ops, code for computation) is a good architectural template for multi-capability systems. The context filtering approach (only retain relevant history per step) is a simple way to manage context bloat in long workflows. The agentic language concept—adding minimal control flow to natural language—is a sweet spot between full programming and pure NL that could apply to other domains like robotic task planning or business process automation.
论文: 2605.00798 作者: Arunabh Srivastava, Mohammad A., Khojastepour, Srimat Chakradhar, Sennur Ulukus 分类: cs.LG, cs.CL, cs.MA
缺口
大语言模型能生成漂亮的文本,但在需要遵循结构化工作流时出了名的不可靠。
此前的工作分成两派:端到端的LLM执行(灵活但混乱——模型会漂移、幻觉或跳步)和刚性的符号规划器(确定但脆弱——无法处理自然语言的歧义)。
ReAct和PlanGEN这类方法试图通过让LLM生成并执行计划来架桥,但它们缺乏强制机制。
模型可能声称在执行第3步,实际却在做第5步的事,或者满足了表面指令却违反了隐含约束。
问题:LLM在结构化工作流中不可靠
    |
    v
假设:需要自然语言的灵活性和执行的确定性
    |
    v
方法:带控制流的智能体语言 + 约束验证
    |
    v
证据:在Natural-plan和SciBench上超越基线
    |
    v
结论:显式控制 + 动态验证 = 可靠执行
增量
一句话:RunAgent之前,你要在灵活但不可靠的LLM执行和刚性但脆弱的符号规划之间二选一;RunAgent之后,你通过显式控制结构和约束验证,获得了自然语言的表达力和编程般的执行保证。
核心机制
RunAgent引入了一种”智能体语言”,介于自然语言和代码之间。
每个计划步骤都带有显式的控制流结构(IF、GOTO、FORALL)来规定执行顺序,加上定义成功标准的评分规则。
系统有三种执行模式:用于开放式任务的LLM推理、用于结构化操作的工具使用、用于计算工作的代码生成。
在每一步,RunAgent不只是检查输出看起来对不对——它从任务描述中自主推导约束并验证它们。
执行流程是这样的:把计划解析成带控制注释的步骤,用合适的模式执行当前步骤,验证步骤的显式评分规则和推导出的约束,然后用控制结构决定下一步。
如果验证失败,错误纠正机制启动——系统分析哪里出错了,带着修正重试。
上下文管理贯穿始终:只保留与当前步骤相关的信息,防止上下文窗口变成无关历史的垃圾场。
把RunAgent想象成即兴剧团的舞台导演。
剧本(计划)用自然语言写成,带有舞台指示(控制结构)。
每个演员(执行模式——LLM、工具、代码)有不同的强项。
导演(RunAgent)读舞台指示知道谁接下来表演,看表演(步骤执行),检查显式提示(评分规则)和隐含的走位规则(推导约束),决定这场戏是否成功。
如果演员说错台词,导演叫停,解释哪里错了,然后重来。
与此同时,提词员(上下文管理器)只给演员喂当前场景相关的台词,而不是整部戏。
控制结构是承重的:没有GOTO,你无法循环回去重试;没有IF,你无法根据验证结果分支;没有FORALL,你无法遍历集合。
这个比喻直接映射:舞台指示→控制流,表演→执行,走位规则→约束,场景转换→步骤排序。
关键概念
- 智能体语言:想象你在给一个非常字面的助手下指令。
“处理客户投诉”太模糊——他们可能忽略紧急的或整天处理垃圾邮件。
你需要更具体:“对队列中的每个投诉,如果优先级高,则在1小时内回复,否则在24小时内回复。
“这就是智能体语言做的事——它给自然语言指令加上类似编程的控制流(循环、条件、跳转)。
“智能体”的部分意味着每一步仍然可以由智能代理(LLM、工具、代码)执行,而不只是愚蠢的字符串匹配。
所以你既得到了”自然地处理投诉”的表达力,又得到了”遵循这个精确工作流”的精确性。
- 约束推导:大多数系统只检查你明确告诉它们检查的东西。
如果你的评分规则说”输出应该是有效邮箱”,它们验证格式但漏掉了你发给了错误的人。
RunAgent读取任务描述(“通知客户他们的订单”)和当前实例(“订单#1234给[email protected]”),推导出隐含约束:邮件必须提到订单#1234,必须发给[email protected],必须包含订单状态。
这些不在评分规则里——系统从上下文推断它们。
就像一个好助手,不只是照着清单走,而是理解你真正想完成什么。
- 动态模式选择:不同任务需要不同工具。
回答”法国首都是什么?
“需要LLM推理。
查询数据库需要工具使用。
计算统计相关性需要代码执行。
RunAgent不强迫所有东西走一个接口——它看每一步,选合适的模式。
如果步骤说”分析情感”,它用LLM。
如果说”获取年龄>30的用户记录”,它生成数据库查询。
如果说”计算标准差”,它写Python代码。
选择根据步骤的结构和需求自动发生,不需要手动标注。
框架转变
之前(主流方法):                之后(RunAgent):

计划:自然语言文本块              计划:自然语言 + 控制结构
  |                                 |
  v                                 v
LLM自由形式执行                   逐步执行器
  |                                 |
  v                                 +---> 模式选择器
检查输出格式                        |       |
  |                                 |       +-> LLM / 工具 / 代码
  v                                 |
完成(希望成功了)                  +---> 约束验证器
                                    |       |
                                    |       +-> 评分规则检查
                                    |       +-> 推导约束
                                    |
                                    +---> 控制流解释器
                                    |       |
                                    |       +-> IF / GOTO / FORALL
                                    |
                                    +---> 错误纠正
                                    |
                                    v
                                  下一步(保证有效)
从隐式执行到显式控制,核心转变是让工作流结构成为一等公民且可强制执行,而不是希望LLM记得遵循它。
专家评审
选题眼光:真实缺口。
“LLM在结构化任务中不可靠”这个问题有充分记录,对实际部署很重要。
这不是人造的——任何试图构建基于LLM的工作流系统的人都碰过这堵墙。
定位聪明:他们不是要替代LLM或符号规划器,只是架桥。
方法成熟度:扎实的工程加一个巧妙洞见(约束推导)和大量好的系统工作(模式选择、上下文过滤、错误纠正)。
智能体语言不是革命性的——基本上就是给自然语言加控制流注释——但它是合适的结构层次。
约束推导确实有用:大多数系统只验证你明确指定的,从任务描述推断隐含约束是实用的胜利。
动态模式选择事后看来显而易见,但常被忽略。
没有关于更简单方法被忽略的重大危险信号。
实验诚意:基线合理(GPT-4、Claude、PlanGEN)。
数据集(Natural-plan、SciBench)适合测试结构化执行。
论文声称”超越”但没展示失败案例分析——我想看RunAgent在哪里仍然失败以及为什么。
约束推导机制在概念上描述了,但论文没详细说明它实际如何工作(是提示工程?
单独的模型?
基于规则?
)。
这对可复现性是重大遗漏。
上下文过滤声称效率提升但没展示消融实验证明它是必要的。
写作功力:摘要和引言清晰。
方法部分开始含糊——“自主推导约束”需要具体算法,不只是描述。
评估部分展示结果但没深挖为什么RunAgent赢或在哪里挣扎。
如果他们用伪代码和约束推导的具体例子重写第3节(方法),论文会从”有趣想法”跃升到”可复现系统”。
判决:弱接收 — 用实用方案解决真实问题,但约束推导机制需要更多细节才能充分评估和复现贡献。
要点总结
约束推导的想法立即可用:构建任何基于LLM的系统时,不只验证显式输出——从任务上下文推断什么必须为真并检查它们。
模式选择模式(LLM用于推理,工具用于结构化操作,代码用于计算)是多能力系统的好架构模板。
上下文过滤方法(每步只保留相关历史)是管理长工作流中上下文膨胀的简单方式。
智能体语言概念——给自然语言加最小控制流——是完整编程和纯自然语言之间的甜蜜点,可应用于机器人任务规划或业务流程自动化等其他领域。