Paper: 2608.06347 Authors: Xinye Wang, Junxiao Liu, Shujian Huang Categories: cs.CL
The Gap
Every frontier reasoning model has the same embarrassing asymmetry: ask it a competition math problem in English and it thinks carefully; ask the same problem in Swahili or Bengali and the chain of thought gets shorter, shakier, and often silently switches languages mid-solution. The capability exists inside the model; it just doesn’t route through non-English inputs reliably.
The prior work splits into three families. Translate-then-SFT takes English chains of thought, machine-translates them, and fine-tunes — cheap, but off-policy: the student learns to imitate sequences it would never have produced itself, so at inference time it walks off the training distribution immediately (classic exposure bias). English-pivot prompting tells the model to translate internally, reason in English, then answer — this works, but it pushes cost to test time and never actually internalizes target-language reasoning. On-policy self-distillation (OPSD) and its relatives (GKD-style objectives, self-distillation with privileged context) fixed the distribution mismatch: let the *student generate the rollout in the target language, then have a teacher — often the same model given privileged information like an English reference solution — score every token of that rollout and minimize a token-level divergence. Dense supervision, on-policy samples, no reward-model needed.
The gap this paper names is narrow but real: the OPSD objective weights every token equally. A multilingual rollout is mostly surface realization — inflections, connectives, particles, target-language phrasing of arithmetic that is already decided. A small minority of tokens are places where the reasoning actually *forks: choosing to set up an equation rather than enumerate cases, deciding to check a boundary condition, updating a running quantity from the problem’s givens. Flat KL spends most of its gradient budget teaching the student to say things in the target language a particular way, when the thing that fails to transfer is the decision-making. The paper’s move: define those forks operationally, and reweight distillation toward them.
[Problem] LLM reasons well in EN, degrades in low-resource langs
     |
     v
[Prior art]
   translate + SFT ..... off-policy, exposure bias
   EN-pivot prompting .. test-time cost, nothing internalized
   OPSD / GKD .......... on-policy, dense token KL  <-- best so far
                         BUT every token weighted equally
     |
     v
[Assumption] target-lang reasoning = surface text + reasoning pivots
             cross-lingual transfer bottlenecks at the pivots only
     |
     v
[Method] RP-OPSD
   two matched teacher views: (q, y_<t) vs (q, EN_ref, y_<t)
   their divergence == pivot score
   pivot score -> weights privileged KL + gates reference anchoring
     |
     v
[Evidence] math reasoning, 17 languages, several difficulty tiers
   > strong multilingual baselines and > OPSD variants
   learned weights land on control tokens + state-update tokens
     |
     v
[Conclusion] *where* you apply privileged supervision matters
             more than how much of it you apply
The Increment
One sentence: Before, on-policy self-distillation for multilingual reasoning spread privileged supervision uniformly across a rollout; after, you get a cheap, label-free way to *locate the tokens where privileged information actually changes the decision, and to spend your distillation budget there.
Core Mechanism
Start with the OPSD skeleton. The student, prompted with a problem in some target language, samples a full solution. That rollout is fixed, and a teacher is asked to evaluate it token by token. The trick that makes this “privileged” is that the teacher is given something the student does not have at inference time — here, an English reference solution to the same problem. The teacher’s next-token distribution is therefore better-informed than anything the student could produce on its own, and minimizing divergence to it is a form of supervision that’s denser than a scalar reward and better-aligned than translated ground truth.
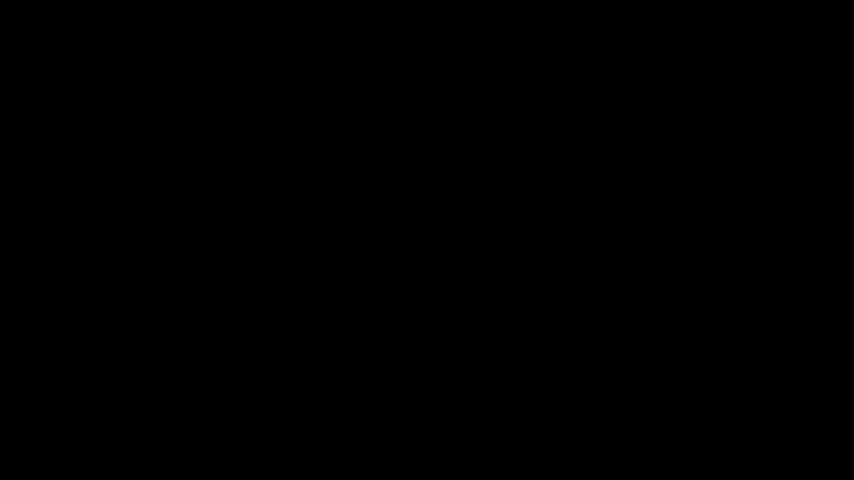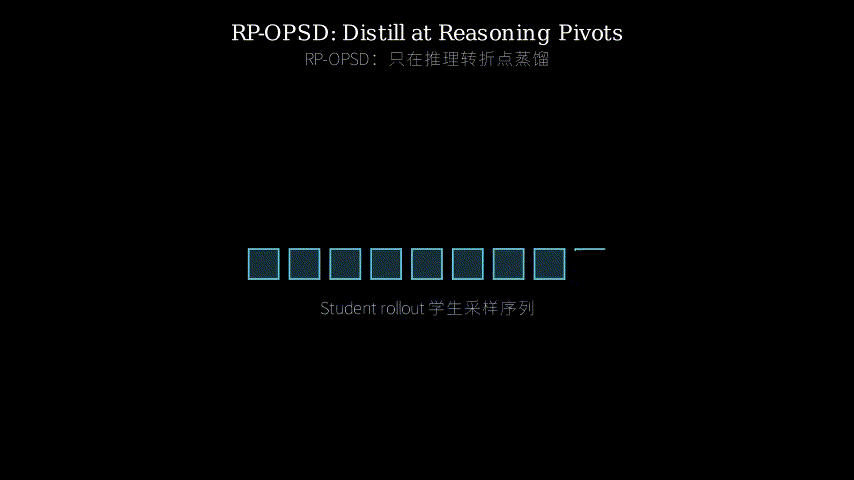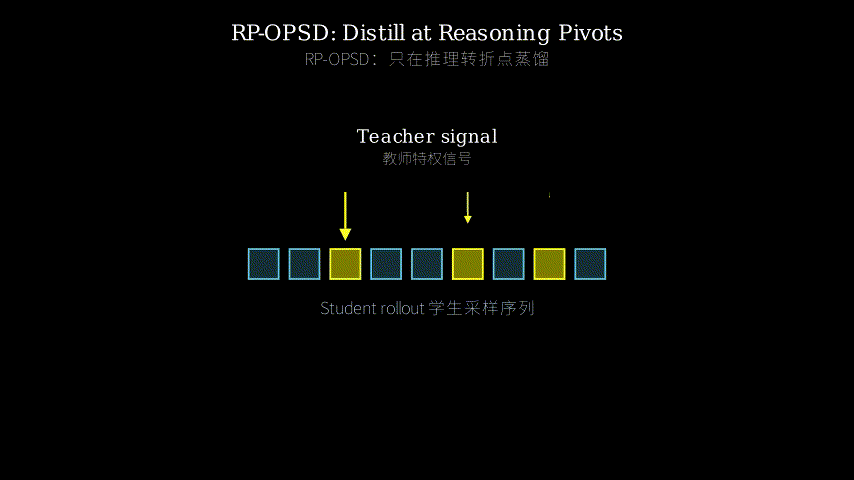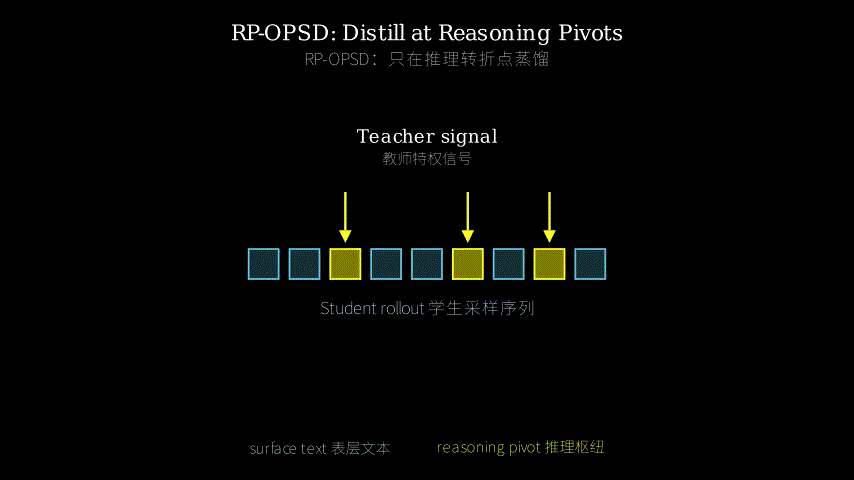
RP-OPSD’s addition is a second, matched teacher pass. Same teacher, same student rollout prefix, same problem — the only difference is whether the English reference solution is in context. Run both. At each position you now have two distributions: p_B (with reference) and p_A (without). Where they agree, the English reference told the teacher nothing it didn’t already know at that position — that position is surface realization, grammatical bookkeeping, or an already-determined continuation. Where they diverge sharply, the reference is actively steering the next decision. That divergence is the paper’s operational proxy for a reasoning pivot. It’s a counterfactual measure of privileged-information influence, computed with two forward passes and no gradients.
The pivot score then does two jobs. First, it weights the privileged distillation term: the token-level divergence between the student and the privileged teacher is scaled up at pivots and down elsewhere, so the gradient concentrates on reasoning-control decisions instead of morphology. Second, it gates reference anchoring: rather than conditioning on the English reference uniformly (which risks the student learning to lean on a crutch that vanishes at test time, or worse, drifting toward English surface form), the reference’s influence is admitted mainly at the positions where it’s diagnostically relevant. The reported analysis is the sanity check that this is doing what it says: high weights fall on reasoning-control tokens (“so”, “instead”, “check whether”) and on problem-conditioned state updates (the numbers and operations that carry the problem’s specifics forward), while tokens that mainly serve surface realization get downweighted.
        problem q (target language)
                 |
                 v
        +--------------------+
        |  STUDENT (policy)  |  sample rollout y = y_1 .. y_T
        +--------------------+  on-policy, in target language
                 |
     +-----------+-----------------------+
     |                                   |
     v                                   v
+------------------+            +----------------------+
| TEACHER view A   |            | TEACHER view B       |
| ctx: q , y_<t    |            | ctx: q , EN_ref, y_<t|
| (no privilege)   |            | (privileged)         |
+------------------+            +----------------------+
     | p_A( . | y_<t )                   | p_B( . | y_<t )
     +-----------------+-----------------+
                       v
            d_t = D( p_B  ||  p_A )        .. pivot score
            "how much did the EN reference
             change the teacher's decision here?"
                       |
                       v
            w_t = f( d_t )   normalize / sharpen
                       |
     +-----------------+-----------------------+
     v                                         v
 sum_t  w_t * KL( p_B || student )      reference anchoring
 privileged distillation,               gated by w_t : pull in
 concentrated at pivots                 EN evidence only where
                                        it is decision-relevant
                       |
                       v
                 update student
The metaphor: a driving lesson in an unfamiliar city, with two navigators.
The student is the one driving, and the route is the chain of thought. Riding along are two navigators who are the same person in two states of knowledge: one has already seen the route map (the English reference solution), one is navigating blind from the destination address alone. You ask both, continuously, “what now?”
On a long straight boulevard, both say “keep going.” The map added nothing — this stretch is surface realization: you still have to steer, stay in lane, signal, but no decision is being made. Then you reach an unmarked five-way intersection. The blind navigator shrugs and guesses straight; the map-holder says “hard left, then immediately right.” That disagreement is the signal. It doesn’t just mean “here is a hard spot” — it means here is a spot where privileged knowledge changes the outcome, which is exactly the definition of a place worth teaching.
RP-OPSD is the driving instructor who keeps hands off the wheel on the boulevard and grabs it firmly at the intersections. And the gating of reference anchoring is the instructor’s rule about the map itself: the learner doesn’t get to drive with the map open on their lap the whole way — that just trains map-reading, not city knowledge. The map comes out at intersections. Everywhere else, drive.
The metaphor is also where the method’s limitation is visible: the divergence detector fires at intersections, but it cannot tell an intersection where the map’s advice is correct from one where the map is being idiosyncratic. Disagreement is not the same as being right.
Key Concepts
-
On-policy self-distillation: Two words doing separate work. “On-policy” means the training sequences come from the student’s own sampling, not from a fixed dataset — so the student is corrected on the mistakes it actually makes, in the regions of sequence space it actually visits. Think of grading a student’s own essay drafts rather than making them copy out a model essay: the model essay never tells them what to do after *their bad third paragraph. “Self” means the teacher is the same network (or a lightly modified version of it), so no bigger model is required; the teacher’s advantage comes purely from being given extra context. Together: the model generates, then a better-informed version of itself annotates every token of that generation.
-
Privileged information: Anything the teacher sees that the student won’t have at test time. Here it’s an English reference solution. The point isn’t to copy the reference — the student must eventually solve problems with no reference at all — but to use it as a temporary oracle that makes the teacher’s token-level distributions trustworthy. It’s the same logic as a chess coach reviewing your game with an engine open: you can’t bring the engine to the tournament, but the annotations it enables are what you learn from.
-
Reasoning pivot (and how to find one without labels): A pivot is a token where the trajectory of the reasoning is chosen rather than merely expressed. “Let” in “Let x be the number of…” is a pivot; the word after it usually isn’t. The genuinely nice idea in this paper is the detection method: don’t try to define pivots linguistically or annotate them by hand. Instead run the same model twice, differing only by the presence of privileged information, and measure where the two next-token distributions pull apart. Positions where the answer key changes your prediction *are the positions where thinking happens. Note the relationship to a nearby idea in RL-for-reasoning — high-entropy “forking tokens” — but with an important difference: entropy measures the model’s own uncertainty, whereas this measures the value of the answer. A token can be uncertain for boring reasons (three synonyms are equally fine), and this proxy correctly ignores those.
Framework Shift
Before (OPSD / GKD, mainstream):        After (RP-OPSD):

 student rollout                         student rollout
  y1  y2  y3  y4  y5  y6                  y1  y2  y3  y4  y5  y6
   |   |   |   |   |   |                   .   .   |   .   |   .
   v   v   v   v   v   v                   .   .   v   .   v   .
  [1] [1] [1] [1] [1] [1]                 .1  .1  .9  .2  .8  .1
   \   |   |   |   |   /                       \      |     /
    \  |   |   |   |  /                         \     |    /
     ONE teacher pass                            +--------+
     ( q + EN_ref )                              | weights from
          |                                      | DIFF of TWO
          v                                      | teacher views |
    flat token-level KL                          +---------------+
    budget spent mostly on                             |
    surface realization                                v
                                              KL concentrated on
                                              decision points only

 supervision = "match the teacher"     supervision = "match the teacher
                                        where the answer key mattered"
From uniform token-level imitation to counterfactually-localized supervision, the core shift is treating the influence of privileged information as the importance signal, so the objective learns reasoning control rather than target-language phrasing.
Expert Assessment
(Caveat: this reading is based on the abstract and stated analysis; I haven’t audited the tables, so the experimental critique below is about what the design must show, not a claim about what the numbers are.)
Problem choice: A real gap, honestly framed, and small. Multilingual reasoning transfer is a genuine deficiency with practical stakes, and “flat KL wastes capacity on surface form” is the kind of criticism that is obviously true once stated. But the field has been converging on token-importance weighting from several directions at once — entropy-based token selection in RLVR, token-level credit assignment in preference optimization, selective/focal knowledge distillation — so this sits comfortably inside a trend rather than opening a direction. The contribution is a well-chosen importance signal for a specific setting, not a new paradigm.
Method maturity: Clever, and cheap in the right way. The two-matched-views diff is the good idea here: it’s essentially context-attribution (the same machinery behind context-aware/contrastive decoding) repurposed as a supervision weight, it requires no annotation, no extra model, no reward function, and the second forward pass is inference-only and cacheable. It also has a clean semantics — “where does the answer key change the prediction” — that entropy-based selection lacks. The worry is the number of unpinned knobs: which divergence, how to sharpen or normalize the weights, what threshold gates reference anchoring. Papers in this genre usually have one temperature-like hyperparameter doing a lot of undisclosed load-bearing, and the abstract gives no reason to think this one is exempt. Simpler things a skeptic will demand: entropy-based weighting, teacher-confidence weighting, and plain top-k selection of the highest-divergence tokens (does soft weighting beat a hard mask?). If a hard mask on the top 20% works as well, the story gets simpler and stronger, not weaker.
Experimental integrity: 17 languages across multiple difficulty tiers is the right breadth, and including difficulty stratification is a good instinct — multilingual math benchmarks like MGSM are close to saturated on strong models, and the interesting transfer failures live on harder problems. Two things I’d check first. (1) Compute parity: RP-OPSD needs two teacher forward passes per rollout. Does the OPSD baseline get an equivalent budget (more rollouts, more steps)? Absent that control, part of the gain is just extra compute. (2) The pivot definition is validated by *inspection — “the weights land on tokens that look like reasoning control” — which is suggestive but circular. The convincing experiment is causal: corrupt or resample the top-scored pivot tokens versus an equal number of low-scored tokens and show accuracy collapses only in the former case. If that ablation is in the paper, it’s the most important table; if it’s absent, the central concept remains an appealing story rather than a demonstrated fact.
Writing quality: The abstract carries a typo in a load-bearing phrase (“problem-condistioned”), which is a small tell about polish. More substantively, the abstract does the classic thing of describing the mechanism at a level (“using the distributional shift … as an operational proxy to guide privileged distillation and reference anchoring”) where you can’t tell whether “reference anchoring” is a second loss term, a context-construction rule, or a decoding constraint. The section that would elevate the paper is a tightened method presentation with a fully worked single-example walkthrough — one target-language rollout, per-token pivot scores printed, the resulting weights, and where the two teacher views disagreed. That would convert the paper from “plausible reweighting scheme” to “here is a phenomenon you can now see.”
Verdict: weak accept — a well-motivated and cheap importance signal with a clean interpretation, but the pivot construct needs causal validation and the compute-matched comparison against vanilla OPSD to be more than a tuning win.
Takeaways
The transferable idea is not multilingual and not distillation-specific: diff two forward passes that differ only in privileged context, and you get a free, per-token map of where that context mattered. That trick generalizes anywhere you have side information the deployed model won’t have.
Concrete places to reuse it:
- RAG training and evaluation: run the model with and without the retrieved passage. The high-divergence tokens are the ones actually grounded in the document; everything else is parametric or filler. Use it to weight a grounding loss, or as a cheap faithfulness/attribution metric with no attention heuristics involved.
- Hint- or solution-conditioned training: for any task where you have gold outputs but want the model to work without them, this localizes which steps the gold answer is really contributing — turning a whole-sequence signal into per-token targets.
- Annotation and data curation triage: the pivot score identifies the small fraction of positions in a long generation where a human reviewer’s attention is worth spending. Same for synthetic data filtering: rollouts with no high-divergence positions are probably trivial and contribute little.
- Tool-use and agent trajectories: run with and without the tool output in context. Where they diverge is where the tool result was decision-relevant, which is exactly what you want to reward or supervise instead of the surrounding boilerplate.
The framing worth stealing: importance should be defined by counterfactual influence of information, not by the model’s own uncertainty. Entropy tells you the model is unsure; this tells you the answer would have changed things. Those are different sets of tokens, and the second one is usually the one you want.
What not to over-read: divergence marks decision points, not correct decisions. If your privileged source is noisy — a mediocre reference solution, a wrong retrieved passage — this method will confidently concentrate your gradient on exactly the places where it’s wrong.
论文: 2608.06347 作者: Xinye Wang, Junxiao Liu, Shujian Huang 分类: cs.CL
缺口
所有前沿推理模型都有一个尴尬的不对称:同一道竞赛数学题,用英文问它会认真思考、反复检查;换成斯瓦希里语或孟加拉语,思维链会突然变短、变脆,甚至中途悄悄切回英文。
能力就在模型里面,只是非英语输入这条通路不可靠。
已有工作大致三派。
翻译 + SFT:把英文思维链机器翻译过来做微调。便宜,但是离策略(off-policy)——学生在模仿自己根本不会产生的序列,推理时一旦偏离就没有救援信号,典型的曝光偏差。
英语枢轴提示:让模型先内部翻译成英文、用英文推理、再输出目标语言答案。有效,但把成本推到测试时,而且目标语言推理能力从未被真正内化。
在策略自蒸馏(OPSD)及其变体(GKD 类目标、带特权上下文的自蒸馏)解决了分布错配:让学生自己用目标语言采样一条 rollout,再由一个教师——通常就是同一个模型,只是额外获得了英文参考解这类特权信息——对这条 rollout 的每一个 token 打分,最小化 token 级散度。
监督稠密、样本在策略、不需要奖励模型。
这篇论文指出的缺口很窄但真实:OPSD 的目标函数对每个 token 一视同仁。
一条多语言 rollout 里绝大多数 token 是表层实现——词形变化、连接词、语气助词、把已经算好的算式换个说法。
真正让推理分岔的 token 只占少数:决定列方程而不是枚举、决定去验一下边界条件、把题目给定的量往前推进一步。
平坦的 KL 把梯度预算主要花在教学生”用目标语言这么说”,而迁移真正失败的地方是”决策怎么做”。
论文的动作:给这些分岔点一个可操作的定义,然后把蒸馏重心搬过去。
[问题] 英文推理很好,低资源语言明显退化
     |
     v
[已有方法]
   翻译 + SFT ........ 离策略,曝光偏差
   英语枢轴提示 ...... 测试时开销,能力没内化
   OPSD / GKD ........ 在策略,token 级稠密 KL  <-- 目前最好
                       但每个 token 权重相同
     |
     v
[假设] 目标语言推理 = 表层文本 + 推理枢纽
       跨语言迁移的瓶颈只在枢纽处
     |
     v
[方法] RP-OPSD
   两个配对教师视图: (q, y_<t) vs (q, 英文参考解, y_<t)
   两者的分布偏移 == 枢纽分数
   枢纽分数 -> 加权特权蒸馏 + 门控参考锚定
     |
     v
[证据] 数学推理,17 种语言,多个难度层级
   优于强多语言基线,优于各 OPSD 变体
   学到的权重落在控制类 token + 状态更新 token 上
     |
     v
[结论] 特权监督"用在哪里"比"用了多少"更重要
增量
一句话:以前多语言推理的在策略自蒸馏把特权监督均匀铺在整条 rollout 上;现在有了一个便宜、无需标注的方法,能定位出”特权信息真的改变了决策”的那些 token,并把蒸馏预算集中过去。
核心机制
先看 OPSD 的骨架。
学生拿到目标语言的题目,采样出一条完整解答。
这条 rollout 固定下来,交给教师逐 token 评估。
让它成为”特权”蒸馏的关键是:教师被喂了学生在推理时拿不到的东西——这里是同题的英文参考解。
于是教师的下一 token 分布比学生自己能产生的任何东西都更靠谱,向它靠拢就是一种比标量奖励更稠密、比翻译答案更对齐的监督。
RP-OPSD 加的东西是第二次配对教师前向。
同一个教师、同一条学生 rollout 前缀、同一道题,唯一区别是上下文里有没有英文参考解。
两次都跑。
于是每个位置你有两个分布:p_B(有参考)和 p_A(无参考)。
两者一致的地方,说明英文参考解在这个位置没告诉教师任何新东西——那就是表层实现、语法记账,或者续写已经被前文定死了。
两者剧烈分歧的地方,说明参考解正在主动引导下一个决策。
这个分歧量就是论文对推理枢纽的可操作代理。
它本质上是”特权信息影响力”的反事实度量,两次前向、不需要梯度。
枢纽分数干两件事。
第一,给特权蒸馏项加权:学生与特权教师之间的 token 级散度,在枢纽处放大、在别处压低,梯度因此集中在推理控制决策而不是词形变化上。
第二,门控参考锚定:不是全程都均匀地条件在英文参考解上(那有两个风险——学生学会依赖一个测试时会消失的拐杖,或者被英文表层形式带跑),而是只在诊断相关的位置放行参考的影响。
论文报告的分析就是对这件事的自检:高权重落在推理控制类 token(“所以”、“改成”、“检查是否”)和题目条件下的状态更新(把题目具体数值和运算往前推的那些 token)上,而主要服务表层实现的 token 被显著下调。
        题目 q(目标语言)
                 |
                 v
        +--------------------+
        |   学生(策略)      |  采样 rollout y = y_1 .. y_T
        +--------------------+  在策略,目标语言
                 |
     +-----------+-----------------------+
     |                                   |
     v                                   v
+------------------+            +----------------------+
| 教师 视图 A       |            | 教师 视图 B           |
| 上下文: q , y_<t  |            | 上下文: q, EN参考, y_<t|
| (无特权)        |            | (有特权)             |
+------------------+            +----------------------+
     | p_A( . | y_<t )                   | p_B( . | y_<t )
     +-----------------+-----------------+
                       v
            d_t = D( p_B  ||  p_A )        .. 枢纽分数
            "英文参考解在这里
              把教师的决策改了多少?"
                       |
                       v
            w_t = f( d_t )   归一化 / 锐化
                       |
     +-----------------+-----------------------+
     v                                         v
 sum_t  w_t * KL( p_B || 学生 )          参考锚定
 特权蒸馏,                              由 w_t 门控: 只在
 集中于枢纽处                            决策相关处引入
                                         英文证据
                       |
                       v
                   更新学生
核喻:在陌生城市上驾驶课,副驾坐着两个领航员。
学生是那个开车的人,路线就是思维链。
副驾上的两个领航员其实是同一个人的两种知识状态:一个已经看过路线图(英文参考解),一个只知道目的地地址、蒙着走。
你不停地问两人:“现在怎么走?”
在长长的直路上,两人都说”继续开”。
地图没有提供任何增量——这一段是表层实现:你依然要打方向、保持车道、打转向灯,但没有任何决策在发生。
然后你开到一个没有标识的五岔路口。
蒙着走的那位耸耸肩猜”直行”,看过地图的那位说”急左,然后立刻右转”。
这个分歧就是信号。
它不只是说”这里难”,它说的是”这里是特权知识会改变结果的地方”——而这恰好就是”值得教”的定义。
RP-OPSD 就是那位教练:在直路上完全放手,在岔路口牢牢抓住方向盘。
而参考锚定的门控,对应教练关于地图本身的规矩:不许学员全程把地图摊在腿上开——那只会练出读图能力,练不出对这座城市的认知。
地图只在岔路口拿出来,其余时间就是开车。
这个比喻同时也照出了方法的局限:分歧探测器会在岔路口响,但它分不清”地图的建议是对的岔路口”和”地图在这里犯了个人怪癖的岔路口”。
分歧不等于正确。
关键概念
-
在策略自蒸馏:两个词各干各的活。“在策略”指训练序列来自学生自己的采样,而不是固定数据集——于是学生是在自己真正会犯的错误上、在自己真正会走到的序列空间区域里被纠正。类比:批改学生自己写的作文草稿,而不是让他抄一篇范文;范文永远不会告诉他”在你那个糟糕的第三段之后该怎么救”。“自”指教师就是同一个网络(或它的轻度变体),不需要更大的模型;教师的优势完全来自被多给了上下文。合起来就是:模型自己生成,然后一个信息更充分版本的自己,逐 token 批注这段生成。
-
特权信息:教师看得到、而学生在测试时看不到的任何东西。这里是英文参考解。重点不是抄参考解——学生最终必须在完全没有参考的情况下解题——而是把它当成一个临时神谕,让教师的 token 级分布变得可信。逻辑和棋手复盘时开着引擎一样:引擎不能带进比赛,但引擎让你写下的那些批注,才是你真正学到的东西。
-
推理枢纽(以及如何无标注地找到它):枢纽是”推理走向被选定、而不只是被表达”的那个 token。“设”在”设 x 为满足……的个数”里是枢纽,紧跟其后的那个词通常不是。这篇论文真正漂亮的地方是检测方式:不去从语言学上定义枢纽,也不去人工标注。而是让同一个模型跑两遍,唯一差别是有没有特权信息,然后测量两个下一 token 分布在哪里拉开。答案会改变你预测的位置,就是思考发生的位置。 顺带提一句它和 RLVR 里”高熵分叉 token”这一相邻想法的关系,但差别很重要:熵度量的是模型自己的不确定性,这里度量的是答案的价值。一个 token 可能因为无聊的理由而不确定(三个同义词都行),而这个代理会正确地忽略它。
框架转变
之前(OPSD / GKD,主流):              之后(RP-OPSD):

 学生 rollout                           学生 rollout
  y1  y2  y3  y4  y5  y6                 y1  y2  y3  y4  y5  y6
   |   |   |   |   |   |                  .   .   |   .   |   .
   v   v   v   v   v   v                  .   .   v   .   v   .
  [1] [1] [1] [1] [1] [1]                .1  .1  .9  .2  .8  .1
   \   |   |   |   |   /                      \      |     /
    \  |   |   |   |  /                        \     |    /
     一次教师前向                                +---------------+
     ( q + 英文参考 )                            | 权重来自两个   |
          |                                     | 教师视图之差   |
          v                                     +---------------+
    平坦 token 级 KL                                   |
    预算大部分花在                                      v
    表层实现上                                  KL 只集中在
                                                决策点上

 监督 = "对齐教师"                     监督 = "在答案真的起作用的
                                        地方对齐教师"
一句话:从”均匀的 token 级模仿”到”反事实定位的监督”,核心转变是把特权信息的影响力当作重要性信号,于是目标函数学的是推理控制,而不是目标语言的措辞。
专家评审
(前提说明:以下评价基于摘要与其中陈述的分析,我没有核对表格,因此实验部分的批评是”这个设计必须证明什么”,而不是对具体数字的断言。)
选题眼光:真缺口,表述诚实,但很窄。
多语言推理迁移是有实际利害的真实短板,“平坦 KL 把容量浪费在表层形式上”这种批评一说出来就显然成立。
但这个领域正从好几个方向同时收敛到 token 重要性加权——RLVR 里的熵筛选、偏好优化里的 token 级信用分配、选择性/focal 蒸馏。
所以它舒服地待在一个趋势内部,而不是开辟方向。
贡献是”为一个特定场景挑了一个好的重要性信号”,不是新范式。
方法成熟度:巧劲,而且省在了对的地方。
两视图取差是这里的好想法:它本质上是上下文归因(和 context-aware / 对比解码背后是同一套机器),被改用来当监督权重;不需要标注、不需要额外模型、不需要奖励函数,第二次前向是纯推理且可缓存。
它还有一个熵筛选所缺乏的干净语义——“答案在哪里改变了预测”。
我担心的是没被钉住的旋钮数量:用哪个散度、权重怎么锐化和归一化、参考锚定用什么阈值门控。
这一类论文通常有一个类似温度的超参在暗中承担大量重量,摘要没给出理由让人相信这篇是例外。
一个挑剔的审稿人会要求的更简方案:熵加权、教师置信度加权,以及对最高分歧 token 做朴素 top-k 硬掩码(软加权真的比硬掩码好吗?)。
如果对 top 20% 做硬掩码效果相当,故事会变得更简单也更强,不是更弱。
实验诚意:17 种语言的覆盖面是对的,做难度分层是个好直觉——MGSM 这类多语言数学基准在强模型上已接近饱和,有意思的迁移失败都在更难的题上。
我会先查两件事。
(1)算力对齐:RP-OPSD 每条 rollout 需要两次教师前向。OPSD 基线有没有拿到等价预算(更多 rollout、更多步数)?没有这个对照,一部分增益就只是多花的算力。
(2)枢纽定义是靠观察验证的——“权重落在看起来像推理控制的 token 上”——这有启发性但循环。
真正能说服人的是因果实验:破坏或重采样得分最高的枢纽 token,与同等数量的低分 token 对照,证明只有前者会让准确率崩掉。
这个消融如果在论文里,它就是最重要的一张表;如果没有,核心概念就仍然是一个动听的故事,而不是被证实的事实。
写作功力:摘要在一个承重短语上有拼写错误(“problem-condistioned”),是关于打磨程度的小信号。
更实质的是,摘要用了那种经典的中间层描述方式(“用有/无英文参考解的配对教师视图之间的分布偏移作为可操作代理,来引导特权蒸馏与参考锚定”),读者根本判断不出”参考锚定”到底是第二个损失项、一条上下文构造规则,还是一个解码约束。
能让整篇升一档的是重写方法部分并配一个完整的单例走查:一条目标语言 rollout,逐 token 打印枢纽分数、由此得到的权重、以及两个教师视图究竟在哪里分歧。
那会把论文从”一个看起来合理的重加权方案”变成”这是一个你现在能亲眼看到的现象”。
判决:弱接收 —— 动机良好、成本低廉、语义干净的重要性信号,但枢纽这个构念需要因果验证,与原版 OPSD 的对比也需要算力对齐,否则难以排除”调参胜利”的解释。
要点总结
可迁移的想法既不关于多语言,也不限于蒸馏:让两次前向只在”是否给了特权上下文”上不同,取其差,你就免费得到一张逐 token 的”该上下文在哪里起了作用”的地图。
只要你手上有部署时拿不到的旁路信息,这个套路就能用。
具体可复用的地方:
- RAG 的训练与评估:带检索段落跑一次、不带跑一次。高分歧的 token 才是真正基于文档的部分,其余是参数记忆或填充词。可以用来加权 grounding 损失,也可以当成一个廉价的忠实度/归因指标,完全不涉及注意力启发式。
- 带提示或带答案条件的训练:任何”有金标输出、但希望模型不看金标也能做”的任务,这套方法能定位金标究竟在哪几步真的做了贡献——把整序列信号变成逐 token 目标。
- 标注与数据筛选的分诊:枢纽分数能指出长生成里那一小撮值得人类审阅者花注意力的位置。合成数据过滤同理:整条 rollout 都没有高分歧位置的,大概是琐碎题,贡献有限。
- 工具调用与 agent 轨迹:把工具返回值放进/移出上下文各跑一次。分歧处就是工具结果对决策起作用的地方,而这正是你想去奖励或监督的部分,而不是周围那一堆样板文字。
值得偷走的框架:重要性应该由信息的反事实影响力定义,而不是模型自身的不确定性。
熵告诉你”模型不确定”,这个方法告诉你”答案会改变结果”。
这是两批不同的 token,而通常你想要的是第二批。
不要过度解读的地方:分歧标记的是决策点,不是正确的决策。
如果你的特权来源本身有噪声——一份平庸的参考解、一段检索错的段落——这个方法会自信地把你的梯度集中到它正好错了的那些位置上。