Paper: 2603.22016 Authors: Xinyan Wang, Xiaogeng Liu, Chaowei Xiao Categories: cs.LG, cs.AI, cs.CL
The Gap
Large Reasoning Models (LRMs) like o1 generate long Chain-of-Thought traces to solve hard problems. They work, but they don’t know when to stop. Even after finding the right answer, they keep reasoning, adding tokens that cost money and time, sometimes even drifting away from the correct solution. Existing fixes either retrain the entire model (expensive, slow) or use hand-crafted rules like “stop after N tokens” (brittle, doesn’t capture real overthinking patterns). No one treats this as a real-time monitoring problem where you watch the model think and intervene the moment it starts spinning its wheels.
Problem: LRMs overthink after solving
         |
         v
Gap: No real-time detection method
     (only post-hoc or rule-based)
         |
         v
Assumption: Overthinking has detectable
            patterns in hidden states
         |
         v
Method: Lightweight detector head
        monitors token stream, triggers
        early exit when overthinking starts
         |
         v
Evidence: 47.2% shorter responses,
          93.51% accuracy maintained
         |
         v
Conclusion: Streaming detection works
            for overthinking mitigation
The Increment
One sentence: Before ROM, you either retrained models or used dumb heuristics to stop overthinking; after ROM, you attach a lightweight detector that watches the model think in real time and cuts it off at the right moment.
Core Mechanism
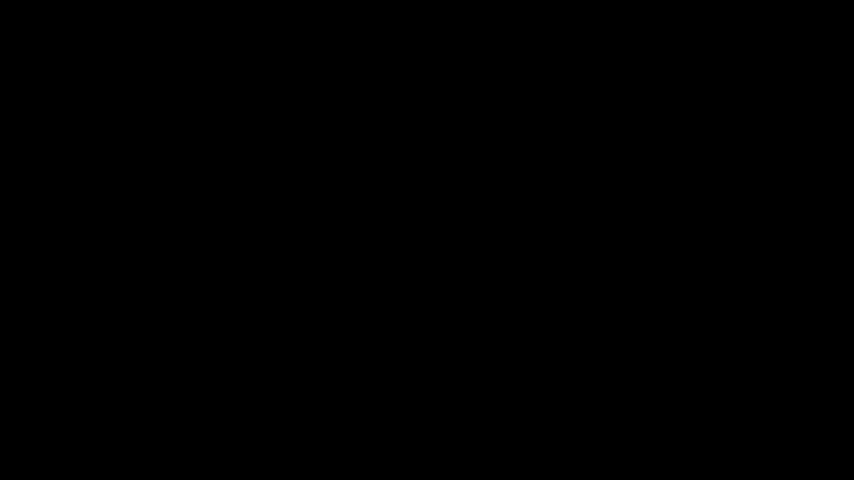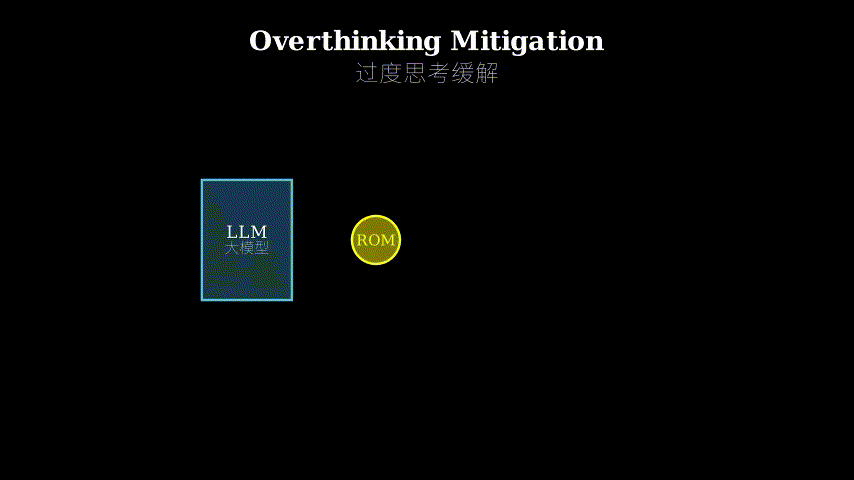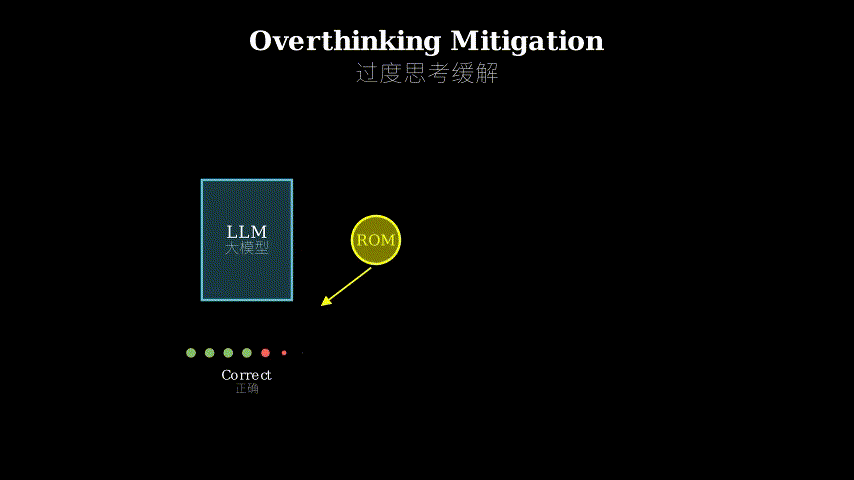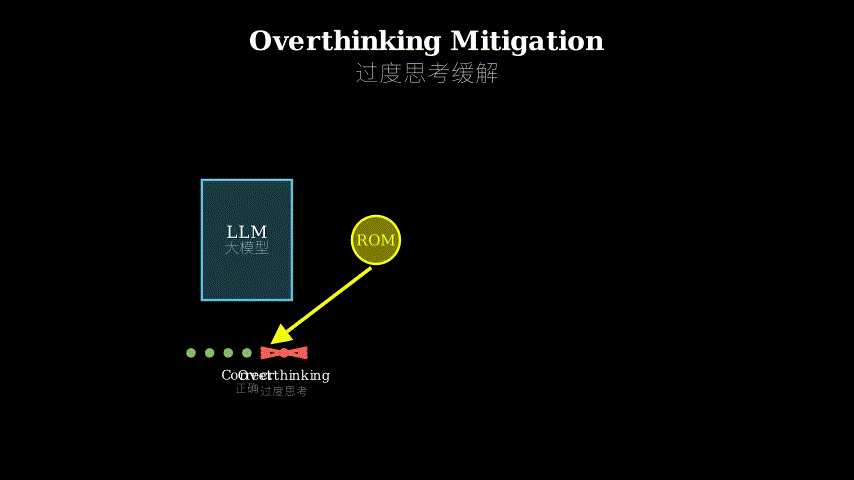
ROM has three parts working together. First, a detection head—a small neural network—sits on top of the frozen LRM’s late-layer hidden states. It doesn’t change the base model at all. Second, during inference, this head reads every token as it’s generated and outputs a probability: “Is the model overthinking right now?” Third, when that probability crosses a threshold, ROM immediately triggers the model to jump to its final answer format, skipping the rest of the reasoning trace.
Training this detector requires knowing where overthinking starts. ROM uses a clever labeling strategy: for each reasoning trace, it finds the point where the model first reaches the correct answer (verified by checking intermediate solutions). Everything before that point is “productive reasoning” (label: 0). Everything after is “overthinking” (label: 1). To make the detector robust, ROM also augments training data by mixing traces from different problems, preventing it from memorizing problem-specific patterns.
Frozen LRM Backbone
    |
    | (hidden states at layer L-k)
    v
[Detection Head]  <-- lightweight classifier
    |
    | (per-token probability)
    v
Decision: p > threshold?
    |
    +--NO--> continue generation
    |
    +--YES--> trigger final answer format
              (stop reasoning trace)
Think of ROM like a driving instructor with a brake pedal. The student (LRM) is learning to drive and solve problems. The instructor doesn’t grab the wheel or tell the student how to think—the student’s brain is frozen, unchanged. But the instructor watches carefully through the windshield (hidden states). The moment the student reaches the destination but keeps driving in circles, the instructor taps the brake (early exit). The instructor learned when to brake by riding with many students and noting exactly when they arrived versus when they stopped circling. To avoid memorizing specific routes, the instructor practiced on mixed-up trips where different students’ drives were spliced together.
Key Concepts
-
Overthinking vs. Productive Reasoning: Not all long reasoning is bad. Productive reasoning is the model working toward the answer—trying approaches, checking logic, building up to the solution. Overthinking is what happens after the model already has the right answer but doesn’t realize it should stop. It’s like continuing to debug code that already works. ROM’s core insight is that these two phases have different signatures in the model’s internal representations, and you can train a classifier to tell them apart in real time.
-
Streaming Detection: Traditional methods look at the entire generated text after it’s done (post-hoc analysis) or use fixed rules (stop after 500 tokens). Streaming detection means making a decision at every single token as it’s being generated. It’s the difference between reviewing a recording versus watching live. This requires the detector to be fast (can’t slow down generation) and accurate (false positives waste the model’s good reasoning; false negatives let overthinking continue). ROM achieves this by using only late-layer hidden states—no need to look at the actual text tokens, which would be slower.
-
Token-Level Supervision with Solution Boundaries: How do you label which tokens are overthinking? ROM doesn’t guess. It runs the model, extracts all intermediate answers from the reasoning trace (like “so x = 5” or “therefore the answer is B”), checks each one against the ground truth, and marks the first correct answer’s position. Everything after that position gets label 1 (overthinking). This is more precise than labeling entire traces as good/bad, because it captures the exact moment overthinking begins within a single response.
Framework Shift
Before (mainstream approach):        After (ROM):

[LRM generates full trace]           [LRM starts generating]
         |                                    |
         v                                    v
[Post-hoc analysis or                [Detection head monitors
 fixed-length truncation]             each token in real time]
         |                                    |
         v                                    v
[Return shortened response]          [Trigger early exit when
                                      overthinking detected]
                                             |
                                             v
                                     [Return response at
                                      optimal stopping point]

Static intervention                  Dynamic intervention
(after generation done)              (during generation)
One sentence: From post-hoc pruning to real-time monitoring, the core shift is treating overthinking mitigation as a streaming control problem rather than a text editing problem.
Expert Assessment
Problem choice: Real gap. LRMs are being deployed at scale, and inference cost is a major bottleneck. Overthinking isn’t just academic—it’s burning money and hurting user experience. The problem sits at the intersection of efficiency and reliability, which is exactly where the field needs solutions right now.
Method maturity: Clever and practical. The detection head is lightweight (doesn’t require retraining the backbone), and the solution boundary labeling is more principled than prior heuristics. However, the method assumes you can verify intermediate answers, which works for math/reasoning tasks but might not generalize to open-ended generation. The data augmentation (mixing traces) is a nice touch to prevent overfitting, but the paper doesn’t deeply explore what happens when overthinking patterns vary significantly across problem types.
Experimental integrity: Baselines are fair—they compare against vanilla generation, fixed-length truncation, and a prior method (SEED). The 93.51% accuracy claim is strong, but I’d want to see error analysis: when ROM fails, is it cutting off too early or too late? The 47.2% length reduction is impressive, but the paper doesn’t show latency measurements in wall-clock time, which matters for real deployment. Also, all experiments are on reasoning benchmarks (math, code, logic)—no evidence this works for creative or ambiguous tasks.
Writing quality: The paper is clear and well-structured, but the related work section is thin—it doesn’t engage deeply with why prior methods failed or what specific assumptions they made. The ablation studies are solid (showing the detection head’s layer choice matters, data augmentation helps), but the paper would benefit from failure case analysis. Which problems does ROM struggle with? When does the detector get confused?
Verdict: weak accept — Addresses a real problem with a practical solution and strong empirical results, but generalization beyond reasoning tasks is uncertain and the evaluation could be more comprehensive.
Takeaways
Steal the labeling strategy: If you’re training any kind of “quality detector” for generated text, ROM’s approach of finding solution boundaries within a trace is more precise than labeling entire outputs as good/bad. This applies beyond overthinking—think detecting hallucinations, off-topic drift, or redundancy in any generative system.
Streaming detection is underused: Most people treat generation as a black box that you analyze after it’s done. ROM shows you can attach lightweight monitors to intermediate representations and make real-time decisions. This pattern transfers: imagine detecting toxicity mid-generation, or steering a model away from unsafe content before it finishes the sentence.
Data augmentation for detectors: Mixing traces from different problems to prevent memorization is a simple trick that makes the detector more robust. If you’re training any classifier on model outputs, consider whether it’s learning problem-specific patterns versus general behavioral patterns, and augment accordingly.
论文: 2603.22016 作者: Xinyan Wang, Xiaogeng Liu, Chaowei Xiao 分类: cs.LG, cs.AI, cs.CL
缺口
像o1这样的大型推理模型(LRM)通过生成长链式思考轨迹来解决难题。
它们有效,但不知道何时停止。
即使找到正确答案后,它们仍继续推理,增加耗费金钱和时间的token,有时甚至偏离正确解。
现有修复方法要么重训整个模型(昂贵、缓慢),要么使用手工规则如”N个token后停止”(脆弱,无法捕捉真实的过度思考模式)。
没人把这当作实时监控问题——观察模型思考并在它开始空转时立即干预。
问题: LRM在解决问题后过度思考
         |
         v
缺口: 无实时检测方法
     (只有事后或基于规则)
         |
         v
假设: 过度思考在隐藏状态中
      有可检测的模式
         |
         v
方法: 轻量级检测头监控
      token流,在过度思考
      开始时触发提前退出
         |
         v
证据: 响应缩短47.2%,
      准确率保持93.51%
         |
         v
结论: 流式检测对过度思考
      缓解有效
增量
一句话: ROM之前,你要么重训模型要么用笨拙的启发式规则阻止过度思考;ROM之后,你接上一个轻量级检测器,实时观察模型思考并在恰当时刻切断它。
核心机制
ROM有三个协同工作的部分。
首先,一个检测头——小型神经网络——位于冻结LRM的后层隐藏状态之上。
它完全不改变基础模型。
其次,推理期间,这个头读取每个生成的token并输出概率:“模型现在是否在过度思考?”第三,当该概率超过阈值时,ROM立即触发模型跳转到最终答案格式,跳过剩余推理轨迹。
训练这个检测器需要知道过度思考从哪里开始。
ROM使用巧妙的标注策略:对每条推理轨迹,找到模型首次得出正确答案的点(通过检查中间解验证)。
该点之前的一切是”生产性推理”(标签:0)。
之后的一切是”过度思考”(标签:1)。
为使检测器鲁棒,ROM还通过混合不同问题的轨迹来增强训练数据,防止它记忆特定问题的模式。
冻结的LRM主干
    |
    | (第L-k层的隐藏状态)
    v
[检测头]  <-- 轻量级分类器
    |
    | (每个token的概率)
    v
决策: p > 阈值?
    |
    +--否--> 继续生成
    |
    +--是--> 触发最终答案格式
             (停止推理轨迹)
把ROM想象成带副刹车的驾校教练。
学员(LRM)在学开车和解决问题。
教练不抓方向盘也不告诉学员怎么想——学员的大脑是冻结的,未改变。
但教练通过挡风玻璃(隐藏状态)仔细观察。
学员到达目的地但继续绕圈的那一刻,教练踩刹车(提前退出)。
教练通过陪很多学员练车并精确记录他们何时到达与何时停止绕圈来学会何时刹车。
为避免记忆特定路线,教练在混合行程上练习,不同学员的驾驶被拼接在一起。
关键概念
- 过度思考vs生产性推理: 并非所有长推理都是坏的。
生产性推理是模型朝答案努力——尝试方法、检查逻辑、构建解决方案。
过度思考是模型已有正确答案但没意识到应该停止后发生的事。
就像继续调试已经正常工作的代码。
ROM的核心洞察是这两个阶段在模型内部表示中有不同特征,你可以训练分类器实时区分它们。
- 流式检测: 传统方法在生成完成后查看整个文本(事后分析)或使用固定规则(500个token后停止)。
流式检测意味着在每个token生成时做决策。
这是回看录像与现场观看的区别。
这要求检测器快速(不能拖慢生成)且准确(假阳性浪费模型的良好推理;假阴性让过度思考继续)。
ROM通过仅使用后层隐藏状态实现这一点——无需查看实际文本token,那样会更慢。
- 基于解边界的token级监督: 如何标注哪些token是过度思考?ROM不猜测。
它运行模型,从推理轨迹提取所有中间答案(如”所以x=5”或”因此答案是B”),对照真值检查每个,标记首个正确答案的位置。
该位置之后的一切获得标签1(过度思考)。
这比将整条轨迹标为好/坏更精确,因为它捕捉单个响应内过度思考开始的确切时刻。
框架转变
之前(主流方法):                  之后(ROM):

[LRM生成完整轨迹]                [LRM开始生成]
         |                              |
         v                              v
[事后分析或固定长度截断]          [检测头实时监控每个token]
         |                              |
         v                              v
[返回缩短的响应]                  [检测到过度思考时
                                   触发提前退出]
                                         |
                                         v
                                  [在最优停止点返回响应]

静态干预                          动态干预
(生成完成后)                      (生成期间)
一句话: 从事后修剪到实时监控,核心转变是将过度思考缓解视为流式控制问题而非文本编辑问题。
专家评审
选题眼光: 真实缺口。
LRM正大规模部署,推理成本是主要瓶颈。
过度思考不只是学术问题——它在烧钱并损害用户体验。
该问题位于效率与可靠性的交叉点,正是该领域现在需要解决方案的地方。
方法成熟度: 巧妙且实用。
检测头轻量(不需重训主干),解边界标注比先前启发式更有原则。
然而,该方法假设你能验证中间答案,这对数学/推理任务有效但可能无法泛化到开放式生成。
数据增强(混合轨迹)是防止过拟合的好手法,但论文未深入探讨当过度思考模式在不同问题类型间显著变化时会发生什么。
实验诚意: 基线公平——与原始生成、固定长度截断和先前方法(SEED)比较。
93.51%准确率声明强劲,但我想看错误分析:ROM失败时,是切得太早还是太晚?47.2%长度减少令人印象深刻,但论文未显示实际时钟时间的延迟测量,这对真实部署很重要。
此外,所有实验都在推理基准(数学、代码、逻辑)上——无证据表明这对创造性或模糊任务有效。
写作功力: 论文清晰且结构良好,但相关工作部分单薄——未深入探讨先前方法为何失败或它们做了什么具体假设。
消融研究扎实(显示检测头的层选择重要,数据增强有帮助),但论文会受益于失败案例分析。
ROM在哪些问题上挣扎?检测器何时会困惑?
判决: 弱接收 — 用实用解决方案和强实证结果解决真实问题,但推理任务之外的泛化不确定,评估可以更全面。
要点总结
偷走标注策略: 如果你在为生成文本训练任何”质量检测器”,ROM在轨迹内找解边界的方法比将整个输出标为好/坏更精确。
这超越过度思考——想想检测幻觉、偏题漂移或任何生成系统中的冗余。
流式检测被低估: 大多数人把生成当作黑盒,完成后才分析。
ROM展示你可以在中间表示上附加轻量级监视器并做实时决策。
这个模式可迁移:想象生成中途检测毒性,或在模型完成句子前引导它远离不安全内容。
检测器的数据增强: 混合不同问题的轨迹以防记忆是使检测器更鲁棒的简单技巧。
如果你在模型输出上训练任何分类器,考虑它是在学习特定问题的模式还是一般行为模式,并相应增强。