Paper: 2606.02577 Authors: Junjie Ye, Rong Xue, Basile Van Hoorick, Runhao Li, Harshitha Rajaprakash, Pavel Tokmakov, Muhammad Zubair Irshad, Vitor Guizilini, Yue Wang Categories: cs.RO, cs.CV
The Gap
Robot learning needs massive diverse demonstrations, but real teleoperation is expensive. Video diffusion models can generate synthetic data, but existing approaches either do shallow visual augmentation (changing lighting, backgrounds) or suffer from “embodiment hallucination” — the generated robot arms move in physically impossible ways because the model doesn’t respect the robot’s kinematic constraints.
The core problem: how do you generate photorealistic robot videos with novel objects and scenes while guaranteeing the robot motion stays physically feasible?
Problem: Need diverse robot data
   |
   v
Current solutions:
   |
   +---> Real teleoperation -----> Expensive, slow
   |
   +---> Visual augmentation -----> Shallow diversity (same motions)
   |
   +---> Direct video generation --> Embodiment hallucination

This paper's path:
   |
   v
Assumption: Decouple trajectory from environment
   |
   v
Method: Anchor to rendered robot + condition on scene priors
   |
   v
Evidence: Generated data improves policy, reduces real data needs
   |
   v
Conclusion: Scalable synthesis without hallucination
The Increment
One sentence: Before, generating diverse robot data meant choosing between visual-only augmentation or physically infeasible motions; after, you can transplant real trajectories into entirely new scenes with photorealistic rendering while maintaining kinematic validity.
Core Mechanism
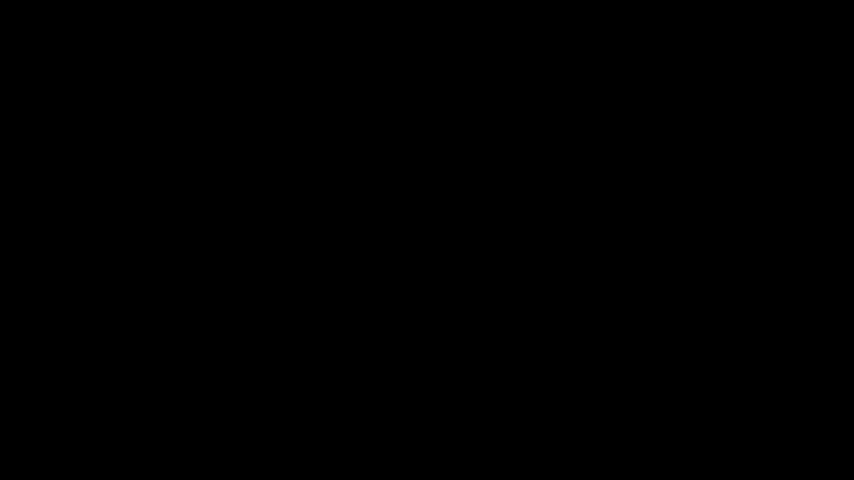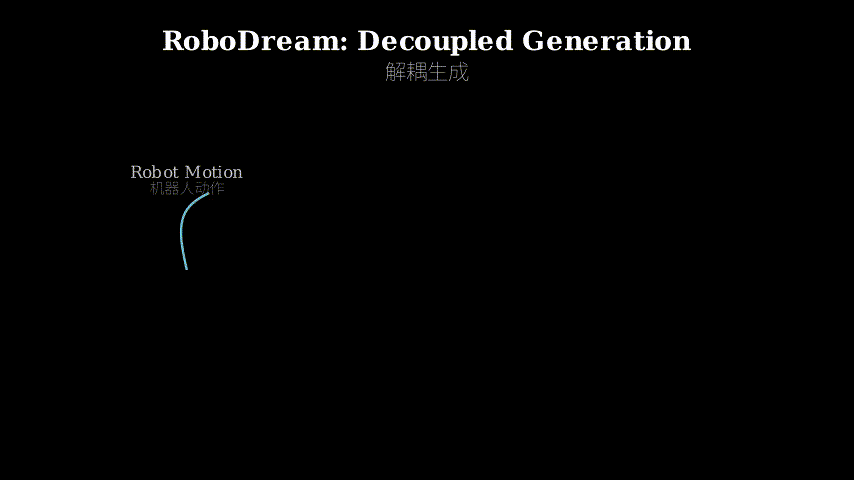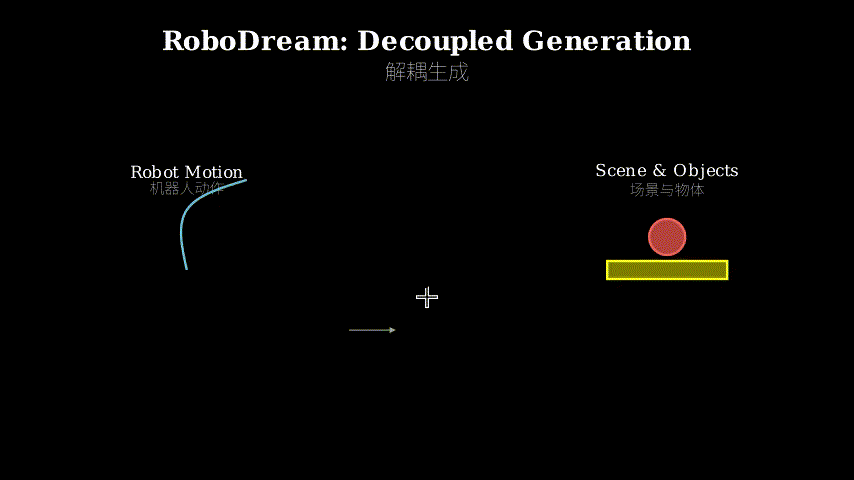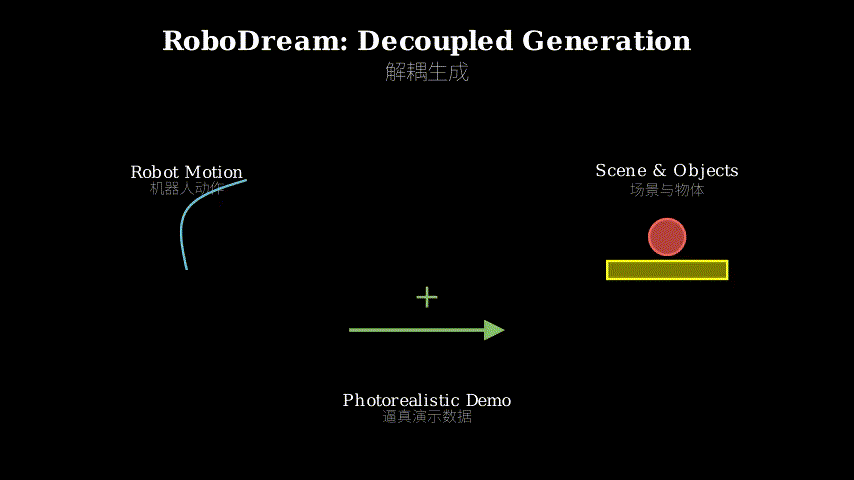
RoboDream has three components working in sequence. First, a trajectory renderer takes a recorded robot motion and renders it as RGB images showing just the robot arm moving in empty space. Second, object and scene priors provide explicit geometric and appearance information about what should be in the scene. Third, a video diffusion model takes the rendered robot motion as a structural anchor and the priors as conditioning inputs, then generates the full scene around the robot.
The data flow is unidirectional: trajectory → render → condition on priors → diffuse → output video. The key operation is that the diffusion process respects the rendered robot skeleton as a hard constraint while hallucinating everything else — objects, textures, backgrounds, lighting. This prevents the model from bending the robot arm in impossible ways because the arm’s structure is given, not generated.
Input trajectory     Scene/object priors
      |                      |
      v                      v
  Render robot          [geometry +
  skeleton              appearance]
      |                      |
      +----------+-----------+
                 |
                 v
         Video diffusion model
         (robot anchored,
          scene hallucinated)
                 |
                 v
         Photorealistic video
         (feasible motion +
          novel environment)
Think of RoboDream as a theater production. The trajectory renderer is like a choreographer who records the actor’s movements using motion capture — just the skeleton, no costume or set. The scene priors are the art director’s notes: “Victorian mansion, crystal chandelier, velvet curtains.” The diffusion model is the film crew that shoots the scene, but instead of building real sets, they paint in the environment around the actor’s recorded movements using CGI. The actor (robot) never moves differently than the original choreography, but now they’re performing in a completely different world. You can take the same dance (trajectory) and drop it into a dozen different theaters (scenes) without re-recording the performance.
Key Concepts
-
Embodiment hallucination: When a generative model creates robot videos, it might show the arm bending at impossible angles or teleporting because the model treats the robot like any other visual element rather than understanding its kinematic constraints. It’s like asking an artist who’s never seen a human skeleton to draw people moving — they might draw arms bending backwards or limbs stretching unnaturally. RoboDream avoids this by providing the robot skeleton upfront as a structural guide, so the model only generates the environment, not the robot motion.
-
Retrieval and rebirth: You have 100 recorded demonstrations of a robot picking up a red cube on a wooden table. Instead of collecting 100 new demonstrations with different objects, you reuse those same 100 trajectories but have the model generate them in new contexts — blue spheres on marble counters, green cylinders on metal desks. The robot’s motion stays identical (same grasp sequence, same arm path), but the visual context changes completely. It’s data multiplication without new teleoperation.
Framework Shift
Before (existing approaches):          After (RoboDream):

Real data collection:                  Real data collection:
  Record demo                            Record demo (once)
     |                                      |
     v                                      v
  Use as-is                              Extract trajectory
     |                                      |
  (expensive, limited)                     v
                                        Render skeleton
Or generate synthetically:                 |
  Text/image prompt                        v
     |                                  Condition diffusion
     v                                  on scene priors
  Diffuse full video                       |
     |                                      v
     v                                  Generate N variations
  Robot + scene                         (same motion, new scenes)
  (embodiment errors)                      |
                                           v
                                        Reusable trajectory
                                        (scalable, accurate)
From monolithic generation to compositional synthesis, the core shift is treating robot motion as a reusable structural primitive rather than regenerating it each time.
Expert Assessment
Problem choice: This is a real gap. The field has been stuck between expensive real data and cheap but flawed synthetic data. The observation that embodiment hallucination is the blocker for scaling video generation is well-targeted. This sits at the intersection of two active areas: robot learning scaling and video diffusion models.
Method maturity: The decoupling is conceptually clean and the execution is solid. Anchoring to rendered motion is not revolutionary but it’s the right engineering choice. The scene prior conditioning could be more sophisticated — explicit geometry and appearance seems brittle compared to learned representations — but it works for the demonstrated scope. The “prop-free teleoperation” idea is clever but feels like a bonus feature rather than core contribution.
Experimental integrity: The baselines are fair and the ablations are thorough. Real-world policy experiments across multiple tasks strengthen the claims significantly. One weakness: the generated data improvements are consistent but modest (10-20% success rate gains). The paper doesn’t address failure modes in detail — when does the decoupling break down? What kinds of scene priors cause artifacts?
Writing quality: The paper front-loads the big ideas well. The related work section could be sharper in drawing boundaries with prior video generation work. The experimental section is comprehensive but dense — the main results table would benefit from visual separation of synthetic-only vs mixed data conditions. The limitations discussion is minimal.
Verdict: weak accept — Solves a legitimate problem with a well-executed method and demonstrates real-world utility, but the contribution is more engineering insight than algorithmic breakthrough.
Takeaways
The decoupling principle transfers broadly: when generating complex structured data, separate the hard constraints (physical laws, geometric relationships) from the free variables (appearance, context). Render or encode the constraints explicitly, then condition the generative model on them rather than asking it to learn them implicitly. This shows up in other domains — generating molecular conformations (fix bond angles, generate spatial arrangements), creating UI layouts (fix widget types, generate styling), synthesizing sensor data (fix signal patterns, generate noise profiles).
The “retrieval and rebirth” framing is worth stealing. If you have expensive ground-truth data in one context, ask whether the core structure can be transplanted into synthetic variations. This works when the underlying dynamics are separable from the surface appearance — motion trajectories, click sequences, control policies, query patterns.
论文: 2606.02577 作者: Junjie Ye, Rong Xue, Basile Van Hoorick, Runhao Li, Harshitha Rajaprakash, Pavel Tokmakov, Muhammad Zubair Irshad, Vitor Guizilini, Yue Wang 分类: cs.RO, cs.CV
缺口
机器人学习需要海量多样的演示数据,但真实遥操作成本高昂。
视频扩散模型可以生成合成数据,但现有方法要么只做浅层视觉增强(改变光照、背景),要么遭遇”具身幻觉”——生成的机器人手臂做出物理上不可能的动作,因为模型不尊重机器人的运动学约束。
核心问题:如何生成包含新物体和新场景的逼真机器人视频,同时保证机器人运动在物理上可行?
问题:需要多样的机器人数据
   |
   v
现有解决方案:
   |
   +---> 真实遥操作 -----> 昂贵、缓慢
   |
   +---> 视觉增强 -----> 多样性浅(动作相同)
   |
   +---> 直接生成视频 --> 具身幻觉

本文路径:
   |
   v
假设:解耦轨迹与环境
   |
   v
方法:锚定渲染机器人 + 条件化场景先验
   |
   v
证据:生成数据提升策略性能,减少真实数据需求
   |
   v
结论:可扩展合成,无幻觉
增量
一句话:之前,生成多样机器人数据意味着在仅视觉增强和物理不可行动作之间二选一; 之后,你可以将真实轨迹移植到全新场景中,获得逼真渲染的同时保持运动学有效性。
核心机制
RoboDream有三个顺序工作的组件。
首先,轨迹渲染器接收记录的机器人运动,将其渲染为RGB图像,只显示机器人手臂在空白空间中移动。
其次,物体和场景先验提供显式的几何与外观信息,描述场景中应有什么。
第三,视频扩散模型以渲染的机器人运动为结构锚点,以先验为条件输入,然后在机器人周围生成完整场景。
数据流是单向的:轨迹 → 渲染 → 条件化先验 → 扩散 → 输出视频。
关键操作在于扩散过程将渲染的机器人骨架作为硬约束,同时幻化其余一切——物体、纹理、背景、光照。
这防止了模型让机器人手臂以不可能的方式弯曲,因为手臂结构是给定的,不是生成的。
输入轨迹         场景/物体先验
      |                  |
      v                  v
  渲染机器人        [几何 +
  骨架              外观]
      |                  |
      +--------+---------+
               |
               v
       视频扩散模型
       (机器人锚定,
        场景幻化)
               |
               v
       逼真视频
       (可行运动 +
        新环境)
把RoboDream想象成一部戏剧制作。
轨迹渲染器像编舞师,用动作捕捉记录演员动作——只有骨架,无服装无布景。
场景先验是艺术指导的笔记:“维多利亚庄园,水晶吊灯,天鹅绒窗帘。 “扩散模型是摄制组,但他们不搭建真实布景,而是用CG在演员的记录动作周围绘制环境。
演员(机器人)的动作从不偏离原始编排,但现在他们在一个完全不同的世界里表演。
你可以用同一段舞蹈(轨迹)投放到十几个不同的剧院(场景)中,无需重新录制表演。
关键概念
- 具身幻觉:当生成模型创建机器人视频时,它可能显示手臂以不可能的角度弯曲或瞬移,因为模型将机器人视为普通视觉元素,不理解其运动学约束。
就像让一个从未见过人体骨骼的画家去画人运动——他们可能画出手臂向后弯或肢体不自然拉伸。
RoboDream通过预先提供机器人骨架作为结构引导来避免这一点,模型只生成环境,不生成机器人运动。
- 检索与重生:你有100条机器人在木桌上抓取红色方块的录制演示。
不收集100条包含不同物体的新演示,你复用这100条轨迹,让模型在新上下文中生成它们——大理石台面上的蓝色球体,金属桌上的绿色圆柱。
机器人运动保持相同(相同抓取序列,相同手臂路径),但视觉上下文完全改变。
这是无需新遥操作的数据乘法。
框架转变
之前(现有方法):                之后(RoboDream):

真实数据收集:                    真实数据收集:
  记录演示                          记录演示(一次)
     |                                  |
     v                                  v
  直接使用                            提取轨迹
     |                                  |
  (昂贵,有限)                          v
                                     渲染骨架
或合成生成:                            |
  文本/图像提示                          v
     |                               条件化扩散
     v                               于场景先验
  扩散完整视频                           |
     |                                  v
     v                               生成N个变体
  机器人 + 场景                      (相同动作,新场景)
  (具身错误)                             |
                                        v
                                     可复用轨迹
                                     (可扩展,精确)
从整体生成到组合式合成,核心转变是将机器人运动视为可复用的结构原语,而非每次重新生成。
专家评审
选题眼光:这是真实缺口。
该领域一直卡在昂贵的真实数据和廉价但有缺陷的合成数据之间。
观察到具身幻觉是扩展视频生成的阻滞因素,这个定位很准。
位于两个活跃领域的交叉点:机器人学习扩展和视频扩散模型。
方法成熟度:解耦概念上干净,执行扎实。
锚定渲染运动不算革命性但是正确的工程选择。
场景先验条件化可以更复杂——显式几何和外观相比学习表示显得脆弱——但对展示的范围有效。
“无道具遥操作”想法巧妙,但更像附加功能而非核心贡献。
实验诚意:基线公平,消融充分。
跨多个任务的真实世界策略实验显著增强了主张。
一个弱点:生成数据的改进一致但适度(10-20%成功率提升)。
论文没有详细讨论失败模式——解耦何时崩溃? 哪些场景先验导致伪影?
写作功力:论文前置核心想法做得好。
相关工作部分在与先前视频生成工作划界上可以更锐利。
实验部分全面但密集——主结果表如果视觉分隔纯合成与混合数据条件会更好。
局限性讨论很少。
判决:弱接收 — 用执行良好的方法解决了合理问题并展示了真实世界效用,但贡献更多是工程洞见而非算法突破。
要点总结
解耦原则广泛迁移:生成复杂结构化数据时,分离硬约束(物理法则、几何关系)和自由变量(外观、上下文)。
显式渲染或编码约束,然后以其为条件给生成模型,而非要求它隐式学习。
这出现在其他领域——生成分子构象(固定键角,生成空间排列)、创建UI布局(固定组件类型,生成样式)、合成传感器数据(固定信号模式,生成噪声轮廓)。
“检索与重生”框架值得偷师。
如果你在一个上下文中有昂贵的真实数据,问问核心结构能否移植到合成变体中。
这在底层动态可与表面外观分离时有效——运动轨迹、点击序列、控制策略、查询模式。