Paper: 2603.30035 Authors: Ming-Hua Tsai, Phat Tran Categories: cs.LG, cs.CL
The Gap
Existing LLM routing methods fall into two camps. Supervised routing trains a classifier on labeled data to predict which model to use, but it’s static—can’t adapt when model performance shifts or new models arrive. Partial-feedback methods like reinforcement learning can adapt online, but they’re sample-inefficient and struggle with the exploration-exploitation tradeoff when you have many models to choose from.
The core tension: you want to route queries to cheaper models when possible (save money), but you need to know which queries each model can handle well (requires exploration). Do it wrong and you either waste money on expensive models or tank quality with cheap ones.
Problem: Many LLMs, different costs/quality
         Need to route queries efficiently
              |
              v
    Supervised methods     Partial-feedback methods
    (static, no adapt) <-> (adaptive, sample-hungry)
              |
              v
    Gap: Need online adaptation + sample efficiency
              |
              v
    Method: NeuralUCB (contextual bandit)
              |
              v
    Evidence: RouterBench experiments
              |
              v
    Conclusion: Competitive quality at lower cost
The Increment
One sentence: Before this paper, LLM routing was either static-but-efficient or adaptive-but-wasteful; after, we have a contextual bandit approach that adapts online while maintaining sample efficiency through neural uncertainty estimation.
Core Mechanism
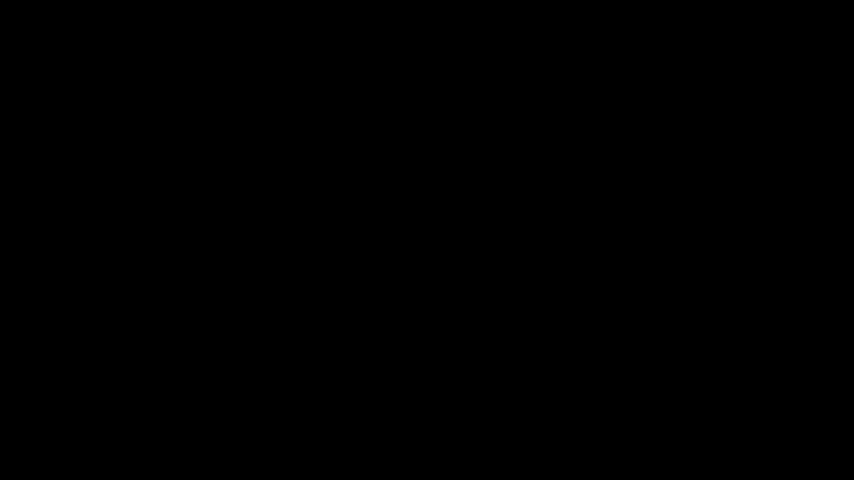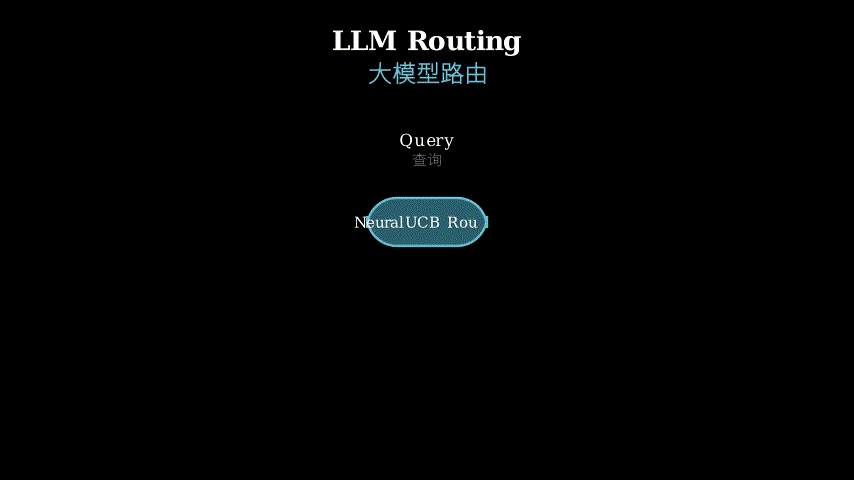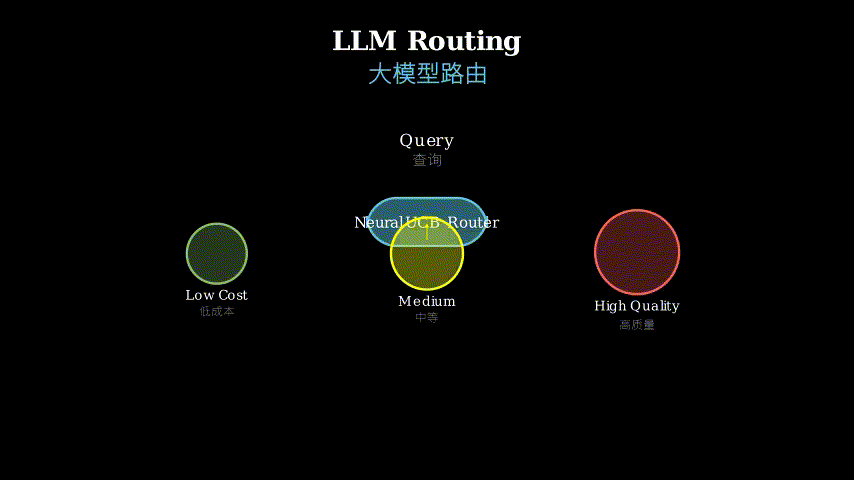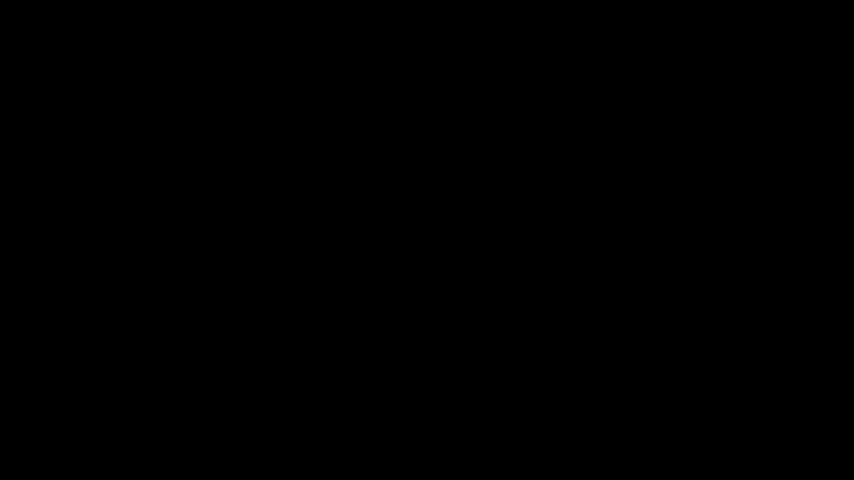
NeuralUCB treats LLM routing as a contextual bandit problem. Each query is a context, each LLM is an arm, and the reward combines quality (how good the answer is) and cost (how much inference costs). The algorithm maintains a neural network that predicts expected reward for each query-model pair, plus an uncertainty estimate. At decision time, it picks the model with highest upper confidence bound: predicted reward plus uncertainty bonus.
The neural network gets trained on accumulated feedback. When you route a query to a model and observe the outcome, that becomes a training example. The uncertainty comes from an ensemble of networks or a Bayesian approximation—regions of input space with sparse data get high uncertainty, encouraging exploration there.
The key insight: use the neural network’s uncertainty to guide exploration. If you’re confident a cheap model will work (low uncertainty, high predicted reward), use it. If you’re unsure (high uncertainty), the UCB bonus makes you try it to gather information. If you’re confident it won’t work, avoid it.
Query arrives
     |
     v
[Neural Net] --predicts--> Reward estimates for each LLM
     |                            |
     +--estimates--> Uncertainty  |
                          |       |
                          v       v
                    UCB = reward + bonus
                          |
                          v
                    Pick max UCB
                          |
                          v
                    Route to LLM
                          |
                          v
                    Observe outcome
                          |
                          v
                    Update neural net
Think of it like a restaurant manager assigning dishes to cooks of different skill levels and wages. You have a star chef (expensive, reliable) and several line cooks (cheap, variable). Each order comes with context—complexity, cuisine type, time pressure. The manager maintains mental models of each cook’s strengths and uncertainties. For a simple burger, confidently assign the cheapest cook. For a complex soufflé with uncertain difficulty, maybe try a mid-tier cook to learn their limits—the uncertainty bonus justifies the risk. Over time, the manager’s mental model sharpens, and assignments get more efficient. The neural network is that mental model, UCB is the decision rule that balances “use what works” with “learn the boundaries.”
Key Concepts
-
Contextual Bandit: You face a sequence of decisions. Each time, you see a context (query features), choose an action (which LLM), and get a reward (quality minus cost). The goal is to maximize cumulative reward. Unlike supervised learning, you only see the reward for the action you took, not the counterfactual “what if I’d chosen differently.” Unlike full reinforcement learning, your action doesn’t change the next context—each query is independent. The challenge is balancing exploitation (pick the action you think is best) with exploration (try uncertain actions to improve your model). Imagine a doctor choosing treatments: each patient is a context, each treatment is an action, and you only learn the outcome of the treatment you prescribed, not the alternatives.
-
Upper Confidence Bound (UCB): A principled way to handle exploration-exploitation. For each action, compute an upper confidence bound: your best guess of the reward plus a bonus proportional to your uncertainty. Pick the action with highest UCB. If you’re certain an action is bad, the bonus is small and it won’t get picked. If you’re uncertain, the bonus is large—maybe it’s actually great and you should find out. Over time, as you gather data, uncertainties shrink and the algorithm converges to exploiting the best actions. It’s like bidding in an auction where you add a “information value” premium to items you know little about.
-
Neural Uncertainty Estimation: Standard neural networks give point predictions but no confidence intervals. To get uncertainty, you can train an ensemble (multiple networks with different initializations—their disagreement indicates uncertainty) or use Bayesian approximations (treat network weights as distributions, not fixed values). In regions with lots of training data, predictions converge and uncertainty is low. In sparse regions, predictions vary and uncertainty is high. This lets the UCB algorithm know where it’s ignorant and needs to explore. Think of weather forecasting: a single model gives a temperature prediction, but an ensemble of models gives a range—if they all agree, you’re confident; if they diverge, you’re uncertain.
Framework Shift
Before (mainstream approach):        After (this paper):

Train classifier on labeled data     Start with no labels
         |                                   |
         v                                   v
  Query -> Classifier -> LLM          Query -> NeuralUCB -> LLM
         (fixed policy)                      |
                                             v
                                      Observe reward
                                             |
                                             v
                                      Update neural net
                                      (adaptive policy)

Static: Can't adapt to new models    Dynamic: Learns online
Supervised: Needs labels upfront     Bandit: Learns from rewards
From offline training to online adaptation, the core shift is treating routing as sequential decision-making under uncertainty rather than a one-time classification problem.
Expert Assessment
Problem choice: Real gap. LLM inference costs are skyrocketing, and the zoo of models (GPT-4, Claude, Llama, Gemini, specialized fine-tunes) keeps growing. Routing is a practical bottleneck. The paper correctly identifies that existing methods are either too rigid (supervised) or too sample-hungry (naive RL). This sits at the intersection of practical ML systems and bandit theory—timely and grounded.
Method maturity: Solid application of existing theory, not a novel algorithm. NeuralUCB has been around since 2020 (Zhou et al.). The contribution here is recognizing that LLM routing fits the contextual bandit framing and implementing it on RouterBench. The execution is competent but not groundbreaking—no new theoretical guarantees, no architectural innovations. A simpler linear UCB might have been a useful ablation to show where the neural component adds value.
Experimental integrity: Baselines are reasonable (random, min-cost, max-quality) but not exhaustive. Missing comparisons to recent supervised routers (RouteLLM, FrugalGPT) and other bandit algorithms (Thompson Sampling, LinUCB). The “simulated online setting” is a bit hand-wavy—how exactly are queries sequenced? Are there distribution shifts? The paper shows NeuralUCB beats random and min-cost, which is a low bar. The gap to max-quality is large, suggesting the method still struggles with hard queries. More error analysis would help: which query types does it route poorly?
Writing quality: The abstract and intro are clear, but the method section is thin—barely two pages. The reader has to fill in gaps: what neural architecture? How is the ensemble trained? What’s the exact UCB formula? The experiments section jumps straight to results without describing the setup in detail. Rewriting the method section with pseudocode and architectural diagrams would elevate the paper from “application note” to “reproducible contribution.”
Verdict: Weak accept—the problem is real, the approach is sensible, and the results are promising, but the execution feels rushed and the evaluation is incomplete. This is a good workshop paper or a starting point for a more thorough study, not a landmark contribution.
Takeaways
Practitioners can steal the framing: if you’re routing between multiple models (LLMs, vision models, speech recognizers), treat it as a contextual bandit, not a classification problem. This lets you adapt online without labeled data. The UCB principle is simple to implement: maintain a model of expected reward and uncertainty, then pick the action with highest reward + uncertainty bonus. You can start with a linear model (cheap, interpretable) and upgrade to neural if you have complex context features. The key insight transfers beyond LLMs: anytime you’re choosing between options with different cost-quality tradeoffs and you can observe outcomes, contextual bandits are a natural fit.
论文: 2603.30035 作者: Ming-Hua Tsai, Phat Tran 分类: cs.LG, cs.CL
缺口
现有的大模型路由方法分两派。
监督路由在标注数据上训练分类器来预测该用哪个模型,但它是静态的——模型性能变化或新模型出现时无法适应。
部分反馈方法比如强化学习可以在线适应,但样本效率低,在模型选择多的时候难以平衡探索和利用。
核心矛盾:你想在可能的时候把查询路由到便宜模型(省钱),但你需要知道每个模型能处理好哪些查询(需要探索)。
做错了要么在昂贵模型上浪费钱,要么用便宜模型搞砸质量。
问题:很多大模型,成本/质量各异
     需要高效路由查询
          |
          v
  监督方法           部分反馈方法
  (静态,不适应) <-> (适应,样本饥渴)
          |
          v
  缺口:需要在线适应 + 样本效率
          |
          v
  方法:NeuralUCB(上下文老虎机)
          |
          v
  证据:RouterBench实验
          |
          v
  结论:更低成本达到有竞争力的质量
增量
一句话: 这篇论文之前,大模型路由要么静态但高效,要么适应但浪费;之后,我们有了一种上下文老虎机方法,通过神经网络不确定性估计在线适应的同时保持样本效率。
核心机制
NeuralUCB 把大模型路由当作上下文老虎机问题。
每个查询是一个上下文,每个大模型是一个臂,奖励结合质量(答案有多好)和成本(推理花多少钱)。
算法维护一个神经网络,预测每个查询-模型对的期望奖励,加上一个不确定性估计。
决策时,它选置信上界最高的模型:预测奖励加不确定性奖励。
神经网络在累积的反馈上训练。
当你把查询路由到某个模型并观察结果,那就成了一个训练样本。
不确定性来自网络集成或贝叶斯近似——输入空间中数据稀疏的区域得到高不确定性,鼓励在那里探索。
关键洞察:用神经网络的不确定性指导探索。
如果你确信便宜模型能行(低不确定性,高预测奖励),就用它。
如果你不确定(高不确定性),UCB 奖励让你试试它来收集信息。
如果你确信它不行,就避开它。
查询到达
     |
     v
[神经网络] --预测--> 每个大模型的奖励估计
     |                        |
     +--估计--> 不确定性      |
                    |         |
                    v         v
              UCB = 奖励 + 奖励
                    |
                    v
              选最大UCB
                    |
                    v
              路由到大模型
                    |
                    v
              观察结果
                    |
                    v
              更新神经网络
把它想成餐厅经理给不同技能水平和工资的厨师分配菜品。
你有一个明星大厨(贵,可靠)和几个普通厨师(便宜,不稳定)。
每个订单带有上下文——复杂度、菜系类型、时间压力。
经理维护每个厨师的强项和不确定性的心智模型。
对于简单的汉堡,自信地分给最便宜的厨师。
对于难度不确定的复杂舒芙蕾,也许试试中等厨师来了解他们的极限——不确定性奖励证明了这个风险。
随着时间推移,经理的心智模型变清晰,分配变得更高效。
神经网络就是那个心智模型,UCB 是平衡”用有效的”和”学习边界”的决策规则。
关键概念
- 上下文老虎机: 你面对一系列决策。
每次,你看到一个上下文(查询特征),选择一个动作(哪个大模型),得到一个奖励(质量减成本)。
目标是最大化累积奖励。
不像监督学习,你只看到你采取的动作的奖励,看不到反事实的”如果我选了别的会怎样”。
不像完整的强化学习,你的动作不改变下一个上下文——每个查询是独立的。
挑战是平衡利用(选你认为最好的动作)和探索(尝试不确定的动作来改进你的模型)。
想象医生选择治疗方案:每个病人是一个上下文,每个治疗是一个动作,你只学到你开的治疗的结果,学不到替代方案。
- 置信上界(UCB): 处理探索-利用的原则性方法。
对每个动作,计算一个置信上界:你对奖励的最佳猜测加上一个与不确定性成比例的奖励。
选 UCB 最高的动作。
如果你确定一个动作很差,奖励很小,它不会被选。
如果你不确定,奖励很大——也许它实际上很棒,你应该搞清楚。
随着时间推移,当你收集数据,不确定性缩小,算法收敛到利用最好的动作。
这就像在拍卖中出价,你给你了解很少的物品加一个”信息价值”溢价。
- 神经不确定性估计: 标准神经网络给点预测但没有置信区间。
要得到不确定性,你可以训练一个集成(多个不同初始化的网络——它们的分歧表示不确定性)或用贝叶斯近似(把网络权重当作分布,不是固定值)。
在有大量训练数据的区域,预测收敛,不确定性低。
在稀疏区域,预测变化,不确定性高。
这让 UCB 算法知道它在哪里无知,需要探索。
想想天气预报:单个模型给温度预测,但模型集成给一个范围——如果它们都同意,你有信心;如果它们分歧,你不确定。
框架转变
之前(主流方法):              之后(本文方法):

在标注数据上训练分类器       从零标签开始
         |                         |
         v                         v
  查询 -> 分类器 -> 大模型    查询 -> NeuralUCB -> 大模型
         (固定策略)                |
                                   v
                            观察奖励
                                   |
                                   v
                            更新神经网络
                            (适应策略)

静态:无法适应新模型          动态:在线学习
监督:需要预先标注            老虎机:从奖励学习
从离线训练到在线适应,核心转变是把路由当作不确定性下的序列决策,而不是一次性分类问题。
专家评审
选题眼光: 真缺口。
大模型推理成本飙升,模型动物园(GPT-4、Claude、Llama、Gemini、专门微调)不断扩大。
路由是实际瓶颈。
论文正确识别出现有方法要么太僵化(监督)要么太样本饥渴(朴素强化学习)。
这处于实用机器学习系统和老虎机理论的交叉点——及时且扎实。
方法成熟度: 现有理论的可靠应用,不是新算法。
NeuralUCB 从 2020 年就有了(Zhou 等人)。
这里的贡献是认识到大模型路由符合上下文老虎机框架并在 RouterBench 上实现它。
执行称职但不突破——没有新的理论保证,没有架构创新。
一个更简单的线性 UCB 可能是有用的消融,展示神经组件在哪里增加价值。
实验诚意: 基线合理(随机、最小成本、最大质量)但不详尽。
缺少与最近监督路由器(RouteLLM、FrugalGPT)和其他老虎机算法(Thompson 采样、LinUCB)的比较。
“模拟在线设置”有点含糊——查询到底怎么排序?有分布偏移吗?论文显示 NeuralUCB 击败随机和最小成本,这是个低标准。
与最大质量的差距很大,表明方法在困难查询上仍然挣扎。
更多错误分析会有帮助:它在哪些查询类型上路由得差?
写作功力: 摘要和引言清晰,但方法部分单薄——勉强两页。
读者得填补空白:什么神经架构?集成怎么训练?确切的 UCB 公式是什么?实验部分直接跳到结果,没有详细描述设置。
用伪代码和架构图重写方法部分会把论文从”应用笔记”提升到”可复现贡献”。
判决: 弱接收——问题真实,方法合理,结果有希望,但执行感觉仓促,评估不完整。
这是一篇好的研讨会论文或更彻底研究的起点,不是里程碑式贡献。
要点总结
实践者可以偷走这个框架:如果你在多个模型间路由(大模型、视觉模型、语音识别器),把它当作上下文老虎机,不是分类问题。
这让你无需标注数据就能在线适应。
UCB 原则实现简单:维护期望奖励和不确定性的模型,然后选奖励加不确定性奖励最高的动作。
你可以从线性模型开始(便宜、可解释),如果你有复杂上下文特征就升级到神经网络。
关键洞察超越大模型:任何时候你在有不同成本-质量权衡的选项间选择,并且你能观察结果,上下文老虎机都是自然契合。