Paper: 2603.13227 Authors: Helen Qu, Rudy Morel, Michael McCabe, Alberto Bietti, François Lanusse, Shirley Ho, Yann LeCun Categories: cs.LG, cs.CV
The Gap
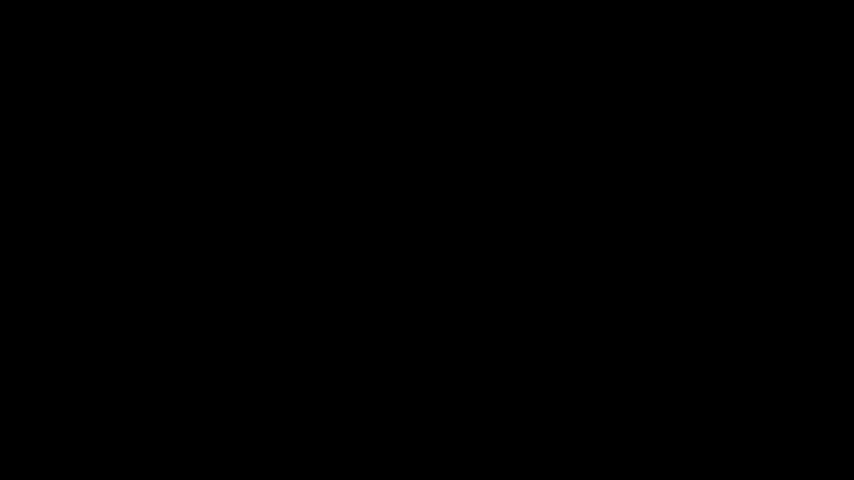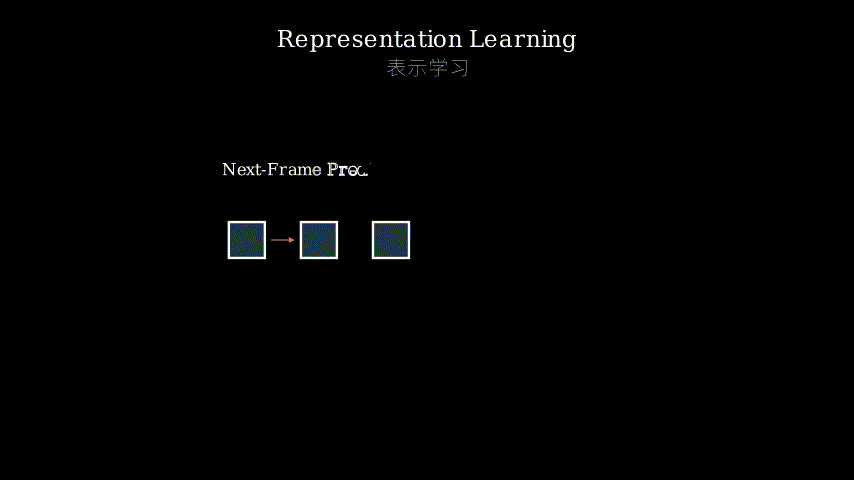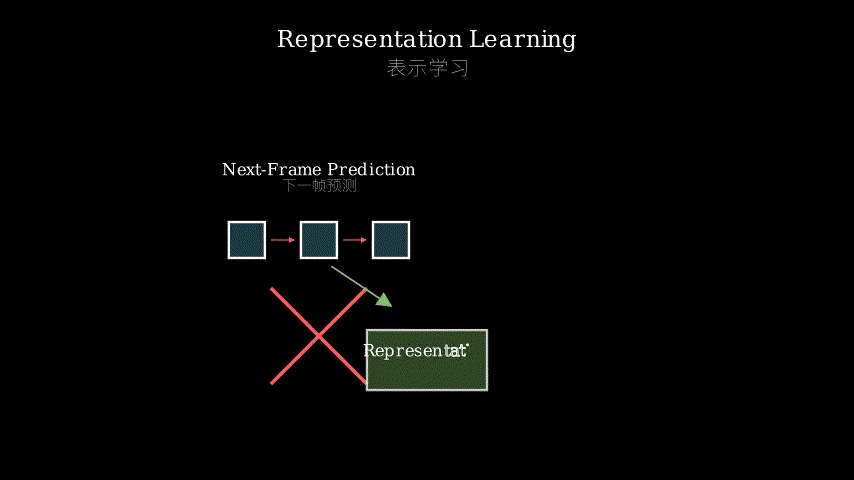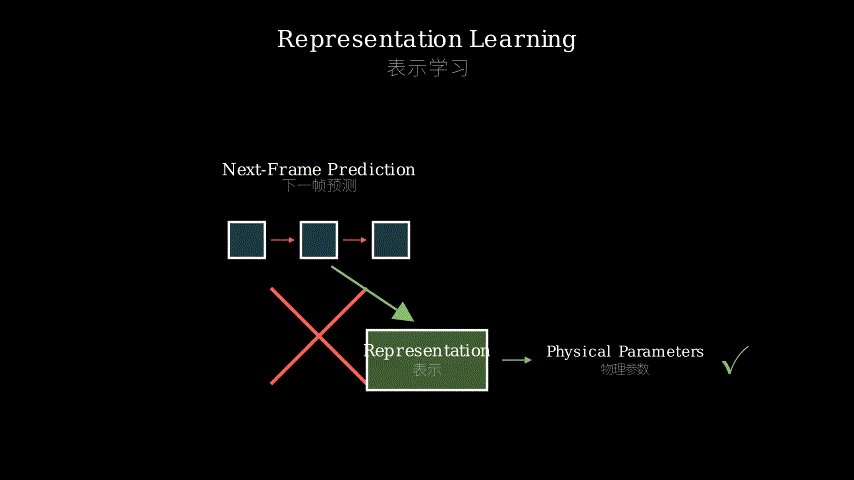
The field has been chasing next-frame prediction as the holy grail for learning from physical systems. Methods like PDE-based neural operators, physics-informed neural networks, and video prediction models all optimize for pixel-level accuracy in predicting future states. But this creates three problems: (1) training is computationally expensive, (2) errors compound during autoregressive rollout, and (3) pixel accuracy doesn’t guarantee physical understanding.
The real gap: scientists don’t just want pretty animations. They want to extract governing parameters (viscosity, diffusion coefficients), predict long-term statistics, and understand physical mechanisms. No one has systematically asked whether next-frame prediction is even the right objective for these downstream scientific tasks.
Problem: Next-frame prediction ≠ physical understanding
   |
   v
Assumption: Representations useful for science
            can be learned without pixel prediction
   |
   v
Method: Evaluate self-supervised methods on
        downstream scientific tasks (parameter estimation)
   |
   v
Evidence: Latent-space methods (JEPAs) outperform
          pixel-level methods on these tasks
   |
   v
Conclusion: Optimize for what you actually need,
            not for pixel reconstruction
The Increment
One sentence: Before this paper, we trained models to predict pixels and hoped they learned physics; after, we have evidence that optimizing latent representations directly is better for actual scientific inference.
Core Mechanism
The method is an evaluation framework, not a new architecture. They take existing self-supervised learning approaches and test them on a battery of scientific tasks. The key components: (1) a frozen encoder trained with various self-supervised objectives (MAE, SimCLR, JEPA variants), (2) simple linear probes or small MLPs trained on top for downstream tasks, (3) evaluation on parameter estimation (e.g., predicting Reynolds number from fluid flow), long-term statistics prediction, and other physics-grounded tasks.
Data flows like this: raw spatiotemporal data (fluid simulations, climate data) → encoder → frozen representations → task-specific probe → scientific prediction. The critical operation is the separation of representation learning from task-specific learning, which isolates what the encoder actually learned about physics.
They compare methods across two axes: (1) pixel-level vs latent-space objectives, and (2) generative vs discriminative approaches. The surprise: methods that never reconstruct pixels (JEPAs) often win.
Input: Spatiotemporal physical data
   |
   v
[Encoder] <-- Trained with self-supervised objective
   |          (MAE, SimCLR, JEPA, etc.)
   v
Frozen representations (latent vectors)
   |
   v
[Linear probe] <-- Trained on downstream task
   |              (parameter estimation, etc.)
   v
Scientific prediction (viscosity, Reynolds #, etc.)

Key insight: Freeze encoder, evaluate on science tasks
Think of this like testing different microscopes by seeing which one helps biologists identify cell types fastest, rather than which one produces the prettiest images. The encoder is the microscope, the downstream task is cell identification, and the frozen representations are what the microscope reveals. Some microscopes (pixel predictors) optimize for image quality but lose information useful for identification. Others (JEPAs) optimize for preserving distinguishing features in a compressed form, which turns out to be more useful for the actual scientific task. The metaphor maps: microscope → encoder, image quality → pixel accuracy, distinguishing features → latent representations, cell identification → parameter estimation.
Key Concepts
-
Joint Embedding Predictive Architecture (JEPA): Instead of predicting raw pixels, predict the representation of future frames in latent space. Imagine you’re learning to forecast weather. A pixel predictor tries to draw every cloud pixel-by-pixel. A JEPA learns abstract features (pressure systems, temperature gradients) and predicts how those features evolve. When you later need to estimate a parameter like humidity, the abstract features are more useful than pixel patterns. JEPAs use two encoders (one for context, one for target) and predict target representations from context representations, avoiding the computational cost of pixel generation.
-
Representation collapse: When a model learns to map all inputs to the same output, making the representation useless. Like a student who answers every exam question with “I don’t know” - technically a valid strategy to minimize effort, but learns nothing. Self-supervised methods fight this with tricks like contrastive losses (push different inputs apart) or variance regularization (ensure representations spread out). The paper shows that methods resistant to collapse (like JEPAs with variance-covariance regularization) learn better physics representations.
Framework Shift
Before (mainstream approach):        After (this paper):

Train model:                         Train model:
[Physical data]                      [Physical data]
      |                                    |
      v                                    v
[Next-frame predictor]               [Self-supervised encoder]
      |                                    |
      v                                    v
[Pixel-level loss]                   [Latent-space objective]

Evaluate:                            Evaluate:
[Rollout accuracy]                   [Freeze encoder]
[Pixel MSE over time]                      |
                                           v
                                     [Train probe on science task]
                                           |
                                           v
                                     [Parameter estimation accuracy]

Focus: Can you predict pixels?       Focus: Can you extract physics?
From “predict the future perfectly” to “learn representations that support scientific inference”, the core shift is evaluation on what scientists actually need rather than what’s easy to measure.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The field has indeed been myopically focused on next-frame prediction, and the authors correctly identify that this doesn’t align with scientific goals. The problem sits at a productive intersection - it’s not just about better architectures, but about rethinking objectives. However, the framing could be sharper: they sometimes conflate “physics-grounded” with “useful for downstream tasks”, which aren’t quite the same thing.
Method maturity: This is primarily an evaluation paper, not a methods paper, which is fine. The experimental design is solid - they compare multiple baselines fairly on the same tasks. However, there’s a missed opportunity: they don’t deeply investigate *why JEPAs work better. Is it the latent-space objective? The architecture? The training dynamics? More ablations would strengthen the claims. The choice to use simple probes is smart (isolates representation quality) but also limits insight into what the representations actually encode.
Experimental integrity: Baselines are reasonable, though I’d want to see more physics-specific methods (e.g., Hamiltonian neural networks, Lagrangian neural networks). The tasks are well-chosen and diverse. One concern: the paper doesn’t discuss computational costs much - if JEPAs are 10x cheaper to train, that’s a huge practical advantage that should be front and center. The results are convincing but not overwhelming - JEPAs win, but not by massive margins in all cases.
Writing quality: The abstract and introduction are clear, but the related work section is too long and doesn’t sufficiently distinguish this work from prior representation learning papers. The results section would benefit from more analysis of failure cases - when do pixel predictors win, and why? The discussion of what makes a representation “physics-grounded” is hand-wavy and could be formalized. If I were reviewing, I’d ask for a clearer definition of this term and metrics to measure it directly.
Verdict: weak accept - solid empirical work that challenges a field assumption, but lacks the theoretical depth or overwhelming empirical evidence for a strong accept. The reframing is valuable, but the execution could be sharper.
Takeaways
For practitioners working with spatiotemporal data (not just physics): consider whether your evaluation metric aligns with your actual goal. If you need to extract parameters or make long-term predictions, optimizing for next-frame pixel accuracy might be the wrong objective. Try latent-space methods like JEPAs, especially if you’re working with high-dimensional data where pixel reconstruction is expensive.
Specific technique to steal: the frozen encoder + simple probe evaluation protocol. This cleanly separates representation quality from task-specific learning and is much cheaper than full fine-tuning. Use it to compare different pretraining strategies on your domain.
For researchers: this paper opens a question more than it answers one. What properties of latent representations make them “physics-grounded”? Can we design objectives that explicitly optimize for these properties? The gap between pixel prediction and scientific utility is real, but we still don’t have a principled theory of what makes a good representation for physical reasoning.
论文: 2603.13227 作者: Helen Qu, Rudy Morel, Michael McCabe, Alberto Bietti, François Lanusse, Shirley Ho, Yann LeCun 分类: cs.LG, cs.CV
缺口
这个领域一直把下一帧预测当作学习物理系统的圣杯。
基于偏微分方程的神经算子、物理信息神经网络、视频预测模型都在优化像素级的未来状态预测精度。
但这带来三个问题:(1)训练计算成本高,(2)自回归展开时误差累积,(3)像素精度不等于物理理解。
真正的缺口在于:科学家不只是想要漂亮的动画。
他们想提取控制参数(粘度、扩散系数),预测长期统计量,理解物理机制。
没人系统地问过:下一帧预测是否是这些下游科学任务的正确目标?
问题:下一帧预测 ≠ 物理理解
   |
   v
假设:对科学有用的表示可以不通过像素预测学到
   |
   v
方法:在下游科学任务(参数估计)上评估自监督方法
   |
   v
证据:潜空间方法(JEPAs)在这些任务上优于像素级方法
   |
   v
结论:优化你真正需要的东西,而非像素重建
增量
一句话:这篇论文之前,我们训练模型预测像素并希望它们学到物理;
之后,我们有证据表明直接优化潜在表示对实际科学推断更好。
核心机制
这个方法是一个评估框架,不是新架构。
他们拿现有的自监督学习方法,在一系列科学任务上测试。
关键组件:(1)用各种自监督目标(MAE、SimCLR、JEPA变体)训练的冻结编码器,(2)在其上训练的简单线性探针或小型MLP用于下游任务,(3)在参数估计(如从流体流动预测雷诺数)、长期统计预测等物理基础任务上评估。
数据流是这样的:原始时空数据(流体模拟、气候数据)→ 编码器 → 冻结表示 → 任务特定探针 → 科学预测。
关键操作是将表示学习与任务特定学习分离,这隔离了编码器实际学到的物理知识。
他们在两个轴上比较方法:(1)像素级vs潜空间目标,(2)生成式vs判别式方法。
意外发现:从不重建像素的方法(JEPAs)经常获胜。
输入:时空物理数据
   |
   v
[编码器] <-- 用自监督目标训练
   |          (MAE, SimCLR, JEPA等)
   v
冻结表示(潜向量)
   |
   v
[线性探针] <-- 在下游任务上训练
   |              (参数估计等)
   v
科学预测(粘度、雷诺数等)

关键洞察:冻结编码器,在科学任务上评估
把这想象成测试不同显微镜,看哪个能帮生物学家最快识别细胞类型,而不是看哪个产生最漂亮的图像。
编码器是显微镜,下游任务是细胞识别,冻结表示是显微镜揭示的东西。
有些显微镜(像素预测器)优化图像质量但丢失了对识别有用的信息。
另一些(JEPAs)优化以压缩形式保留区分特征,这对实际科学任务更有用。
比喻映射:显微镜 → 编码器,图像质量 → 像素精度,区分特征 → 潜在表示,细胞识别 → 参数估计。
关键概念
- 联合嵌入预测架构(JEPA):不预测原始像素,而是在潜空间中预测未来帧的表示。
想象你在学习预测天气。
像素预测器试图逐像素画出每朵云。
JEPA学习抽象特征(气压系统、温度梯度)并预测这些特征如何演化。
当你后来需要估计湿度这样的参数时,抽象特征比像素模式更有用。
JEPAs使用两个编码器(一个用于上下文,一个用于目标)并从上下文表示预测目标表示,避免了像素生成的计算成本。
- 表示坍缩:当模型学会将所有输入映射到相同输出时,使表示变得无用。
就像一个学生在每道考题上都回答”我不知道”——技术上是最小化努力的有效策略,但什么都没学到。
自监督方法用一些技巧对抗这个问题,比如对比损失(把不同输入推开)或方差正则化(确保表示分散开)。
论文表明抗坍缩的方法(如带方差-协方差正则化的JEPAs)学到更好的物理表示。
框架转变
之前(主流方法):                之后(本文方法):

训练模型:                        训练模型:
[物理数据]                        [物理数据]
      |                                |
      v                                v
[下一帧预测器]                    [自监督编码器]
      |                                |
      v                                v
[像素级损失]                      [潜空间目标]

评估:                            评估:
[展开精度]                        [冻结编码器]
[随时间的像素MSE]                      |
                                      v
                                [在科学任务上训练探针]
                                      |
                                      v
                                [参数估计精度]

焦点:你能预测像素吗?            焦点:你能提取物理吗?
从”完美预测未来”到”学习支持科学推断的表示”,核心转变是在科学家真正需要的东西上评估,而不是在容易测量的东西上。
专家评审
选题眼光:这是真缺口,不是人造的。
领域确实过度聚焦于下一帧预测,作者正确识别出这与科学目标不一致。
问题处于一个富有成效的交叉点——不只是关于更好的架构,而是关于重新思考目标。
但框架可以更锐利:他们有时混淆”物理基础”和”对下游任务有用”,这两者不完全相同。
方法成熟度:这主要是评估论文,不是方法论文,这没问题。
实验设计扎实——他们在相同任务上公平比较多个基线。
但有个错失的机会:他们没有深入研究为什么JEPAs效果更好。
是潜空间目标?架构?训练动态?更多消融实验会加强论证。
选择使用简单探针很聪明(隔离表示质量)但也限制了对表示实际编码内容的洞察。
实验诚意:基线合理,但我想看更多物理特定方法(如哈密顿神经网络、拉格朗日神经网络)。
任务选择得好且多样。
一个担忧:论文没怎么讨论计算成本——如果JEPAs训练成本是1/10,这是个巨大的实际优势,应该放在前面。
结果令人信服但不是压倒性的——JEPAs获胜,但不是在所有情况下都大幅领先。
写作功力:摘要和引言清晰,但相关工作部分太长,没有充分区分这项工作与先前表示学习论文的不同。
结果部分会受益于更多失败案例分析——像素预测器什么时候赢,为什么?关于什么使表示”物理基础”的讨论很模糊,可以形式化。
如果我在审稿,我会要求更清晰地定义这个术语和直接测量它的指标。
判决:弱接收——扎实的实证工作挑战了领域假设,但缺乏强接收所需的理论深度或压倒性实证证据。
重新框架有价值,但执行可以更锐利。
要点总结
对于处理时空数据的实践者(不只是物理):考虑你的评估指标是否与实际目标一致。
如果你需要提取参数或做长期预测,优化下一帧像素精度可能是错误目标。
试试潜空间方法如JEPAs,特别是如果你在处理像素重建昂贵的高维数据。
可偷的具体技术:冻结编码器+简单探针评估协议。
这干净地分离了表示质量和任务特定学习,比完全微调便宜得多。
用它在你的领域比较不同的预训练策略。
对研究者:这篇论文提出的问题多于回答的问题。
什么属性使潜在表示”物理基础”?我们能设计明确优化这些属性的目标吗?像素预测和科学效用之间的差距是真实的,但我们仍然没有关于什么构成物理推理良好表示的原则性理论。