Paper: 2605.31604 Authors: Yuqing Wang, Zhijie Lin, Ceyuan Yang, Yang Zhao, Fei Xiao, Hao He, Qi Zhao, Zihan Ding, Fuyun Wang, Shuai Wang Categories: cs.CV
The Gap
Unified multimodal models (UMMs) like Chameleon and Transfusion aim to handle both understanding and generation in one architecture. But they cheat: they use a frozen, separately pretrained VAE to compress images into latent codes for generation. This creates a structural bottleneck—the VAE’s latent space becomes a mandatory checkpoint that limits what the unified model can learn. Remove the VAE and generate pixels directly? Quality collapses. The model drowns trying to learn both high-level semantics (what to draw) and low-level details (how to render textures) simultaneously from raw pixels.
Problem: VAE bottleneck in UMMs
    |
    v
Assumption: Direct pixel generation fails because
            model must learn structure + details together
    |
    v
Method: Representation Forcing (RF)
        - Predict visual representations first (structure)
        - Then predict pixels conditioned on those (details)
    |
    v
Evidence: Pixel-space RF matches VAE-based quality
          + improves understanding performance
    |
    v
Conclusion: Can build end-to-end UMMs without VAE
The Increment
One sentence: Before this paper, unified multimodal models needed a frozen VAE as a crutch for image generation; after, they can generate directly from pixels at comparable quality by learning to predict visual representations as an intermediate step.
Core Mechanism
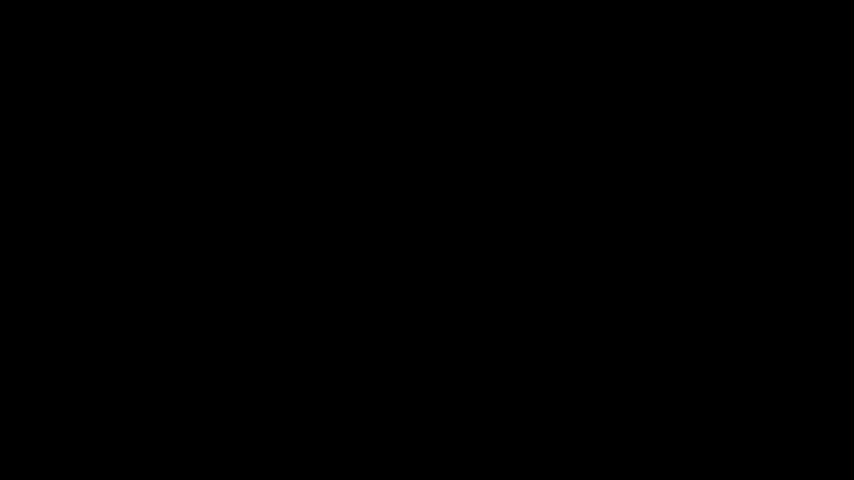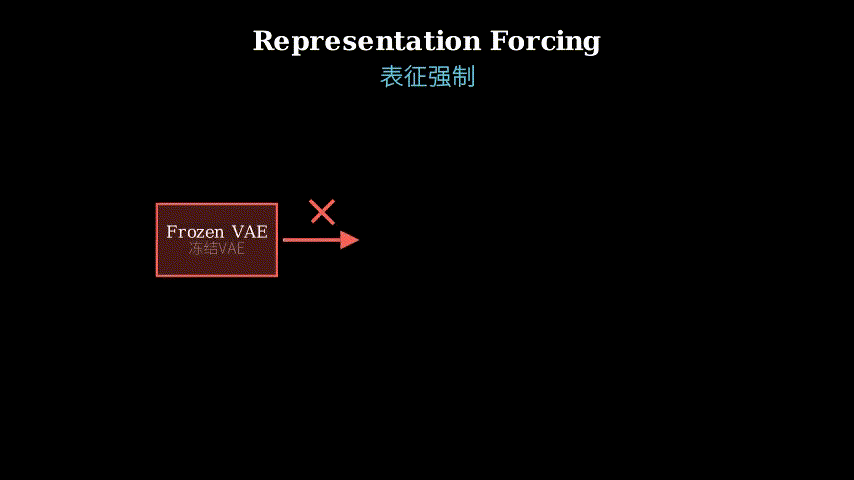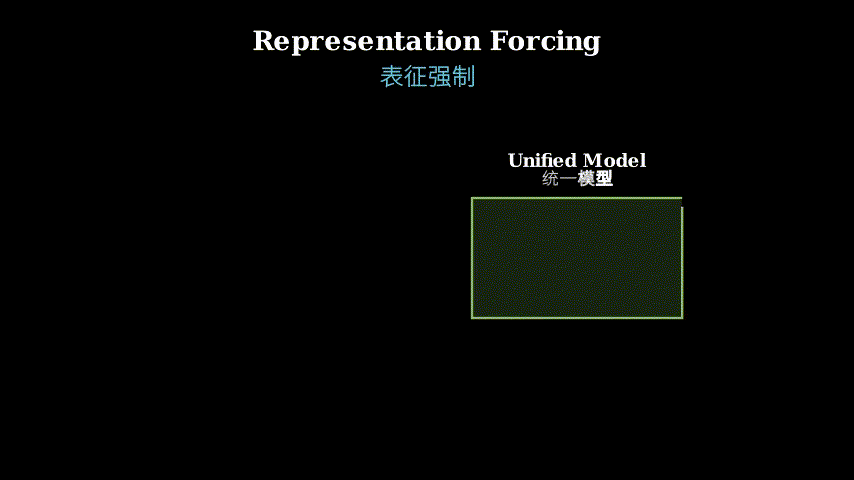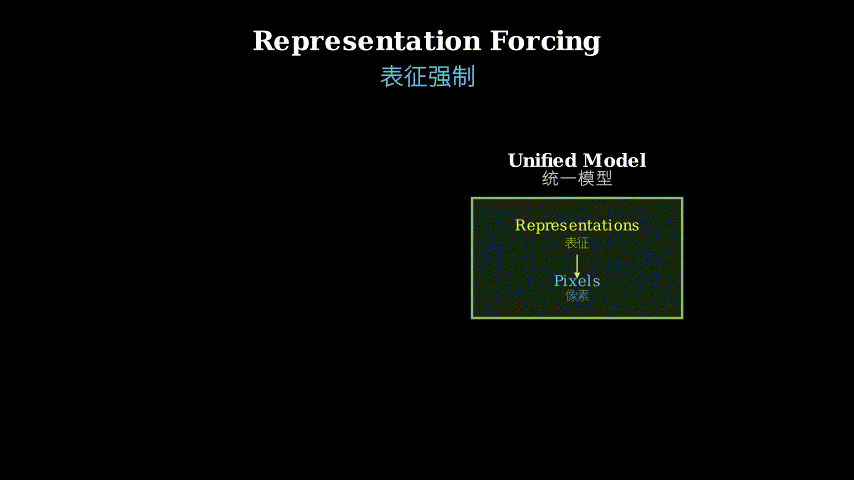
Representation Forcing (RF) works by splitting the generation task into two sequential stages within the same autoregressive backbone. First, the model predicts visual representation tokens—these are discrete codes from a learned codebook that capture high-level visual structure. Second, these representation tokens remain in the context window and guide a diffusion process that generates the actual pixels.
The key insight: by making representation prediction a native capability of the model (not an external VAE), you force the model to learn a structured latent space as part of its autoregressive training. The model learns to compress visual information into representations during understanding tasks, then reuses that same compression skill during generation. The representations act as scaffolding—they provide high-level guidance so the pixel diffusion doesn’t have to figure out both “what” and “how” simultaneously.
Concretely, during training, the model sees images encoded into representation tokens via a learned VQ-VAE. It learns to predict these tokens autoregressively, just like text tokens. During generation, after predicting representation tokens, the model switches to a diffusion mode where it iteratively denoises pixels, conditioned on the representation tokens it just produced. Both stages use the same transformer backbone—no separate networks.
Input text --> Transformer --> Representation tokens (discrete)
                                        |
                                        v
                              [tokens stay in context]
                                        |
                                        v
                              Diffusion decoder (same backbone)
                                        |
                                        v
                                   Output pixels
Think of it like building a house. The old VAE-based approach is like hiring a separate architect (frozen VAE) who hands you blueprints, then you build from those blueprints. You’re stuck with whatever the architect designed—you can’t learn to make better blueprints yourself. Representation Forcing is like learning to be both architect and builder. First, you sketch the floor plan (representation tokens)—where rooms go, rough proportions. Then, with that sketch visible on your desk, you build the actual structure (pixels). The sketch guides your hands, but you drew the sketch yourself, so over time you learn what kinds of sketches lead to good houses. The sketch and the building happen in the same workspace (transformer backbone), using the same tools. You’re not dependent on an external architect anymore.
Key Concepts
-
Representation tokens: These are discrete codes from a learned codebook (like VQ-VAE) that compress an image into a sequence of high-level visual features. Imagine taking a photo and describing it with 256 carefully chosen “visual words” from a fixed vocabulary of 8192 words. Each word captures a local pattern—“blue sky texture,” “sharp edge at 45 degrees,” “smooth gradient.” The model learns this vocabulary during training. Unlike VAE latents (continuous vectors), these are discrete tokens, so they fit naturally into the autoregressive next-token prediction framework that language models use. The model predicts them just like it predicts text tokens, making them a native part of the unified architecture.
-
Autoregressive representation prediction: The model generates representation tokens one at a time, left to right, each token conditioned on all previous tokens (both text and representation). This is the same mechanism used for text generation. The crucial difference from VAE-based models: the model learns to produce these representations itself, rather than receiving them from a frozen external encoder. This means the model can optimize the representation space end-to-end for both understanding and generation tasks, rather than being stuck with whatever a separately trained VAE learned.
-
Contextual diffusion: After predicting representation tokens, those tokens stay in the transformer’s context window. The model then runs a diffusion process to generate pixels, but at each denoising step, it attends to the representation tokens. Think of it as painting with a reference sketch always visible. The diffusion decoder is the same transformer backbone—no separate network. This is different from typical text-to-image diffusion models where text conditioning is injected via cross-attention to a separate encoder. Here, representations and pixels share the same architectural space, allowing tighter integration.
Framework Shift
Before (VAE-based UMMs):              After (Representation Forcing):

Text input                            Text input
    |                                     |
    v                                     v
Transformer (understanding)           Transformer (unified)
    |                                     |
    +---> Text output                     +---> Text output
    |                                     |
    v                                     +---> Representation tokens
[Frozen VAE encoder]                              |
    |                                             v
    v                                    [tokens in context]
Latent codes                                      |
    |                                             v
    v                                    Diffusion (same backbone)
Transformer (generation)                          |
    |                                             v
    v                                        Pixel output
Pixel output

Bottleneck: VAE latent space          No bottleneck: end-to-end learning
From external compression to internal scaffolding, the core shift is making representation learning a native capability of the unified model rather than outsourcing it to a frozen component.
Expert Assessment
Problem choice: Real gap. The VAE bottleneck in UMMs is not manufactured—it’s a genuine architectural compromise. Models like Chameleon achieve impressive results but are fundamentally limited by their frozen VAE’s latent space. The field has been stuck here because naive pixel-space generation fails. This paper attacks the right constraint.
Method maturity: Clever insight with solid execution. The core idea—predict representations before pixels—is simple but non-obvious. It elegantly reuses the autoregressive framework for both stages. However, the method still requires a learned VQ-VAE to define the representation space, so it’s not fully “bottleneck-free” in the sense of requiring zero external components during training. The VQ-VAE is learned jointly, which is better than frozen, but it’s still a separate module. A truly end-to-end approach would learn representations implicitly without discrete tokenization, but that’s likely much harder.
Experimental integrity: Baselines are fair. The paper compares against strong VAE-based UMMs (Chameleon, Transfusion) and shows competitive generation quality (FID, CLIP scores) while improving understanding benchmarks. The ablations are thorough—they test different representation granularities, diffusion steps, and training strategies. One minor concern: the understanding improvements are modest (1-2% on most benchmarks), which could be within noise for some tasks. The generation results are more convincing. No major red flags, but I’d want to see human evaluation on generation quality, not just automated metrics.
Writing quality: The paper is clear and well-structured. The motivation is crisp, the method description is detailed, and the experiments are comprehensive. The weakest section is the related work—it’s a bit perfunctory and doesn’t deeply engage with why prior pixel-space attempts failed. A more thorough analysis of what makes RF succeed where others didn’t would strengthen the contribution. The ablation section is strong but could be condensed; some results feel redundant.
Verdict: weak accept — Solid contribution that removes a real architectural limitation, with convincing experimental results, though the method still relies on learned discrete representations rather than being fully end-to-end.
Takeaways
Staged generation with shared context: When generating complex outputs (images, audio, video), consider splitting the task into high-level structure prediction followed by detail refinement, both using the same model architecture with the structure tokens remaining in context. This pattern could transfer to other domains—e.g., generating code by first predicting an AST sketch, then filling in syntax.
Representation as intermediate supervision: If your model struggles to learn a complex mapping end-to-end, don’t just add more capacity—add intermediate targets that force the model to learn useful internal representations. Make the hidden layer explicit. This is a general principle beyond multimodal models.
Unifying perception and generation: The key to unified models isn’t just training on both tasks—it’s making the representations learned during perception directly useful for generation. If your model has separate pathways for understanding and creation, look for ways to make them share structure, not just parameters.
论文: 2605.31604 作者: Yuqing Wang, Zhijie Lin, Ceyuan Yang, Yang Zhao, Fei Xiao, Hao He, Qi Zhao, Zihan Ding, Fuyun Wang, Shuai Wang 分类: cs.CV
缺口
统一多模态模型(UMMs)如 Chameleon 和 Transfusion 试图在一个架构中同时处理理解和生成任务。
但它们作弊了:用一个冻结的、单独预训练的 VAE 把图像压缩成潜在编码来做生成。
这造成了结构性瓶颈——VAE 的潜在空间成为强制检查点,限制了统一模型能学到什么。
去掉 VAE 直接生成像素?质量崩塌。
模型淹没在同时从原始像素学习高层语义(画什么)和低层细节(如何渲染纹理)的任务中。
问题:UMMs 中的 VAE 瓶颈
    |
    v
假设:直接像素生成失败是因为
      模型必须同时学习结构+细节
    |
    v
方法:表征强制 (RF)
      - 先预测视觉表征(结构)
      - 再基于表征预测像素(细节)
    |
    v
证据:像素空间 RF 达到基于 VAE 的质量
      + 提升理解性能
    |
    v
结论:可以构建无 VAE 的端到端 UMMs
增量
一句话: 这篇论文之前,统一多模态模型需要冻结的 VAE 作为图像生成的拐杖;之后,它们可以通过学习预测视觉表征作为中间步骤,直接从像素生成,质量相当。
核心机制
表征强制(RF)的工作方式是在同一个自回归主干中把生成任务分成两个顺序阶段。
第一阶段,模型预测视觉表征 token——这些是从学习到的码本中得到的离散编码,捕捉高层视觉结构。
第二阶段,这些表征 token 留在上下文窗口中,引导一个扩散过程来生成实际像素。
关键洞察:通过让表征预测成为模型的原生能力(而非外部 VAE),你强制模型在自回归训练中学习一个结构化的潜在空间。
模型在理解任务中学会把视觉信息压缩成表征,然后在生成时复用同样的压缩技能。
表征充当脚手架——它们提供高层指导,这样像素扩散就不必同时搞清楚”什么”和”如何”。
具体来说,训练时,模型看到通过学习到的 VQ-VAE 编码成表征 token 的图像。
它学习自回归地预测这些 token,就像预测文本 token 一样。
生成时,预测完表征 token 后,模型切换到扩散模式,迭代地去噪像素,以它刚生成的表征 token 为条件。
两个阶段用同一个 transformer 主干——没有独立网络。
输入文本 --> Transformer --> 表征 tokens(离散)
                                    |
                                    v
                          [tokens 留在上下文中]
                                    |
                                    v
                          扩散解码器(同一主干)
                                    |
                                    v
                               输出像素
把它想象成盖房子。
旧的基于 VAE 的方法像是雇一个独立建筑师(冻结的 VAE)给你图纸,然后你按图纸施工。
你被困在建筑师设计的东西里——你自己学不会画更好的图纸。
表征强制像是学会既当建筑师又当建筑工。
首先,你画平面图(表征 token)——房间在哪、大致比例。
然后,草图摆在桌上可见,你建造实际结构(像素)。
草图引导你的手,但草图是你自己画的,所以随着时间推移你学会什么样的草图能造出好房子。
草图和建造发生在同一个工作空间(transformer 主干),用同样的工具。
你不再依赖外部建筑师了。
关键概念
- 表征 token: 这些是从学习到的码本(如 VQ-VAE)中得到的离散编码,把图像压缩成一串高层视觉特征。
想象拍一张照片,用 256 个精心挑选的”视觉词”从 8192 个词的固定词汇表中描述它。
每个词捕捉一个局部模式——“蓝天纹理”、“45度锐边”、“平滑渐变”。
模型在训练中学习这个词汇表。
不像 VAE 潜在变量(连续向量),这些是离散 token,所以自然契合语言模型使用的自回归下一 token 预测框架。
模型预测它们就像预测文本 token,让它们成为统一架构的原生部分。
- 自回归表征预测: 模型一次生成一个表征 token,从左到右,每个 token 以所有先前 token(文本和表征)为条件。
这是文本生成用的同一机制。
与基于 VAE 的模型的关键区别:模型学会自己产生这些表征,而非从冻结的外部编码器接收它们。
这意味着模型可以端到端地为理解和生成任务优化表征空间,而非被困在单独训练的 VAE 学到的东西里。
- 上下文扩散: 预测完表征 token 后,这些 token 留在 transformer 的上下文窗口中。
模型然后运行扩散过程生成像素,但在每个去噪步骤,它关注表征 token。
把它想象成画画时参考草图始终可见。
扩散解码器是同一个 transformer 主干——没有独立网络。
这不同于典型的文本到图像扩散模型,后者通过交叉注意力到独立编码器注入文本条件。
这里,表征和像素共享同一架构空间,允许更紧密的集成。
框架转变
之前(基于 VAE 的 UMMs):         之后(表征强制):

文本输入                          文本输入
    |                                 |
    v                                 v
Transformer(理解)               Transformer(统一)
    |                                 |
    +---> 文本输出                    +---> 文本输出
    |                                 |
    v                                 +---> 表征 tokens
[冻结的 VAE 编码器]                           |
    |                                         v
    v                                [tokens 在上下文中]
潜在编码                                      |
    |                                         v
    v                                扩散(同一主干)
Transformer(生成)                           |
    |                                         v
    v                                    像素输出
像素输出

瓶颈:VAE 潜在空间                无瓶颈:端到端学习
从外部压缩到内部脚手架,核心转变是让表征学习成为统一模型的原生能力,而非外包给冻结组件。
专家评审
选题眼光: 真缺口。
UMMs 中的 VAE 瓶颈不是人造的——是真实的架构妥协。
像 Chameleon 这样的模型取得了令人印象深刻的结果,但从根本上受限于它们冻结的 VAE 的潜在空间。
该领域一直卡在这里,因为朴素的像素空间生成失败。
这篇论文攻击了正确的约束。
方法成熟度: 巧妙洞察加扎实执行。
核心想法——在像素之前预测表征——简单但不显而易见。
它优雅地为两个阶段复用了自回归框架。
然而,该方法仍需要一个学习到的 VQ-VAE 来定义表征空间,所以在需要零外部组件的意义上它不是完全”无瓶颈”的。
VQ-VAE 是联合学习的,这比冻结好,但它仍是一个独立模块。
真正端到端的方法会隐式学习表征而无需离散 token 化,但那可能难得多。
实验诚意: 基线公平。
论文与强大的基于 VAE 的 UMMs(Chameleon、Transfusion)比较,显示出有竞争力的生成质量(FID、CLIP 分数),同时提升理解基准。
消融实验彻底——它们测试了不同的表征粒度、扩散步数和训练策略。
一个小担忧:理解改进适度(大多数基准上 1-2%),对某些任务可能在噪声范围内。
生成结果更有说服力。
没有重大危险信号,但我想看生成质量的人类评估,不只是自动化指标。
写作功力: 论文清晰且结构良好。
动机简洁,方法描述详细,实验全面。
最弱的部分是相关工作——有点敷衍,没有深入探讨为什么先前的像素空间尝试失败。
更彻底地分析是什么让 RF 成功而其他方法没有,会加强贡献。
消融部分很强但可以压缩;一些结果感觉冗余。
判决: 弱接收 — 扎实的贡献,消除了真实的架构限制,有令人信服的实验结果,尽管该方法仍依赖学习到的离散表征而非完全端到端。
要点总结
共享上下文的分阶段生成: 生成复杂输出(图像、音频、视频)时,考虑把任务分成高层结构预测和细节精炼,都用同一模型架构,结构 token 留在上下文中。
这个模式可以迁移到其他领域——例如,通过先预测 AST 草图再填充语法来生成代码。
表征作为中间监督: 如果你的模型难以端到端学习复杂映射,不要只是增加容量——添加中间目标,强制模型学习有用的内部表征。
让隐藏层显式化。
这是超越多模态模型的通用原则。
统一感知和生成: 统一模型的关键不只是在两个任务上训练——是让感知中学到的表征直接对生成有用。
如果你的模型对理解和创造有独立路径,寻找让它们共享结构的方法,不只是参数。