Paper: 2604.11554 Authors: Liujie Zhang, Benzhe Ning, Rui Yang, Xiaoyan Yu, Jiaxing Li, Lumeng Wu, Jia Liu, Minghao Li, Weihang Chen, Weiqi Hu Categories: cs.CL
The Gap
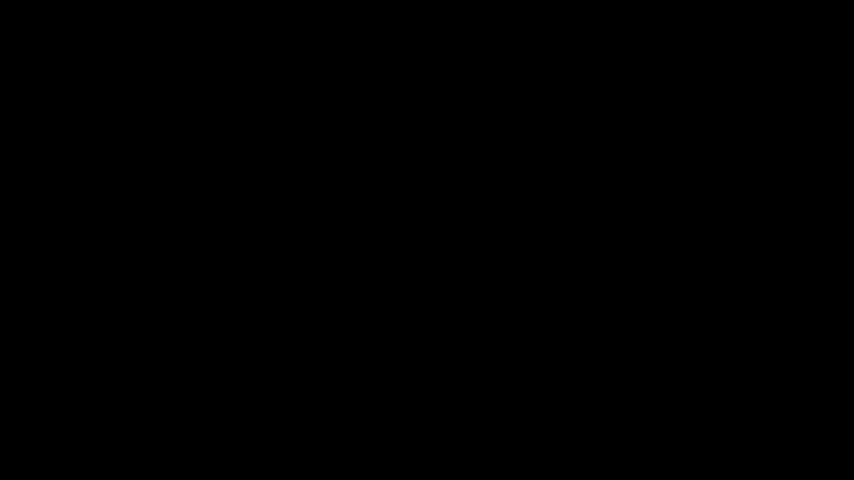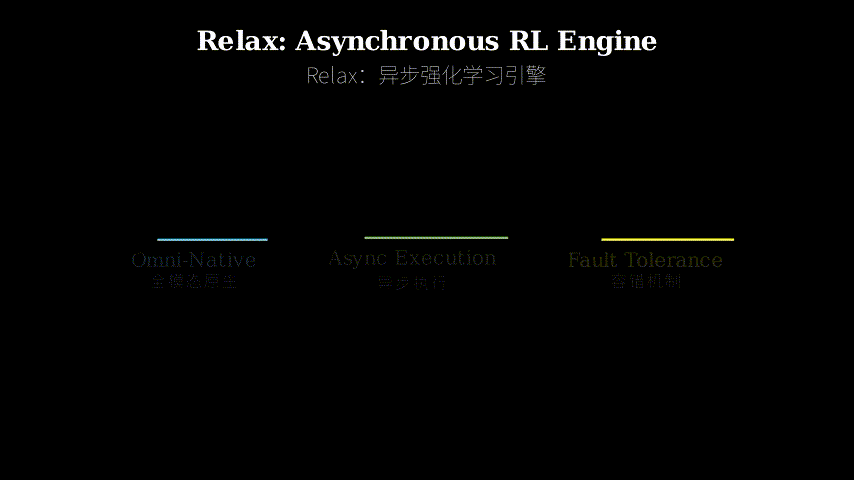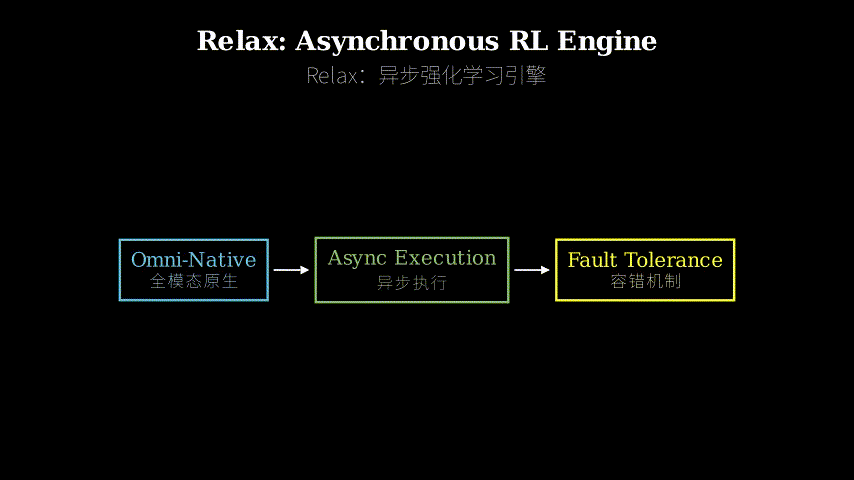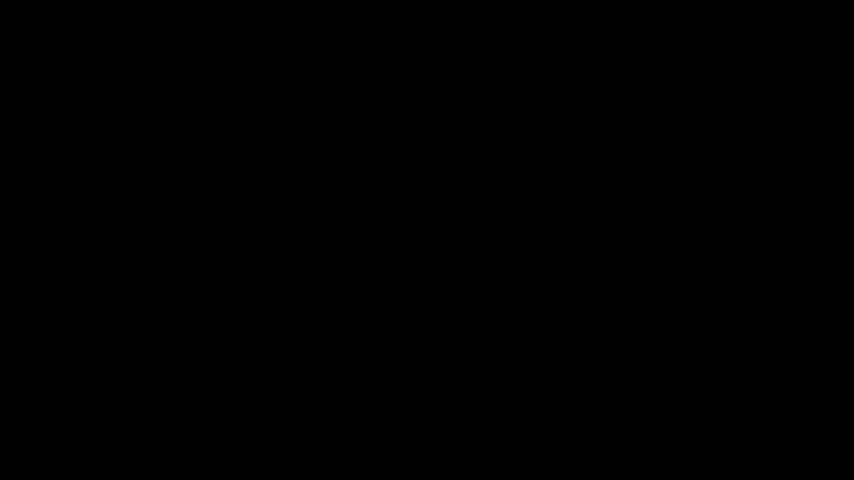
RL post-training (RLHF, PPO, etc.) has unlocked reasoning in LLMs, but existing systems like veRL and OpenRLHF were built for text-only, single-turn scenarios. Now models handle images, audio, video, and multi-turn agentic workflows. Three walls appeared: (1) Heterogeneous data flows — text pipelines can’t handle variable-sized images or streaming audio without hacky retrofits. (2) Operational fragility — tightly coupled components mean one GPU failure kills the entire training run. (3) Staleness-throughput tradeoff — strict on-policy training is slow; going fully async risks divergence. Prior systems force you to pick speed or stability, not both.
Problem: Omni-modal RL at scale
    |
    v
Assumption: Service decoupling + async execution can maintain convergence
    |
    v
Method: Three-layer architecture (omni-native / fault-isolated / async queue)
    |
    v
Evidence: 2× speedup on 30B model, stable convergence across modalities
    |
    v
Conclusion: Async RL works if you design the right staleness control
The Increment
One sentence: Before Relax, you chose between slow on-policy training or risky async speedups; after Relax, a single staleness knob smoothly trades off speed and convergence while natively handling video, audio, and text in one system.
Core Mechanism
Relax splits RL training into independent services: Rollout (generates trajectories), Trainer (updates policy), Critic (scores actions), and Reference (provides KL penalty). Each service runs in its own process with isolated fault recovery. Between them sits TransferQueue, a data bus that decouples producers from consumers. When Rollout finishes a batch, it pushes to the queue and immediately starts the next batch — no waiting for Trainer to finish. Trainer pulls from the queue whenever ready, even if the data is a few steps stale.
The staleness parameter τ controls how old data can be. τ=0 is strict on-policy (wait for fresh data). τ=∞ is fully async (use whatever’s available). τ=2 means “use data up to 2 training steps old.” This turns the binary choice (sync vs async) into a continuous dial.
For multimodal data, Relax doesn’t bolt modalities onto a text pipeline. It treats each modality as a first-class citizen from data loading through inference. Images get their own preprocessing, audio streams through dedicated buffers, video frames are batched with temporal awareness. The parallelism strategy adapts per modality — text uses sequence parallelism, images use tensor parallelism, video uses a hybrid.
Rollout Service          TransferQueue           Trainer Service
[Generate batch 1] ---> [Queue: batch 1] ---> [Update policy w/ batch 1]
[Generate batch 2] ---> [Queue: batch 2]      [Still working on batch 1...]
[Generate batch 3] ---> [Queue: batch 3]      [Now pull batch 2, update]
     ^                        |                        |
     |                        v                        v
  (no wait)            (staleness buffer)        (async pull)
Think of Relax like a restaurant kitchen. Old RL systems (veRL) are like a single chef who must finish cooking one dish before starting the next — if the stove breaks, service stops. Relax is a brigade: one station preps ingredients (Rollout), another cooks (Trainer), another plates (Critic). Between stations are pass-through windows (TransferQueue). The prep station doesn’t wait for the cook to finish — it keeps prepping and slides dishes through the window. The cook grabs whatever’s ready, even if it sat for a minute. The staleness parameter is like “how long can a prepped dish sit before we toss it?” Fresh dishes (τ=0) mean slower service but perfect quality. Older dishes (τ=2) mean faster throughput with slight quality variance. The kitchen keeps running even if one station’s equipment fails — just swap in a backup.
Key Concepts
-
Staleness in RL: In on-policy RL (like PPO), the policy must be updated with trajectories generated by the current policy. If you use old trajectories (generated by a past policy), that’s “stale data.” Traditional wisdom says staleness breaks convergence because the policy distribution shifts. Relax’s insight: small staleness (τ=1-2 steps) barely shifts the distribution, but massively improves throughput because services don’t block each other. It’s like training on yesterday’s data — not ideal, but close enough if “yesterday” was only 30 seconds ago in wall-clock time.
-
Omni-native architecture: Most multimodal systems are text pipelines with image/audio bolted on. You tokenize images into patches, treat them like text, and hope for the best. This fails for video (too many tokens) and audio (streaming doesn’t fit batch processing). Omni-native means each modality has its own data path from disk to GPU, with modality-specific parallelism and memory management. Text gets sequence parallelism (split along sequence length), images get tensor parallelism (split the model), video gets pipeline parallelism (split across time). It’s not “make everything look like text” — it’s “give each modality what it needs.”
-
Service-level fault isolation: In monolithic RL systems, all components (rollout, training, critic) run in one process. A single GPU OOM kills everything. Relax runs each component as a separate service with its own process and memory space. If Rollout crashes, Trainer keeps running on queued data while Rollout restarts. If a GPU dies, only that service’s replica fails — others continue. Recovery is local, not global. It’s the difference between a power outage shutting down your whole house vs. just one room’s circuit breaker tripping.
Framework Shift
Before (veRL, OpenRLHF):              After (Relax):

Rollout --> Trainer --> Critic        Rollout ----+
   |           |          |                        |
(tightly coupled, sync)                            v
   |           |          |                   TransferQueue
(one fails, all stop)                              |
                                                   v
                                              Trainer ----+
                                                          |
                                                          v
                                                      Critic
                                              (decoupled, async)
                                              (isolated failures)
From synchronous monolith to asynchronous microservices, the core shift is trading coordination overhead for independent scalability.
Expert Assessment
Problem choice: Real gap. As models go multimodal and agentic, existing RL infrastructure genuinely breaks. The paper targets a pain point that will only grow (video RL, long-horizon agents). Not manufactured — this is where the field is heading.
Method maturity: Solid engineering, not a research breakthrough. The async RL idea isn’t new (A3C did it in 2016), but applying it to modern RLHF with proper staleness control is valuable. The omni-native architecture is mostly plumbing — necessary plumbing, but not conceptually novel. The service decoupling is borrowed from distributed systems. What’s clever is the integration: making these three ideas work together at scale.
Experimental integrity: Baselines are fair (veRL is the current standard). The 2× speedup on 30B models is believable and well-documented. The convergence curves look clean — all methods reach similar final reward, which validates the staleness approach. One concern: experiments are mostly on Qwen models from the same institution. Would love to see results on Llama or other architectures. The R3 MoE comparison (1.9% overhead vs 32% in veRL) is striking but only shown on one setup.
Writing quality: The paper front-loads architecture diagrams before motivating why each piece exists. Section 3 (architecture) should come after Section 4 (challenges). The related work is thin — doesn’t engage with distributed RL literature (Impala, Seed RL) or explain why their approaches don’t transfer. The experimental section is strong but could use ablations on staleness values (only τ=0 and τ=2 are tested, what about τ=1, 3, 5?).
Verdict: Weak accept — this is a well-executed systems paper that solves a real problem, but the novelty is in integration rather than new ideas. The open-source release adds value. It’ll be cited by practitioners, less by theorists.
Takeaways
Staleness as a hyperparameter: Don’t treat sync vs async as a binary choice. Expose staleness as a tunable parameter and sweep it. Small staleness (1-2 steps) often gives 80% of async speedup with 95% of sync stability.
Service boundaries for fault tolerance: If your training pipeline has distinct stages (data generation, model update, evaluation), run them as separate processes with a queue between. One crash doesn’t kill the whole job. This applies beyond RL — any long-running ML training benefits.
Modality-specific parallelism: Stop forcing all modalities through the same pipeline. Text, images, and video have different memory/compute profiles. Design separate data paths and choose parallelism strategies per modality. The performance gains are non-trivial (2× in this paper).
TransferQueue pattern: A bounded queue between producer/consumer services is a simple but powerful decoupling mechanism. The producer never blocks (unless queue is full), the consumer pulls when ready. Add a staleness check (drop data older than τ steps) and you have async execution with bounded divergence. Steal this pattern for any multi-stage pipeline.
论文: 2604.11554 作者: Liujie Zhang, Benzhe Ning, Rui Yang, Xiaoyan Yu, Jiaxing Li, Lumeng Wu, Jia Liu, Minghao Li, Weihang Chen, Weiqi Hu 分类: cs.CL
缺口
强化学习后训练(RLHF、PPO等)已经解锁了大语言模型的推理能力,但现有系统如veRL和OpenRLHF是为纯文本、单轮场景设计的。
现在模型要处理图像、音频、视频和多轮智能体工作流。
三堵墙出现了:(1)异构数据流 —— 文本管道无法优雅处理可变大小的图像或流式音频,只能打补丁。
(2)运维脆弱性 —— 紧耦合组件意味着一块GPU故障就会导致整个训练崩溃。
(3)陈旧度-吞吐量权衡 —— 严格的on-policy训练很慢;
完全异步又有发散风险。
现有系统逼你在速度和稳定性之间二选一。
问题:大规模全模态强化学习
    |
    v
假设:服务解耦 + 异步执行可以保持收敛
    |
    v
方法:三层架构(原生多模态 / 故障隔离 / 异步队列)
    |
    v
证据:30B模型上2倍加速,跨模态稳定收敛
    |
    v
结论:设计合适的陈旧度控制,异步强化学习可行
增量
一句话: Relax之前,你要在慢速on-policy训练和有风险的异步加速之间二选一;
Relax之后,一个陈旧度旋钮就能平滑权衡速度和收敛性,同时在一个系统里原生处理视频、音频和文本。
核心机制
Relax把强化学习训练拆成独立服务:Rollout(生成轨迹)、Trainer(更新策略)、Critic(评分动作)、Reference(提供KL惩罚)。
每个服务运行在独立进程中,有隔离的故障恢复机制。
它们之间是TransferQueue,一条解耦生产者和消费者的数据总线。
Rollout完成一批数据后推入队列,立即开始下一批 —— 不等Trainer完成。
Trainer随时从队列拉取,即使数据已经过时几步。
陈旧度参数τ控制数据可以多旧。
τ=0是严格on-policy(等待新鲜数据)。
τ=∞是完全异步(用任何可用数据)。
τ=2意味着”使用最多2个训练步之前的数据”。
这把二元选择(同步vs异步)变成了连续旋钮。
对于多模态数据,Relax不是把模态硬塞进文本管道。
它从数据加载到推理都把每种模态当作一等公民。
图像有自己的预处理,音频通过专用缓冲区流动,视频帧带时序感知地批处理。
并行策略按模态适配 —— 文本用序列并行,图像用张量并行,视频用混合并行。
Rollout服务           TransferQueue           Trainer服务
[生成批次1] ---> [队列:批次1] ---> [用批次1更新策略]
[生成批次2] ---> [队列:批次2]      [还在处理批次1...]
[生成批次3] ---> [队列:批次3]      [现在拉取批次2,更新]
     ^                  |                    |
     |                  v                    v
  (不等待)         (陈旧度缓冲)         (异步拉取)
把Relax想象成餐厅厨房。
旧的强化学习系统(veRL)像单个厨师必须做完一道菜才能开始下一道 —— 炉子坏了,服务就停了。
Relax是厨师团队:一个工位备菜(Rollout),另一个烹饪(Trainer),还有一个摆盘(Critic)。
工位之间是传菜窗口(TransferQueue)。
备菜工位不等厨师做完 —— 它持续备菜,把菜品推过窗口。
厨师抓取任何准备好的,即使放了一分钟。
陈旧度参数就像”备好的菜能放多久才扔掉?”
新鲜菜品(τ=0)意味着服务慢但质量完美。
稍旧菜品(τ=2)意味着吞吐量更快,质量略有波动。
即使一个工位的设备故障,厨房也能继续运转 —— 换个备用的就行。
关键概念
- 强化学习中的陈旧度: 在on-policy强化学习(如PPO)中,策略必须用当前策略生成的轨迹来更新。
如果用旧轨迹(由过去策略生成),那就是”陈旧数据”。
传统观点认为陈旧度会破坏收敛,因为策略分布发生了偏移。
Relax的洞察:小陈旧度(τ=1-2步)几乎不偏移分布,但大幅提升吞吐量,因为服务之间不互相阻塞。
就像用昨天的数据训练 —— 不理想,但如果”昨天”在墙上时钟只是30秒前,就足够接近了。
- 原生多模态架构: 大多数多模态系统是文本管道加上硬塞的图像/音频。
你把图像分块token化,当文本处理,然后祈祷。
这对视频(token太多)和音频(流式不适合批处理)会失败。
原生多模态意味着每种模态从磁盘到GPU都有自己的数据路径,有模态特定的并行和内存管理。
文本用序列并行(沿序列长度切分),图像用张量并行(切分模型),视频用流水线并行(沿时间切分)。
不是”让一切看起来像文本” —— 而是”给每种模态它需要的东西”。
- 服务级故障隔离: 在单体强化学习系统中,所有组件(rollout、训练、critic)运行在一个进程里。
单个GPU内存溢出就杀死一切。
Relax把每个组件作为独立服务运行,有自己的进程和内存空间。
如果Rollout崩溃,Trainer继续用队列中的数据运行,同时Rollout重启。
如果GPU挂了,只有那个服务的副本失败 —— 其他继续。
恢复是局部的,不是全局的。
这是整个房子断电和只有一个房间的断路器跳闸的区别。
框架转变
之前(veRL、OpenRLHF):          之后(Relax):

Rollout --> Trainer --> Critic    Rollout ----+
   |           |          |                     |
(紧耦合,同步)                                v
   |           |          |                TransferQueue
(一个失败,全部停止)                           |
                                               v
                                          Trainer ----+
                                                      |
                                                      v
                                                  Critic
                                          (解耦,异步)
                                          (隔离故障)
从同步单体到异步微服务,核心转变是用协调开销换独立可扩展性。
专家评审
选题眼光: 真实缺口。
随着模型走向多模态和智能体化,现有强化学习基础设施确实会崩溃。
论文瞄准的痛点只会越来越大(视频强化学习、长时程智能体)。
不是人造的 —— 这是领域的走向。
方法成熟度: 扎实的工程,不是研究突破。
异步强化学习的想法不新(A3C在2016年就做了),但把它应用到现代RLHF并配上合适的陈旧度控制是有价值的。
原生多模态架构主要是管道工程 —— 必要的管道,但概念上不新颖。
服务解耦借鉴自分布式系统。
巧妙之处在于集成:让这三个想法在规模上协同工作。
实验诚意: 基线公平(veRL是当前标准)。
30B模型上的2倍加速可信且有充分文档。
收敛曲线看起来干净 —— 所有方法达到相似的最终奖励,验证了陈旧度方法。
一个担忧:实验主要在同一机构的Qwen模型上。
希望看到Llama或其他架构上的结果。
R3 MoE对比(1.9%开销 vs veRL的32%)很惊人,但只在一个配置上展示。
写作功力: 论文在解释每个部分存在的必要性之前就堆砌架构图。
第3节(架构)应该放在第4节(挑战)之后。
相关工作单薄 —— 没有与分布式强化学习文献(Impala、Seed RL)交锋,也没解释为什么它们的方法不能迁移。
实验部分很强,但缺少陈旧度值的消融(只测试了τ=0和τ=2,τ=1、3、5呢?)。
判决: 弱接收 —— 这是一篇执行良好的系统论文,解决了真实问题,但新颖性在于集成而非新想法。
开源发布增加了价值。
会被实践者引用,理论家较少。
要点总结
陈旧度作为超参数: 不要把同步vs异步当二元选择。
把陈旧度暴露为可调参数并扫描它。
小陈旧度(1-2步)通常能获得异步加速的80%,同时保持同步稳定性的95%。
服务边界实现容错: 如果你的训练管道有明确阶段(数据生成、模型更新、评估),把它们作为独立进程运行,中间用队列连接。
一个崩溃不会杀死整个任务。
这超越强化学习 —— 任何长时运行的机器学习训练都受益。
模态特定并行: 停止强迫所有模态通过同一管道。
文本、图像和视频有不同的内存/计算特征。
设计独立数据路径,按模态选择并行策略。
性能增益不小(本文中2倍)。
TransferQueue模式: 生产者/消费者服务之间的有界队列是简单但强大的解耦机制。
生产者永不阻塞(除非队列满),消费者随时拉取。
加上陈旧度检查(丢弃超过τ步的数据),你就有了有界发散的异步执行。
把这个模式偷走用于任何多阶段管道。