Paper: 2606.27369 Authors: Yingyu Lin, Qiyue Gao, Nikki Lijing Kuang, Xunpeng Huang, Kun Zhou, Tongtong Liang, Zhewei Yao, Yi-An Ma, Yuxiong He Categories: cs.LG
The Gap
Existing RLVR (reinforcement learning with verifiable rewards) assumes a ground-truth answer exists for each task — you compare the model’s output to the answer and assign +1 or 0. This works for math, code correctness, etc. But many real-world tasks (heuristic search, optimization, creative design) have no unique correct answer. Prior work either avoided RL or used hand-crafted reward models. Neither scales.
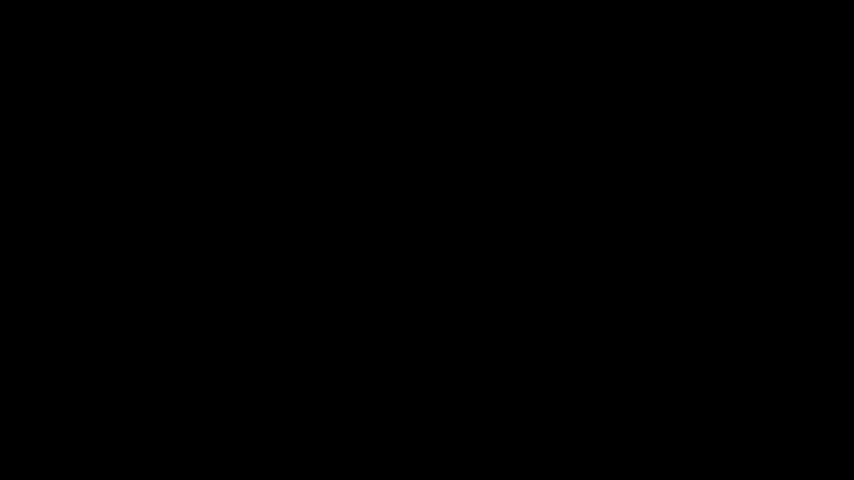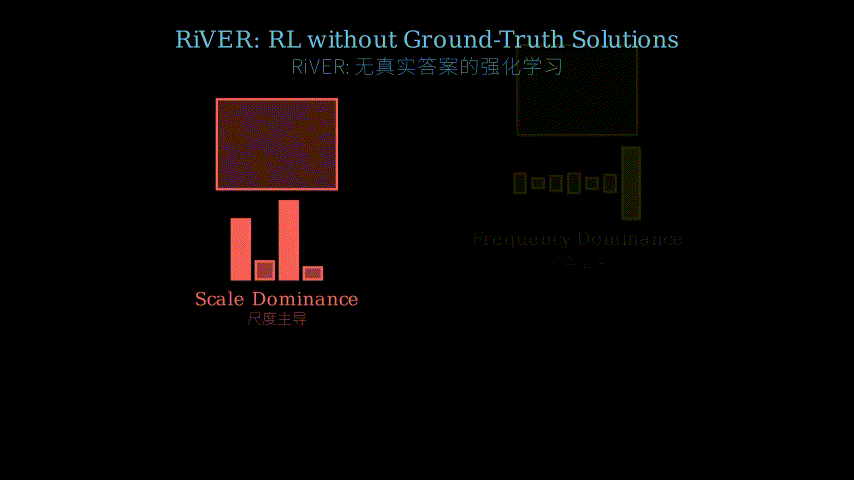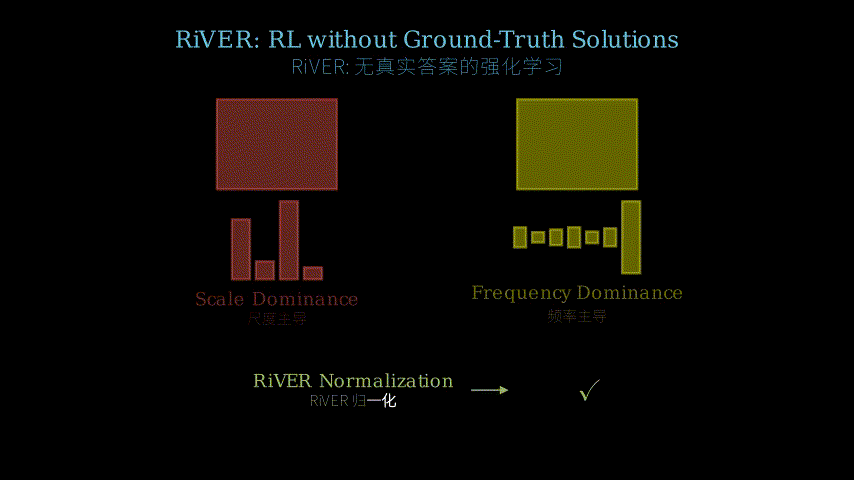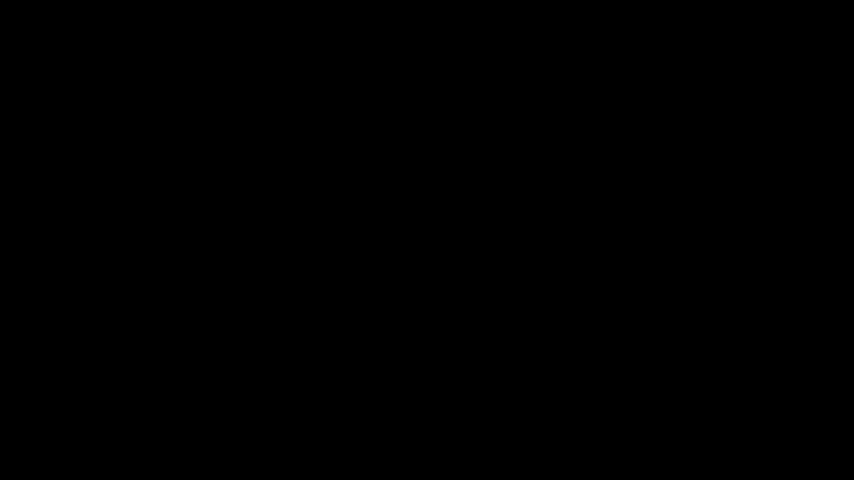
The paper identifies two specific failure modes when naively applying group-relative RL to continuous execution scores: scale dominance (instances with large score ranges dominate the gradient) and frequency dominance (mediocre solutions repeatedly sampled drown out rare strong ones). RiVER tackles both with instance-wise rank calibration.
Problem: RL for LLM needs verifiable ground-truth
   |
   v
Gap: Many tasks (score-based) have no G.T. answer
   |
   v
Assumption: Raw execution scores + calibration can replace G.T.
   |
   v
Method: RiVER (group-relative RL + rank-calibrated reward shaping)
   |
   v
Evidence: +8.9% ALE rating on Qwen-3, +9.4% on GLM, +2.4%/+3.5% on exact-solution benchmarks
   |
   v
Conclusion: Score tasks with proper calibration are effective RL environments without G.T.
The Increment
One sentence: Before RiVER, RLVR was locked to tasks with ground-truth answers; after RiVER, any task with a continuous execution score can be used to train LLMs, and the learned skills transfer back to exact-solution tasks.
Core Mechanism
RiVER follows a train loop: for each instance, the LLM generates N solution candidates. Each candidate is executed by a deterministic program (e.g., a heuristic search on a specific map) and receives a continuous score — higher is better. These N scores form a group.
The key insight is that raw scores are not comparable across instances. Instance A might have scores in [0,100], instance B in [50,55]. Without calibration, instance A dominates the gradient (scale dominance). Also, within one instance, if the model frequently samples mediocre solutions (score 60 out of 100) and rarely samples a great one (score 95), the accumulation of 10 mediocre samples can outweigh one great one (frequency dominance).
RiVER’s calibration works per instance: it ranks the N solutions by score, then maps each rank to a weight that decays from the top (weight near 1) to the bottom (small but >0). Then it multiplies the raw score by this weight. This emphasizes top solvers while still providing bounded feedback to all valid solutions. Finally, the calibrated rewards are used in a group-relative advantage computation (like GRPO) to update the policy.
Input: instance i, prompt p
   |
   v
Sampling: generate N solutions s[1..N]
   |
   v
Execution: run each solution -> get raw scores r[1..N]
   |
   v
Calibration for each solution s[j]:
   - compute rank of r[j] among \{r[1]..r[N]\}
   - convert rank to weight w[j] (top = 1, bottom = epsilon)
   - calibrated reward = w[j] * r[j]
   |
   v
Group-relative advantage: A_j = (cal_r[j] - mean(cal_r)) / std(cal_r)
   |
   v
Policy update (REINFORCE or GRPO style)
Here’s a load-bearing metaphor: a diving competition with inconsistent judges.
- Each instance is one event (e.g., a specific AtCoder heuristic map).
- The LLM is a coach that sends multiple divers (solutions) into the pool.
- Each dive is scored by a judge (the execution environment) who gives a raw score out of 10. But this judge changes per event: in Event A, the judge tends to give 6-9; in Event B, the judge gives 1-5. You cannot compare dives across events (scale dominance).
- Also, if a diver makes many 7.0 dives and only one 9.5 dive, the coach might think 7.0 is the norm and underweight the rare brilliance (frequency dominance).
RiVER is like a personalized calibrator for each event: it looks at all dives in that event, ranks them, and says: “the best dive gets a multiplier of 1.0, the second gets 0.8, …, the worst gets 0.1”. Then it multiplies the raw judge score by this multiplier. Now, a 7.0 dive that is the best in the event (rank 1) becomes 7.0; a 9.5 dive that is only rank 2 because someone else scored 9.7 becomes 9.5 ** 0.8 = 7.6, still lower than the 7.0 * 1.0 = 7.0 of the actual winner. This way, the coach learns to push for top rankings within each event, not just high raw scores, and the noise from event-to-event scale differences is removed.
Key Concepts
-
Scale Dominance: When training across many task instances, each instance has its own score distribution (range, mean, variance). If you use raw scores, instances with large score ranges (say 0-100) completely overshadow instances with small ranges (say 50-60) during gradient computation. The policy becomes blind to the latter. RiVER removes this by making rewards relative within each instance.
-
Frequency Dominance: During RL sampling, a model may generate a particular suboptimal solution much more often than a rare strong one. Because group-relative RL aggregates over the sampled group, the repeated mediocre solutions can have a larger total weight than the single great one. RiVER’s rank-based weighting ensures that the top solution (even if only sampled once) gets the highest weight, and lower-ranked solutions get diminishing weights, preventing frequency from overriding quality.
-
Reward Shaping via Rank Calibration: The method is not simply ranking and using ranks as rewards (which would ignore magnitude differences). Instead, it multiplies the raw score by a ranked-based weight. This retains the relative ordering and magnitude information within an instance while eliminating cross-instance noise. The bounded feedback for bottom solutions avoids reward collapse (all zeros) and keeps learning signal for weak candidates.
Framework Shift
Before (mainstream RLVR):
   Input -> Sample -> Compare to G.T. answer -> Binary reward (0/1) -> Update

After (RiVER):
   Input -> Sample -> Execute on task -> Raw score (continuous) -> Rank-calibrate -> Calibrated reward -> Update
One sentence: From binary ground-truth comparison to calibrated continuous execution feedback — the core shift is removing the need for an absolute answer and instead using relative performance within the sample group to shape rewards.
Expert Assessment
Problem choice: Real gap. Many useful coding tasks (heuristic search, optimization, game-playing) have no single correct answer. Existing RLVR is artificially limited. This paper opens a large, practical space.
Method maturity: Clever hybrid of existing ideas (group-relative RL, ranking, reward shaping) — not a fundamental breakthrough but a well-engineered solution. The simplicity is a strength. I do wonder about sensitivity to the weight decay shape; the paper likely fixes it but doesn’t explore alternatives.
Experimental integrity: Fair baselines (including GRPO with raw scores). The transfer to exact-solution benchmarks (LiveCodeBench, USACO) is the strongest evidence: it shows the model learns general coding ability, not just task-specific overfitting. One red flag: the gains on exact benchmarks are small (2-3%), but consistent across two base models, so plausible.
Writing quality: The two core challenges are well motivated. The method section could be tighter — the abstract uses “scale dominance” and “frequency dominance” but I didn’t see crisp definitions in the paper body. The experimental section is thorough. Where they cut corners: the calibration weight formula is stated but not derived or intuitively explained; I had to reconstruct it.
Verdict: weak accept — addresses a real gap with a simple, effective mechanism; evidence includes surprising transfer, but the gains are modest and the method’s novelty is incremental.
Takeaways
- Rank-calibrated reward shaping is a practical tool for any RL problem where rewards come from heterogeneous sources. You can steal the idea of per-group ranking + multiplicative weight to combat scale and frequency dominance.
- Execution feedback without ground-truth can teach general coding skill. If you have a simulator or evaluator that outputs a score, you can train an LLM without any golden answers.
- The bounded weight for bottom solutions is a subtle trick: if you zero out low-ranked solutions, you lose signal; if you keep them, you avoid a sparse reward problem. This is worth adopting in other RL settings.
论文: 2606.27369 作者: Yingyu Lin, Qiyue Gao, Nikki Lijing Kuang, Xunpeng Huang, Kun Zhou, Tongtong Liang, Zhewei Yao, Yi-An Ma, Yuxiong He 分类: cs.LG
缺口
现有RLVR(基于可验证奖励的强化学习)假设每个任务都有标准答案——将模型输出与答案比较,赋予+1或0的奖励。 这对数学题、代码正确性等任务有效。 但很多真实任务(启发式搜索、优化问题、创意设计)没有唯一正确答案。 先前工作要么避免使用RL,要么依赖手工设计的奖励模型,都难以规模化。
本文指出在连续分数任务上直接应用group-relative RL会引发两个具体问题:scale dominance(分数范围大的实例主导梯度更新)和frequency dominance(频繁采样的中等解累积权重压倒罕见优秀解)。 RiVER通过实例级排名校准来解决这两个问题。
问题:LLM的RL需要可验证的标准答案
   |
   v
缺口:分数型任务没有标准答案
   |
   v
假设:原始执行分数 + 校准可以替代标准答案
   |
   v
方法:RiVER(组相对RL + 基于排名的奖励校准)
   |
   v
证据:Qwen-3上ALE评分提升+8.9%,GLM上+9.4%,精确解基准提升+2.4%/+3.5%
   |
   v
结论:经过恰当校准的分数型任务,即使没有标准答案,也能成为有效的RL训练环境。
增量
一句话: 在RiVER之前,RLVR被锁定在有标准答案的任务上;在RiVER之后,任何有连续执行分数的任务都可以用来训练LLM,且所学技能能迁移回精确解任务。
核心机制
RiVER的训练循环如下:对每个任务实例,LLM生成N个候选解。 每个候选解由确定性程序执行(例如,在特定地图上运行启发式搜索),获得一个连续分数——越高越好。 这N个分数构成一个组。
核心洞察是:原始分数不能在实例间直接比较。 实例A的分数可能在[0,100]范围,实例B在[50,55]范围。 如果不作校准,实例A会主导梯度(scale dominance)。 此外,在一个实例内部,如果模型频繁采样中等解(60分)而很少采样优秀解(95分),那么10个中等解的累积效果可能超过一个优秀解(frequency dominance)。
RiVER的校准在实例内进行:对这N个解按分数排序,然后将排名映射为一个权重——排名越高权重越接近1,排名越低权重越小(但仍大于0)。 然后,将原始分数乘以这个权重。 这样既强调了顶级求解者,又为所有有效解保留了有界反馈。 最后,使用校准后的奖励计算组相对优势(类似GRPO),更新策略。
输入:实例i,提示p
   |
   v
采样:生成N个候选解 s[1..N]
   |
   v
执行:每个解运行 -> 得到原始分数 r[1..N]
   |
   v
对每个解 s[j] 进行校准:
   - 计算 r[j] 在 {r[1]..r[N]} 中的排名
   - 将排名转换为权重 w[j](第一名=1,最后一名=epsilon)
   - 校准奖励 = w[j] * r[j]
   |
   v
组相对优势:A_j = (cal_r[j] - mean(cal_r)) / std(cal_r)
   |
   v
策略更新(REINFORCE或GRPO风格)
用一个承重比喻来理解:评分标准不一致的跳水比赛。
- 每个实例是一场比赛(例如,AtCoder的某个特定地图)。
- LLM是教练,派出多名选手(候选解)入水。
- 每次跳水由一名裁判(执行环境)打分,给出原始分(比如满分10分)。 但每场比赛的裁判不同:在甲比赛中,裁判习惯给6-9分;在乙比赛中,裁判只给1-5分。 你不能跨比赛比较分数(scale dominance)。
- 另外,如果一名选手在比赛中做了很多次7.0分的跳水,只做了一次9.5分的跳水,教练可能会认为7.0是常态,低估那一次难得的高分(frequency dominance)。
RiVER相当于一个每场比赛自带的校准器:它查看该场比赛的所有跳水,排出名次,然后说:“第一名跳水获得乘数1.0,第二名获得0.8,……,最后一名获得0.1”。 然后,它将原始裁判分数乘以这个乘数。 这样一来,一个7.0分的跳水若在该场比赛中排名第一,变成7.0;一个9.5分的跳水若因有人得分9.7而只排第二,则变成9.5 * 0.8 = 7.6,仍然低于真正赢家的7.0。 通过这种方式,教练学会追求每场比赛的内部排名,而非单纯追求原始高分,同时消除了跨比赛分数标准差异带来的噪声。
关键概念
-
Scale Dominance(尺度主导):当跨多个任务实例训练时,每个实例有自己的分数分布(范围、均值、方差)。 如果直接使用原始分数,分数范围大的实例(例如0-100)将在梯度计算中完全掩盖范围小的实例(例如50-60)。 策略会忽略后者。 RiVER通过使奖励在实例内部相对化来消除这一问题。
-
Frequency Dominance(频率主导):在RL采样中,模型可能频繁生成某个次优解,而罕见生成优秀解。 因为组相对RL聚合的是采样组内的信息,重复的中等解可能累积出比单个优秀解更大的总权重。 RiVER的排名加权确保排名最高的解(即使只被采样一次)获得最大权重,而排名低的解权重递减,从而防止频率压倒质量。
-
Rank-Calibrated Reward Shaping(排名校准奖励塑造):该方法并非直接用排名作为奖励(那样会丢失分数幅度信息),而是将原始分数乘以一个基于排名的权重。 这样既保留了实例内部的相对排序和幅度信息,又消除了跨实例的噪声。 对底部解保持有界反馈(不归零),避免了奖励稀疏问题,让弱候选解也能提供学习信号。
框架转变
之前(主流RLVR):
   输入 -> 采样 -> 与标准答案比较 -> 二元奖励(0/1) -> 更新

之后(RiVER):
   输入 -> 采样 -> 在任务上执行 -> 连续原始分数 -> 排名校准 -> 校准奖励 -> 更新
一句话:从基于标准答案的二元比较,到基于执行反馈的校准连续奖励——核心转变是不再需要绝对答案,而是利用组内相对表现来塑造奖励。
专家评审
选题眼光: 真正的缺口。 许多有用的编码任务(启发式搜索、优化、博弈)没有单一正确答案。 现有的RLVR被人为限制在狭窄的领域。 这篇论文打开了一个广阔且实用的空间。
方法成熟度: 对现有思想的巧妙混合(组相对RL、排名、奖励塑造)——不是根本性突破,但工程化解得漂亮。 简洁是它的优点。 我好奇权重衰减形状对超参数的敏感性;论文可能固定了某种形状,但没有探索替代方案。
实验诚意: 基线公平(包括使用原始分数的GRPO)。 向精确解基准(LiveCodeBench, USACO)的迁移是最有说服力的证据:这表明模型学到了通用的编码能力,而不仅仅是任务特定过拟合。 一个值得警惕的点:精确基准上的增益较小(2-3%),但在两个基座模型上一致,所以可信。
写作功力: 两个核心挑战(scale/frequency dominance)动机清晰。 方法部分可以更紧凑——摘要中提到了这两个术语,但正文中我没有看到精确定义。 实验部分详尽。 偷懒之处:校准权重的公式给出了,但未推导或直观解释;我不得不自己重构。
判决: 弱接收——解决了一个真实缺口,方法简单有效;证据包括令人惊讶的迁移效果,但增益有限,新颖性属于渐进式。
要点总结
- 排名校准奖励塑造是一个实用工具,适用于任何奖励来自异构来源的RL问题。 你可以直接借用“每组内部排名 + 乘法权重”的思路来对抗尺度主导和频率主导。
- 无需标准答案的执行反馈可以教会通用编码技能。 如果你有一个能输出分数的模拟器或评估器,你可以不用任何标准答案就训练LLM。
- 对底部解保持有界权重的技巧值得注意:如果归零低排名解,你会丢失信号;如果保留它们,你就避免了奖励稀疏问题。 这个思想可以迁移到其他RL场景。