Paper: 2605.13826 Authors: Gordan Prastalo, Kevin Maik Jablonka Categories: cs.LG, cond-mat.mtrl-sci, physics.chem-ph
The Gap
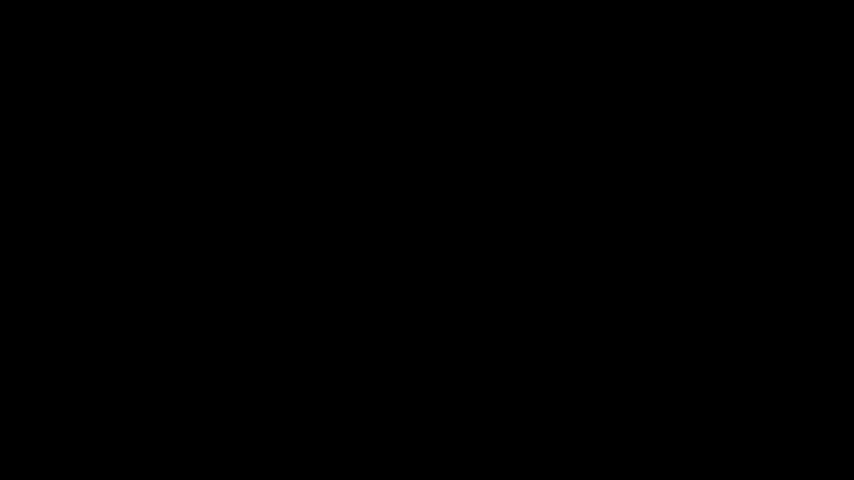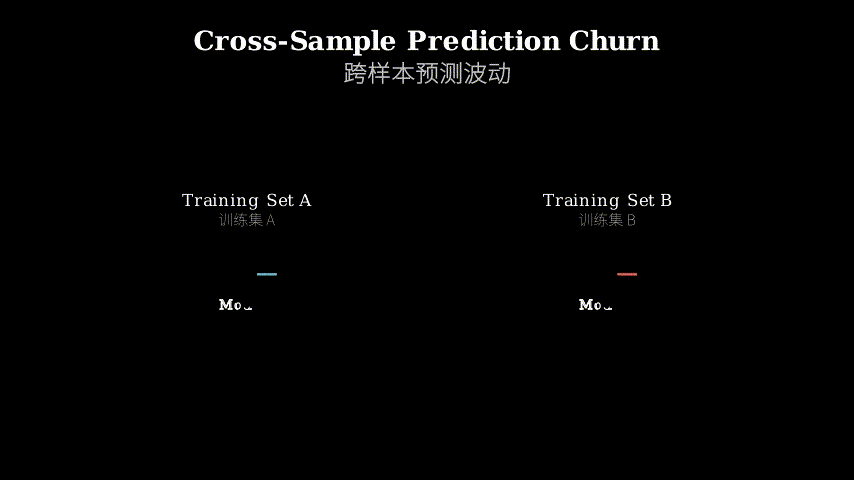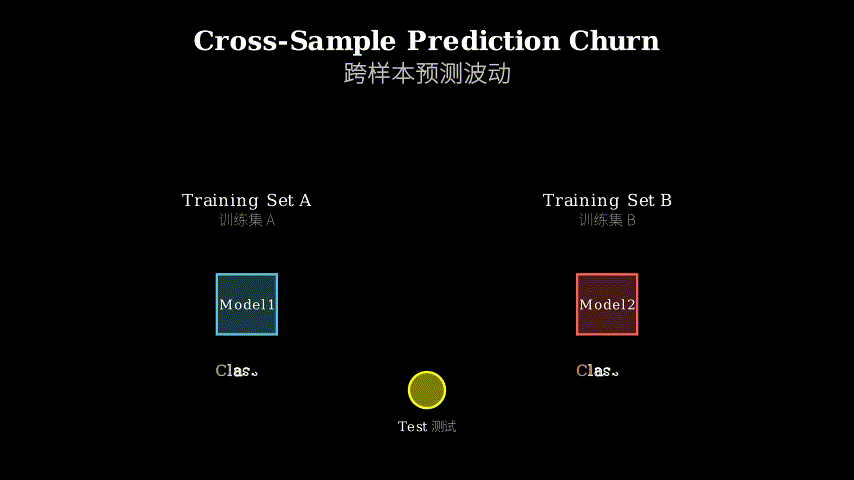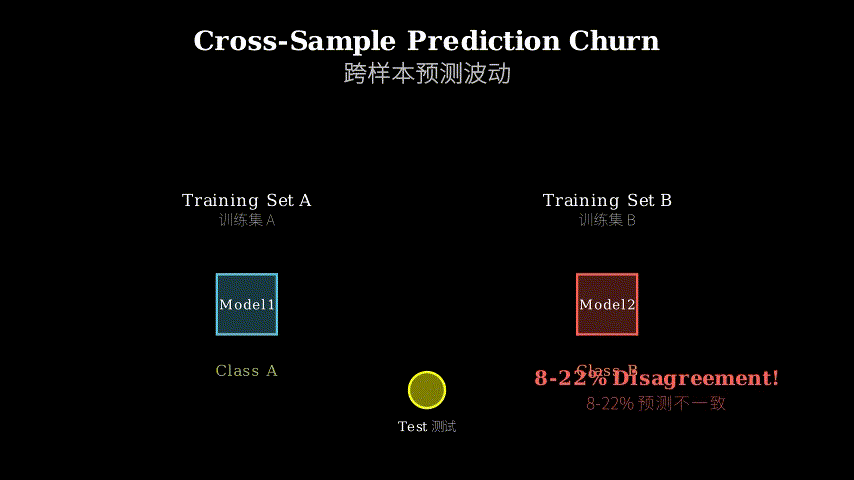
Scientific ML benchmarks report test accuracy. They don’t report whether your model’s predictions would survive if you’d drawn a different training set from the same distribution. Train two classifiers on independent bootstraps of the same data — they’ll agree on aggregate accuracy to within 1-4 percentage points, but disagree on the predicted class for 8-22% of test molecules. The field has been optimizing for a metric (accuracy) while ignoring the stability of individual predictions.
Existing uncertainty methods (deep ensembles, MC dropout, stochastic weight averaging) all operate on the parameter side — they vary model weights while keeping training data fixed. None of them address the question: would this prediction hold if I’d sampled different training examples?
Problem: Models agree on accuracy, disagree on predictions
   |
   v
Hypothesis: Parameter-side methods can't see data-side instability
   |
   v
Method: Twin-bootstrap (two nets, two data samples, consistency loss)
   |
   v
Evidence: 45% churn reduction beyond bagging at matched compute
   |
   v
Conclusion: Data-side variation matters; needs its own metric
The Increment
One sentence: Before this paper, scientific ML treated prediction disagreement as noise; after, it’s a measurable quantity with dedicated reduction methods.
Core Mechanism
Twin-bootstrap trains two neural networks simultaneously, each on an independent bootstrap sample of the training data. During training, the networks see different subsets of examples, but they’re forced to agree on their predictions through a symmetric KL divergence loss added to the standard classification loss.
The architecture is simple: two identical networks with separate parameters. Each forward pass processes a batch through both networks. Network A sees bootstrap sample 1, network B sees bootstrap sample 2. The total loss has three terms: classification loss for A, classification loss for B, and a consistency term that penalizes disagreement between A’s and B’s predicted probability distributions.
At test time, you average the predictions from both networks. The key insight is that by explicitly training for agreement across different data samples, you get models that are less sensitive to which specific training examples they happened to see.
Training:
  Bootstrap 1 --> Network A --> Predictions A --\
                                                  \
                                                   >-- sym-KL loss
                                                  /
  Bootstrap 2 --> Network B --> Predictions B --/
                    |                |
                    v                v
              Loss_A (CE)      Loss_B (CE)
                    |                |
                    \----------------/
                            |
                            v
                  Total = Loss_A + Loss_B + lambda * sym-KL

Inference:
  Test sample --> Network A --\
                               >-- Average --> Final prediction
  Test sample --> Network B --/
Think of it like training two apprentices who study different textbooks but must defend their answers to each other. Each apprentice (network) learns from different examples (bootstrap sample), but they’re graded not just on getting the right answer, but also on whether they agree with each other. When they disagree, both get penalized, forcing them to converge on predictions that are robust to which specific examples they studied. The disagreement penalty acts like peer review during training — it filters out predictions that are artifacts of particular training samples.
Key Concepts
-
Cross-sample prediction churn: Train two models on independent bootstraps of the same dataset. They’ll have similar test accuracy, but they’ll disagree on the predicted class for a significant fraction of test examples. That disagreement rate is the churn. It measures how much your predictions depend on the random draw of training data, not model randomness. If you train on Monday’s bootstrap and predict “toxic” for molecule X, then train on Tuesday’s bootstrap and predict “safe” for the same molecule X, that’s churn. It’s not about confidence intervals or epistemic uncertainty — it’s about whether the same input gets the same output when you resample training data.
-
Parameter-side vs data-side methods: Parameter-side methods (ensembles, dropout, weight averaging) vary model parameters while keeping training data fixed. They answer: “Given this training set, how uncertain is my model?” Data-side methods vary training data while tracking prediction stability. They answer: “If I’d sampled different training examples, would I get the same prediction?” The paper shows these are orthogonal dimensions. Deep ensembles reduce parameter uncertainty but don’t touch data-side churn. Bagging reduces churn but doesn’t help with parameter uncertainty. You need both.
-
Symmetric KL divergence: Standard KL divergence KL(P || Q) measures how much information you lose when approximating distribution P with distribution Q. It’s asymmetric — KL(P || Q) ≠ KL(Q || P). Symmetric KL is just the sum: KL(P || Q) + KL(Q || P). In twin-bootstrap, P is network A’s prediction, Q is network B’s prediction. The symmetric version penalizes both networks equally for disagreement, so neither network can “dominate” the other. It’s a mutual consistency constraint, not a teacher-student setup.
Framework Shift
Before (standard training):          After (twin-bootstrap):

  Training data                        Training data
       |                                    |
       v                              +-----+-----+
  Single model                        |           |
       |                              v           v
       v                         Bootstrap 1  Bootstrap 2
  Test predictions                     |           |
                                       v           v
                                   Network A   Network B
                                       |           |
                                       +-----+-----+
                                             |
                                             v
                                    Consistency loss
                                             |
                                             v
                                      Test predictions
                                      (averaged)

Focus: Accuracy                      Focus: Accuracy + Stability
Metric: Test error                   Metric: Test error + Churn rate
From single-model optimization to dual-model co-training, the core shift is treating prediction stability as a first-class objective alongside accuracy.
Expert Assessment
Problem choice: This is a real gap. The field has been reporting accuracy as if it’s the only thing that matters, but in scientific applications (drug discovery, materials design), you care whether a prediction is robust to data sampling. The authors didn’t manufacture this problem — they measured it across 9 chemistry benchmarks and found 8-22% churn rates. That’s not noise; that’s a systematic issue.
Method maturity: Twin-bootstrap is elegant but not groundbreaking. It’s essentially bagging with a consistency loss. The insight is solid: if you want models to agree across data samples, train them to agree. The execution is straightforward — no architectural tricks, no hyperparameter hell. The comparison to parameter-side methods is the real contribution, showing they’re solving different problems. One concern: the method requires 2x training compute. The authors compare to bagging-K=2 at matched compute, which is fair, but practitioners might balk at doubling training time.
Experimental integrity: Baselines are fair. They compare to deep ensembles, MC dropout, SWA, and bagging across 9 datasets. The churn metric is well-defined and consistently measured. One weakness: all experiments are on molecular property prediction. Does this generalize to other scientific domains (genomics, climate, physics)? The paper doesn’t say. The ablation on lambda (consistency loss weight) is minimal — just one plot showing sensitivity. More analysis of when twin-bootstrap helps vs hurts would strengthen the claims.
Writing quality: The abstract and introduction are crisp. The method section is clear. The results section is dense with tables but lacks intuition about *why twin-bootstrap works better than bagging. The discussion of computational cost is buried in the appendix — it should be front and center since 2x compute is a real barrier. The paper would benefit from a failure case analysis: when does twin-bootstrap not help?
Verdict: weak accept — Identifies a real problem, proposes a simple solution, demonstrates effectiveness across multiple benchmarks. The method isn’t novel enough for a strong accept, but the problem framing and the data-side vs parameter-side distinction are valuable contributions. The field needs this metric.
Takeaways
-
Add churn to your benchmark reports: If you’re publishing scientific ML results, report cross-sample prediction churn alongside test accuracy. Train two models on independent bootstraps, measure disagreement rate on test set. It’s cheap to compute and reveals instability that accuracy hides.
-
Consistency losses for stability: When you care about prediction stability, add a consistency term between models trained on different data samples. The symmetric KL formulation is simple and effective. This transfers beyond chemistry — any domain where predictions inform decisions (medical diagnosis, financial risk, infrastructure monitoring).
-
Parameter-side and data-side are orthogonal: Deep ensembles and bagging solve different problems. If you want both low uncertainty and low churn, you need both. Don’t assume one subsumes the other.
-
Bootstrap as a stability diagnostic: Even if you don’t use twin-bootstrap, train models on multiple bootstraps and check prediction agreement. High churn is a red flag that your model is overfitting to specific training examples rather than learning robust patterns.
论文: 2605.13826 作者: Gordan Prastalo, Kevin Maik Jablonka 分类: cs.LG, cond-mat.mtrl-sci, physics.chem-ph
缺口
科学机器学习的基准测试报告测试准确率。
它们不报告你的模型预测是否能在换一批训练数据后依然成立。
从同一数据集抽两个独立的自举样本,训练两个分类器——它们的总体准确率会在 1-4 个百分点内一致,但在 8-22% 的测试分子上预测的类别不同。
该领域一直在优化一个指标(准确率),却忽略了单个预测的稳定性。
现有的不确定性方法(深度集成、MC dropout、随机权重平均)都在参数侧操作——它们改变模型权重,但训练数据保持不变。
它们都没有回答这个问题:如果我抽样了不同的训练样本,这个预测还会成立吗?
问题:模型在准确率上一致,在预测上分歧
   |
   v
假设:参数侧方法看不到数据侧的不稳定性
   |
   v
方法:孪生自举(两个网络,两个数据样本,一致性损失)
   |
   v
证据:在匹配计算量下,波动率比装袋法再降 45%
   |
   v
结论:数据侧变化很重要;需要专门的指标
增量
一句话: 这篇论文之前,科学机器学习把预测分歧当噪声;之后,它成了可测量的量,有专门的降低方法。
核心机制
孪生自举同时训练两个神经网络,每个网络在训练数据的独立自举样本上学习。
训练期间,两个网络看到不同的样本子集,但它们被迫通过一个对称 KL 散度损失在预测上达成一致,这个损失被加到标准分类损失上。
架构很简单:两个参数独立的相同网络。
每次前向传播都把一个批次送入两个网络。
网络 A 看自举样本 1,网络 B 看自举样本 2。
总损失有三项:A 的分类损失、B 的分类损失,以及一个惩罚 A 和 B 预测概率分布分歧的一致性项。
测试时,你对两个网络的预测取平均。
关键洞察是:通过显式地训练跨数据样本的一致性,你得到的模型对它们碰巧看到的具体训练样本不那么敏感。
训练:
  自举样本 1 --> 网络 A --> 预测 A --\
                                      \
                                       >-- 对称 KL 损失
                                      /
  自举样本 2 --> 网络 B --> 预测 B --/
                    |            |
                    v            v
              损失_A (交叉熵)  损失_B (交叉熵)
                    |            |
                    \------------/
                         |
                         v
              总损失 = 损失_A + 损失_B + lambda * 对称 KL

推理:
  测试样本 --> 网络 A --\
                        >-- 平均 --> 最终预测
  测试样本 --> 网络 B --/
把它想象成训练两个学徒,他们学习不同的教材,但必须互相为自己的答案辩护。
每个学徒(网络)从不同的例子(自举样本)中学习,但他们的评分标准不仅是答对,还包括他们是否彼此同意。
当他们意见不一致时,两人都会被扣分,迫使他们收敛到对所学的具体例子具有鲁棒性的预测上。
分歧惩罚就像训练期间的同行评审——它过滤掉那些是特定训练样本产物的预测。
关键概念
- 跨样本预测波动: 在同一数据集的独立自举样本上训练两个模型。
它们的测试准确率会相似,但它们会在相当一部分测试样本上对预测类别产生分歧。
那个分歧率就是波动率。
它衡量你的预测对训练数据的随机抽样有多依赖,而不是模型随机性。
如果你在周一的自举样本上训练,对分子 X 预测”有毒”,然后在周二的自举样本上训练,对同一个分子 X 预测”安全”,那就是波动。
这不是关于置信区间或认知不确定性——而是关于当你重新抽样训练数据时,同一个输入是否得到同一个输出。
- 参数侧 vs 数据侧方法: 参数侧方法(集成、dropout、权重平均)改变模型参数,但保持训练数据不变。
它们回答:“给定这个训练集,我的模型有多不确定?“数据侧方法改变训练数据,同时跟踪预测稳定性。
它们回答:“如果我抽样了不同的训练样本,我会得到同样的预测吗?“论文表明这些是正交维度。
深度集成降低参数不确定性,但不触及数据侧波动。
装袋法降低波动,但对参数不确定性没帮助。
你两者都需要。
- 对称 KL 散度: 标准 KL 散度 KL(P || Q) 衡量当你用分布 Q 近似分布 P 时损失了多少信息。
它是非对称的——KL(P || Q) ≠ KL(Q || P)。
对称 KL 就是求和:KL(P || Q) + KL(Q || P)。
在孪生自举中,P 是网络 A 的预测,Q 是网络 B 的预测。
对称版本对两个网络的分歧施加相等的惩罚,所以任何一个网络都不能”主导”另一个。
这是一个相互一致性约束,不是师生设置。
框架转变
之前(标准训练):                之后(孪生自举):

  训练数据                          训练数据
     |                                  |
     v                            +-----+-----+
  单一模型                        |           |
     |                            v           v
     v                       自举样本 1   自举样本 2
  测试预测                         |           |
                                   v           v
                               网络 A       网络 B
                                   |           |
                                   +-----+-----+
                                         |
                                         v
                                    一致性损失
                                         |
                                         v
                                    测试预测
                                    (平均)

焦点:准确率                      焦点:准确率 + 稳定性
指标:测试误差                    指标:测试误差 + 波动率
从单模型优化到双模型协同训练,核心转变是把预测稳定性作为与准确率并列的一等目标。
专家评审
选题眼光: 这是真缺口。
该领域一直在报告准确率,好像它是唯一重要的东西,但在科学应用(药物发现、材料设计)中,你关心预测是否对数据抽样具有鲁棒性。
作者没有制造这个问题——他们在 9 个化学基准上测量了它,发现 8-22% 的波动率。
那不是噪声;那是系统性问题。
方法成熟度: 孪生自举优雅但不突破性。
它本质上是带一致性损失的装袋法。
洞察是扎实的:如果你想让模型在数据样本间达成一致,就训练它们达成一致。
执行很直接——没有架构技巧,没有超参数地狱。
与参数侧方法的比较是真正的贡献,表明它们在解决不同的问题。
一个担忧:该方法需要 2 倍训练计算量。
作者在匹配计算量下与装袋法-K=2 比较,这是公平的,但实践者可能会对训练时间翻倍犹豫。
实验诚意: 基线公平。
他们在 9 个数据集上与深度集成、MC dropout、SWA 和装袋法比较。
波动指标定义明确且一致测量。
一个弱点:所有实验都在分子性质预测上。
这能推广到其他科学领域(基因组学、气候、物理)吗?论文没说。
关于 lambda(一致性损失权重)的消融实验很少——只有一张显示敏感性的图。
更多关于孪生自举何时有帮助 vs 有害的分析会加强论断。
写作功力: 摘要和引言简洁。
方法部分清晰。
结果部分表格密集但缺乏关于为什么孪生自举比装袋法更好的直觉。
关于计算成本的讨论埋在附录里——它应该放在前面中心位置,因为 2 倍计算量是真正的障碍。
论文会受益于失败案例分析:孪生自举何时没帮助?
判决: 弱接收——识别了真问题,提出了简单解决方案,在多个基准上展示了有效性。
方法不够新颖,不足以强接收,但问题框架和数据侧 vs 参数侧的区分是有价值的贡献。
该领域需要这个指标。
要点总结
- 在基准报告中加入波动率: 如果你在发表科学机器学习结果,在测试准确率旁边报告跨样本预测波动率。
在独立自举样本上训练两个模型,测量测试集上的分歧率。
计算成本低,揭示准确率隐藏的不稳定性。
- 用一致性损失提高稳定性: 当你关心预测稳定性时,在不同数据样本上训练的模型之间加一个一致性项。
对称 KL 公式简单有效。
这超越化学——任何预测影响决策的领域(医疗诊断、金融风险、基础设施监控)都适用。
- 参数侧和数据侧是正交的: 深度集成和装袋法解决不同的问题。
如果你想要低不确定性和低波动,你两者都需要。
不要假设一个包含另一个。
- 自举作为稳定性诊断: 即使你不用孪生自举,在多个自举样本上训练模型并检查预测一致性。
高波动是一个危险信号,表明你的模型过拟合到特定训练样本,而不是学习鲁棒模式。